Command Palette
Search for a command to run...
일반화 가능한 에이전트 강화학습을 위한 Harness Scaling
일반화 가능한 에이전트 강화학습을 위한 Harness Scaling
Fei Bai Huatong Song Chuan Hao Ran Tao Jian Yang Bryan Dai Wayne Xin Zhao Ji-Rong Wen
초록
에이전트 하네스는 현대적 에이전트 시스템의 핵심 구성 요소가 되었으며, 모델이 도구를 사용하고, 컨텍스트를 관리하며, 장기적 상호작용을 조율하는 방식을 규정한다. 이들 하네스의 이점을 실현하는 것은 기저 모델이 이를 얼마나 효과적으로 활용하는가에 달려 있으며, 이는 하네스를 통해 직접 수행하는 강화학습의 필요성을 제기한다. 그러나 기존 방법들은 일반적으로 단일 고정 하네스를 통해 학습하므로, 특정 하네스에 대한 특화와 하네스 구성 간 제한된 전이로 이어질 수 있다. 이를 해결하기 위해, 우리는 에이전트 강화학습의 새로운 스케일링 차원인 Harness Scaling을 제안하며, 학습 범위를 단일 하네스에서 다양한 실행 구성으로 확장한다. 구체적으로, 요인화된 하네스 공간을 구성하고, 균형 잡힌 조합적 커버리지를 갖는 컴팩트한 학습 하위 집합을 선별하며, 동일한 과제에 대해 전역적 커버리지와 통제된 변형을 결합하도록 하네스 간 학습을 조직한다. 다양한 벤치마크, 모델 규모, 강화학습 알고리즘에 걸쳐 Harness Scaling은 본 적 없는 화이트박스 구성에 대한 일반화 성능을 일관되게 향상시킨다. 또한, 구조화된 화이트박스 변형을 통해 학습된 모델들은 본 적 없는 외부 블랙박스 하네스로도 효과적으로 전이되어, 단일 복잡한 블랙박스 하네스를 통해 학습된 모델보다 우수한 성능을 보인다. 이러한 결과는 하네스 다양성이 에이전트 강화학습의 의미 있는 스케일링 차원임을 확립하며, 하네스 간 일반화를 위해서는 이러한 다양성이 어떻게 조직되는지가 중요하다는 점을 강조한다.
One-sentence Summary
Researchers at Renmin University of China, IQuest Research, and Beihang University introduce Harness Scaling, an agentic reinforcement learning scaling dimension that extends training from a single fixed harness to diverse execution configurations by constructing a factorized harness space, selecting a compact training subset with balanced factorial coverage, and organizing cross-harness training with controlled variation, improving generalization to unseen white-box configurations and effective transfer to unseen external black-box harnesses across multiple benchmarks, model scales, and RL algorithms.
Key Contributions
- Introduces Harness Scaling, a scaling dimension for agentic RL that trains policies across diverse execution harness configurations rather than a single fixed harness, addressing specialization and limited transfer.
- Develops a structured framework that factorizes harness variation, selects a compact training subset with balanced factorial coverage, and assigns structurally nearby configurations to the same task during cross-harness training.
- Across benchmarks, model scales, and RL algorithms, Harness Scaling improves generalization to unseen white-box harnesses and transfers effectively to complex external black-box harnesses, outperforming training through a single complex black-box harness.
Introduction
Agent harnesses shape how language-model agents use tools, manage context, and recover from errors, making them central to long-horizon agentic systems. Prior work mainly scales the tasks and environments used for reinforcement learning, or trains policies inside one fixed harness, which can cause overfitting to a specific execution setup and poor transfer to new harnesses. The authors introduce Harness Scaling, treating the harness as a trainable variation dimension by factorizing it into system prompt, tool interface, observation, context management, and workflow. They leverage orthogonal design to build a compact set of diverse harness configurations and pair each task with structurally nearby configurations during RL. This approach improves generalization to unseen white-box harnesses and transfers effectively to external black-box harnesses.
Method
The authors propose Harness Scaling, a methodology that treats the execution harness as a new scaling axis to improve policy generalization. Rather than relying on a single monolithic execution environment, the framework systematically explores diverse execution configurations to train more robust policies.
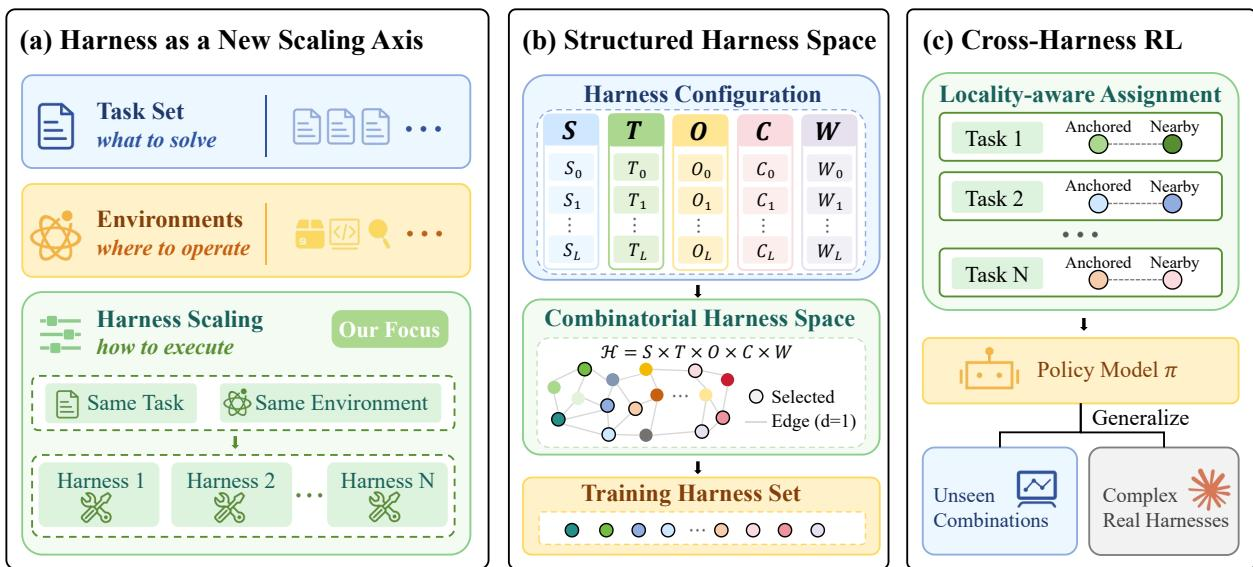
As illustrated in the framework diagram, the approach encompasses three core stages: conceptualizing the harness as a scaling axis, constructing a structured combinatorial harness space, and executing cross-harness reinforcement learning to achieve generalization across unseen configurations and complex real-world harnesses.
To study this systematically, the authors formalize the space of execution configurations by factorizing the harness into five distinct components: system prompt (S), tool interface (T), observation (O), context management (C), and workflow (W). Each component is instantiated through a family of specific transformations applied to a base realization. A complete harness configuration h selects one realization from each component set, defining the factorized harness space as:
H=S×T×O×C×WThe product structure of this space induces a natural notion of structural proximity, measured by the Hamming distance dH(hi,hj), which counts the number of component dimensions on which two configurations differ. The generalization objective focuses on two complementary forms: in-space combinatorial generalization to held-out configurations within H, and out-of-space generalization to complex real-world black-box harnesses beyond the constructed design space.
Because the factorized harness space grows combinatorially, exhaustive training is computationally prohibitive and introduces redundancy. To address this, the authors construct a compact training set that preserves broad factorial coverage under a fixed optimization budget. They treat the harness space as a factorial design and enforce strength-2 balance. This requires component balance, ensuring each realization is represented evenly, and pairwise combination balance, where every pair of realizations from any two components appears equally often in the selected set. The authors instantiate a strength-2 orthogonal design over the component realizations to directly construct the training harness set Htr⊂H. This design satisfies the Rao bound and ensures that while low-order projections are perfectly balanced, many complete harness combinations remain unseen, thereby enabling the evaluation of in-space combinatorial generalization.
The training procedure exposes the policy to multiple execution configurations for the same underlying task through a locality-aware assignment strategy and multi-harness policy optimization. For the cross-harness task assignment, the authors assign a small group of structurally related configurations to each task. For a given task x, an anchor harness hx is sampled uniformly from the training set Htr. The remaining K−1 configurations are selected as those with the smallest Hamming distance to the anchor. This yields a task-specific harness set:
Hx={hx,hx(1),…,hx(K−1)}This approach combines local cross-harness variation with broad global coverage, as different tasks are distributed across different regions of the training space.
During multi-harness policy optimization, each task-harness instance (x,h) is executed to produce a trajectory τ and a corresponding reward. The K harnesses assigned to the same task are utilized over successive training steps. For a policy-update batch B induced by the task-harness training distribution, the authors optimize the standard clipped policy objective:
L(θ)=NB1(x,h,τ)∈B∑t=1∑∣τ∣Mtmin(ρt(θ)At,clip(ρt(θ),1−ϵ,1+ϵ)At)where NB is the total number of valid policy-generated tokens, ρt(θ) is the probability ratio, Mt is a masking variable, and At is the advantage computed by the underlying reinforcement learning algorithm. This cross-harness training procedure is seamlessly applied to both PPO and GRPO, allowing the policy to learn robust behaviors that generalize beyond any single harness configuration.
Experiment
The experiments compare Harness Scaling with single-harness and black-box baselines across multiple agent benchmarks, testing in-space generalization to unseen harness configurations and transfer to external black-box harnesses. Results show that training over structured, diverse harness configurations improves robustness to execution settings without requiring exposure to every combination, and this benefit persists across model sizes, RL algorithms, and external harnesses. Ablations indicate that harness selection, per-task harness diversity, and locality-aware assignment are important, while behavioral analysis shows gains in state tracking, workflow compliance, and error recovery rather than overfitting to the base harness.
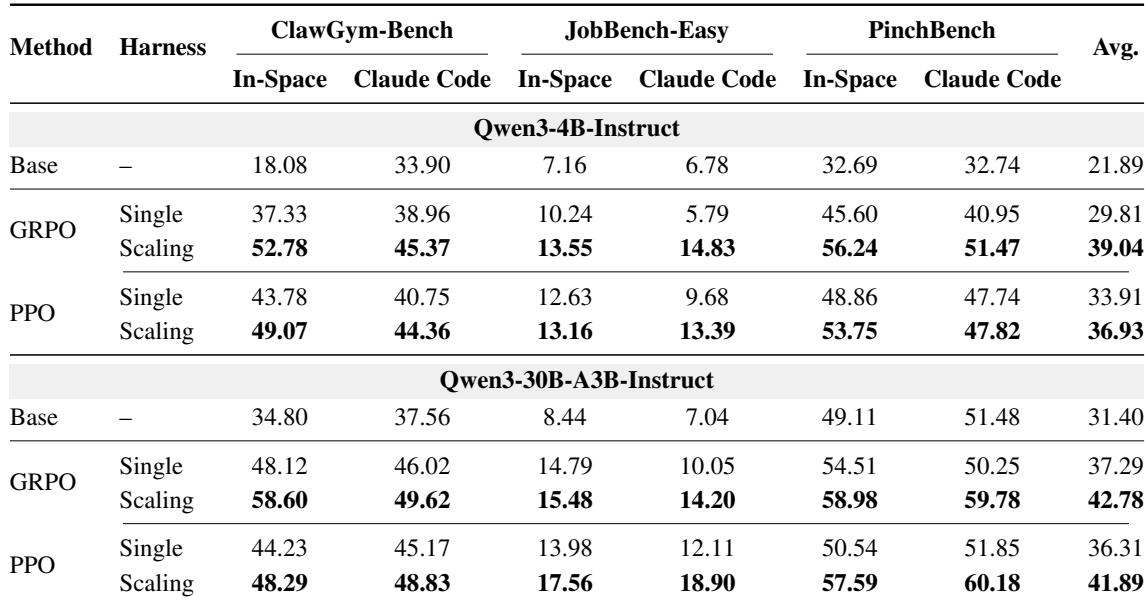
Harness scaling improves pass@1 results across held-out configurations and the external black-box harness compared with single-harness training. The benefit appears for both smaller and larger backbones and for GRPO and PPO, indicating robustness across model sizes and optimization methods. The trend also suggests that training over diverse structured harnesses supports better cross-harness transfer than direct training through one complex harness. Harness scaling raises average performance on held-out harness configurations for both evaluated model scales. The improvement holds under GRPO and PPO rather than depending on one optimizer. The scaled harness approach remains effective on the external black-box harness, where it outperforms direct black-box training baselines.
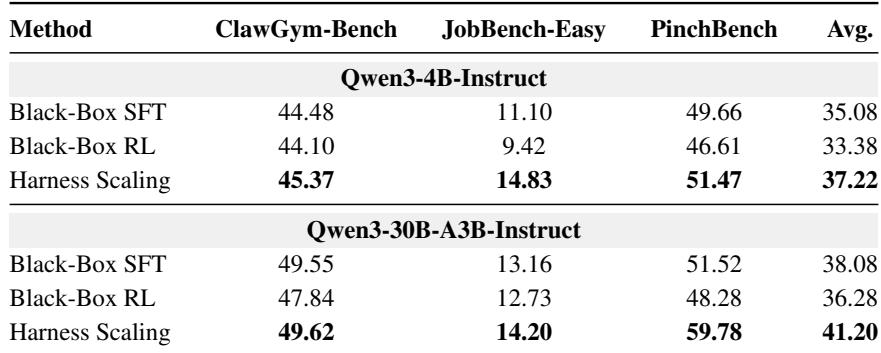
On Claude Code, models trained with Harness Scaling achieve the highest average Pass@1 for both Qwen model scales, surpassing black-box SFT and black-box RL baselines trained through OpenClaw. The result indicates that structured training over diverse white-box harness configurations transfers more effectively to an unseen black-box harness than direct training through a single complex black-box harness. Harness Scaling improves transfer to the unseen black-box harness at both model scales. Black-box SFT yields higher average Pass@1 than black-box RL in this transfer setting.
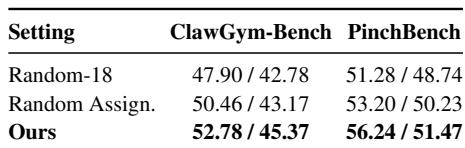
Structured selection of the 18-harness training set outperforms a randomly selected 18-harness set on both benchmarks under both evaluation settings. Locality-aware assignment also improves over random assignment, supporting the combination of broad harness coverage with controlled per-task variation. Structured 18-harness selection yields higher In-Space and Claude Code scores than Random-18 on ClawGym-Bench and PinchBench. Locality-aware assignment improves over random assignment across both benchmarks and evaluation settings.
For Qwen3-30B-A3B-Instruct trained with GRPO, scaling across harnesses leaves base-harness performance nearly unchanged while increasing in-space benchmark and Claude Code scores. The larger gains on alternative harnesses, compared with the slight base-harness decline, indicate better robustness to execution variation without major specialization loss. Base-harness performance changes only slightly after scaling. In-space and Claude Code performance improve under scaling, with the in-space gain especially large.
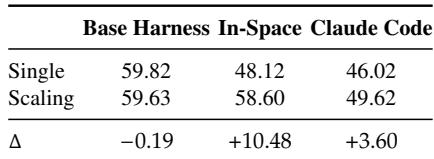
Experiments evaluate pass@1 performance across held-out harness configurations, an external black-box harness, and benchmark suites using Qwen backbones trained with GRPO and PPO. Harness scaling consistently improves transfer to unseen harnesses while preserving base-harness performance, indicating robustness across model scales and optimization methods. Structured harness selection with locality-aware assignment also outperforms random selection, suggesting that broad but controlled exposure to execution environments supports better cross-harness generalization.