Command Palette
Search for a command to run...
Épi: 지속적이고 자기 개선적인 자율 연구 에이전트를 향하여
Épi: 지속적이고 자기 개선적인 자율 연구 에이전트를 향하여
초록
Épi를 제시한다. Épi는 축적된 경험을 통해 방법론을 진화시키며 여러 모델 세션을 넘어 연구를 지속하는 자율 연구 에이전트이다. Épi는 지속적인 연구 이력, 계층적 기억, 분기, 독립적 검토를 결합하여 연구의 연속성을 유지하고 실험으로부터 학습하며 대안적 접근법을 탐색하고 재방문한다. 실험들은 세션 경계를 넘어 수행되며, 고정된 검증기가 그 출력을 평가한다. Épi는 120개의 기록 경신 결과를 생성했으며, 이는 12개 계열에 걸친 20개의 수치적 경계 기록과 8개 계열에 걸친 100개의 구성 기록으로 구성된다. 여기에는 n-queens 상수에 대해 약 84배 더 좁은 구간과 4차 Feigenbaum 끌개 차원에 대해 360만 배 이상 더 좁은 엄밀한 구간이 포함된다. 정확한 쌍대 인증서는 Cohn–Elkies 선형계획법 상한이 10차원과 11차원에서는 정확할 수 없음을 입증한다. 수치적 개선 외에도 Épi는 클릭 부분이 8개 꼭짓점으로 이루어져 있고 삼각형 활성 근접 유형이 최대 3개이며 그 중복도는 임의로 허용되는 분할 그래프에 대한 Tuza 추측의 컴퓨터 지원 증명을 제시한다. 이 연구 과정을 알고리즘 코딩으로 확장하기 위해 Épi-turbo를 사용하는데, Épi-turbo는 차량 경로 문제, 스케줄링, 생산 계획 등의 과제에 대한 실행 가능한 풀이자를 개발하는 경량 설정이다. 30개의 FrontierOR 과제에서 Épi-turbo는 동일한 기반 모델과 추론 노력을 사용하면서 모델 비용을 Codex의 64%로 낮추어 총 벤치마크 점수를 5.4% 더 달성한다. Épi는 계산 결과를 연구자가 검토하고 그 위에 구축할 수 있는 명시적 방법 및 수학적 논증과 연결함으로써 인간의 이해를 돕도록 설계되었다.
One-sentence Summary
The authors present Épi, a persistent, self-improving autonomous research agent that sustains investigations across model sessions through research history, hierarchical memory, branching, independent review, cross-session experiments, and a fixed verifier, yielding 120 record-setting results, including 20 numerical bound records and 100 construction records, plus a computer-assisted proof of Tuza’s conjecture for split graphs, while its Épi-turbo configuration develops executable solvers that achieve a 5.4% higher total benchmark score than Codex on 30 FrontierOR tasks at 64% of Codex’s model cost under the same underlying model and reasoning effort.
Key Contributions
- Épi is introduced as an autonomous research agent that sustains investigations across model sessions by coupling persistent research history, hierarchical memory, branching, independent review, and a fixed verifier to learn from experiments and revisit alternative approaches.
- Épi yields 120 record-setting results, including an approximately 84-fold narrower interval for the n-queens constant and a more than 3.6-million-fold narrower rigorous interval for the quartic Feigenbaum attractor dimension. Épi also supplies exact dual certificates showing that the Cohn-Elkies linear-programming bound cannot be sharp in dimensions 10 and 11 and a computer-assisted proof of Tuza’s conjecture for split graphs with an eight-vertex clique part and at most three triangle-active neighborhood types.
- Épi-turbo extends this research process to algorithmic coding, developing executable solvers for vehicle routing, scheduling, and production planning. On 30 FrontierOR tasks, Épi-turbo achieves a 5.4% higher total benchmark score than Codex at 64% of Codex's model cost under the same underlying model and reasoning effort.
Introduction
Autonomous research agents matter for workflows where progress depends on many experiments, program generation, and executable checking, especially in mathematical discovery and algorithmic optimization. Earlier systems show that LLMs can propose code and evaluate it, but they can struggle when research must continue across sessions, convert results into reusable lessons, and explore alternative methods without losing the evidence that made a choice successful or unsuccessful. The authors introduce Épi, a persistent autonomous research agent that uses hierarchical memory, versioned branches, independent review, and a fixed verification protocol to sustain and refine long running investigations.
Method
The authors present Épi, an autonomous research system designed to conduct verifiable investigations and improve its methods through accumulated experience. The overall architecture orchestrates a continuous research loop where an agent explores alternative formulations, executes durable experiments, and submits candidates to a frozen evaluation environment.
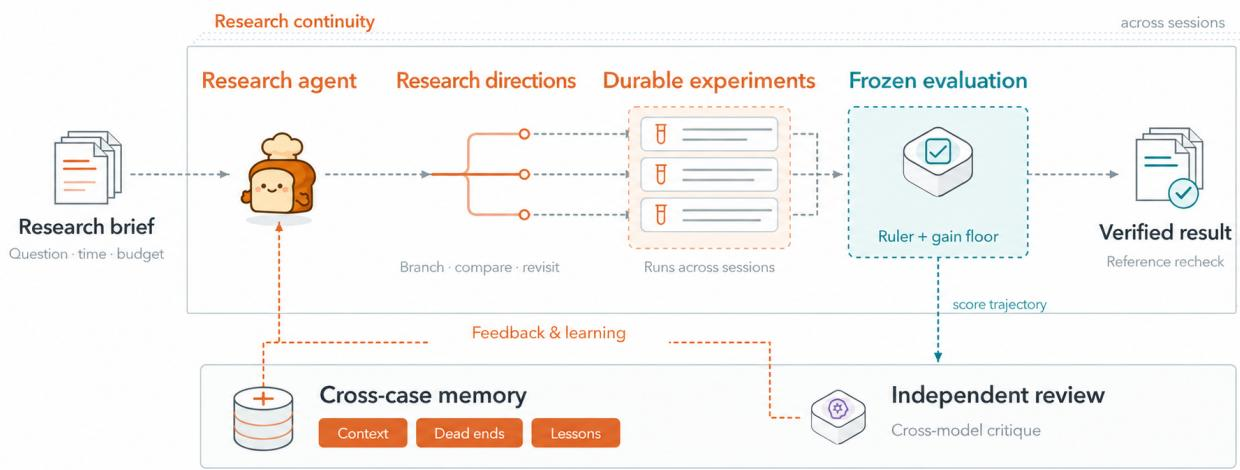
As illustrated in the framework diagram, the process begins with a research brief containing the question, time budget, and constraints. The research agent develops methods on versioned branches, allowing it to branch, compare, and revisit different approaches. These durable experiments run across sessions and feed into a frozen evaluation module. This module applies a strict ruler and a gain floor to produce a verified result, which is then subjected to a reference recheck. The system incorporates a feedback and learning loop driven by cross-case memory and an independent review model.
To ensure consistent validity checks, the authors establish a fixed evaluation rule, termed a ruler, before the search begins. For a minimization problem, the verifier’s feasibility decision is denoted as V(x)∈{0,1}, the objective as f(x), and the reference value as b. The improvement is defined as Δ(x)=b−f(x). The system specifies a positive gain floor δ>0, representing the smallest meaningful improvement. A candidate is accepted when it satisfies both feasibility and the gain threshold:
V(x)=1,Δ(x)≥δ.For maximization tasks, the improvement is defined as Δ(x)=f(x)−b. This rigid evaluation framework ensures that every branch is compared under a shared rule, providing a consistent basis for method comparison throughout the investigation.
The research agent improves its methodology through three core mechanisms: branching, hierarchical memory, and independent review. First, the system maintains versioned branches to develop alternatives while preserving each method’s code and evidence. The agent can backtrack by returning to a saved implementation and trying a different continuation, or it can abandon a branch while recording the reason for later inspection.
Second, Épi leverages a hierarchical memory structure to accumulate and reuse research experience. Short-term memory supports the current investigation, while long-term memory retains experience for subsequent research. The cross-case memory store retains research context, lessons that capture reusable findings, and dead ends that document unproductive approaches. At a session boundary, the agent records its findings and a handover note. A subsequent session retrieves these relevant memory records to guide its next experiment without needing to replay the full history of earlier sessions.
Third, to mitigate the limited perspective of the developing agent, the system employs an independent review model. This separate model assesses the score trajectory, attempted approaches, retrieved findings, and resource use. The reviewer evaluates whether the agent’s interpretation of progress is justified and whether a score increase reflects the intended task rather than reward hacking. The isolated verifier checks the candidate’s validity and gain under the fixed ruler, while the reviewer evaluates the overall research direction.
The execution infrastructure, Breadboard, supports these processes by providing isolated experimental environments and enabling long-running jobs across model sessions. It stores the research history, including code, branch states, and experimental outputs, and runs the fixed verifier. For fast, low-cost algorithm design tasks, the authors introduce Épi-turbo, a lightweight configuration that runs campaigns as continuous sessions, strictly controls model call budgets, and stops the campaign when additional sessions fail to improve the best verified score.
Experiment
Experiments were conducted with frontier language models over bounded budgets, comparing final artifacts against literature or registry baselines across mathematical and optimization tasks. The results show broad record-setting activity in geometric packing, numerical bounds, and specialized constructions, while case studies validate refined packings, a structural limitation of the Cohn-Elkies method, tightened constants, and certified optimization bounds. On the FrontierOR protocol, Épi-turbo generally produced algorithms that balanced solution quality and runtime while using less compute than the coding-agent baseline. Overall, the evaluation supports Épi as a practical research tool for constructing verified mathematical artifacts and designing efficient standalone solvers.
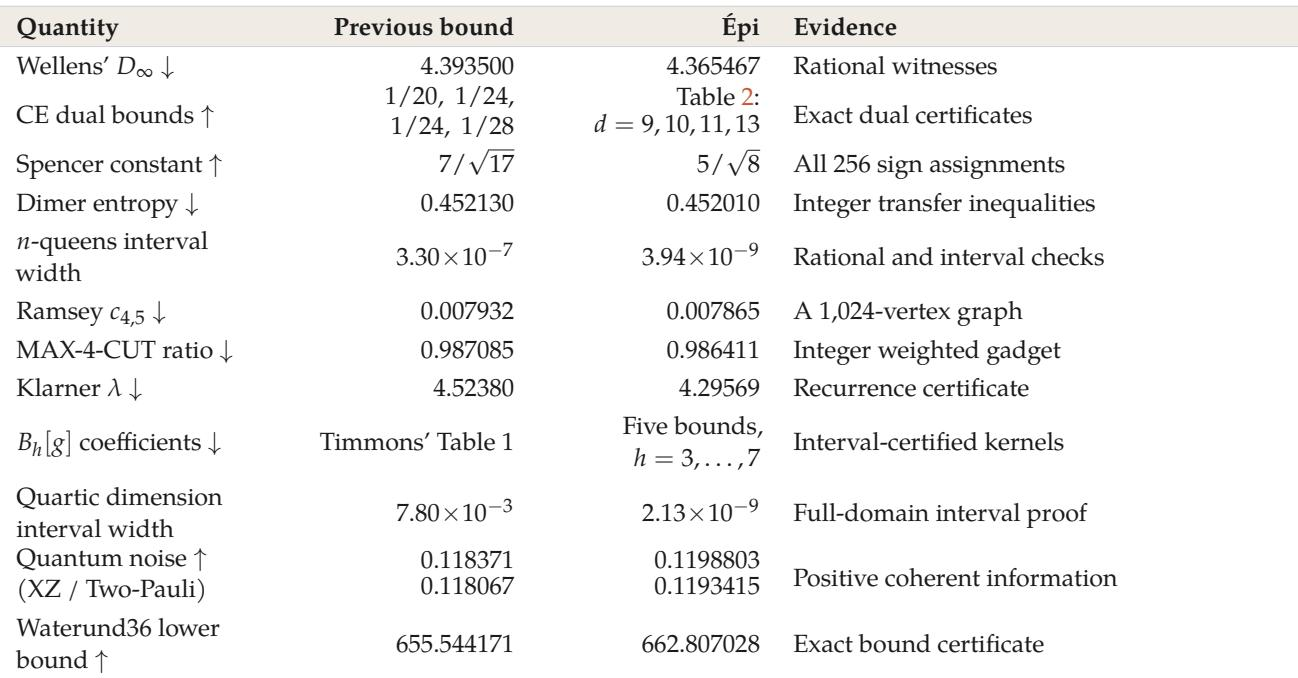
The reported numerical records show tighter bounds across several families, with each entry pointing in its improving direction. Several interval widths are also reduced, indicating more concentrated numerical estimates. The improvements are supported by diverse forms of evidence, including rational witnesses, exact certificates, exhaustive checks, inequalities, and explicit constructions. Several bound families are tightened in their stated improving directions. The supporting evidence is varied, including rational witnesses, dual certificates, exhaustive assignments, integer inequalities, and graph or gadget constructions.
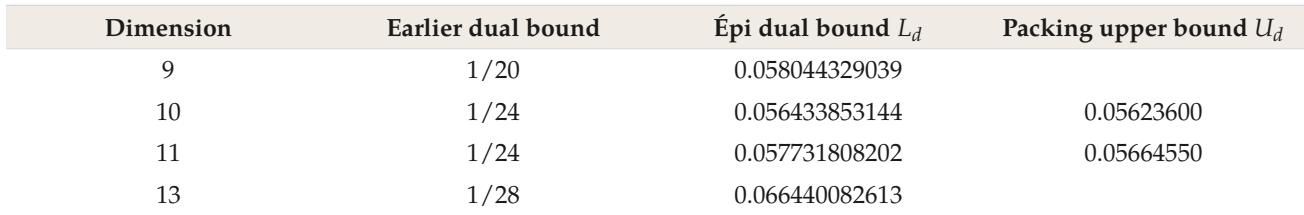
The reported center-density lower bounds from the Épi dual approach improve on the earlier dual bounds in dimensions 9, 10, 11, and 13. In dimensions 10 and 11, the new lower bounds exceed the corresponding packing upper bounds even with conservative rounding, giving a strict separation between packing density limits and the best Cohn-Elkies bound. Dimensions 9 and 13 are included as improved lower-bound cases, but the shown values do not establish the same separation. The new Épi dual bounds are stronger than the earlier dual bounds in every listed dimension. In dimensions 10 and 11, the lower bounds exceed packing upper bounds, showing that the Cohn-Elkies method is not tight there.
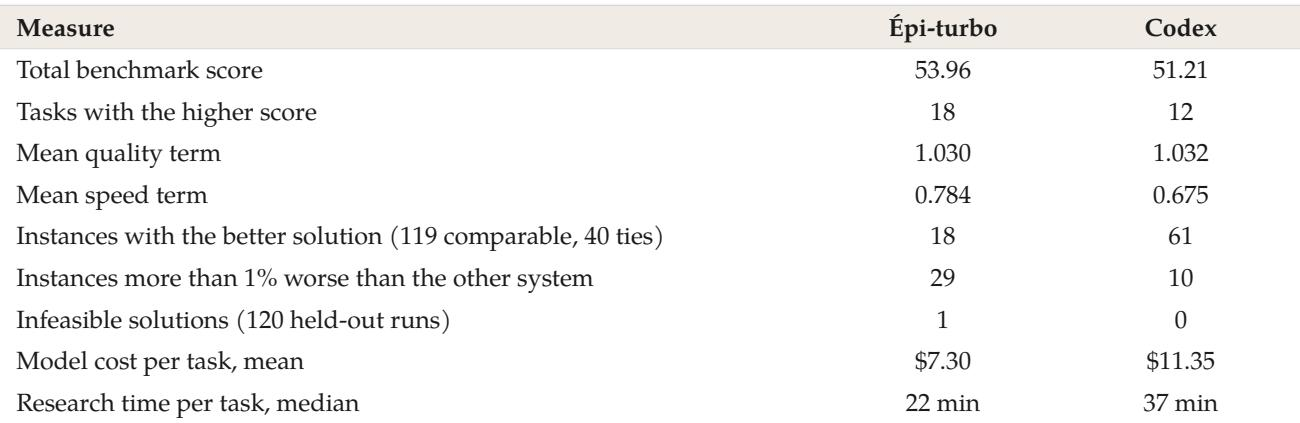
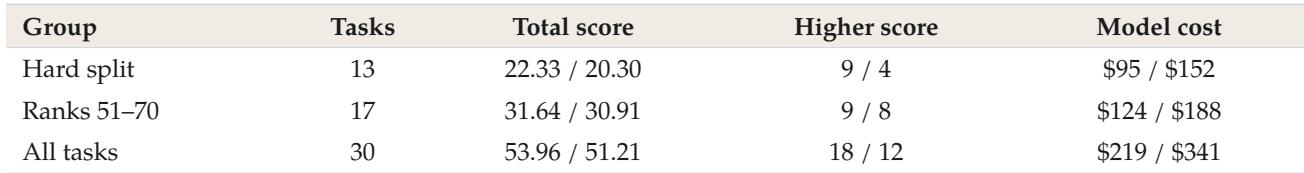
On FrontierOR tasks, Épi-turbo achieves a higher overall benchmark score than Codex while using less model budget. Its advantage comes mainly from faster held-out programs and more frequent task-level wins, with gains exceeding losses. The speed advantage also helps offset cases where solution quality is similar or slightly lower. Épi-turbo scored higher on more tasks and produced larger aggregate gains than its losses. Its generated programs ran faster during held-out evaluation, making speed a key source of the score difference.
The results show that Epi-turbo has a slightly higher overall score than Codex across the task set while using substantially less model cost. Its advantage is clearer on the hardest task group, where its aggregate score is about 10 percent higher and it wins more tasks than it loses, while the middle ranked tasks are much closer. The pattern suggests that much of the score gain comes from faster generated programs rather than only better solutions. Epi-turbo has the higher total score across all tasks while spending much less than Codex. On the hardest task group, Epi-turbo wins most tasks and has a clearly higher aggregate score. The score gap narrows on the middle ranked tasks, where the two systems are close. Several tasks show Epi-turbo combining a higher score with lower model cost. Faster execution helps Epi-turbo's score, while long runs can reduce Codex's speed advantage.
Across tasks with the largest score differences favoring Épi-turbo, generated programs cover diverse optimization areas including routing, scheduling, planning, and clustering. The advantage is often driven by faster execution, while solution quality remains comparable or better in several highlighted cases. These selected examples also align with broader results showing that Épi-turbo frequently uses less model cost than Codex. Speed is a major source of advantage, because Épi-turbo programs often run well below the runtime used by Codex. Solution quality is strong in several cases, with Épi-turbo matching references or producing better solutions. The selected wins span many problem types, showing broad practical relevance. Model costs are often lower for Épi-turbo in these comparisons.
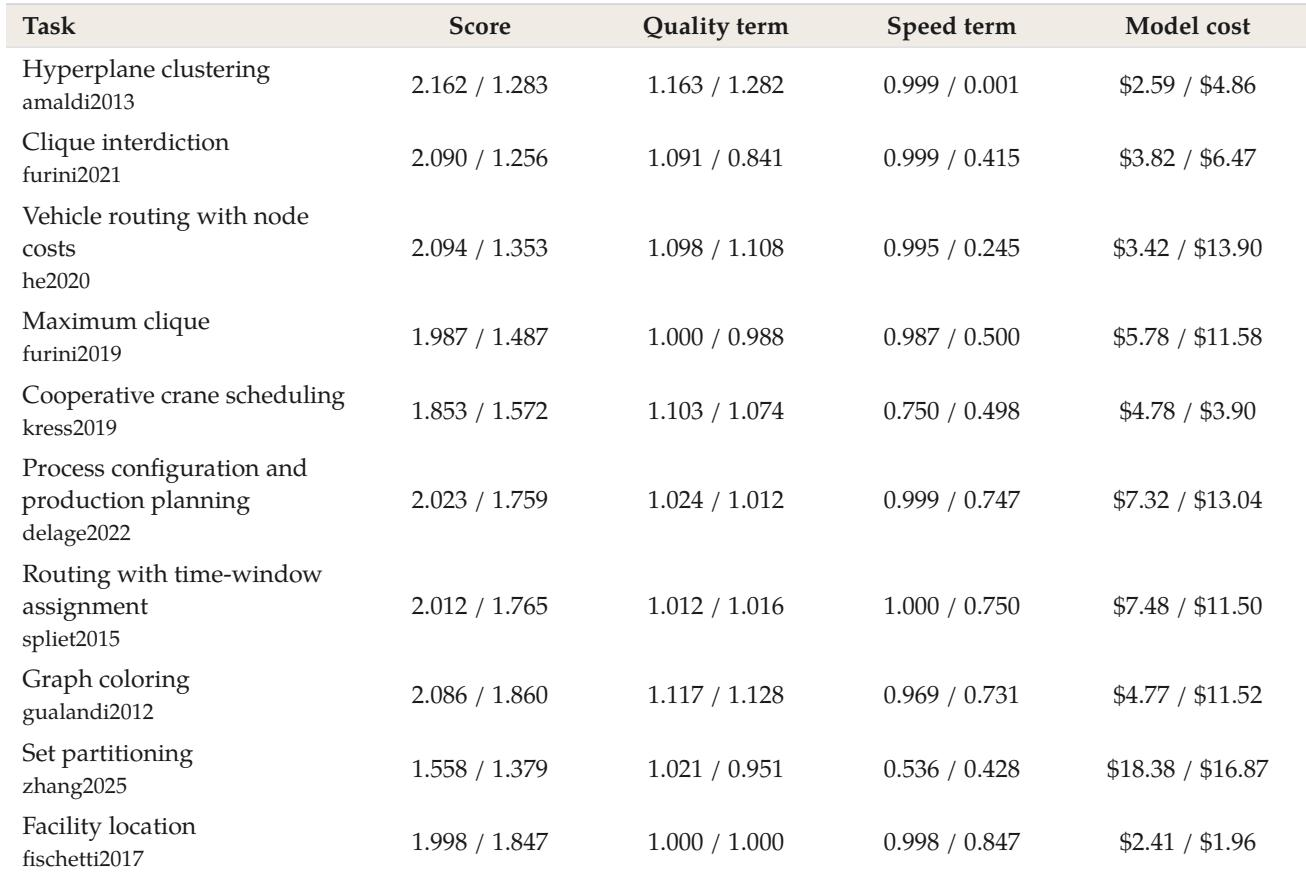
The experiments validate the approach through tighter numerical bounds, more concentrated interval estimates, and stronger center-density lower bounds obtained from the Épi dual framework, with improved separation in selected dimensions. They also evaluate FrontierOR tasks, where Épi-turbo achieves a higher overall score than Codex at lower model cost, especially on harder tasks and broader optimization settings. The qualitative results indicate that faster generated programs are a major source of advantage, while solution quality remains comparable or better across diverse cases.