Command Palette
Search for a command to run...
DiscoveryRSI: 귀중한 가설 발견을 위한 재귀적 학습
DiscoveryRSI: 귀중한 가설 발견을 위한 재귀적 학습
초록
과학적 발견은 가치 있는 가설을 실질적인 연구로 발전시켜야 하지만, 이 진화하는 연구 과정으로부터 학습하는 것은 여전히 어려운 과제이다. 본 논문은 가치 있고 검증 가능한 연구 가설의 조작적 정의를 제시한다. 이는 중요한 불확실성에 대한 증거 기반 주장이며, 실행 가능한 조사, 명시적 의사결정 기준, 대안적 설명이 결합된 것이다. DiscoveryRSI 프레임워크는 다중 에이전트 진화적 탐색을 통해 가설 트리를 성장시키고, 선택된 조사를 실행 가능한 Harbor 과업으로 컴파일하며, 가설 기여도 최적화(hypothesis credit optimization), harness replay, 재발견(rediscovery)의 세 가지 메커니즘을 통해 재귀적으로 학습한다. 가설 기여도 최적화는 문서화된 연구 공헌도에 과학적 평가를 할당한다. harness replay는 생산적 전략과 반복적 실패를 식별하여 연구 워크플로를 정제한다. 재발견은 수용된 개선 사항을 새로운 조사에 적용하여 후속 학습을 위한 추가 경험을 생성한다. 또한 DFM-Bench를 도입하는데, 이는 가설, 수정, 개발 경로 및 연구 실행 단계에서 가설의 질과 누적적 연구 진전을 포괄적으로 평가한다. 네 개의 생명과학 도메인에서 자동 평가 결과, 기본 모델의 가설 질은 4.86에서 두 차례의 자기 개선 이후 5.39로 상승하며, 특히 반증 가능성과 데이터 판별 가능성에서 큰 향상이 나타난다. 또한 전문가 검토를 통해 가설 질을 추가로 검증하며, DiscoveryRSI-27B를 다른 연구 에이전트와 비교한다. 예비 인간 평가에 따르면, DiscoveryRSI-27B는 GPT-6 Luna보다 가설의 중요성, 주장의 타당성, 주장이 증거에 의해 한정되는 정도에서 더 높은 점수를 얻는다. DiscoveryRSI-27B는 모델 컷오프 이후 출판된 연구와의 가설 부합률이 6.3%로, GPT-6의 2.5%와 Claude Opus 5의 2.3%를 크게 상회하며, 연구 경로를 따라 인간 평가 기준 더 큰 향상을 제공한다.
One-sentence Summary
PhAI Labs, The Chinese University of Hong Kong, University of Michigan, et al. propose DiscoveryRSI, which recursively improves research agents by building evidence-grounded hypothesis trees through multi-agent evolutionary search, compiling investigations into executable Harbor tasks, and refining workflows via hypothesis credit optimization, harness replay, and rediscovery, thereby improving hypothesis quality on DFM-Bench across four life-science domains from 4.86 to 5.39 after two rounds.
Key Contributions
-
The paper introduces DiscoveryRSI, a framework that defines valuable research hypotheses as evidence-grounded claims about consequential uncertainties, coupled with feasible investigations, explicit decision criteria, and alternative explanations. It develops hypothesis trees through multi-agent evolutionary search, compiles selected investigations into executable Harbor tasks, and recursively learns via hypothesis credit optimization, harness replay, and rediscovery.
-
The paper also introduces DFM-Bench, which assesses hypothesis quality and cumulative research progress at the levels of individual hypotheses, revisions, development paths, and complete research runs.
-
Across four life-science domains, automated evaluation shows DiscoveryRSI raising hypothesis quality from 4.86 for the base model to 5.39 after two self-improvement rounds, with gains in falsifiability and data resolvability. DiscoveryRSI-27B achieves a 6.3% post-cutoff hypothesis correspondence rate, compared with 2.5% for GPT-6 and 2.3% for Claude Opus 5, and receives higher expert-rated hypothesis importance than GPT-6 Luna.
Introduction
The authors focus on AI research agents that generate hypotheses, plan investigations, and execute computational experiments. This matters because scientific discovery depends on turning proposed explanations into testable studies and then using that experience to design better future research. Prior systems can propose and evaluate hypotheses, but they often treat the final proposal as the learning target, obscuring which revisions, evidence, or agent actions actually improved the work, and they struggle to make evolving hypotheses concrete enough to execute. The authors contribute DiscoveryRSI, a framework that builds research trees of testable hypotheses, compiles selected investigations into executable Harbor tasks, preserves full development histories, and uses hypothesis credit optimization, harness replay, and rediscovery to learn recursively from documented contributions. They also introduce DFM-Bench to measure hypothesis quality, revision value, and cumulative research progress.
Dataset
-
The provided text describes evaluation data rather than a conventional training corpus. The authors use DFM-Bench to make scientific assessment objects explicit, including generated hypotheses, revisions, development paths, research runs, and contribution families. This allows evaluation of evidence use, experimentation, and research-process integrity alongside existing scientific benchmarks.
-
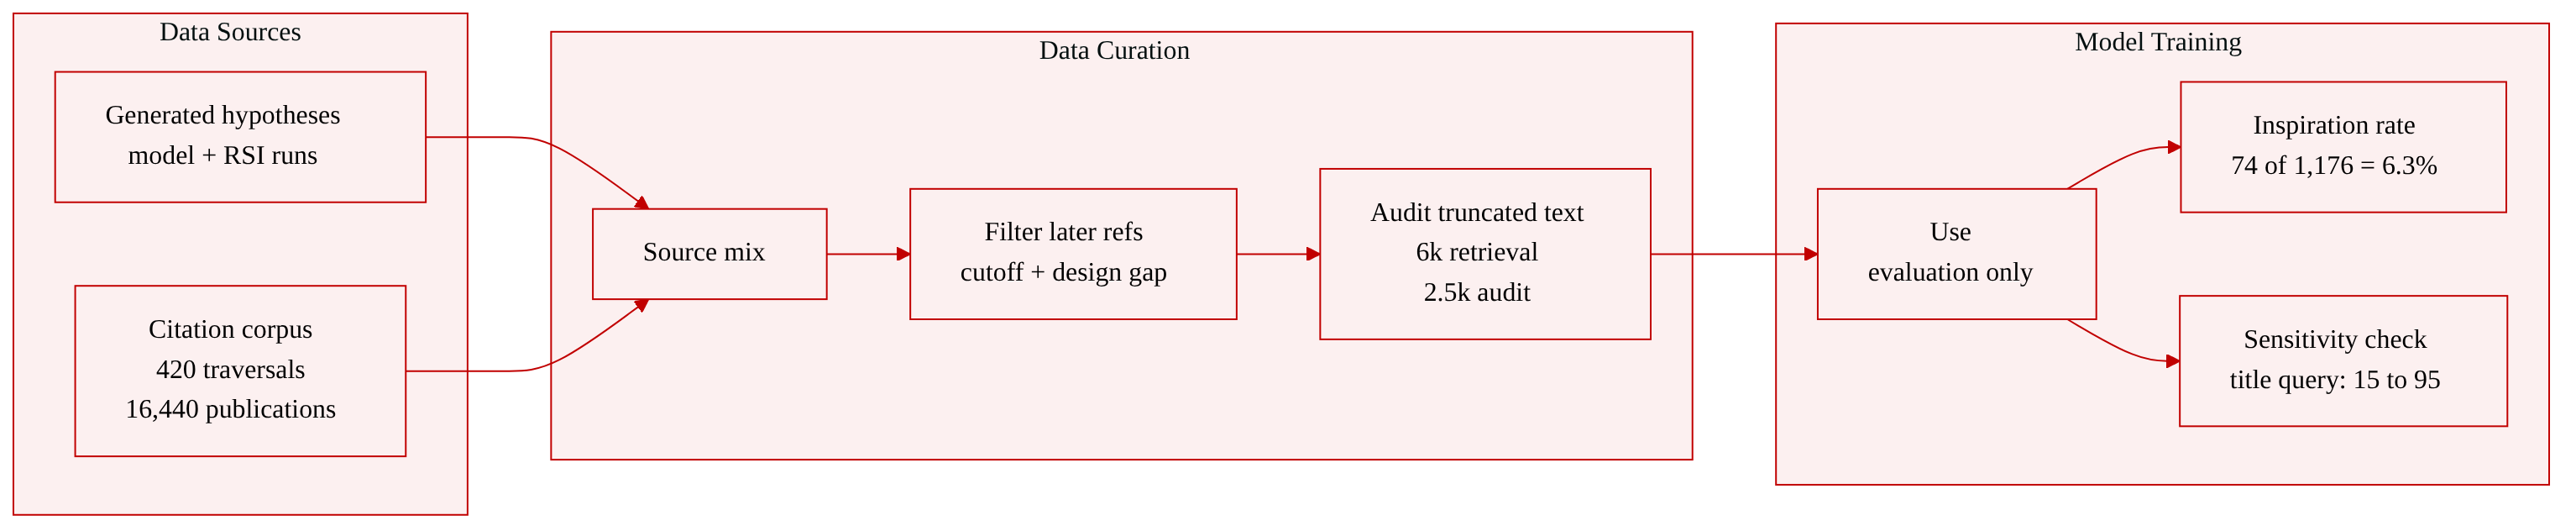
The inspiration analysis uses generated hypothesis versions grouped by model. Reported group sizes are 257 for DeepSeek, 36 for GLM, 2,341 for GPT, and 131 for Claude. A pooled DiscoveryRSI set from two production runs contains 1,176 hypothesis versions, and the authors also report inspiration rates by domain, including therapeutic targets, population multi-omics, disease mechanisms, and clinical and population health.
-
The literature reference corpus is built from 420 backward and forward citation traversals. This produces 17,790 citation edges and 16,440 resolved publications. The authors filter the resolved references using each model group’s recorded cutoff, so only later literature can qualify as an inspiration match.
-
The filtering rule is strict. A post-cutoff publication is counted only if it provides an experimental design, comparator, measurement, or testable evidence gap relevant to developing or testing the generated hypothesis. The authors then assign an automated positive judgment to qualifying hypothesis versions and compute the inspiration rate as the proportion of generated versions with a positive judgment.
-
Cropping is part of the processing pipeline. Retrieval uses the first 6,000 characters of a proposal, and the semantic audit reads only the first 2,500 characters. This can move scientific content away from the evaluated text when proposals contain extensive provenance or revision notes. The authors show this sensitivity with a diagnostic where querying by proposal title increases Claude’s retrieved proposal count from 15 to 95.
-
The data are used for evaluation and diagnostic analysis, not for reported model training. In the supplied excerpts, there is no described training split, mixture ratio, or training use for these datasets. Their role is to support hypothesis generation comparison, literature citation analysis, inspiration-rate measurement, and auditing of how retrieval coverage and proposal format affect measured outcomes.
Method
The authors introduce a joint operational definition of valuable and testable research hypotheses for hypothesis driven research agents. A research hypothesis is represented as H=(c,π,d,a), where c is a claim grounded in evidence, π is an investigation plan, d specifies decision criteria, and a identifies relevant alternative explanations. It is considered valuable if resolving its uncertainty adds to current understanding, and testable if the plan is feasible under given constraints and its outcomes can support or weaken the claim.
As shown in the figure below, this definition is instantiated with a concrete proposal.
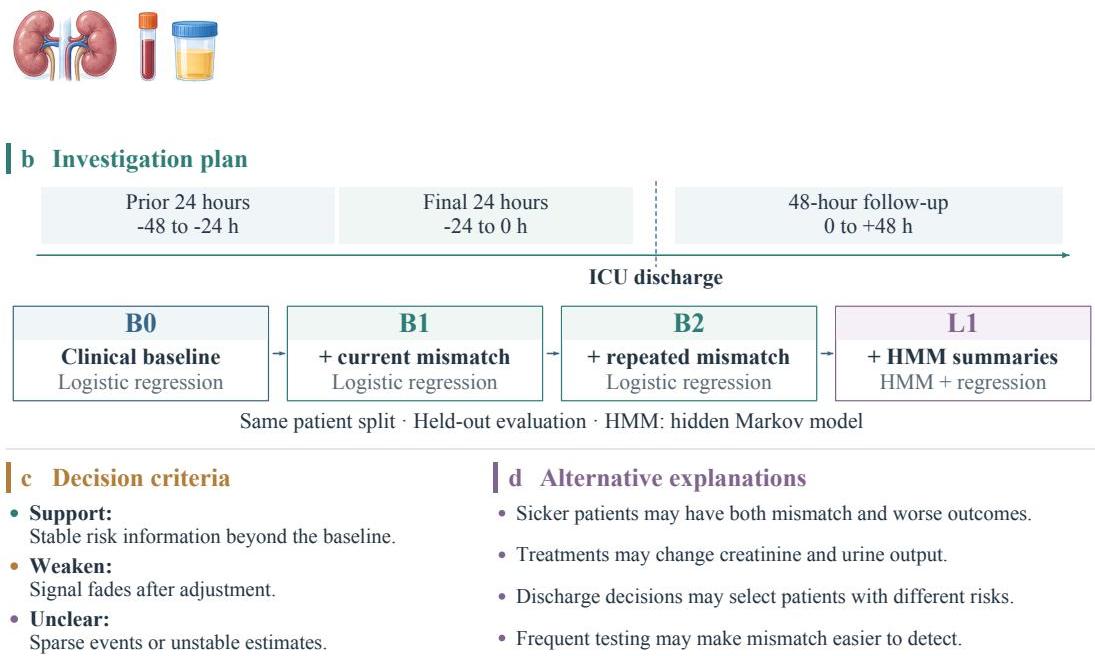
The figure illustrates a MIMIC IV proposal investigating whether repeated creatinine and urine output mismatch adds information about adverse outcomes after ICU discharge. The investigation plan defines the timeline, baseline models, and comparisons, while the decision criteria and alternative explanations explicitly bound the claim and interpretability of the results.
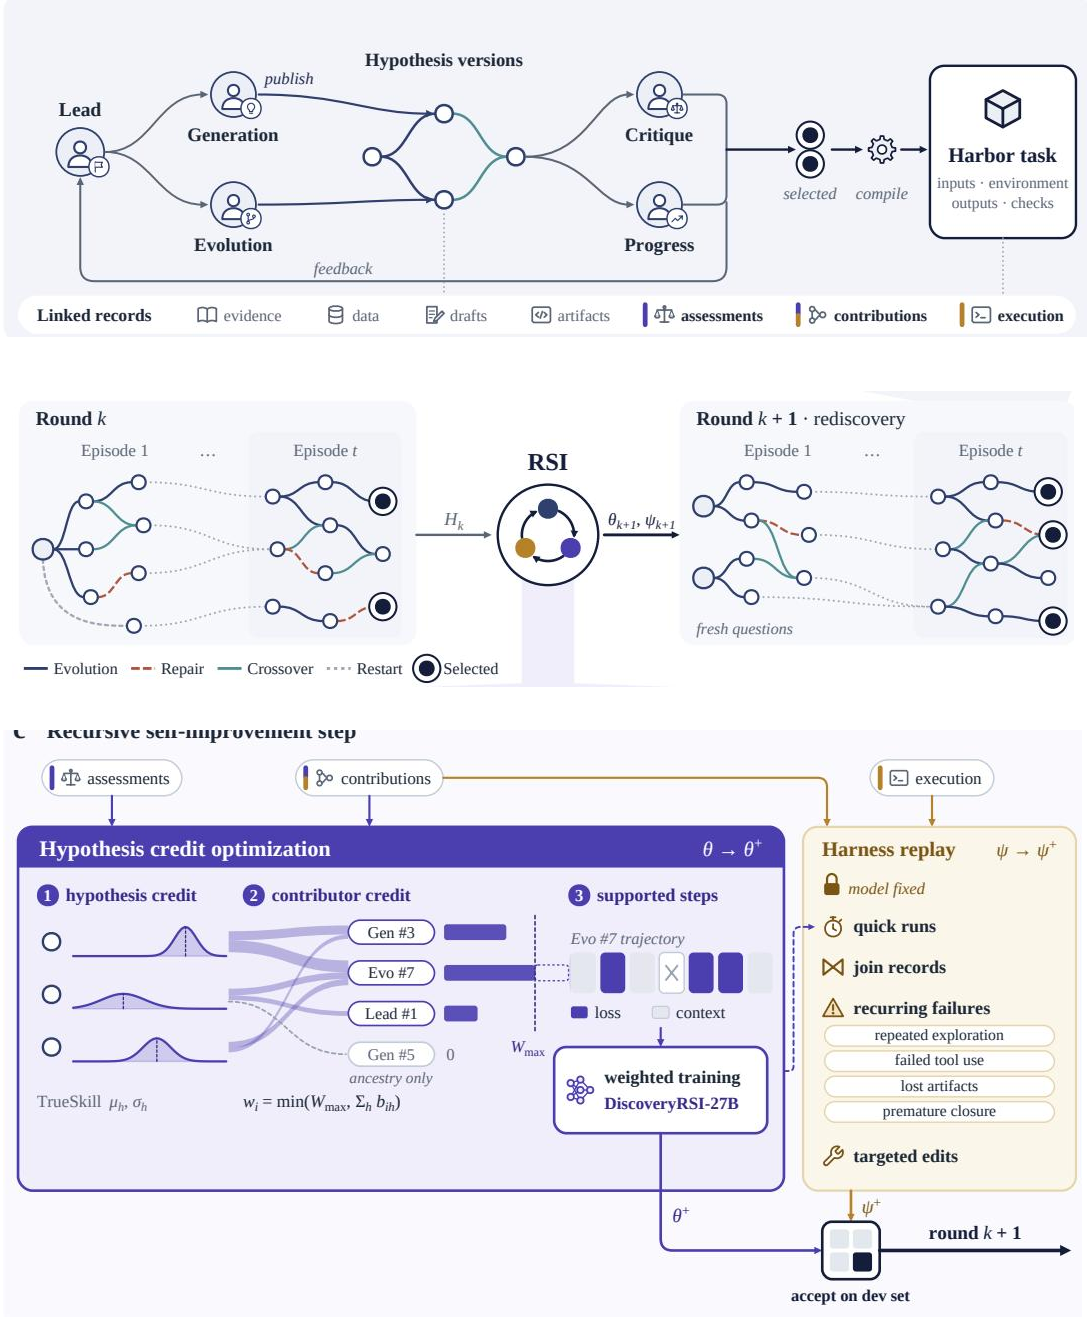
To turn hypothesis development into a recursive learning process, the authors propose DiscoveryRSI. This framework develops research trees of testable hypotheses through multiple agent evolutionary search and retains the evidence and decisions behind each proposal.
As shown in the figure below, the framework couples multiple agent hypothesis development with recursive self improvement.
In the hypothesis development phase, a Lead agent directs Generation and Evolution agents to create or revise hypotheses. These versions are evaluated by Critique and Progress agents. Selected hypotheses are compiled into executable Harbor tasks, which include concrete inputs, environments, required outputs, and verification checks, preserving the scientific commitments of the original proposal.
The retained research histories support three coupled recursive improvement mechanisms. First, Hypothesis Credit Optimization links assessments of research quality to documented contributions. Blinded Critique provides preferences, which are summarized using TrueSkill to estimate relative preference strength zh and uncertainty. The probability of preference is modeled as:
P(a≻b∣za,zb)=Φ(2βza−zb−ε)Assessment coverage, uncertainty, validity, and progress determine a bounded hypothesis weight wi=min(Wmax,∑hbih), where bih is the allocation from hypothesis h after contributor sharing and duplicate suppression. This credit controls how strongly a history contributes to training. The authors train DiscoveryRSI 27B using a weighted loss function:
L(θ)=−i∑∣Ui∣ωiu∈Ui∑logπθ(aiu∣xiu)where Ui contains eligible assistant token positions, xiu is the recorded context, and ωi combines contributor credit with domain balancing.
Second, Harness Replay improves the research workflow while holding model weights fixed. By analyzing agent contribution and decision records alongside execution logs, the system identifies recurring failures such as repeated exploration or lost artifacts. Candidate harness edits are proposed and evaluated through quick runs and matched development evaluation to determine acceptance.
Finally, Rediscovery applies accepted model and harness updates to fresh investigations. The acceptance procedure evaluates qualifying updates separately and jointly, allowing the model, harness, both, or neither to change. The accepted system then returns to fresh questions, collecting new hypotheses and evidence, thereby completing the recursive learning cycle.
Experiment
The experiments use DFM-Bench to evaluate generated research at the levels of individual hypotheses, revisions, development paths, full runs, and scientific contributions, combining automated quality judgments, expert human review, and literature-based inspiration checks across biomedical and battery domains. Across iterative research rounds, hypothesis quality improves mainly through better testability, clearer evidence requirements, and more disciplined revision behavior, while models increasingly evolve existing hypotheses instead of restarting them. Expert reviewers recognize more favorable progress from revisions, although absolute proposal quality remains mixed and inspiration findings are descriptive, indicating promising but uneven scientific value.
The comparison evaluates how selected scientific-discovery benchmarks explicitly assess scientific outputs and research processes. Existing benchmarks provide complementary but narrower coverage, with OEB offering explicit assessment of evidence use and revision and partial coverage of development paths and whole-run allocation, while DFM-Bench is presented as covering all listed scientific and research-process dimensions. The comparison defines coverage through explicit assessment objects rather than the mere recording of intermediate actions. DFM-Bench is described as explicitly assessing hypothesis merit, contribution maturity, evidence use, revision, development paths, and whole-run allocation. OEB gives the strongest research-process coverage among the other listed benchmarks, while AgentIdeaBench gives the clearest prior hypothesis-merit assessment. The comparison distinguishes explicit coverage from partial or related coverage and emphasizes that intermediate actions must be assessment objects to count.
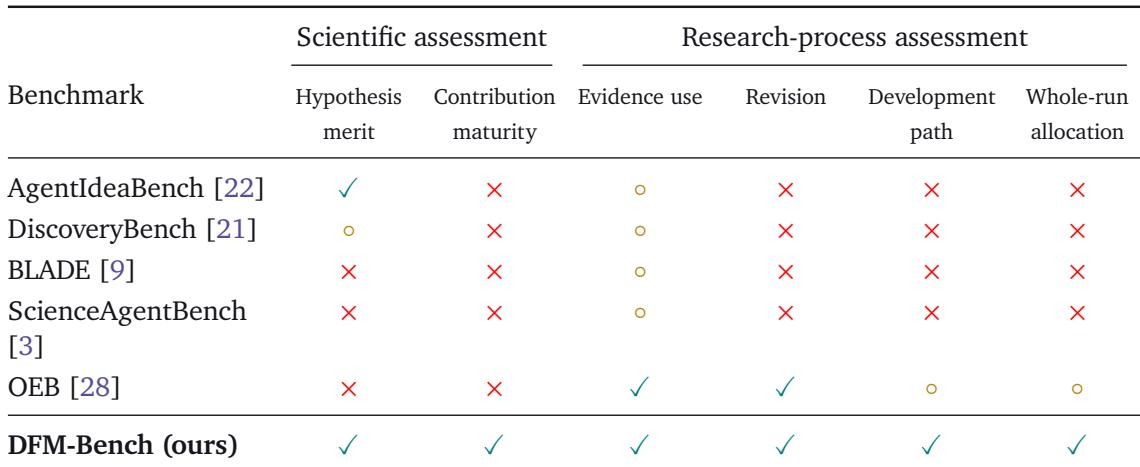
The experiment compares scientific-discovery benchmarks by evaluating which ones explicitly assess scientific outputs and research-process dimensions, such as hypothesis merit, evidence use, revision, development paths, and whole-run allocation. It finds that DFM-Bench provides the broadest explicit coverage, while OEB offers the strongest research-process assessment among the other benchmarks and AgentIdeaBench is clearest on prior hypothesis merit. The comparison emphasizes that only dimensions treated as explicit assessment objects should be counted, rather than merely recorded intermediate actions.