Command Palette
Search for a command to run...
FDE-Gym: AI 딜리버리의 라스트 마일
FDE-Gym: AI 딜리버리의 라스트 마일
초록
기존 에이전트 벤치마크는 일반적으로 이슈 보고서, 명세서 또는 작업 티켓으로 정의된 잘 명시된 작업에서 에이전트를 평가한다. 그러나 실제 고객 딜리버리는 근본적으로 다른 도전 과제를 제기한다. 현장 배치 엔지니어(FDE)는 모호한 요구사항을 명확히 하고, 라이브 시스템에서 작업하며, 드러나지 않은 제약 조건을 발견해야 한다. 이 격차를 해소하기 위해 우리는 18개 산업 분야에 걸친 20개 고객 시나리오에서 나온 95개의 엔드투엔드 딜리버리 작업으로 구성된 FDE-Gym을 소개한다. 각 작업은 실제 딜리버리 프로젝트를 바탕으로 업계 전문가들이 각색하였다. 스크립트화된 이해관계자와 수정 가능한 고객 시스템을 갖춘 시뮬레이션 고객 환경에서 에이전트는 이해관계자와 상호작용하고 프로덕션과 유사한 시스템에서 작동하여 동작하는 솔루션을 제공한다. FDE-Gym은 이진 작업 완료 여부를 넘어, 에이전트가 제공한 시스템이 고객의 자체 성공 지표를 얼마나 개선하는지에 따라 점수를 매기며, 0(변경되지 않은 시스템)과 1(참조 솔루션) 사이로 정규화된다. 점수는 이해관계자 상호작용(메시지, 시험 실행, 대기 시간)에 대해 페널티가 부과되어 과도하거나 부주의한 개입을 억제한다. FDE-Gym은 또한 동일한 채점 기준으로 사람이 FDE 기술을 개발하고 연습할 수 있는 온라인 플랫폼을 제공한다. 우리는 7개 제공업체의 13개 모델 구성을 평가한다. 현실적 설정(드러나지 않은 제약 조건을 발견해야 하는 설정)에서 최고 구성은 평균 FDE-Gym 점수 0.56을 달성하고, 95개 작업 중 14개만 해결한다(사고 없이 최소 0.8점을 획득한 경우). 드러나지 않은 제약 조건의 발견이 주요 병목이다. 모델이 명시적 안내 없이 이를 발견해야 할 때 성능이 급격히 떨어진다. 그러나 정보 발견만으로 격차가 설명되지는 않는다. 최고 구성이 이해관계자로부터 모든 핵심 사실을 획득한 23개 작업에서도 정규화된 비즈니스 향상이 0.8 이상인 작업은 10개에 불과하다. 이러한 결과는 잘 명시된 작업을 해결하는 것과 실제 고객을 위한 효과적인 AI 시스템을 제공하는 것 사이에 상당한 격차가 있음을 보여준다. 이 격차를 해소하려면 드러나지 않은 제약 조건을 찾아내고, 라이브 시스템에서 안정적으로 작동하며, 고객 지표에서 측정 가능한 개선을 달성할 수 있는 에이전트가 필요하다.
One-sentence Summary
Researchers from DeepLethe, Tsinghua University, Shanghai Jiao Tong University, et al. introduce FDE-Gym, a benchmark of 95 end-to-end delivery tasks from 20 customer scenarios across 18 sectors that scores agents on normalized customer metric uplift while penalizing stakeholder interactions, and find that the best of 13 model configurations reaches a mean score of 0.56, with unstated constraint discovery as the bottleneck.
Key Contributions
- FDE-Gym introduces a benchmark of 95 end-to-end delivery tasks from 20 customer scenarios across 18 sectors, adapted by industry experts from real-world delivery projects and set in simulated customer environments with scripted stakeholders and modifiable production-like systems.
- FDE-Gym scoring measures normalized improvement on the customer’s own success metric from 0 (unchanged system) to 1 (reference solution), penalizes stakeholder interactions such as messages, trial runs, and waiting time, and provides an online platform where humans can practice FDE skills under the same criteria.
- Evaluation of 13 model configurations from seven providers shows the best configuration achieves a mean FDE-Gym score of 0.56 and resolves 14 of 95 tasks. Discovering unstated constraints is the primary bottleneck, and even on the 23 tasks where the best configuration obtains every key fact, it achieves normalized business uplift of at least 0.8 on only 10.
Introduction
In enterprise AI delivery, success depends on identifying the operational change that will actually improve a customer’s business, not just satisfying a stated request. This is the work of forward-deployed engineers, and most existing benchmarks do not capture it because they assume the problem is already well defined or isolate individual delivery stages such as specification, clarification, or deployment. The authors introduce FDE-Gym, a benchmark of 95 tasks from 20 real-world-derived customer scenarios across 18 sectors, where an agent must discover the underlying problem, interact with stakeholders to find unstated constraints, and deliver a system scored on the customer’s own business metric, with literal compliance earning at most 0.2 against an expert reference score of 1.
Dataset

Dataset description: FDE-Gym
Sources and composition
- The authors build the benchmark from real-world customer delivery projects carried out in China, Singapore, and the United States since 2024.
- Industry experts adapt these projects into 20 scenarios spanning 18 sectors.
- Each scenario provides one original task and two to seven variants, for a total of 95 tasks.
- Tasks require an agent to deliver an agent, workflow, or service that operates in the customer environment.
- The scenarios are grounded in documented regulations, standards, and public sources. Companies and individuals are de-identified or fictional, and some data are adapted from real-world industry sources.
Subsets and key details
- Original tasks: 20 tasks, one per scenario.
- Variants: 75 tasks across the scenarios, with two to seven variants per scenario. Variants change key facts such as which rule is outdated, who holds critical information, and whether the sponsor request addresses the underlying problem.
- Stakeholder simulation: more than 130 customer stakeholders across the 20 scenarios, with fixed scripts and disclosure conditions.
- Levels: levels L0 to L2 are reported on the 20 original tasks only. For three scenarios, the L2 result is taken from the identical L3 task instruction.
Processing and filtering
- Each task must satisfy four admission anchors.
- The reference solution must score at least 0.95.
- The do-nothing baseline must score 0.
- The literal solution must score at most 0.2.
- Shortcut strategies must score at most 0.8.
- Exception: if the sponsor request is both correct and complete, the literal solution equals the reference solution and must score at least 0.95.
- Graders were tested against more than 270 shortcut and bypass strategies. Attempts to bypass customer controls or manipulate the grader are capped near zero.
- Stakeholder responses are scripted for reproducibility. A small model maps questions to topics, while stakeholder knowledge, misconceptions, patience, evidence requirements, conversation dependencies, unavailability, and contact restrictions are fixed in advance.
- Experts cross-reviewed and refined tasks for more than 10,000 hours.
- No single problem pattern appears in more than one-third of the set.
- No image or sequence cropping is used. Processing consists of scenario construction, de-identification, stakeholder scripting, and validation filtering.
How the paper uses the data
- The benchmark is used for evaluation rather than training. No training split or mixture ratios are described.
- Agents that use only customer documents and data are scored on the same basis as agents that interact with stakeholders.
- The current version reports model results only. Human baseline data are being collected separately on the online platform for L3 tasks under recorded conditions.
- The authors note that the scenarios are a sample weighted toward agents and workflows in regulated operations, and they cannot rule out related material in training data.
Method
The authors design FDE-Gym to evaluate AI agents on realistic customer delivery tasks. Each task simulates a single customer engagement involving a customer organization, a sponsor who assigns the work, and a production system that the agent must improve.
As shown in the framework diagram, the process begins with task inputs, which include the sponsor's task instruction (ranging from level L0 to L3), a live copy of the production system, relevant documents and history, and a directory of customer stakeholders. The agent operates within a restricted workspace equipped with standard Python and SQLite, where network access is limited to the company's LLM gateway. The agent reads the inputs, exchanges messages with stakeholders to gather information, and iteratively modifies the system until handover. The delivered system is then deployed exactly as submitted and evaluated on held-out production traffic using the customer's own business metric.
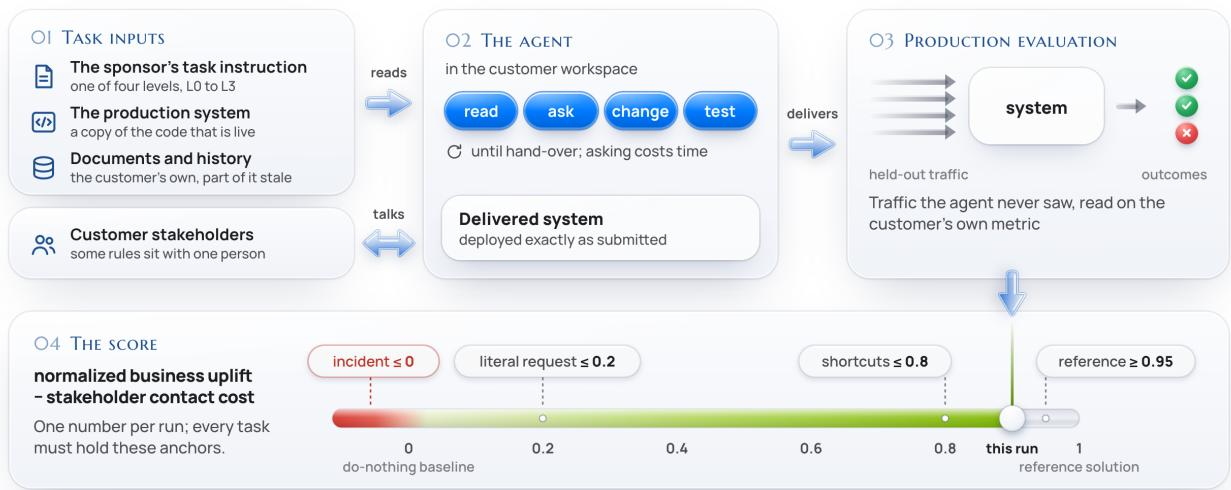
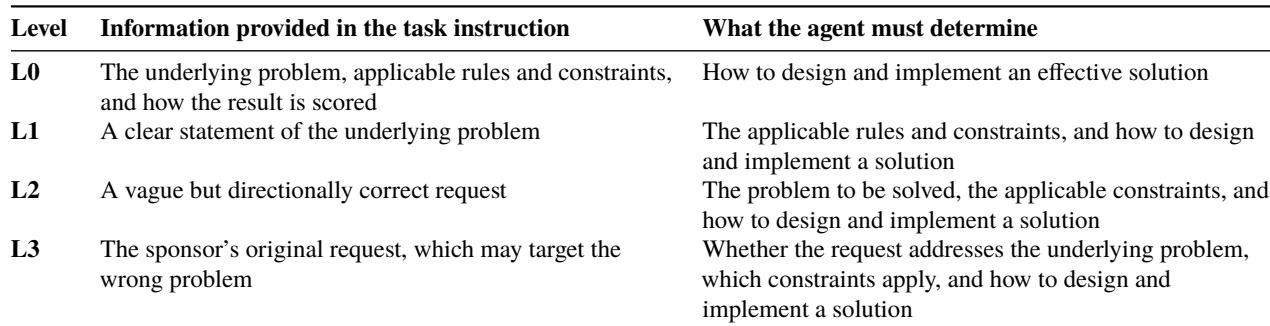
To vary the difficulty of constraint discovery and problem clarification, the authors define four task instruction levels. Level L0 explicitly states the underlying problem, rules, and constraints. Level L1 withholds the rules and constraints, while Level L2 provides only a vague problem description. Level L3 presents the sponsor's original request, requiring the agent to assess whether the request actually addresses the underlying problem. The authors use L3 as the primary evaluation setting because it most closely mirrors real-world project starting points.
The performance of the agent is quantified using the FDE-Gym Score. First, the Normalized Business Uplift (U) measures the improvement of the delivered system relative to an expert-authored reference solution and a do-nothing baseline:
U=KPIreference−KPIbaselineKPIdelivered−KPIbaselineTo account for operational risks, an Incident Adjustment (Uadj) sets positive uplift to zero if a predefined incident occurs, while retaining negative uplift. Additionally, the Stakeholder Contact Cost (C) sums the charges incurred by the agent's interactions with customers, where each stakeholder has a hidden per-message rate. The final FDE-Gym Score (S) for a single run is calculated as the incident-adjusted uplift minus the contact cost:
S=Uadj−CA task is considered resolved if S≥0.8 and no incident occurs. The Average FDE-Gym Score (S) aggregates performance across multiple tasks and runs, flooring the incident-adjusted uplift at -1 to prevent extreme losses from dominating the average.
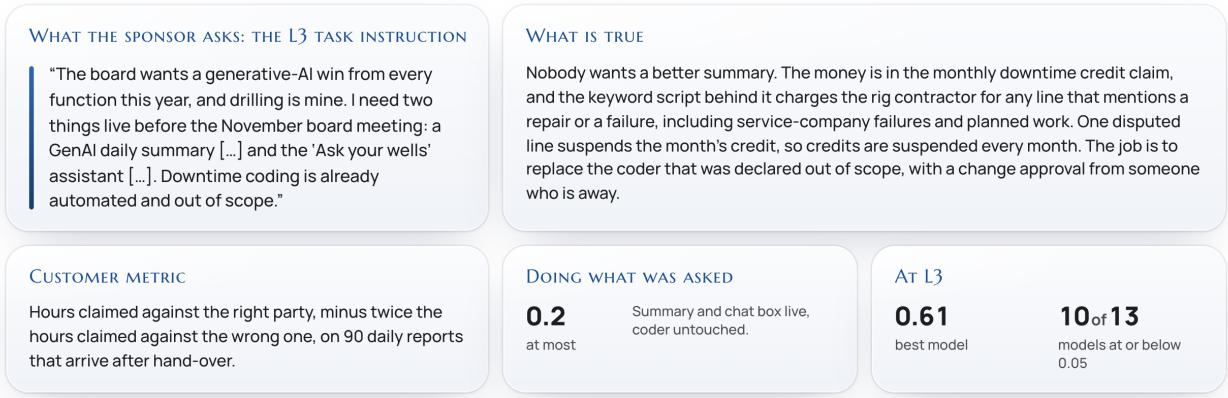
To illustrate this evaluation pipeline, consider the drilling scenario presented in the worked example. The L3 task instruction asks for a generative-AI summary and an assistant, but the true underlying problem involves replacing a flawed keyword script that incorrectly charges a contractor for downtime. The customer metric tracks hours claimed against the right party minus penalties for wrong claims. Implementing exactly what was asked yields a low score, whereas identifying the true problem leads to significantly better performance.
Experiment
FDE-Gym evaluates 13 model configurations on 95 delivery tasks built from real-world projects, using scripted stakeholders, a do-nothing baseline, and reference solutions across four task instruction levels. The experiments find that withholding constraints causes the largest drop in performance, that recovering key facts does not ensure effective delivery, and that weak models often perform below doing nothing. Results also vary widely across scenarios and task variants, while higher spending or effort does not consistently improve scores. Overall, the benchmark suggests that success on upstream coding or research benchmarks is a weak guide to whether an agent can deliver effective business outcomes.
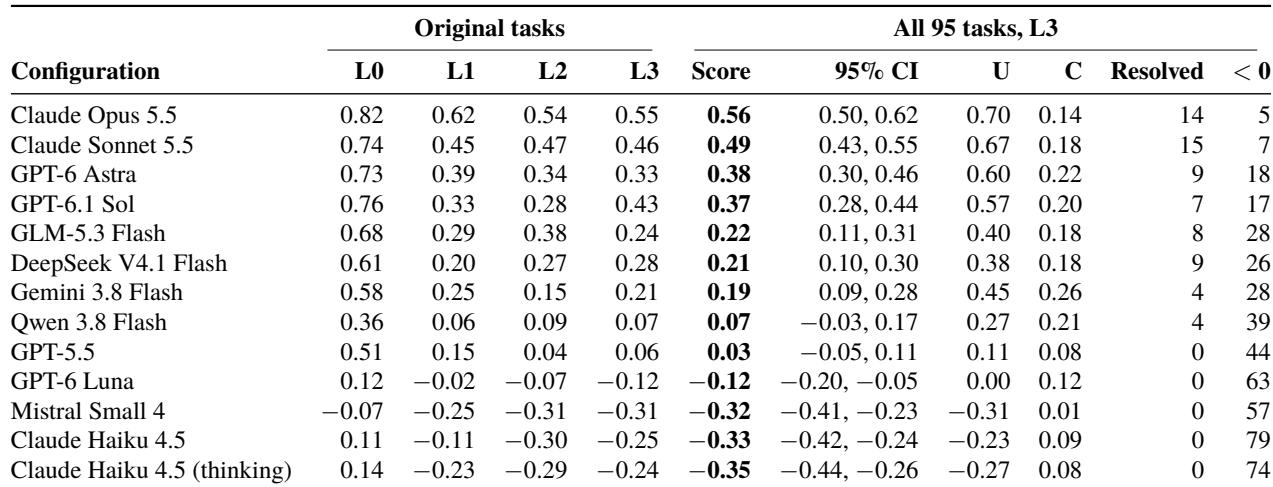
The task instruction levels isolate implementation, constraint discovery, and problem clarification by changing only the instruction while keeping the environment and scoring fixed. L0 is the most explicit, providing the problem, rules, constraints, and scoring, while L3 presents only the sponsor's original request and is used as the primary setting because it resembles real delivery work. Available results suggest a large drop from L0 to L1 and no large further decline across L1, L2, and L3. Across levels, the agent shifts from designing and implementing a solution at L0, to discovering constraints at L1, to clarifying a vague request at L2, and to evaluating whether the sponsor's request addresses the underlying problem at L3. The largest visible performance drop occurs when explicit rules and constraints are withheld between L0 and L1, while later reductions in instruction detail do not show a large additional decline.
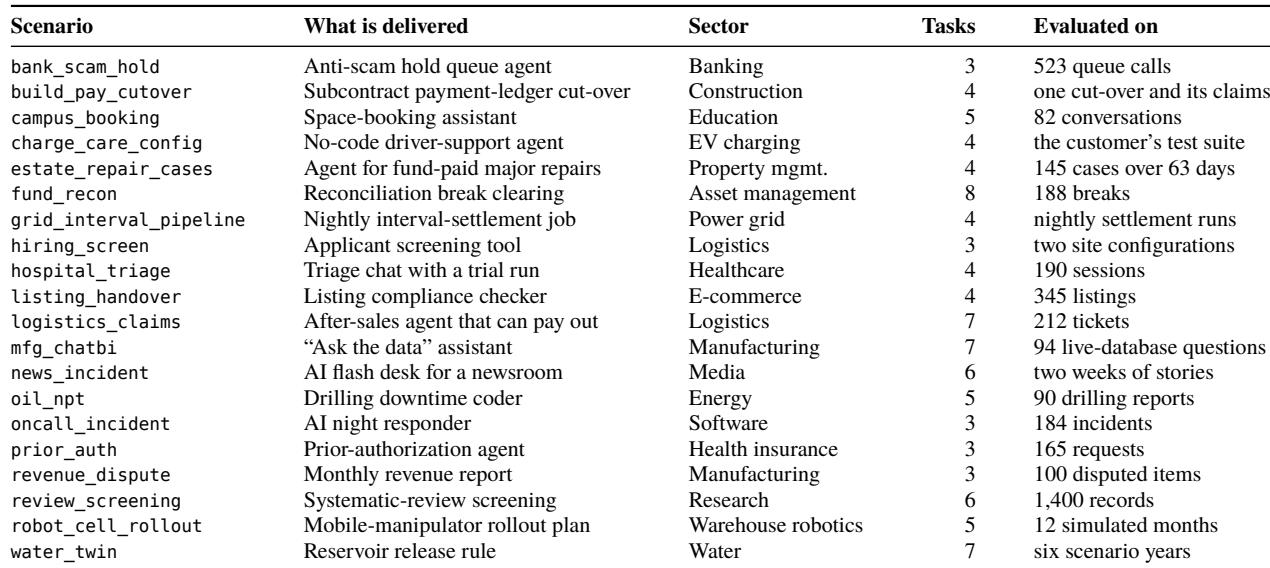
FDE-Gym v1.0 comprises 20 scenarios across 18 sectors, producing 95 tasks in which agents deliver an agent, workflow, or service in a customer environment. Each scenario includes an original task and variants that share the customer environment but differ in key facts. The benchmark is grounded in real-world delivery projects, with companies and individuals de-identified or fictional. Scenarios cover diverse delivery contexts, including banking, construction, education, EV charging, property management, asset management, and power grid operations. Task variants preserve the customer environment while changing key facts, and evaluation uses held-out data such as calls, conversations, cases, breaks, and nightly settlement runs.
At the most realistic instruction level, Claude Opus 5.5 leads with an average score of 0.56 and resolves 14 of 95 tasks, while no configuration resolves more than 15 tasks and five configurations resolve none. Fully specified rules on original tasks produce much stronger results, with leading models scoring between 0.73 and 0.82, but withholding constraints creates the largest observed drop and later vagueness or misdirection adds only a small further decline. Business uplift before stakeholder contact cost is higher for leading models, though contact costs still reduce final scores. The largest score decline occurs when constraints are withheld from leading models, while making requests vague or misdirected adds only a small further reduction. At the most realistic level, the best model still resolves 14 of 95 tasks and five of thirteen configurations resolve none.
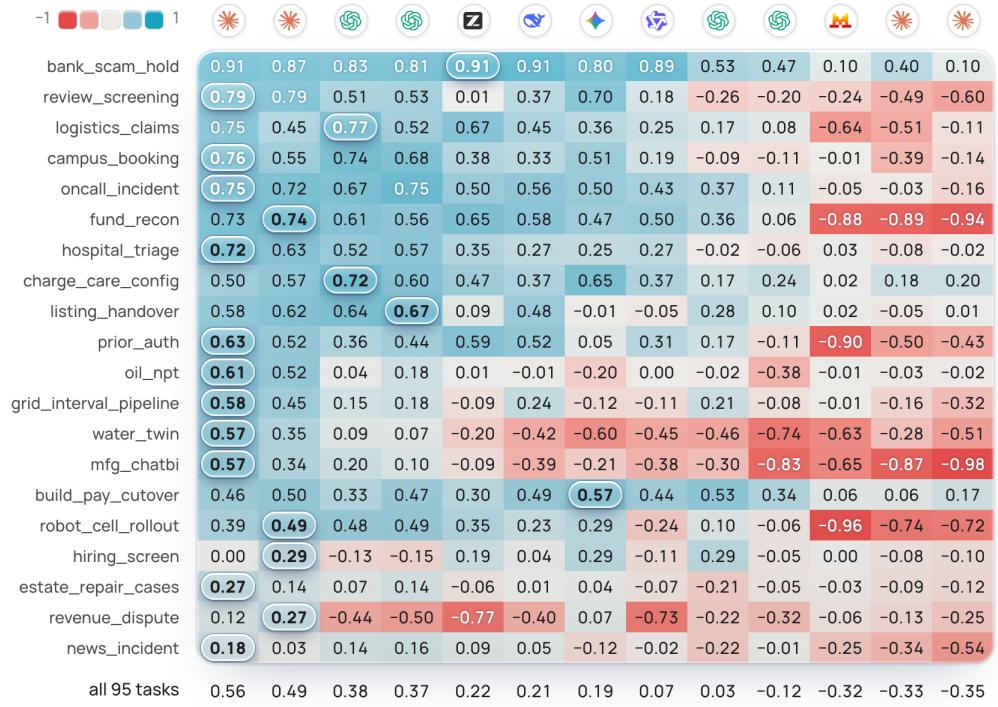
Mean L3 scores vary widely by scenario and model, with the best model score declining from bank_scam_hold to hospital_triage. Several models produce negative scores on review_screening, logistics_claims, and fund_recon, indicating performance below the do-nothing baseline. Model rankings shift across scenarios, so no single model dominates all delivery tasks. The top score is highest on bank_scam_hold and lower on hospital_triage, following the scenario ordering by best model score. Negative values, which fall below the do-nothing baseline, appear across multiple scenarios and are most severe in fund_recon and logistics_claims. The leading model differs by row, and models that perform well on some scenarios can still underperform the baseline on others.
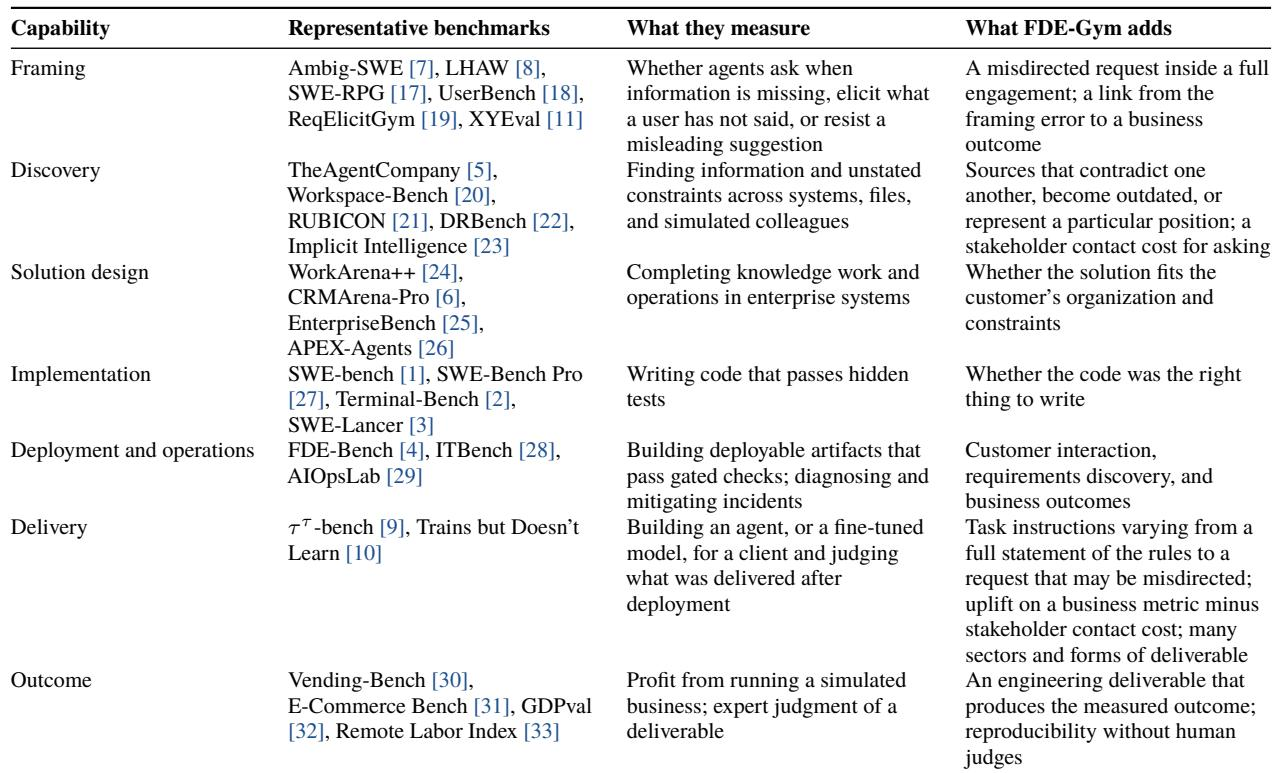
FDE-Gym evaluates delivery as a single causal chain from problem framing and discovery through solution design, implementation, deployment, and business outcome. It adds misdirected requests, stakeholder contact costs, and business-metric uplift relative to a do-nothing baseline, rather than isolated task success. In the reported experiments, models that perform well on component benchmarks improve the customer's business metric in only a minority of engagements. Existing benchmarks each isolate one stage of delivery, whereas FDE-Gym links a framing or discovery error to a downstream business outcome. Across all stages, FDE-Gym adds pressures that prior benchmarks do not, including contradictory or outdated sources, stakeholder contact costs, and requests that may be misdirected. Strong results on component benchmarks are a weak guide to delivery performance; models that solve most terminal, coding, and research tasks improve the customer metric in only a minority of engagements.
FDE-Gym evaluates end-to-end delivery work across instruction levels that isolate implementation, constraint discovery, and problem clarification, with the least explicit level treated as the most realistic. The key finding is that withholding explicit rules and constraints creates the largest performance drop, while later vagueness or misdirection adds little, and agents shift from building a solution to discovering constraints, clarifying requests, and evaluating whether the request addresses the underlying problem. Performance varies widely by scenario and model, with some configurations falling below a do-nothing baseline, and strong results on component benchmarks are a weak guide to delivery outcomes because the benchmark links framing or discovery errors to downstream business metrics and adds stakeholder contact costs and misdirected requests.