Command Palette
Search for a command to run...
OpenGCUA: 범용 컴퓨터 사용을 위한 완전 개방형 스택을 향하여
OpenGCUA: 범용 컴퓨터 사용을 위한 완전 개방형 스택을 향하여
초록
컴퓨터 사용은 전환점에 도달했다. 초점이 GUI 전용 상호작용에서 시각적·프로그램적 인터페이스를 통해 사용자의 컴퓨터에서 과제를 완수하는 시스템으로 확장되고 있다. 우리는 범용 컴퓨터 사용 에이전트(GCUA)를, 시각적 및 프로그램적 인터페이스 전반에서 모델이 관찰·행동·작업 조직 방식을 선택하는 시스템으로 정의한다. 그러나 GPT-6 Astra의 컴퓨터 사용 시스템과 같은 최전선 구현은 대체로 폐쇄적이어서 설계에 대한 체계적 연구가 제한적이다. 우리는 커뮤니티와 함께 GCUA 전체 스택을 개발하고 개방하기 위한 진행형 프로젝트인 Open Generalist CUA(OpenGCUA)를 소개한다. 본 보고서는 OpenGCUA의 첫 번째 릴리스를 제시한다. 코드 실행은 우리 에이전트 설계의 핵심 특징으로, 중간 결과가 후속 작업을 결정하게 하고 모델이 기존 프로그래밍 능력을 컴퓨터 상호작용에 직접 적용할 수 있게 한다. 또한 우리는 하네스-모델 결정 이전(harness-to-model decision transfer)을 제안하여, 선택된 관찰과 과제 상태 결정을 고정된 하네스 규칙에서 모델로 옮긴다. OSWorld-v2에서 우리의 전체 구성은 GPT-6 Astra와 Claude Opus 5를 포함한 평가된 8개 모델 모두에서 과제 점수를 향상시켰고, 일괄 GUI 전용 실행 대비 평균 부분 점수를 +19.6점 높였으며 과제당 보고된 단계 수를 평균 53.0% 줄였다. 우리는 구현체와 프롬프트, 8개 모델 전체의 평가 궤적, 실제 기기 하네스와 교차 기기 SDK의 예비 버전을 공개한다. 이 하네스는 벤치마크가 완전히 포착하지 못하는 실제 기기 문제를 다루고, SDK는 컴퓨터·모바일·브라우저 전반에 공통 프로그래밍 인터페이스를 제공한다. 실제 기기 하네스에서 수행한 네 가지 실제 macOS 과제에서, 선별된 Qwen3.8-Max 실행은 GPT-6 Astra보다 보고된 추론 토큰을 19.4배 많이 사용하여 실제 기기 실행 효율성에서 모델 간 상당한 차이가 있음을 보여준다.
One-sentence Summary
Alibaba Token Hub, Alibaba Group introduce OpenGCUA, an open full-stack generalist computer-use agent that combines code execution with harness-to-model decision transfer; on OSWorld-v2, it raises mean partial score by +19.6 points and reduces reported steps per task by an average of 53.0% across all eight evaluated models, including GPT-6 Astra and Claude Opus 5, and the project releases a real-device harness and a cross-device SDK.
Key Contributions
- The first release introduces Open Generalist CUA (OpenGCUA), an open full-stack project for generalist computer-use agents, with an agent design centered on code execution and a proposed harness-to-model decision transfer that moves selected observation and task-state decisions from fixed harness rules to the model.
- On the offline OSWorld-v2 subset, the full OpenGCUA configuration improves task scores across all eight evaluated models, raising mean partial score by 19.6 points and reducing reported steps per task by an average of 53.0% relative to batched GUI-only execution; ablations show additional benefits from code execution beyond interface access alone.
- The release includes the implementation, prompts, evaluation trajectories, and preliminary versions of a real-device harness and cross-device SDK, and across four real macOS tasks selected Qwen3.8-Max runs use 19.4 times as many reported reasoning tokens as GPT-6 Astra.
Introduction
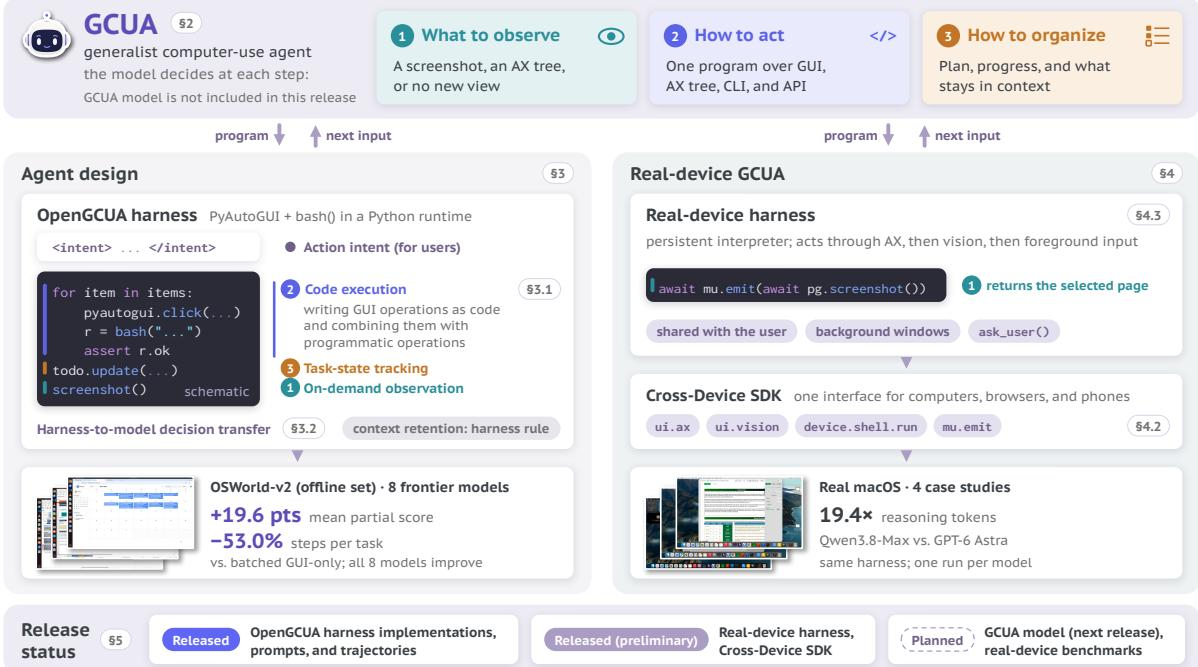
Computer use has shifted from GUI-only control toward generalist systems that combine visual interaction, shell commands, accessibility APIs, and code execution to complete work on real computers. This matters because operating on a user’s own machine introduces challenges such as shared control, background windows, changing requests, and efficiency constraints that traditional benchmark settings do not fully capture. Prior work is limited because most open agents remain GUI-centric or fix observation and action choices in advance, while frontier systems such as GPT-6 Astra are largely closed, making their prompts, harnesses, and trajectories difficult to reproduce or compare. The authors introduce OpenGCUA to open the full stack for generalist computer use, defining a generalist computer-use agent as one whose model decides what to observe, how to act, and how to organize work at each step, and providing an initial real-device harness, cross-device SDK, and released trajectories.
Method
The authors design an agent framework centered on two core behaviors: code execution and harness-to-model decision transfer. Instead of relying on fixed harness rules, the model is empowered to write executable programs that unify graphical user interface interactions and programmatic operations. By combining tools like PyAutoGUI for desktop interaction and bash for shell commands within a single Python program, the model can specify not only what operations to perform but also how execution proceeds. Loops and conditional logic allow the program to repeat operations and choose subsequent actions based on intermediate results without requiring a new model call for each step.
To further enhance autonomy, the framework shifts selected workflow decisions from fixed harness rules to the model. This harness-to-model decision transfer dictates what the model observes and how it organizes its task state. The system provides mechanisms for on-demand observation, allowing the model to request a new screenshot only when visual feedback is necessary, thereby reducing context length. Task-state tracking is maintained through a persistent todo interface, where the model updates and retrieves progress records to distinguish between pending work, attempted changes, and verified outcomes. Additionally, an action intent mechanism requires the model to state the purpose of each code-execution step before it runs, making the program's goal explicit.
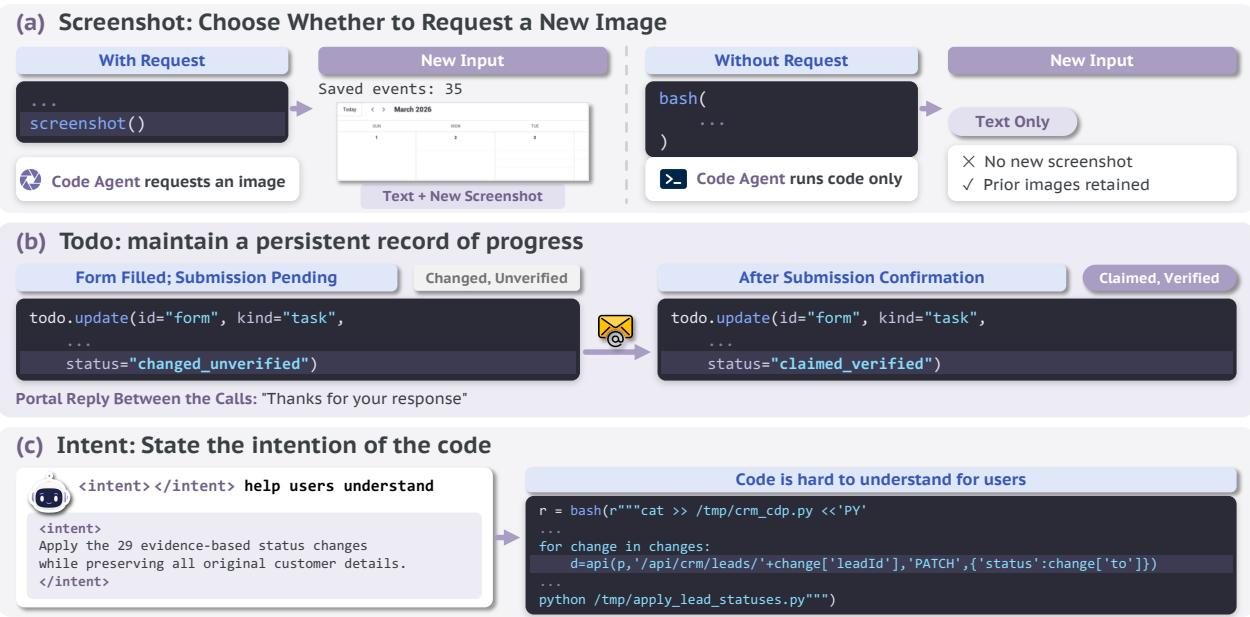
These interfaces are illustrated in the model outputs above, demonstrating how the agent selectively requests visual feedback, maintains persistent task records across programs, and explicitly states its intentions before executing complex code.
For deployment on actual user computers, the authors introduce a Cross-Device SDK and a real-device harness to handle the complexities of uncontrolled environments. The Cross-Device SDK provides a unified programming interface that allows a single agent to coordinate operations across mobile applications, desktop tools, and browser-based services. It supports shared operations with explicit targets, cross-device coordination within a single task, and shared observation processing.
The real-device harness integrates this SDK with the agent loop and platform-specific mechanisms through a structured five-layer architecture.
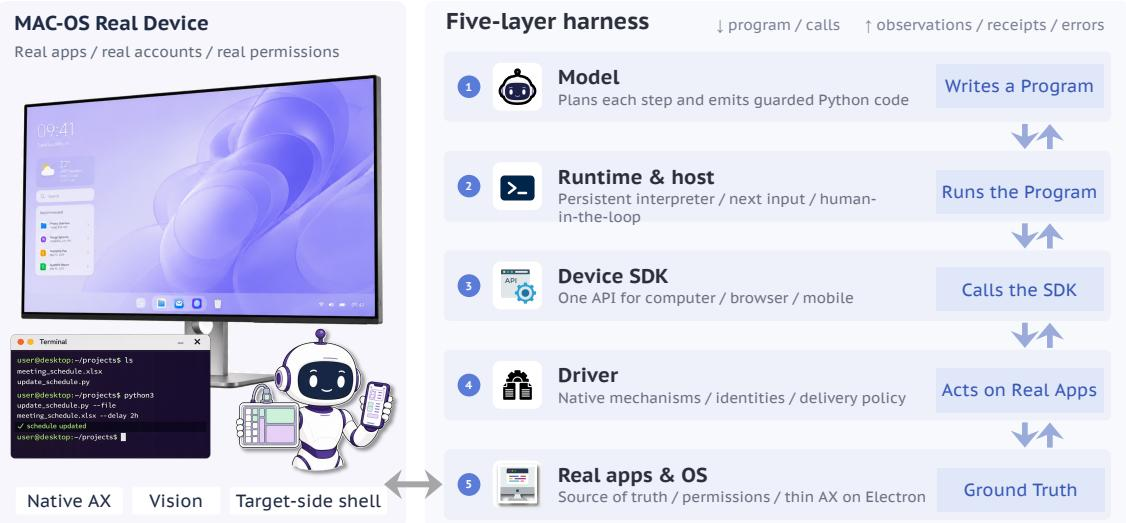
As shown in the figure above, the system is separated into five distinct layers. The Model layer generates Python programs based on the task and interaction history. The Runtime layer manages the agent loop and executes these programs in a persistent interpreter, handling context retention and constructing the next model input. The Device SDK layer binds observations and actions to explicit resources like devices and windows. The Driver layer translates SDK requests into native operations, managing element identities and action delivery policies. Finally, the Applications and Operating System layer represents the ground truth, determining available observations and control capabilities based on permissions and application state. This explicit separation of responsibilities allows compatible components to be replaced independently and ensures that execution failures are properly reported and distinguished from task-level outcomes.
Experiment
These experiments evaluate the OpenGCUA agent design on the offline OSWorld-v2 subset across multiple frontier models, comparing GUI-only and GUI+CLI baselines with the full configuration that adds code execution and harness-to-model decision transfer. The full design consistently improves task completion and interaction efficiency across all models, showing that gains come from executable control over GUI and shell operations and from model-controlled observation and workflow management rather than interface access alone. Ablations indicate that code execution supports adaptive coordination, on-demand observation improves cache reuse, and task-state tracking helps maintain progress, while resource-aware analysis shifts model rankings under cost or time limits. Preliminary real-device results further suggest that practical performance depends on observation targeting, reasoning volume, and whether models write code that verifies complete task coverage.
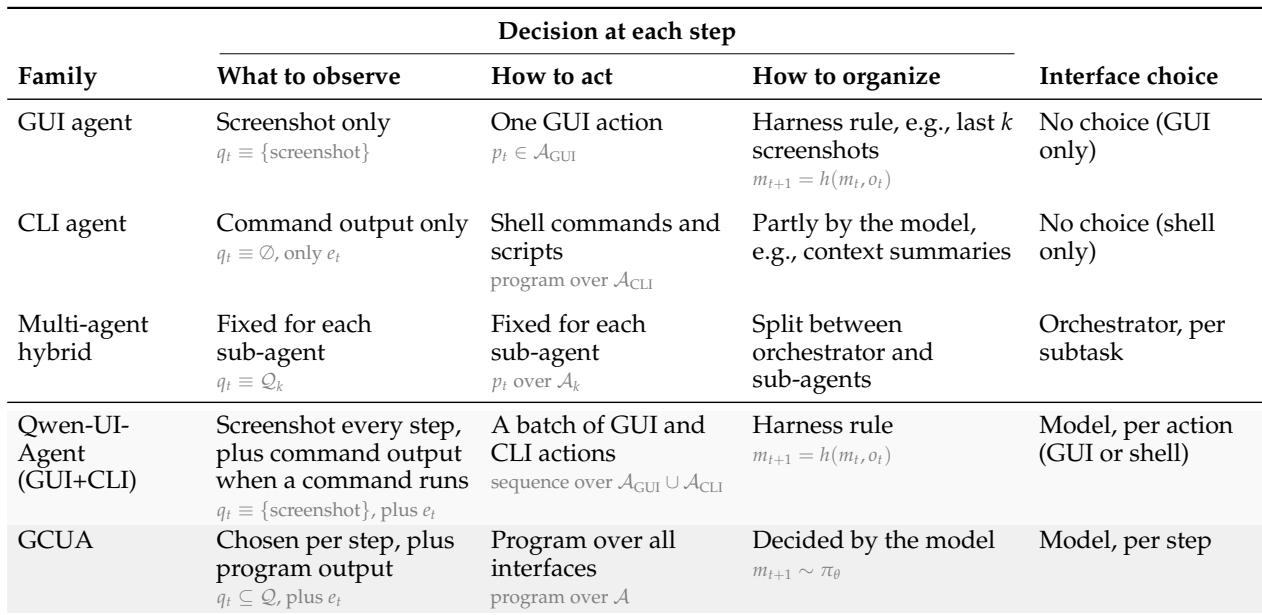
GCUA is defined against existing agent families by which of three decisions are fixed in advance: what to observe, how to act, and how to organize. GUI and CLI agents lock in their observation and interface choices, while multi-agent hybrids make interface choices only per subtask. The progression from an earlier GUI+CLI agent to GCUA moves toward a single model making all three decisions at every step. Existing families fix at least one of these decisions, whereas GCUA leaves observation scope, action interface, and working-state updates to the model each step. The earlier GUI+CLI agent already selects between GUI and shell actions per action, but GCUA also makes observation and memory organization decisions dynamically.
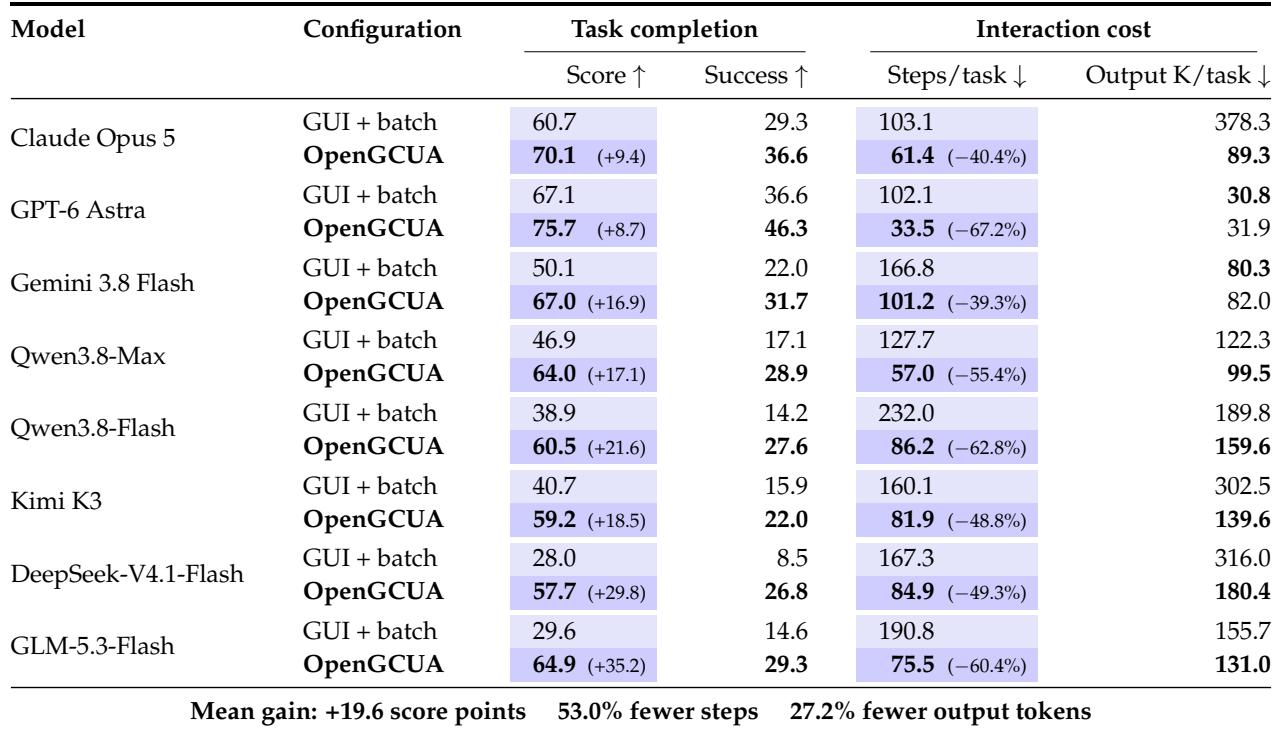
The full OpenGCUA configuration improves task completion scores and full-task success while sharply reducing steps per task across the evaluated models, relative to a batched GUI-only baseline. Output-token use falls for most models but not universally, so fewer steps do not always mean fewer tokens. The gains hold across models with very different baseline performance and efficiency. Across the eight evaluated models, the cross-model mean score rises from 45.3 to 64.9 while steps per task fall by an average of 53.0%. In the shown model subset, output-token use is mixed: one model reduces tokens sharply, while others use similar token budgets despite large step reductions.
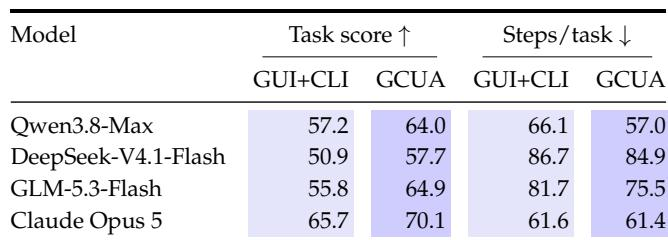
Full GCUA improves over the batched GUI+CLI baseline by adding code execution and model-initiated workflow control. In selected runs, all four models achieved higher task scores, and most also used fewer steps per task. The results suggest that control over execution and workflow matters beyond simply providing GUI and CLI access. Every evaluated model achieved a higher task score under full GCUA than under the batched GUI+CLI baseline. Steps per task decreased for most models under full GCUA, while Claude Opus 5 improved in score with almost no change in step count. Score gains in the selected runs were roughly 4 to 9 points, with Qwen3.8-Max showing the largest reported step reduction.
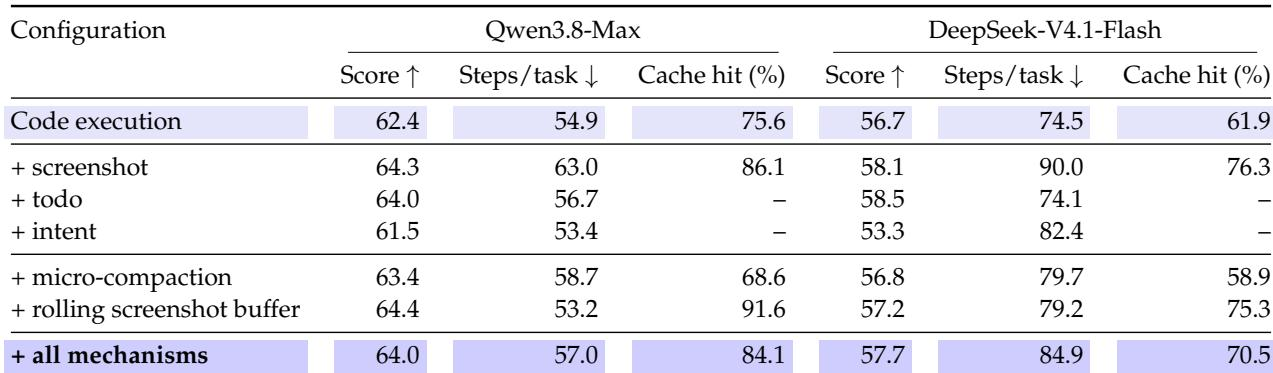
An ablation from a code execution baseline shows that the added mechanisms mainly affect cache reuse and step efficiency, while task score changes stay modest. Screenshot observation and the rolling screenshot buffer improve cache hit without lowering task scores, and todo yields a small score increase. Intent lowers scores slightly, while micro-compaction reduces cache reuse but does not appear to lower the selected task scores. Screenshot observation improves cache hit and task score over code execution for both evaluated models. Rolling screenshot buffer produces the largest cache hit improvements among the added mechanisms, while task scores remain at or above baseline. Todo increases task score slightly, consistent with its role in tracking progress and unresolved work. Intent annotation slightly lowers task scores, reflecting its focus on user interpretability rather than benchmark performance. Micro-compaction reduces cache hit compared with code execution, but task scores do not fall in these selected comparisons.
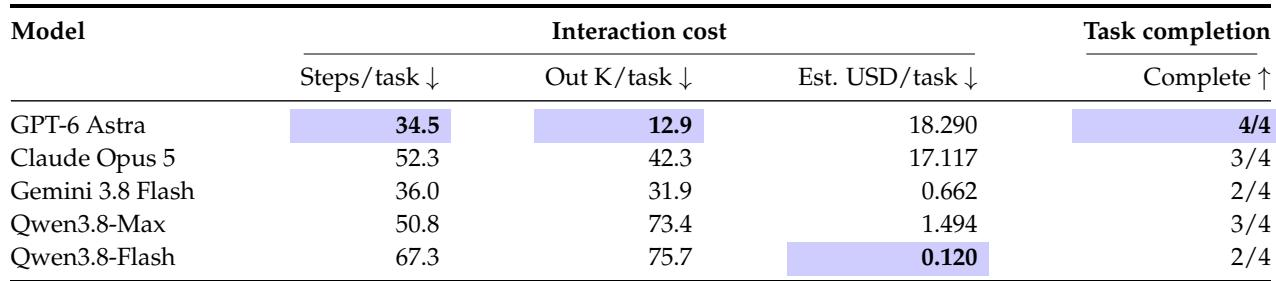
Real-device evaluations reveal substantial trade-offs among completion, generation volume, interaction length, and estimated cost. GPT-6 Astra attains the highest completion count with the fewest steps and output tokens but is the most expensive under the pricing assumptions, while Qwen3.8-Max uses far more reasoning tokens yet costs much less. Task-level cases show that reasoning overhead and code coverage can diverge even when models perform similar operations. Across configurations, completion counts range from two to four tasks, and lower token usage does not always imply lower cost. GPT-6 Astra completes all four tasks while using the fewest steps and output tokens, but its estimated cost per task is the highest. Qwen3.8-Max produces about 5.7 times more output tokens per task than GPT-6 Astra, mostly from reasoning, yet its estimated cost is much lower. On a workbook task, GPT-6 Astra fills all 125 required answer cells, whereas Qwen3.8-Max leaves 40 empty after processing only a subset of rows. A simple screenshot operation highlights a reasoning-cost gap: Qwen3.8-Max emits over two thousand output tokens while GPT-6 Astra emits around one hundred and twenty.
The experiments evaluate GCUA against fixed-decision baselines such as GUI-only and batched GUI+CLI agents, showing consistent task-score gains and large step reductions across models, though token use and cost vary. Full GCUA benefits from code execution and model-initiated workflow control, improving scores beyond what GUI and CLI access alone provides. Ablations indicate that added mechanisms mainly affect cache reuse and step efficiency with modest score changes, while real-device evaluations reveal trade-offs where fewer tokens and steps do not always mean lower cost.