Command Palette
Search for a command to run...
WAYPOINT-OPD: 게이트형 온폴리시 증류를 통한 RL 유도 정책 변화 전이
WAYPOINT-OPD: 게이트형 온폴리시 증류를 통한 RL 유도 정책 변화 전이
Bingxi Hou Guochao Jiang Guofeng Quan Weiqing Li Wenfeng Feng Guohua Liu Yuewei Zhang
초록
정책 변화 증류(policy-shift distillation)는 강화학습(RL) 전후 교사 모델의 로그 확률 차이를 학생이 생성한 궤적에 대한 지도 신호로 재사용한다. 그러나 이러한 종료 시점 정책 변화는 교사 학습 동안 국소 행동 선호가 일관되게 진화했는지를 드러내지 못한다. 동일한 종료 시점 변화는 서로를 강화하거나 부분적으로 상쇄하는 초기 변화와 후기 변화에서 비롯될 수 있다. 우리는 초기와 후기 교사 정책 변화 간의 일치 여부가 선택적 전이를 안내할 수 있는지 조사한다. 동일한 RL 실행에서 얻은 중간 교사 체크포인트를 사용하여 학생이 방문한 프리픽스에서 상대적 행동 선호의 초기 및 후기 변화를 비교하는 Waypoint-guided On-Policy Distillation(Waypoint-OPD)을 제안한다. 초기 및 후기 변화 간의 방향 일치도에 따라 종료 시점 변화를 게이팅하며, 두 변화가 반대 방향을 가리킬 때 이를 억제한다. 종료 시점만 사용하는 전이와 비교해, 우리 방법은 동결된 교사로 점수를 한 번만 추가 계산하면 된다. RL로 학습된 Qwen3-4B 교사 모델을 사용하여 수학 및 코드 추론에서 Qwen3-8B, Qwen3-14B, Qwen3-30B A3B를 학생 모델로 평가한다. 6개의 도메인-학생 설정 모두에서 Waypoint-OPD는 비교된 증류 방법 중 가장 높은 도메인 평균 점수를 달성한다. Qwen3-8B 학생 모델을 사용한 소거 실험은 게이트를 제거하거나 뒤섞으면 수학적 추론 성능이 저하됨을 보여준다. 이러한 결과는 학생 훈련 중 종료 시점 변화에 가중치를 부여하기 위해 초기 및 후기 교사 정책 변화 간 방향 일치도를 사용하는 것을 뒷받침한다. 코드는 https://github.com/hhhbxloveai/WaypointOPD에서 제공된다.
One-sentence Summary
Alibaba Cloud Computing researchers introduce Waypoint-guided On-Policy Distillation (Waypoint-OPD), which uses an intermediate teacher checkpoint to compare early and late RL policy shifts, gates endpoint supervision when they disagree, requires only one extra frozen-teacher scoring pass, and yields the highest domain-average scores across Qwen3-8B, Qwen3-14B, and Qwen3-30B A3B students on mathematical and code reasoning.
Key Contributions
- The paper introduces Waypoint-guided On-Policy Distillation (Waypoint-OPD), which uses an intermediate teacher checkpoint to compare early and late shifts in relative action preferences at student-generated prefixes and gates the centered Initial-to-Final policy shift by their directional agreement.
- Directional agreement between consecutive teacher RL shifts serves as prefix-level evidence for selective endpoint transfer, suppressing updates where early and late shifts oppose each other while requiring only one additional frozen-teacher scoring pass and no verifier calls during distillation.
- Experiments with RL-trained Qwen3-4B teachers and Qwen3-8B, Qwen3-14B, and Qwen3-30B A3B students in mathematical and code reasoning demonstrate that Waypoint-OPD achieves the highest domain-average score in all six domain-student settings, and ablations show that removing or shuffling the gates reduces mathematical reasoning performance.
Introduction
Reinforcement learning improves language models on instruction following with human preference rewards and on mathematical and code reasoning with verifiable rewards, but reusing a teacher model’s RL gains across target models remains costly. Prior on-policy distillation methods transfer either the teacher’s absolute distribution, a teacher-to-base change, or the endpoint log-probability ratio between pre-RL and post-RL checkpoints. The endpoint approach is limited because the same Initial-to-Final shift can combine early and late policy changes that point in compatible or opposing directions, and endpoint-only signals cannot distinguish these cases. The authors leverage an intermediate Waypoint checkpoint from the teacher’s RL run to measure agreement between the Initial-to-Waypoint and Waypoint-to-Final shifts, then use that agreement to gate the centered Initial-to-Final signal on student-generated prefixes. Waypoint-OPD retains aligned RL-induced changes, suppresses reversals, and requires only one additional frozen teacher scoring pass with no new teacher training or verifier calls during student transfer.
Method
The authors propose Waypoint-OPD, a method that augments the endpoint signal of direct on-policy distillation by incorporating a Waypoint checkpoint from the same teacher reinforcement learning run. Instead of using the Waypoint model as an imitation target, the framework leverages it to supply consistency evidence. Agreement between the early and late policy shifts is used to weight the endpoint signal on student-visited prefixes.
As shown in the figure below:
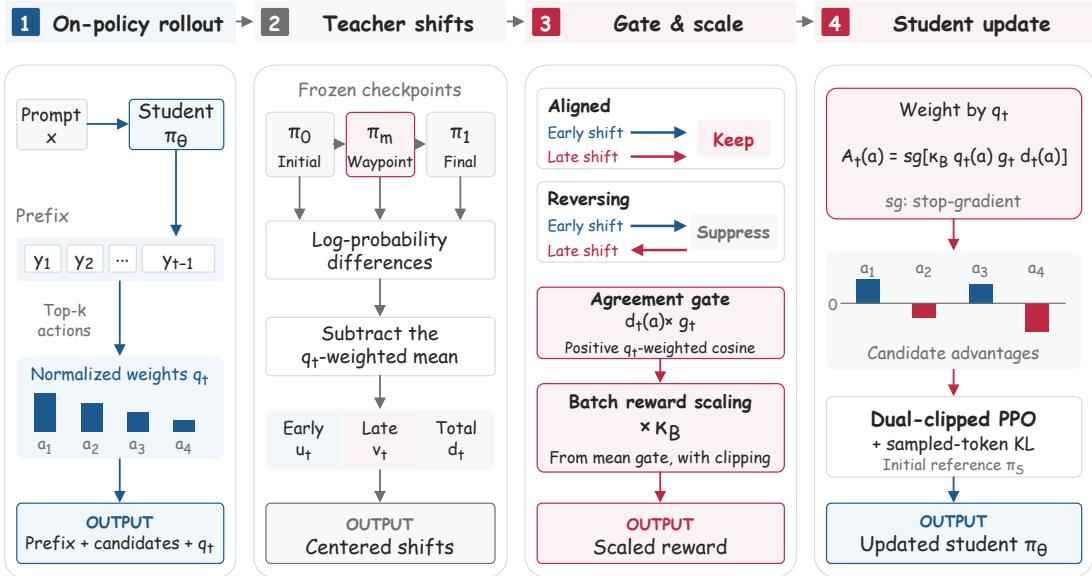
The training pipeline consists of four primary stages: on-policy rollout, teacher shift computation, agreement gating with batch scaling, and the student update.
Student-Local Trajectory Consistency At a student-visited prefix st, the method selects the top-k token candidates with the highest student probabilities and computes a normalized student distribution qt over this support. These weights focus the comparison on likely student actions. The authors then score these candidates using three frozen teacher checkpoints: the initial π0, Waypoint πm, and final π1 models. Two consecutive teacher shifts are calculated as:
δt(1)(a)=logπm(a∣st)−logπ0(a∣st) δt(2)(a)=logπ1(a∣st)−logπm(a∣st)These shifts telescope to the total endpoint shift δt=δt(1)+δt(2).
To remove action-independent components that might affect the angle between raw shift vectors, a centering operator is applied using the normalized student distribution. The centered shifts for the early segment ut, late segment vt, and total endpoint dt are then used to compute local temporal agreement. This agreement is measured as the cosine similarity between the centered early and late shift vectors, weighted by the student probabilities:
ct=∥ut∥qt∥vt∥qt⟨ut,vt⟩qtAgreement Gating and Batch-Scale Normalization To filter the endpoint signal, a positive-cosine gate is applied. If the centered segment norms exceed a small numerical threshold ε, the gate value is set to:
gt=max(0,ct)This mechanism suppresses the endpoint signal when the early and late shifts are misaligned and preserves it when they are aligned. If either norm falls below the threshold, a low-norm fallback sets the gate to one.
To stabilize the average gate scale across different batches, all gated rewards within a batch are multiplied by a shared scaling factor κB:
κB=clip(max(∣Bpref∣−1∑t∈Bprefgt,εnum)τ,κmin,κmax)This batch scaling preserves relative gate weights and zero gates while preventing the reward-vector norm from collapsing.
Dense Candidate Objective The final coefficient for each candidate action a is derived by combining the batch scaling factor, the normalized student probability, the agreement gate, and the centered total endpoint shift:
At(a)=sg[κBqt(a)gtdt(a)]A stop-gradient operator sg is applied to detach all these factors during differentiation.
The local on-policy surrogate objective maximizes the weighted log-probabilities of the candidate actions while regularizing the student policy toward its own initialization using a KL divergence penalty:
JWP(θ)=Ex∼D[Ey∼πθ(⋅∣x)[t=1∑Ta∈Kt∑At(a)logπθ(a∣st)]−βDKL(πθ(⋅∣x)∥πS(⋅∣x))]The rollout samples and candidate supports are held fixed when differentiating this surrogate. The implementation utilizes dual-clipped PPO, which shares the same gradient as the surrogate at the rollout policy. Relative to direct on-policy distillation, this approach adds only one frozen teacher checkpoint and a scoring pass, requiring no additional trainable parameters or student rollouts.
Experiment
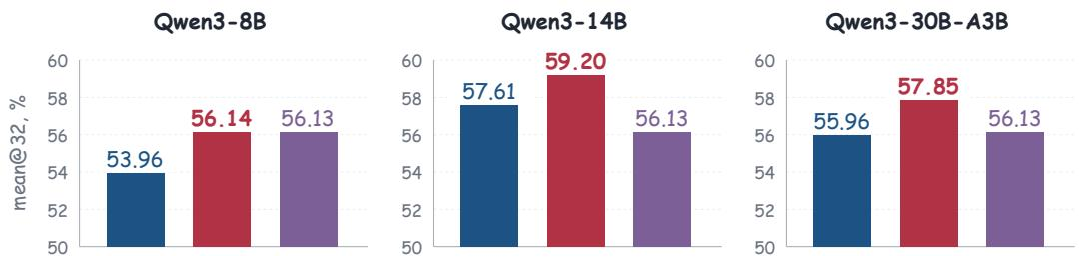
This work evaluates Waypoint-OPD, which transfers policy shifts from frozen Qwen3-4B RL checkpoints at initial, waypoint, and final stages to Qwen3-8B, Qwen3-14B, and Qwen3-30B-A3B students on math and code benchmarks, using on-policy distillation and endpoint transfer baselines. Waypoint-OPD achieves the highest domain average in all six settings and improves over Direct-OPD across both domains and all student scales, with the larger students surpassing the final teacher on math and code averages. Learning trajectory results show sustained gains over Direct-OPD during training, and ablations on Qwen3-8B math indicate that temporal gating, correct gate-prefix assignment, and mean normalization each contribute to performance.
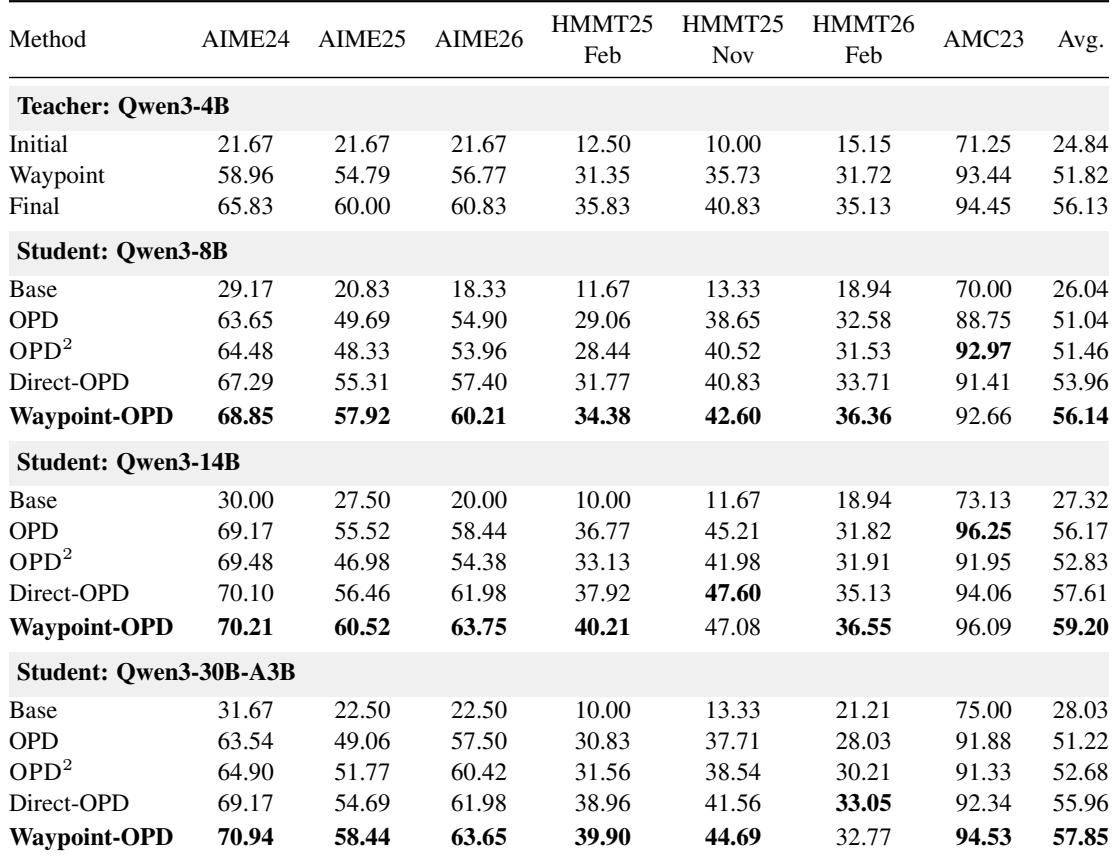
Waypoint-OPD achieves the highest domain-average score among evaluated student methods across all three student sizes in both math and code. On math, it outperforms Direct-OPD, with the 14B student surpassing the final teacher on all seven benchmarks and the 30B-A3B student also exceeding the teacher average, while the 8B student essentially matches it. Gains are broad and sustained, improving 19 of 21 math benchmark comparisons and holding an advantage from step 60 onward in the 8B learning trajectory. Waypoint-OPD records the highest domain-average score among evaluated student methods in all six settings spanning math and code. For math, Waypoint-OPD improves over Direct-OPD by about 1.6 to 2.2 percentage points across the three student sizes. The 14B and 30B-A3B students exceed the final teacher math average, while the 8B student essentially matches it. Waypoint-OPD improves 19 of 21 math benchmark comparisons over Direct-OPD and sustains gains from step 60 onward in the 8B learning trajectory.
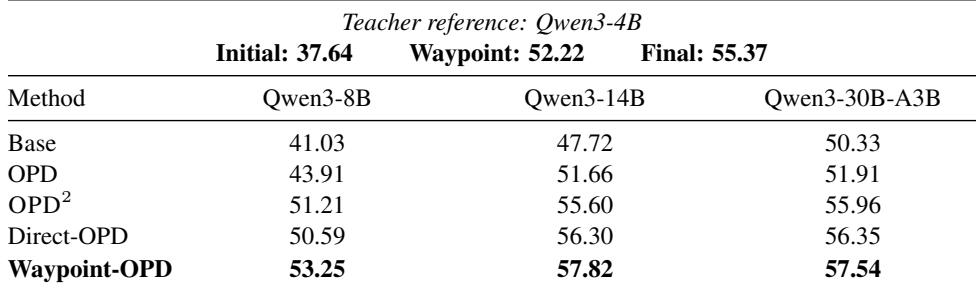
Waypoint-OPD achieves the highest average code reasoning performance among the evaluated student methods across all three student scales. It improves over Direct-OPD in every code comparison, with the largest average gain on the smallest student, while the 14B and 30B-A3B students exceed the final teacher checkpoint average. Waypoint-OPD is the strongest student method for code reasoning across all three student sizes. It improves over Direct-OPD in all 15 code comparisons, and the 14B and 30B-A3B students surpass the final teacher average code score.
Ablations on Qwen3-8B mathematical reasoning show that Waypoint-OPD benefits most from consistency-dependent gating and from matching each gate to the prefix that produced it. Removing the gate lowers accuracy on all seven benchmarks, while shuffled gate assignment is even more harmful. Normalization provides a smaller additional average benefit and improves most benchmarks, though the unnormalized variant still outperforms Direct-OPD on all seven benchmarks. Removing the gate reduces average accuracy and produces lower scores on all seven benchmarks. Shuffled gate assignment is more detrimental than removing the gate, with the same ordering across every benchmark. Mean normalization gives a smaller average benefit and improves six of seven benchmarks, with HMMT February 2025 as the exception. Even without normalization, the method still outperforms Direct-OPD on average and on all seven benchmarks.
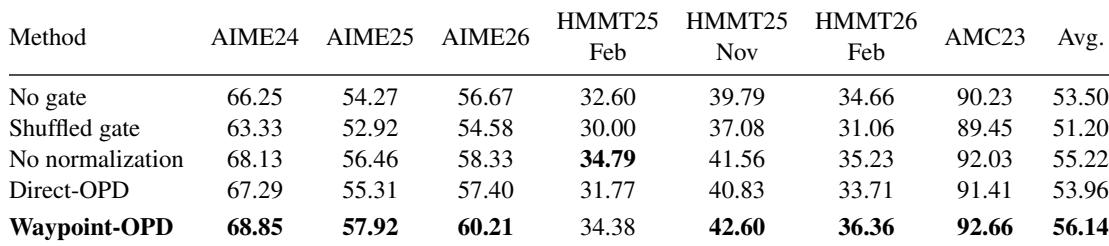
Waypoint-OPD consistently outperforms Direct-OPD across math and code reasoning tasks for all evaluated student sizes, with the 14B and 30B-A3B students often surpassing the final teacher average and the 8B student roughly matching it. The gains are broad across benchmarks and sustained during training. Ablations on mathematical reasoning show that consistency-dependent gating and matching each gate to its originating prefix are the most important components, while mean normalization provides a smaller additional benefit and the method remains effective without it.