Command Palette
Search for a command to run...
PLAYER-1: 합성 경험을 통한 플레이 학습
PLAYER-1: 합성 경험을 통한 플레이 학습
초록
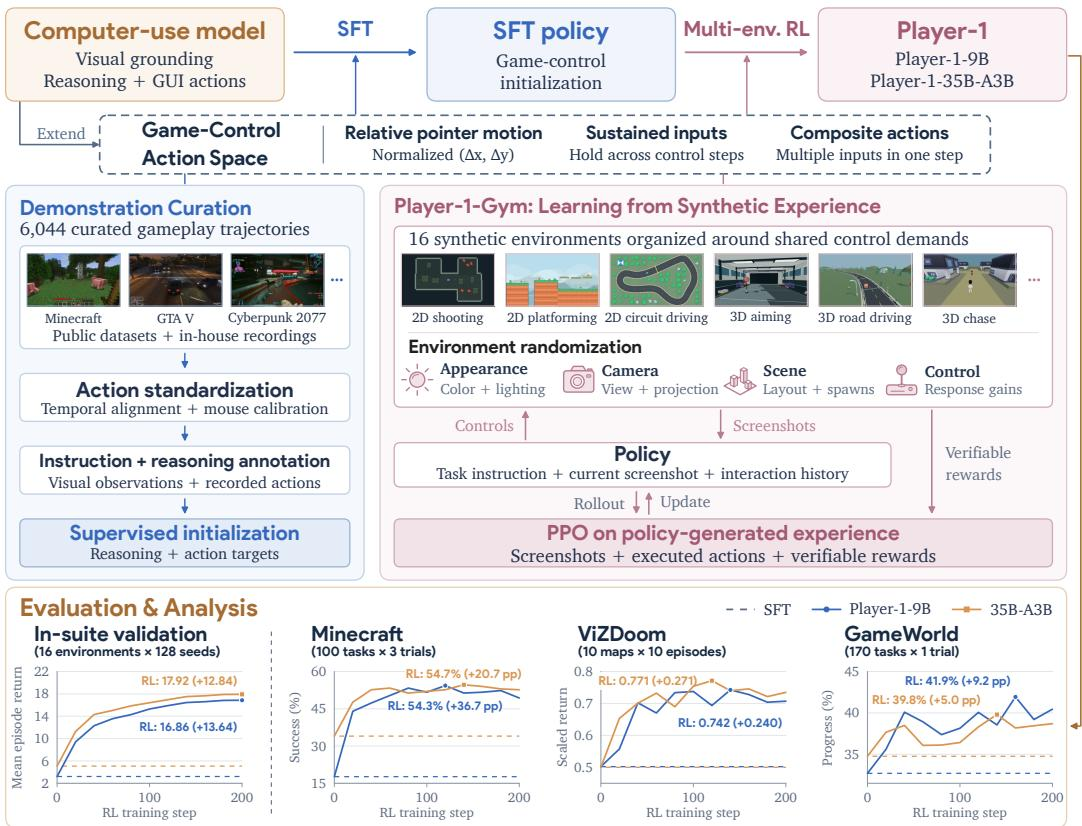
컴퓨터 사용 에이전트는 화면을 해석하고 키보드 및 마우스 행동을 실행하는 데 강력한 능력을 보여 왔다. 그러나 게임은 시각적으로 풍부한 세계와 다양한 메커니즘을 지니고 있어 여전히 어려운 과제이며, 범용 디지털 제어를 향한 까다로운 다음 단계를 제시한다. 현재 게임 에이전트 학습 파이프라인은 동적 게임 상태에 대한 포괄 범위가 제한적인 대규모 시연 데이터에 의존하는 경우가 많고, 상호작용 훈련을 위한 확장 가능한 환경은 여전히 확보하기 어렵다. 우리는 합성 경험을 통해 시연을 넘어 게임 제어를 학습하기 위한 포스트트레이닝 프레임워크인 PLAYER-1을 소개한다. 우리는 컴퓨터 사용 행동 공간을 상대 포인터 이동, 지속 입력, 복합 행동으로 확장한다. 지도 학습 초기화를 위해, 기록된 행동을 작업 지시문 및 시각적 추론과 짝지은 6,044개의 정제된 게임플레이 궤적에 대해 컴퓨터 사용 모델을 미세 조정한다. 우리는 게임들 간에 공유되는 제어 요구를 중심으로 설계한 16개의 합성 2D 및 3D 환경인 PLAYER-1-GYM을 구축한다. 프로그램적으로 검증 가능한 보상과 무작위화된 관측 및 제어 동역학은 PPO를 이용한 다중 환경 강화 학습을 뒷받침한다. 그 결과 얻은 Player-1-9B와 Player-1-35B-A3B는 각각의 SFT 정책 대비 MineDojo-300 성공률을 27.8%포인트와 17.7%포인트 향상시킨다. Player-1-9B는 가장 강력한 평가 기준선의 12.63%와 비교해 38.33%의 성공률을 달성하며, ViZDoom-10과 GameWorld에서도 SFT 대비 추가적인 향상을 보인다. 추가 분석에서는 합성 환경 커버리지가 넓어질수록 전이가 향상되고, 여러 키보드 및 마우스 입력을 결합하는 복합 행동의 사용이 RL 동안 증가함을 보여준다. 우리는 합성 경험으로부터의 학습이 지도 학습 초기화를 넘어 게임 제어를 상당히 향상시키며, 그 성능 향상은 RL 훈련 환경 모음을 넘어 일반화됨을 입증한다.
One-sentence Summary
Researchers from National University of Singapore, ARC Lab, Tencent IEG, and Nanyang Technological University introduce PLAYER-1, a post-training framework for learning game control from synthetic experience that extends the computer-use action space with relative pointer motion, sustained inputs, and composite actions, fine-tunes on 6,044 curated gameplay trajectories, and applies PPO across sixteen synthetic PLAYER-1-GYM environments, improving MineDojo-300 success by 27.8 percentage points over SFT and generalizing beyond the RL training suite.
Key Contributions
- PLAYER-1 is a post-training framework that extends the computer-use action space with relative pointer motion, sustained inputs, and composite actions, and uses 6,044 curated gameplay trajectories for supervised initialization before interactive learning.
- PLAYER-1-GYM consists of sixteen synthetic 2D and 3D environments with programmatically verifiable rewards and randomized observations and control dynamics, supporting multi-environment reinforcement learning with PPO.
- The resulting Player-1-9B and Player-1-35B-A3B improve MineDojo-300 success over their SFT policies by 27.8 and 17.7 percentage points, respectively, with Player-1-9B reaching 38.33% success versus 12.63% for the strongest evaluated baseline and further gains on ViZDoom-10 and GameWorld outside the RL training suite.
Introduction
Foundation models now offer broad visual understanding and instruction following, and computer-use agents extend these capabilities to interpreting screens and controlling keyboard and mouse actions. Games are a demanding testbed for general digital control because they require precise, sustained, and concurrent actions under rapidly changing visual feedback. Prior game agents mostly learn from gameplay demonstrations and interactive experience, but demonstrations cover only a limited part of the state space in open-ended tasks, while scalable environments for interactive training remain hard to obtain. To address this, the authors present PLAYER-1, a post-training framework that starts from curated demonstrations and then learns from synthetic experience in PLAYER-1-GYM, sixteen 2D and 3D environments built around shared control demands such as aiming, movement, and UI interaction. With verifiable rewards and randomized observations and dynamics, the framework supports multi-environment reinforcement learning and produces models that improve beyond supervised initialization and generalize to games outside the RL training suite.
Dataset
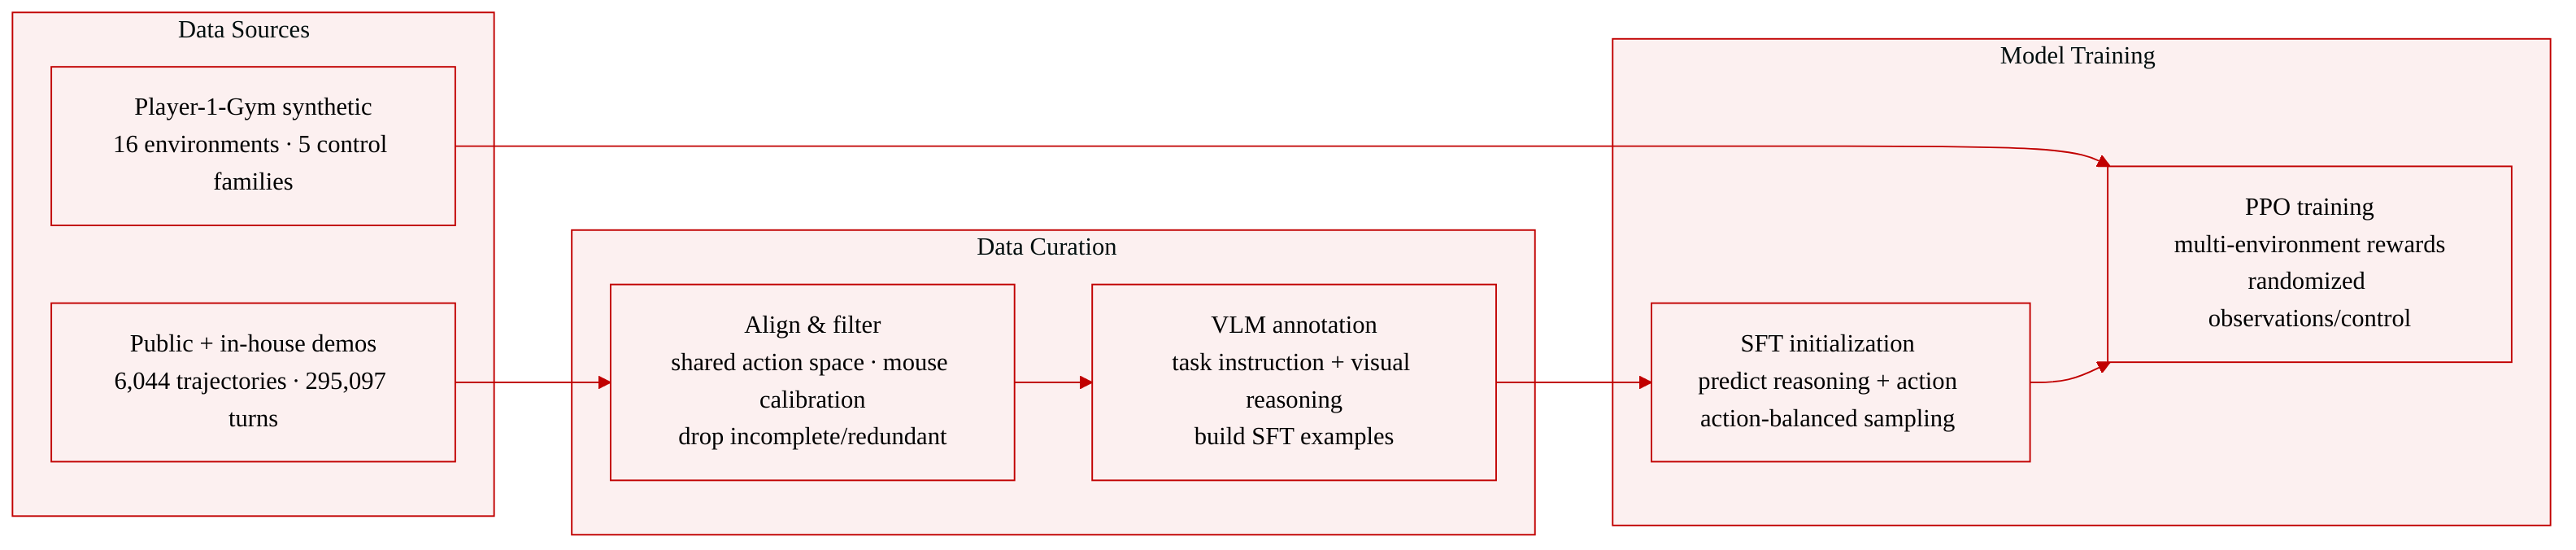
The authors use two complementary data components for game-control training.
1. Curated gameplay demonstration dataset
- Composition and scale: 6,044 gameplay trajectories with 295,097 interaction turns, collected from public datasets and in-house recordings.
- Control alignment and calibration: Recorded controls are mapped into a shared game-control action space. Source-specific mouse calibration expresses relative inputs in normalized, pixel-equivalent coordinates.
- Filtering: Incomplete or redundant recordings are filtered out.
- Annotation: A VLM annotates each recorded action with task instructions and per-turn visual reasoning. Reasoning annotation conditions on the task instruction, current and past observations, and the action target.
- Example schema: Each supervised fine-tuning example is constructed as (q,It,CH(h<t),zt,at), where q is the task instruction, It is the current screenshot, CH(h<t) is retained history, zt is visual reasoning, and at is the action.
- Use in training: The dataset initializes the policy through supervised fine-tuning. The policy learns to predict (zt,at) from the task instruction, current screenshot, and retained history. The authors use a 2+2 history setting: two recent visual-action turns and two earlier action-only turns, with reasoning omitted. Action-balanced sampling increases exposure to less frequent controls and composite actions.
2. Player-1-Gym synthetic environment suite
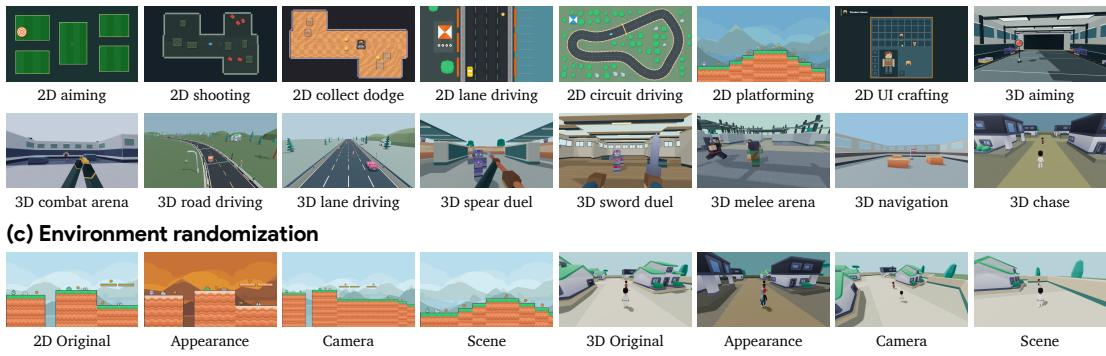
- Composition: 16 synthetic environments organized into five control-demand families: aiming, combat, driving, navigation, and UI interaction.
- Construction: Environments are built from shared 2D and 3D engines, reusable assets, and scene templates. A unified runtime provides screenshot observations and executes the shared game-control action space.
- Reward design: Each environment defines game- and task-specific scoring rules over changing game states. Score increments supply step-level rewards, giving dense, verifiable feedback without a learned judge. Privileged state is not exposed to the policy.
- Randomization: Training experience is broadened across four dimensions:
- Appearance: colors, lighting, and assets
- Camera: projection, placement, and initial orientation
- Scene: layouts, spawns, and task-specific configurations
- Control: input-response gains for camera rotation and movement
- Use in training: The synthetic environments support multi-environment PPO training of the SFT-initialized policy.
Method
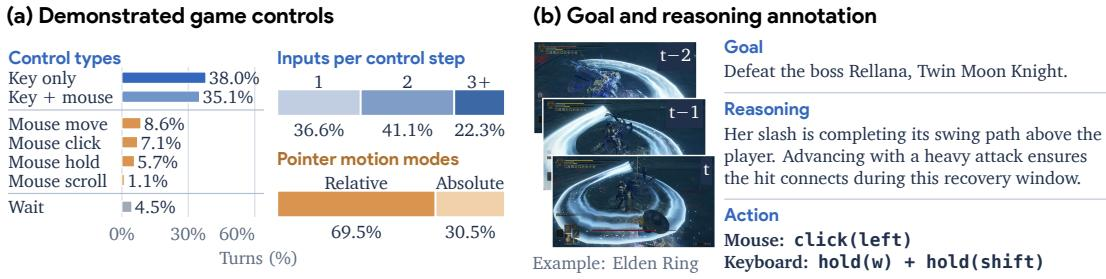
The authors propose PLAYER-1, a framework that bridges supervised initialization with learning from synthetic experience through a unified game-control action space. The method begins by extending standard computer-use actions to support dynamic game control, incorporating relative pointer motion, sustained inputs, and composite actions. This allows the policy to handle complex interactions like concurrent aiming and firing or sustained movement.
To initialize the policy, the authors leverage supervised fine-tuning on a curated collection of gameplay demonstrations. They process trajectories from public datasets and in-house recordings, mapping controls to the shared action space. A vision-language model is then used to annotate these recordings with task instructions and per-turn visual reasoning. The training examples are constructed using the task instruction, current screenshot, and a retained history of past turns, training the policy to predict both visual reasoning and the corresponding action. Action-balanced sampling is employed to ensure adequate exposure to less frequent controls.
As shown in the figure below:
Following initialization, the policy is optimized across PLAYER-1-GYM, a suite of synthetic environments designed around shared control demands. The authors construct sixteen 2D and 3D environments spanning five task families: aiming, combat, driving, navigation, and UI interaction. Each environment provides programmatically verifiable rewards based on game-state scoring rules, offering dense feedback without a learned judge. To broaden the training experience, the environments undergo extensive randomization across appearance, camera, scene layout, and control dynamics.
The synthetic environments and randomization examples are shown in the figure below:
The authors jointly optimize the initialized policy using Proximal Policy Optimization across these randomized environments. To mitigate the impact of varying reward scales across different environments on policy updates, they apply per-environment advantage normalization to the generalized advantage estimates. The normalized advantage Ai,j for turn i and token j in environment e is computed as:
Ai,j=σe2+ϵAi,j−μewhere μe and σe2 are the mean and sample variance of the advantages within the rollout batch for environment e. Return-to-go targets are used to accumulate rewards from subsequent turns, enabling later outcomes to inform earlier control decisions.
Experiment
The experiments evaluate Player-1 models initialized from Qwen3.5 backbones and trained with supervised fine-tuning followed by reinforcement learning across sixteen PLAYER-1-GYM environments, using both in-domain tasks and external benchmarks such as MineDojo, ViZDoom, and GameWorld. The results show that reinforcement learning on synthetic experience substantially improves task-directed control and generalization beyond supervised fine-tuning, with learned capabilities transferring to unseen games and interaction settings. Analyses indicate that supervised initialization is important for effective reinforcement learning, learning dynamics vary across environments, and the models naturally develop more coordinated composite actions during training.
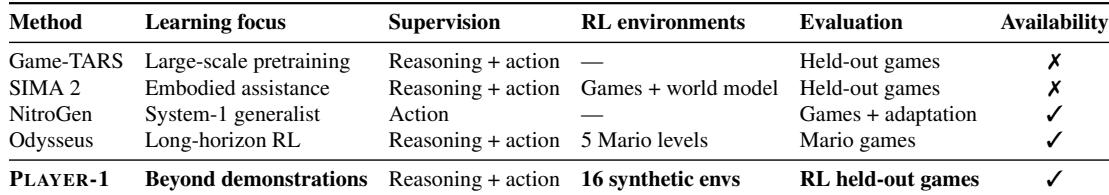
The comparison shows that representative game-agent pipelines differ in their RL environment support, evaluation scope, and availability. Some earlier methods lack dedicated RL environments or evaluate on narrower game settings, while PLAYER-1 combines reasoning and action supervision with synthetic RL environments and held-out game evaluation. PLAYER-1 is among the available pipelines focused on learning beyond demonstrations. PLAYER-1 is the only compared pipeline that combines reasoning and action supervision with held-out game evaluation and is available. Relative to other available pipelines, PLAYER-1 evaluates on held-out games and uses synthetic RL environments, while comparable methods either lack RL environments or evaluate on a narrow set of Mario games.
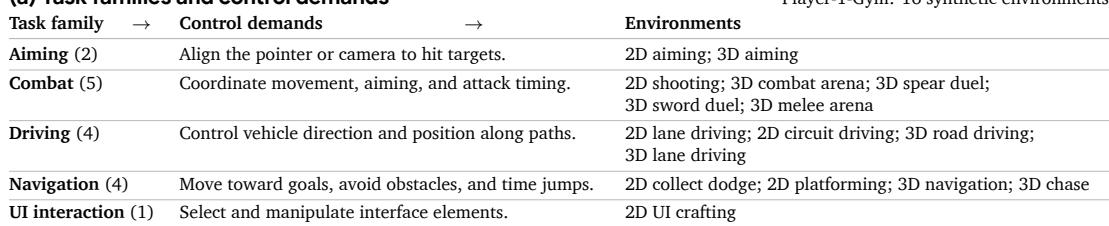
The training suite spans five task families: aiming, combat, driving, navigation, and UI interaction, with control demands ranging from focused pointer alignment or interface manipulation to coordinated movement, aiming, and attack timing. Policies trained on this synthetic experience transfer to unseen commercial games and improve during reinforcement learning, with composite actions becoming more frequent. Combat is the most represented task family in the environment suite, while UI interaction is the least represented. Control demands range from aligning a pointer or camera and selecting interface elements to coordinating movement, aiming, and attack timing.
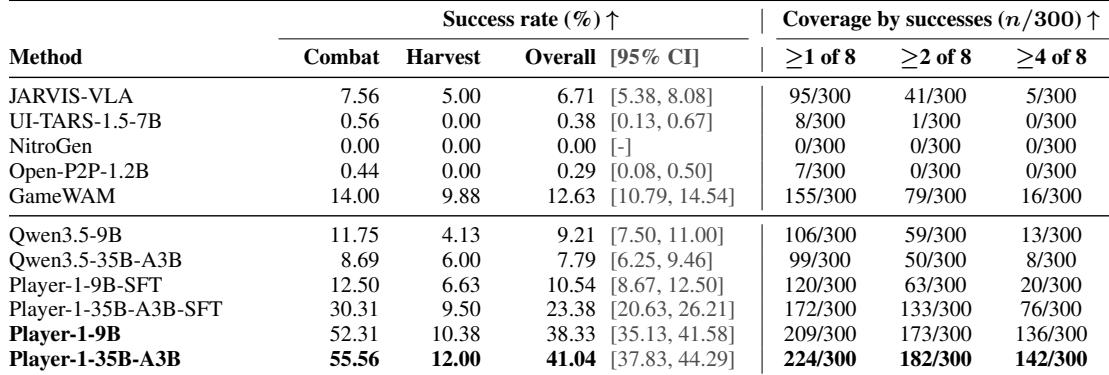
On the MineDojo-300 benchmark, GameWAM achieves the highest combat and harvest success rates and the broadest task coverage across all success thresholds. Qwen3.5-9B ranks second overall and outperforms JARVIS-VLA, while the remaining methods show very limited coverage or no successful trials. GameWAM leads all evaluated methods in overall success rate and in the number of tasks with at least one, two, or four successful trials. Qwen3.5-9B is the strongest runner-up, surpassing JARVIS-VLA and all other baselines on overall success and coverage. Most baselines rarely or never meet success thresholds, with NitroGen achieving zero successful trials and UI-TARS-1.5-7B and Open-P2P-1.2B reaching only a small number of tasks.
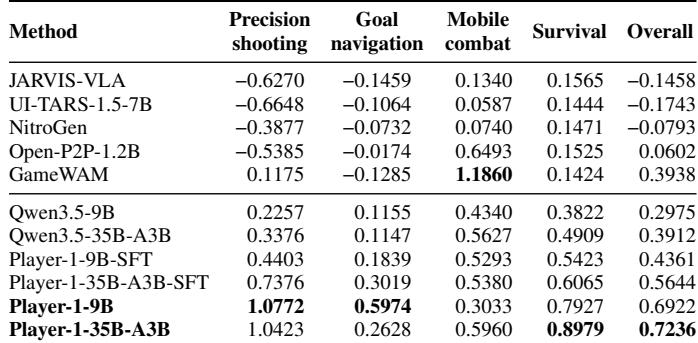
On first-person ViZDoom-10 tasks, GameWAM and Qwen3.5-35B-A3B lead overall mean scaled return by a wide margin over the remaining agents, with GameWAM slightly ahead and Qwen3.5-9B in third. Qwen3.5-based models are the strongest on precision shooting and survival, and they are the only compared methods with positive goal navigation returns. GameWAM dominates mobile combat, while most other agents score near zero or negative overall. GameWAM and Qwen3.5-35B-A3B occupy the top two overall positions, with Qwen3.5-35B-A3B also leading precision shooting and survival. GameWAM leads mobile combat by a wide margin, far exceeding the next best agent on that task.
In browser-game control across 170 tasks and 34 games, Qwen3.5-35B-A3B achieves the highest success and progress, followed by Qwen3.5-9B and NitroGen. Most evaluated methods reach only modest success rates, while progress scores are consistently higher, indicating partial task completion. The larger Qwen model outperforms the smaller Qwen model on both reported metrics. Qwen3.5-35B-A3B leads all methods in both success and progress. Qwen3.5-9B ranks second on both metrics, ahead of NitroGen and other baselines. Open-P2P-1.2B has the lowest success and progress among reported methods. Progress scores exceed success rates for every method, showing that tasks are often partially completed rather than fully solved.
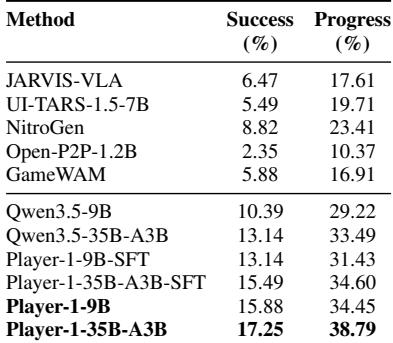
The experiments evaluate representative game-agent pipelines and training suites spanning aiming, combat, driving, navigation, and UI interaction. PLAYER-1 is distinguished as the only available pipeline combining reasoning and action supervision with held-out game evaluation, and policies trained on synthetic RL environments transfer to unseen commercial games. On MineDojo-300 and ViZDoom-10, GameWAM and Qwen3.5 models lead in task coverage and returns, while in browser-game control Qwen3.5-35B-A3B achieves the highest success and progress, with most other methods showing limited or partial task completion.