Command Palette
Search for a command to run...
Any Time, Any Space: 에이전틱 비디오 생성을 위한 세계 상태 중심 프레임워크
Any Time, Any Space: 에이전틱 비디오 생성을 위한 세계 상태 중심 프레임워크
Weijie Wang Haomin Zhang Ye Li Akide Liu Zeyu Zhang Haoyu Zhao Yefei He Donny Y. Chen Feng Chen Bohan Zhuang
초록
장편 에이전틱 비디오 생성은 시나리오를 비연속적인 요청들에 걸쳐 공간적·시간적으로 일관성을 유지하는 숏들로 변환해야 한다. 숏 간에 프롬프트나 최근 프레임을 전달하는 것만으로는 장면을 다시 방문하기 위한 공유된 공간적 기준틀이나 이전 사건을 재생하기 위한 시간 인덱스 기록을 제공하지 못한다. 우리는 Any Time, Any Space(ATAS)를 제시한다. ATAS는 시나리오를 명시적 위치, 카메라, 사건 시간 참조를 가진 숏 요청들로 컴파일한다. 생성 전에 ATAS는 등록된 정적 지오메트리의 장면 메모리와 장면, 사건, 시간으로 인덱싱된 동적 관측의 사건 메모리로부터 관련 증거를 검색한다. 생성 후 ATAS는 클립을 재구성하고 등록한다. 메모리는 검토 및 상태 검사가 관측을 수용할 때만 갱신되며, 영상 전달은 메모리 반영 여부와 독립적으로 유지된다. 네 가지 비디오 생성기에서 ATAS는 보고된 모든 교차 숏 일관성 지표를 향상시키고 각 백본에 대해 가장 높은 종합 벤치마크 점수를 달성한다. 또한 비교된 에이전트 및 3D 유도 방법들보다 목표 이미지 공간 재방문에서 우수하고, 세 가지 사건 재포착 기준에서 앞서며, 여섯 가지 기준 모두에서 가장 높은 인간 평가 점수를 받는다.
One-sentence Summary
Researchers from Zhejiang University, Monash University, BAIR, UC Berkeley, and Adelaide University propose Any Time, Any Space (ATAS), a world-state-centric agentic video generation framework that compiles screenplays into shot requests with explicit location, camera, and event-time references, retrieves relevant scene and event memory, and registers clips to improve cross-shot consistency and achieve the highest aggregate benchmark score across four video generator backbones.
Key Contributions
- Any Time, Any Space (ATAS) is a world-state-centric framework that compiles screenplays into shot requests with explicit location, camera, and event-time references, enabling later shots to query evidence from earlier observations.
- ATAS combines complementary spatially registered scene memory and time-indexed event memory with a validation-controlled update mechanism that separates film acceptance from admission of new evidence into persistent state.
- Experiments across four video generators and five agent baselines show that ATAS improves all reported cross-shot consistency measures and attains the highest aggregate score per backbone; it also outperforms evaluated agent and 3D-guided methods on all three spatial-revisit metrics, leads three of five event-recapture criteria, and receives the highest mean human rating on all six criteria.
Introduction
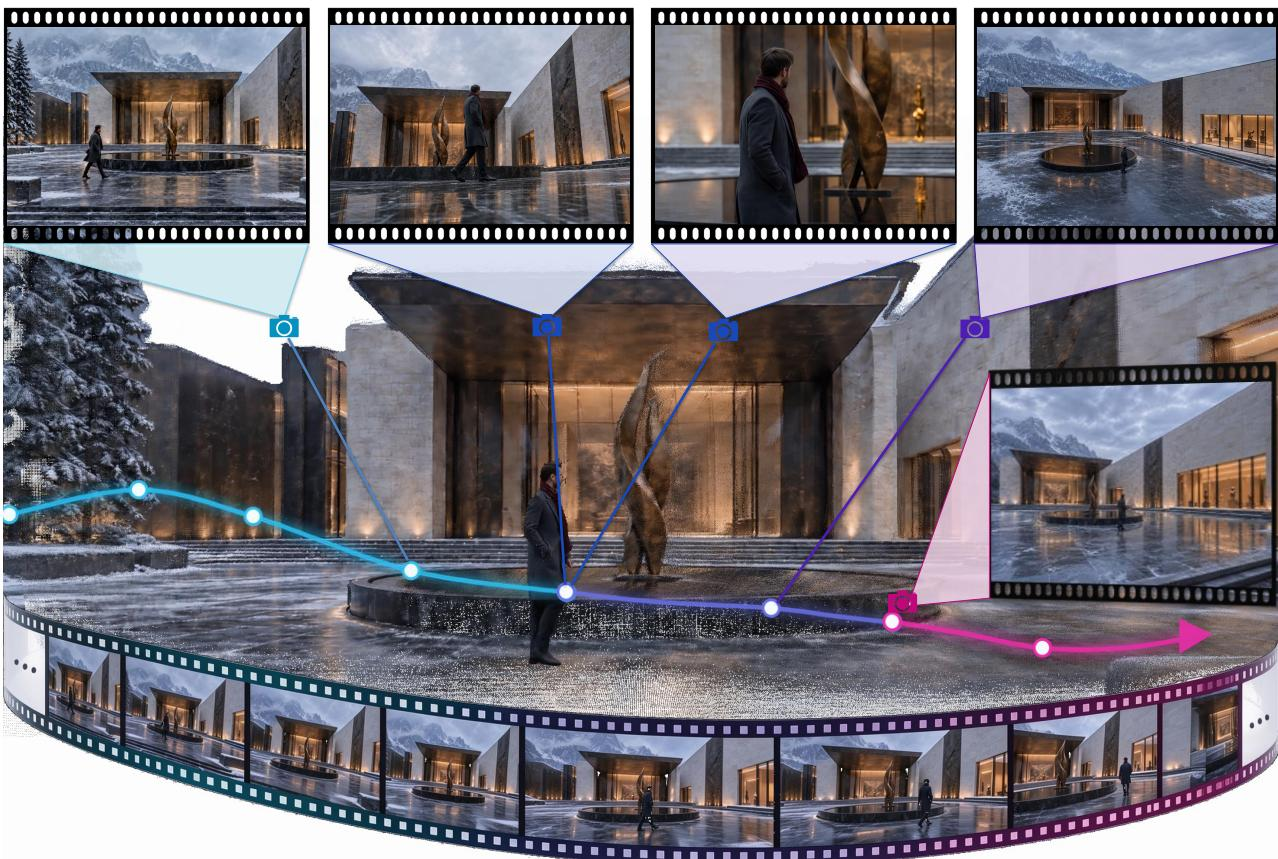
Agentic video generation turns a screenplay into a sequence of video shots, but story coherence depends on preserving spatial and temporal relationships across non-consecutive shots, such as returning to an earlier room or replaying a past event from a new camera view. Prior systems usually maintain continuity through recent frames, text summaries, or retrieved reference images, which helps locally consecutive shots but does not provide a shared, addressable world state across space and time, and it can propagate errors from unreliable generated content. The authors introduce Any Time, Any Space (ATAS), a world-state-centric framework that maintains persistent scene and event memories: a scene state for spatial structure in a shared coordinate frame and an event state for dynamic observations with temporal context. ATAS compiles each screenplay request into a grounded shot specification, retrieves relevant evidence, conditions a short-video generator, and validates each generated clip before allowing it to update the persistent world state.
Method
The ATAS framework transforms a high-level screenplay into coherent short video shots by maintaining a persistent world state that preserves spatial and temporal evidence across generations. The core of this approach is a continuous loop of compilation, generation, validation, and state updating. The overall workflow is illustrated below.
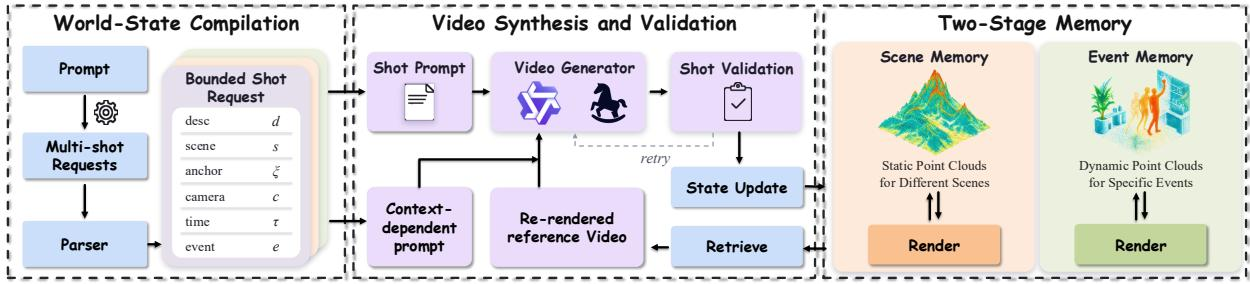
The process begins with World-State Compilation. Instead of processing a list of fully specified video prompts, the system takes a high-level screenplay u and recursively splits it by scene, spatial and temporal relations, event references, and camera requirements. This produces a schedule of bounded shot requests Qt={qt,1,…,qt,Kt}. Each renderable request is structured as qt,k=(dt,k,st,k,ξt,k,ct,k,τt,k,et,k), where the tuple encapsulates the local shot description, scene identifier, spatial anchor, target camera, requested time interval, and an optional event identifier.
To condition the video generation, the authors leverage a Two-Stage Memory architecture that maintains the persistent world state Wt=(St,Et). The scene memory St stores accepted static geometry within a coordinate frame established by a source observation. When a request requires spatial context, the system renders these coordinates at the requested spatial anchor and camera to produce a re-rendered scene reference Ctscene. Concurrently, the event memory Et retains dynamic evidence as a set of records containing scene, event, source observation, time interval, and frame-level RGB-D, mask, and dynamic point-cloud data. If a request references a specific event, the system retrieves the matching dynamic context Ctevent directly from this memory.
During Video Synthesis and Validation, the local description from the request forms the shot prompt, while the retrieved scene and event references form the context-dependent prompt Ct=(Ctscene,Ctevent). The short-video generator G utilizes both prompts to synthesize a clip Vt=G(qt,Ct). Following generation, the clip undergoes a rigorous validation process that yields two independent decisions. A film review determines if the clip is accepted for delivery (ft=1). If accepted, reconstruction and registration align the generated clip to the scene coordinate frame, yielding a registration decision (rt=1).
Finally, the system performs a State Update. A candidate observation is admitted to the persistent state only if it passes the film review, registration, and an additional admission check (at=1) that verifies provenance and scene scope. The state transition is governed by the rule:
Wt+1={Wt+1,Wt,ft=rt=at=1,otherwise.This design ensures that film delivery and state updating are decoupled. A generated clip can remain part of the final film even if it fails to update the persistent world state, preventing invalid observations from corrupting the spatial and temporal evidence required for subsequent shots.
Experiment
The paper evaluates long-form video generation on VBench, ST-Bench, and ViStory, with additional spatial revisit, event recapture, human ratings, and efficiency measures. Results show that ATAS improves cross-shot consistency across multiple generators while retaining competitive local quality, and it recovers target views and source-grounded event replays better than compared multi-shot and 3D-guided methods, with human raters also preferring its outputs. Ablations indicate that scene and event memory contribute complementary continuity gains, recursive compilation amplifies these benefits, and persistent memory reduces retries and film-review rejection at a measurable runtime and throughput cost.
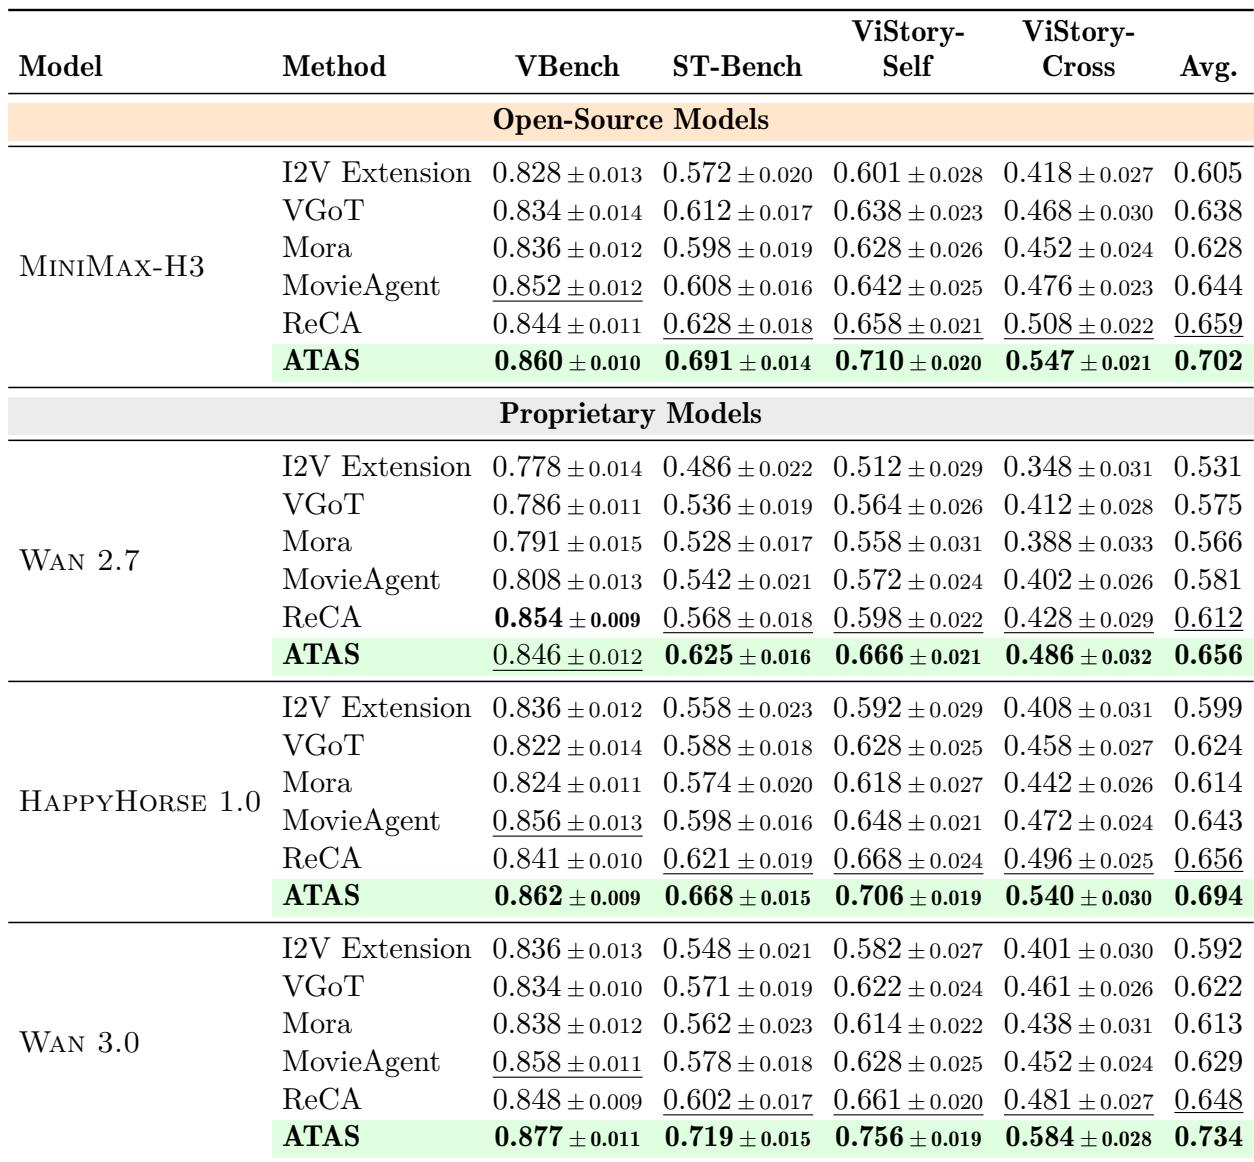
ATAS consistently improves agent-level benchmark performance over compared multi-shot methods, leading every reported aggregate on MiniMax-H3, Wan 3.0, and HappyHorse 1.0. Within the MiniMax-H3 block, it ranks first across all individual metrics and the average. The pattern across backbones suggests the benefit comes from persistent multi-shot state rather than a single renderer. ATAS leads every reported aggregate on MiniMax-H3, Wan 3.0, and HappyHorse 1.0. In the MiniMax-H3 block, ATAS ranks first on VBench, ST-Bench, ViStory-Self, ViStory-Cross, and average, with ReCA generally the closest competitor on consistency measures. With Wan 2.7, ATAS remains ahead on ST-Bench and both ViStory consistency scores despite trailing on VBench.
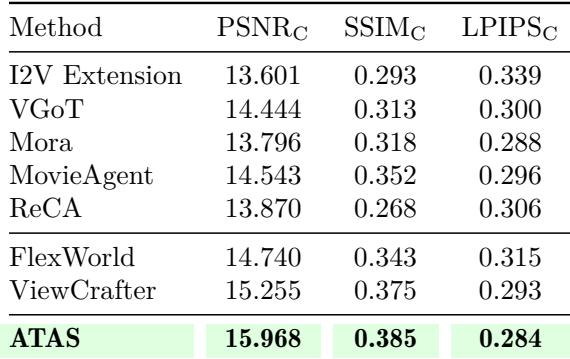
On the spatial revisit benchmark, ATAS outperforms the compared agent-based and 3D-guided methods for target-view recovery under a common-visibility mask. Among the listed baselines, ViewCrafter is strongest overall, while ReCA shows weaker structural similarity. The results indicate that persistent multi-shot state improves spatial consistency when returning to previously visited locations. ATAS achieves higher PSNR and SSIM, and lower LPIPS, than all compared methods, including the strongest listed baseline ViewCrafter. ViewCrafter leads the listed baselines on all three spatial revisit metrics, while ReCA has the lowest SSIM and among the lowest PSNR values. The improvement appears across both agent-based and 3D-guided approaches, supporting the benefit of persistent multi-shot state rather than a single renderer.
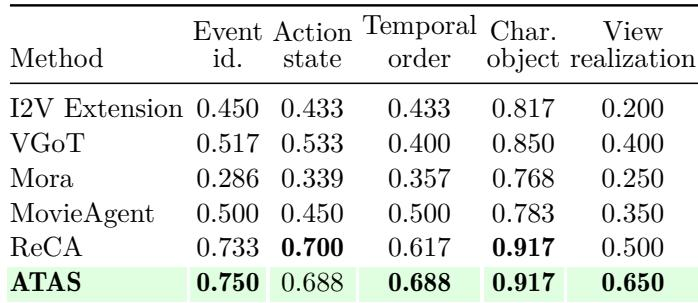
ATAS achieves the strongest source-grounded event recapture among the compared methods, leading on event identity, temporal order, and viewpoint realization while tying ReCA on character and object consistency. Its action-state preservation is slightly below ReCA but above the other baselines. Human ratings similarly highlight script faithfulness and character consistency as clearer strengths, while background consistency and narrative coherence remain lower. ATAS leads on event identity, temporal order, and viewpoint realization, with the highest viewpoint realization score among compared methods. ATAS ties ReCA on character and object consistency and trails ReCA only slightly on action-state preservation, indicating exact action-state reproduction remains the weaker area.
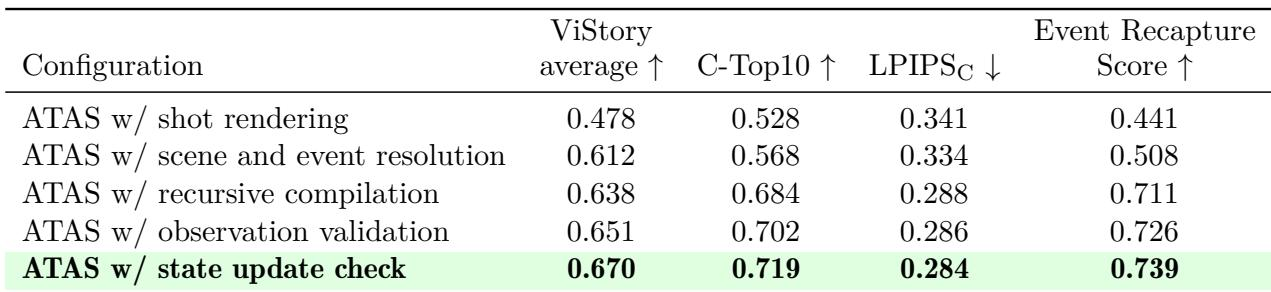
Cumulatively adding memory, recursive compilation, observation validation, and state-update checking improves ViStory average, retrieval consistency, and event recapture while lowering spatial error. The largest gains come from memory and recursive compilation, especially for event continuity and C-Top10. Later validation and state-check components add smaller refinements, suggesting they preserve capabilities rather than introducing a separate retrieval effect. Scene and event resolution substantially improves ViStory average and event recapture, with only a modest spatial-error reduction. Recursive compilation produces the largest event recapture gain and a clear improvement in retrieval consistency. Observation validation and state-update checking contribute small further gains across most metrics, indicating they mainly safeguard existing capabilities.
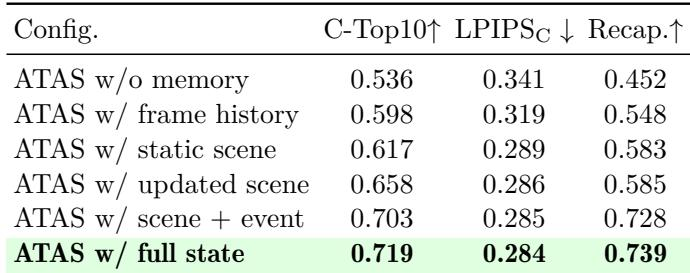
This ablation varies stored evidence and state checks while keeping the ATAS generation model fixed. Frame history improves all three reported continuity measures over no memory, with static and updated scene evidence mainly lowering spatial error and improving character matching, while event memory produces the largest recapture gain. Full state achieves the strongest overall scores, though the gain over scene-plus-event is modest. Frame history improves continuity, recapture, and spatial consistency compared with no memory. Static scene evidence primarily reduces spatial error, while updated scene evidence improves character matching with little change in recapture. Event memory gives the largest recapture improvement, and full state reaches the best overall metrics with only a modest final increase.
The experiments evaluate ATAS on multi-shot video generation benchmarks, spatial revisit recovery, and source-grounded event recapture, along with ablations over memory and state components. ATAS consistently leads agent-level and spatial consistency results, with persistent multi-shot state improving benchmark aggregates, target-view recovery, event identity, temporal order, and viewpoint realization, though exact action-state reproduction remains a weaker area. Ablations show that memory and recursive compilation provide the largest gains in continuity and event recapture, while scene and event evidence, validation, and state checks mainly refine spatial consistency, character matching, and safeguard existing capabilities.