Command Palette
Search for a command to run...
Doc 2 Harness: 코딩 에이전트의 장기 지평 하네스 엔지니어링에 대한 LLM 벤치마킹
Doc 2 Harness: 코딩 에이전트의 장기 지평 하네스 엔지니어링에 대한 LLM 벤치마킹
초록
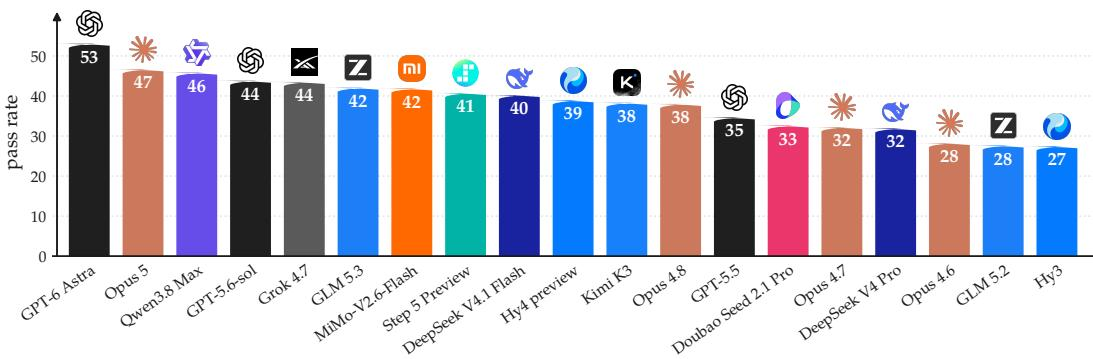
대규모 언어 모델로 구동되는 에이전트는 도구를 사용하고 실제 작업 공간을 수정하는 장기 지평(long-horizon) 작업에 점점 더 많이 배치되고 있다. 이들이 얼마나 잘 수행하는지는 모델 자체만큼이나 모델을 둘러싼 하네스(harness)에 달려 있다. 기존 벤치마크는 고정된 하네스 아래에서 다운스트림 작업의 성공을 측정하므로, 하네스 엔지니어링 자체는 탐구되지 않은 채 남아 있다. 우리는 장기 지평 하네스 엔지니어링을 직접 평가하는 2단계 벤치마크인 Doc2Harness를 제안한다. 1단계에서는 고정된 빌더 하네스 내부에서 동작하는 빌드 모델이 인터페이스만 포함된 계약 골격과 12개의 프런티어 하네스 전반의 동작을 통합한 개발 문서를 받고, 격리된 컨테이너에서 완전한 후보 하네스를 구축한다. 2단계에서는 동결된 후보 하네스가 구축 환경과 분리된 컨테이너들에서 테스트 케이스마다 하나씩 실행되며, 스크립트로 작성된 모의 모델에 의해 end-to-end로 구동된다. 우리는 모델로 전송된 요청, 디스크의 파일, 프로세스 종료 코드, 명령 출력이라는 네 가지 관찰 가능한 채널을 사용하여 각 테스트 케이스를 채점하며, 양성 대조군을 통해 무의미한 통과를 배제한다. 19개의 프런티어 모델을 328개의 테스트 케이스에서 각각 3회의 독립적인 빌드로 평가한 결과, GPT-6 Astra가 53.05%로 가장 높은 통과율을 기록했고, 가장 약한 모델은 27.44%에 그쳐 약 26%포인트의 격차를 보였다. 가장 강한 모델조차 테스트 케이스의 거의 절반에서 실패하며, 실패는 여러 모듈에 걸친 횡단적 기능이 어떻게 분할되는지와 관련된 부분에 집중된다. 우리가 아는 한, Doc2Harness는 장기 지평 하네스 엔지니어링을 측정하는 최초의 결정적 벤치마크를 제공한다.
One-sentence Summary
Researchers from the Institute of Computing Technology, Chinese Academy of Sciences, Tsinghua University, Peking University, and Southeast University propose Doc2Harness, a two-stage benchmark that evaluates long-horizon harness engineering by building candidate harnesses from interface-only contracts and consolidated development documents and then scoring them in isolated containers via requests, files, exit codes, and command output, with GPT-6 Astra achieving the highest pass rate of 53.05% across 328 test cases.
Key Contributions
- The paper introduces Doc2Harness, a two-stage benchmark that directly evaluates long-horizon harness engineering by having a build model construct a complete candidate harness from a contract skeleton and a development document consolidating functionality across twelve frontier harnesses, then running the frozen harness under a scripted mock model in isolated containers.
- Each test case is scored through four observable channels: the requests sent to the model, the files on disk, the process exit code, and the command output; positive controls rule out vacuous passes and enable clause-by-clause behavioral conformance checking.
- Across nineteen frontier models, each evaluated with three independent builds on 328 test cases, GPT-6 Astra achieves the highest pass rate at 53.05%, while the weakest model reaches 27.44%. Even the strongest model fails nearly half of the test cases, with failures concentrated on how cross-cutting functionality is split across modules; the benchmark is presented as the first deterministic benchmark for measuring long-horizon harness engineering.
Introduction
As LLM-driven coding agents operate in more complex settings, the harness that manages interaction loops, tool execution, permissions, state, failure recovery, and verification determines how much of a model’s capability reaches the environment. However, prior SWE benchmarks rely on mature repositories and unit tests, which suit code completion or reconstruction but do not capture the many valid harness implementations or black-box behavioral requirements. Existing harness benchmarks also measure quality through downstream tasks, which confounds the driving model and test-time search, while output-only scoring can miss unauthorized behavior. The authors propose Doc2Harness, a two-stage deterministic benchmark where a build model constructs a harness from a development document and an interface-only contract skeleton, and the resulting harness is then driven by a mock model through preset scripted sessions, with observations across four channels and positive controls to rule out vacuous passes. This assesses harness development directly rather than through downstream task performance.
Dataset
Dataset Description
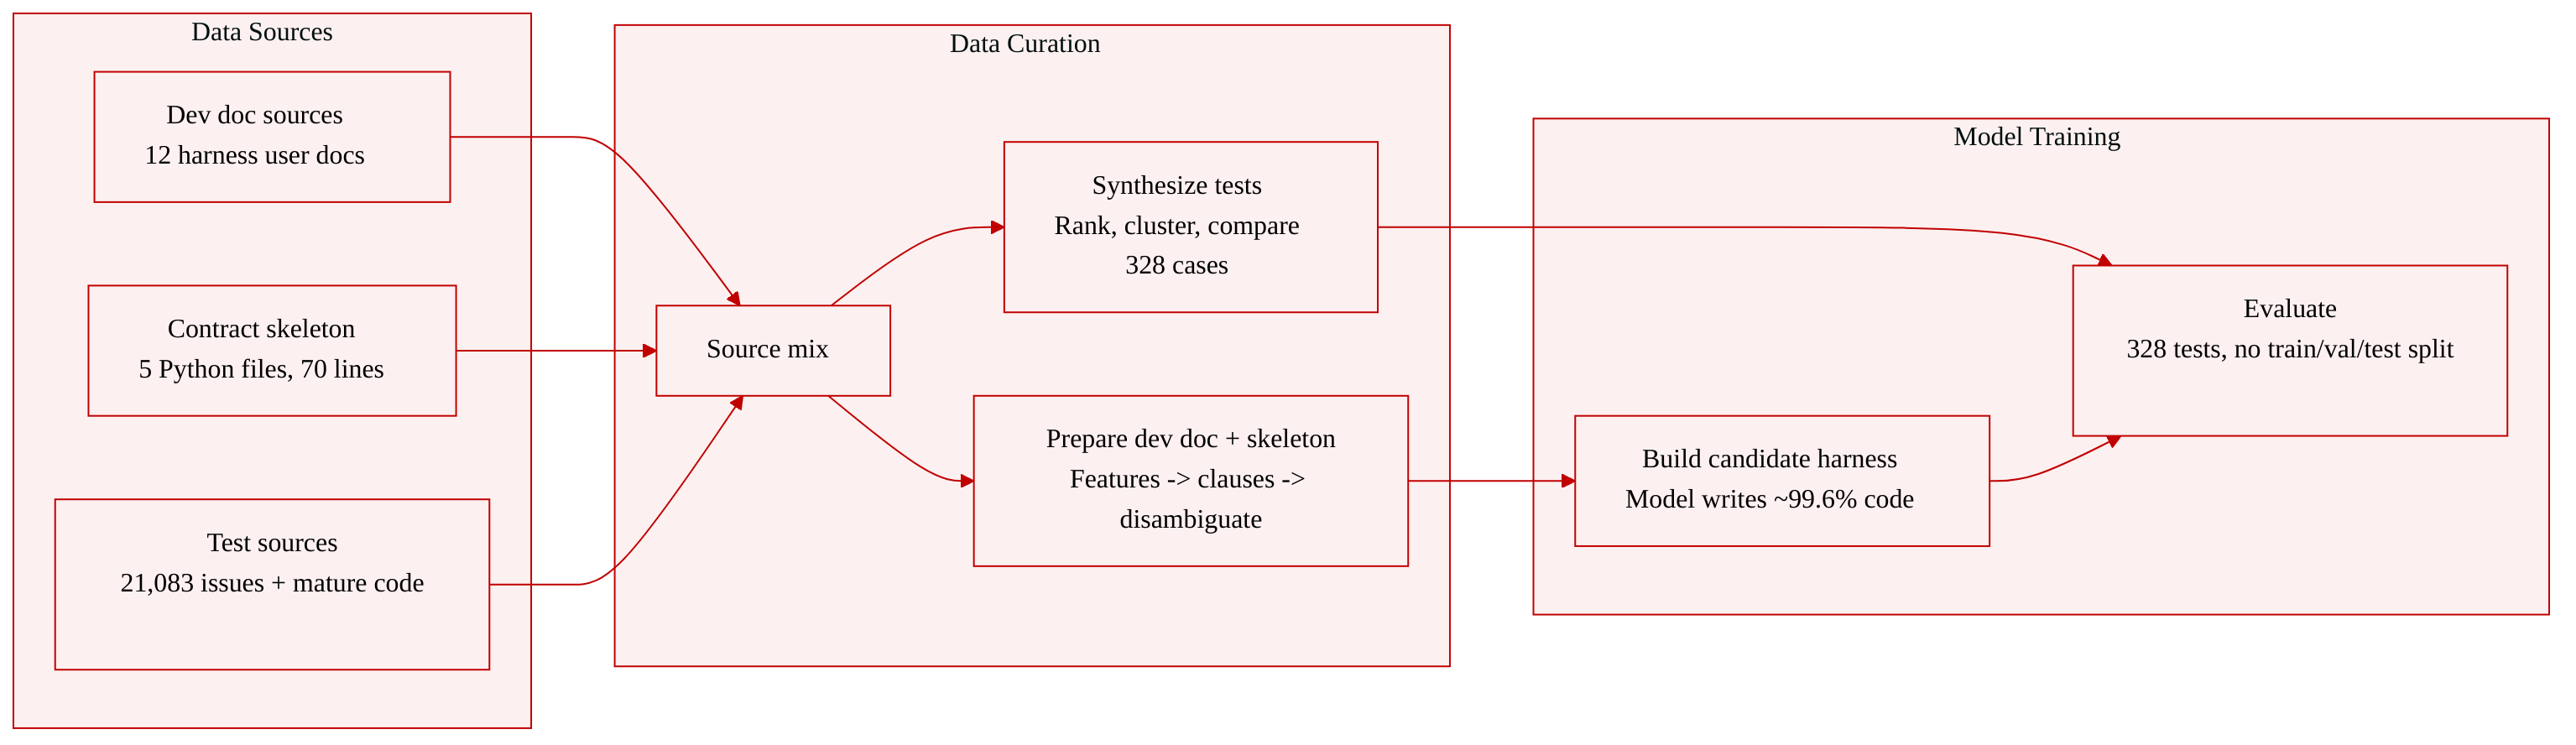
The authors use three main text-based artifacts: a development document, a contract skeleton, and a test suite.
1. Development document
Sources
- User documentation from 12 frontier harnesses: Claude Code, Kimi Code, Gemini CLI, Qwen Code, OpenCode, OpenClaw, Codex CLI, Aider, OpenHands, Cline, Crush, and Cursor.
Processing and composition
- First, candidate features are collected from the documentation.
- The authors then fill in invocation form, parameter semantics, and boundary behavior for each candidate.
- The resulting inventory is merged, deduplicated, and pruned into a set of clauses.
- Each clause has a syntax, a meaning, and an expected behavior.
- Clauses cover built-in tools, top-level commands, subcommands, permission and role modes, global flags, in-session commands, persistent memory, convention files, consistency rules, exit codes, and the evaluation API.
- Observable effects are restricted to four channels: model requests, files on disk, process exit code, and command output.
- Disambiguation merges overlapping commands, such as
/compactand/summarize, and separates distinct concepts that share a name, such asplanas a permission mode versus role-based planning responsibility.
2. Contract skeleton
Sources and composition
- Five Python source files, roughly seventy lines total.
- One install script, one entry script, and one project config.
- Three immutable external contracts: CLI, headless entry point, and API for driving automated evaluation.
Scale
- A representative completed candidate harness contains roughly 30 Python source files and about 16,000 lines.
- About 99.6% of the final candidate harness is written by the build model beyond the contract skeleton.
3. Test suite
Sources and filtering
- Public issue mining:
- Issues are pulled from Claude Code, OpenCode, Gemini CLI, and Kimi Code.
- After filtering out pull requests, the counts are 9,868, 5,438, 4,831, and 946, for 21,083 total.
- Records are ranked by relevance to the development document and manually reviewed from the top until marginal yield falls.
- Related reports are clustered, with one candidate test case per cluster.
- Overlapping clusters are merged if they would pass and fail together.
- Retained candidates must be convertible into deterministic assertions and must not already be covered.
- Cross-harness comparison:
- Uses public source of mature harnesses such as Kimi Code and Qwen Code.
- Candidate and comparison sources are partitioned into modules by development-document features.
- Implementation differences are enumerated module by module.
- A difference is kept only if it is derivable from the purpose of a development-document clause.
- Existing-suite expansion:
- Variants are derived from seed test cases.
- A distance check discards candidates too close to their seed.
Statistics
- The final test suite contains 328 test cases.
- Test cases are partitioned into nine mutually disjoint categories.
- 130 test cases are gated by at least one positive control.
- Among those, 114 are gated by one control, 15 by two, and one by three.
- The widest positive control gates six test cases and confirms that a symlink pointing outside the workspace is readable.
- Two other positive controls gate five test cases each: one for range reading and one for search hit behavior.
How the data is used
- There is no traditional training split or mixture ratio.
- The development document and contract skeleton are placed in a newly created empty container.
- The build model writes the candidate harness using only the designated model gateway, with no other external network access.
- A preflight check confirms that the container holds no unexpected files and that OpenCode starts normally.
- The test suite is used for evaluation; each test case must anchor to a development-document clause and discriminate between implementations.
- Evaluation is not an iterative build-evaluate-repair loop. Each build allows up to three submissions.
- No image cropping or visual metadata construction is described; the artifacts are text-based documents, source files, and test cases.
Method
The authors propose Doc2Harness, a two-stage evaluation framework designed to assess the ability of build models to develop coding agent harnesses. The overall pipeline consists of a Construction stage and an Evaluation stage, as illustrated in the framework diagram.
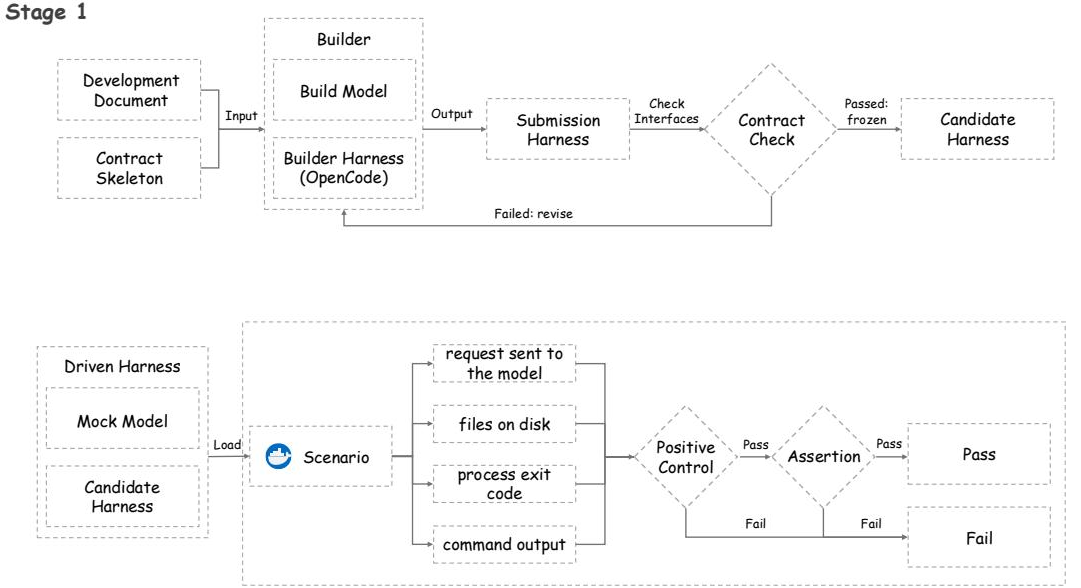
In Stage 1, the Construction phase, the builder combines the build model under evaluation with a fixed builder harness, specifically the open-source framework OpenCode. The builder takes a development document and a contract skeleton as input. The contract skeleton provides the necessary interfaces without implementation details. The builder iteratively constructs a candidate harness and issues a submission. A contract check then verifies that the deliverable compiles, installs, contains all required commands, lacks placeholder stubs, and implements the three contract interfaces. If the check passes, the deliverable is frozen as the candidate harness. If it fails, the builder revises and resubmits within its quota.
In Stage 2, the Evaluation phase, the frozen candidate harness is loaded into isolated containers alongside a mock model to form a driven harness. The mock model executes the scenario of each test case according to a preset script, avoiding the instability of real large language models. The effects of the execution are observed across four channels: requests sent to the model, files on disk, process exit codes, and command output. To ensure that a passing test case reflects genuine requirement fulfillment rather than a failure in the observation mechanism, the framework employs a positive control mechanism. A test case is recorded as a pass only if it passes its own assertion and all gating positive controls.
To generate the test cases used in Stage 2, the authors employ a yield-driven cycle of three synthesis methods, ensuring both broad coverage and deep inspection.
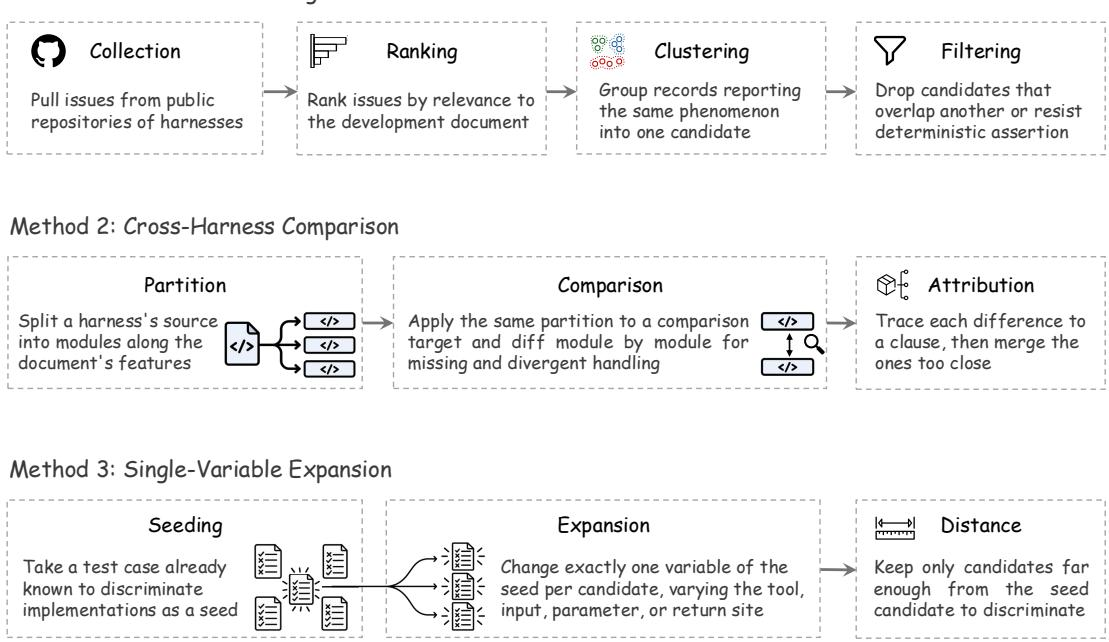
The first method, Public Issue Mining, leverages the assumption that defects in mature harnesses overlap with mistakes made by build models. The authors collect public issues from frontier harness repositories, rank them by relevance to the development document, cluster records reporting the same phenomenon, and filter out overlapping or non-deterministic candidates.
The second method, Cross-Harness Comparison, broadens coverage by comparing a candidate harness against the source code of a mature comparison target. The source is partitioned into modules based on the features listed in the development document. The authors enumerate implementation differences module by module and attribute them to specific clauses, retaining only those that stem from the purpose of a clause.
The third method, Single-Variable Expansion, deepens the inspection by starting from a seed test case known to discriminate between implementations. The authors vary exactly one variable in the seed scenario, such as the tool used, input form, erroneous parameter, or the site where the result is returned. A distance check ensures that the new candidate is sufficiently different from the seed to add discriminative power. These three methods are used in alternation until the marginal yield declines.
Experiment
The study evaluates nineteen models from eleven vendors using a two-stage setup: a builder harness constructs candidate harnesses via OpenCode under turn, time, and submission limits, then each test case runs once in its own container with a timeout. The main results indicate the suite is not saturated and discriminates among models, with top models differing mainly on boundary scenarios, while category analyses show substantial but positively correlated differences that point to one overall capability. Architecture results show implementation scale is driven primarily by model identity and fragmented harnesses tend to score lower; limitations note that the protocol measures a single build and correlated test cases may cause clustered failures.
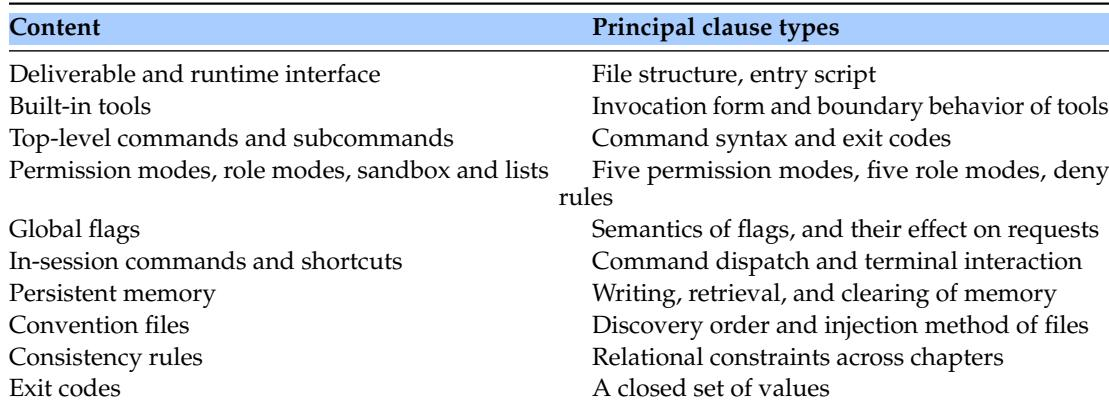
The development document structures its clauses around externally observable interface areas, including the deliverable and runtime interface, built-in tools, top-level commands, permission and role modes, global flags, in-session commands, and persistent memory. Each area is assigned principal clause types that define verifiable behavior such as file structure and entry points, tool invocation boundaries, command syntax and exit codes, access rules, flag effects on requests, terminal interaction, and memory operations. Deliverable and runtime interface clauses cover file structure and the entry script, grounding the specification in observable project layout. Built-in tool clauses focus on invocation form and boundary behavior, while command clauses specify syntax and exit codes. Access and interaction clauses describe permission modes, role modes, deny rules, flag semantics, command dispatch, and terminal interaction. Persistent memory clauses define the writing, retrieval, and clearing of stored information.
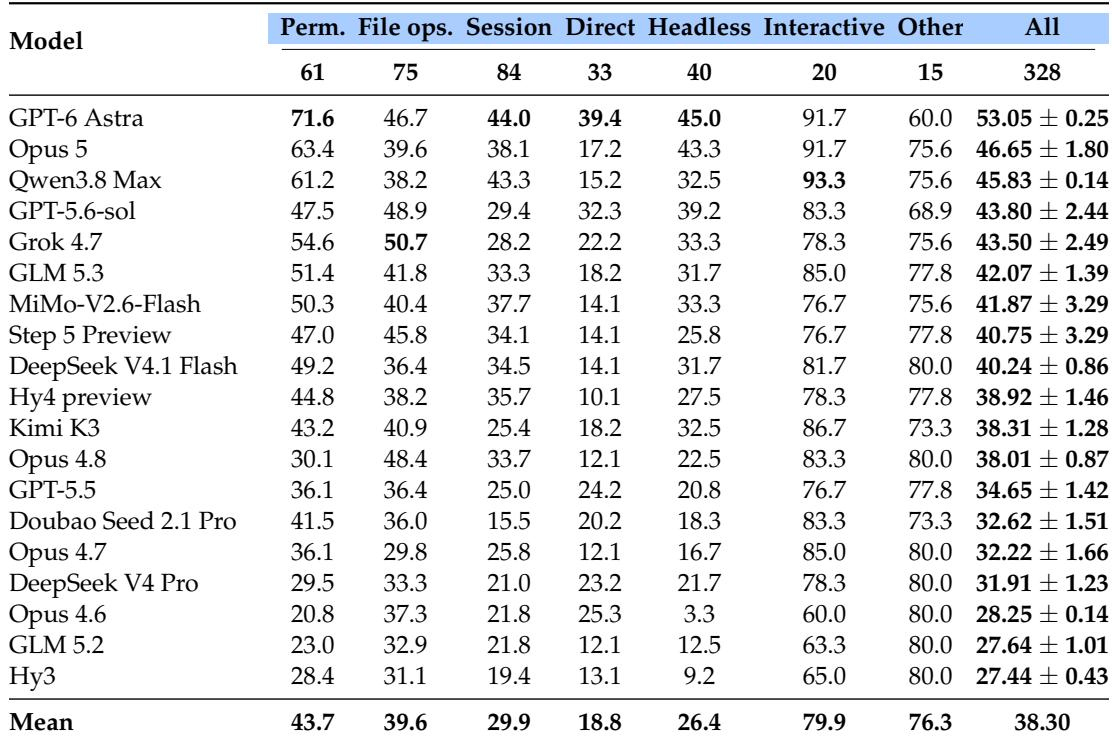
The suite is far from saturated: the strongest model passes just over half of the test cases while the weakest passes just over a quarter, leaving a gap of more than twenty-five percentage points. Among the leading models, overall pass rates are relatively close, but the top model gains its edge on boundary scenarios where the second-ranked model drops sharply. Category performance varies, with interactive terminal tasks generally scoring highest and direct-drive tasks scoring lowest for the reported models. The strongest model fails nearly half of the test cases, while the weakest passes just over a quarter, so the suite is not saturated. The overall leader trails on ordinary scenarios but moves ahead on boundary scenarios, where the second-ranked model's pass rate drops sharply.
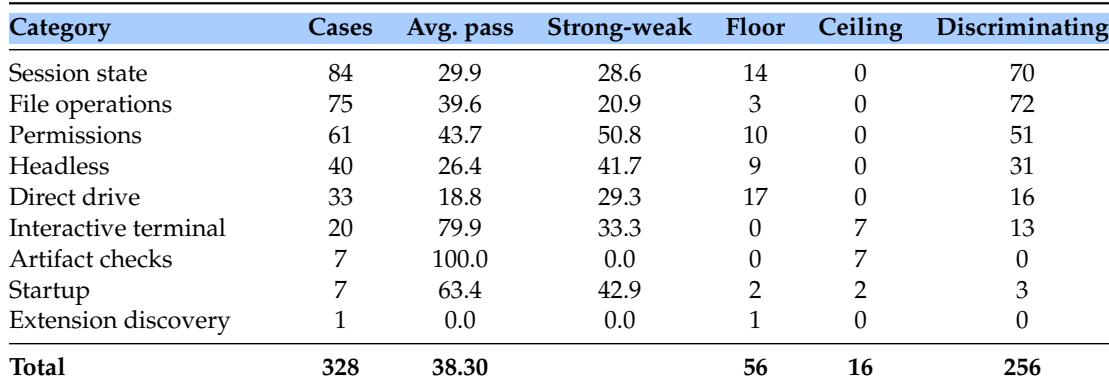
Evaluation categories differ sharply in discriminative power: permissions separates candidate harnesses most strongly, file operations has a similar average pass rate but a much smaller gap, and interactive terminal is nearing saturation while artifact checks provide no spread. Floor test cases are concentrated in direct drive, session state, permissions, and headless. Rankings vary substantially across categories despite positive pairwise correlations, consistent with a largely one-dimensional capability. The permissions category provides the greatest model separation, while file operations has a similar average pass rate but a much smaller strong-weak gap. Floor test cases are concentrated in direct drive, session state, permissions, and headless, and artifact checks are passed by every candidate harness.
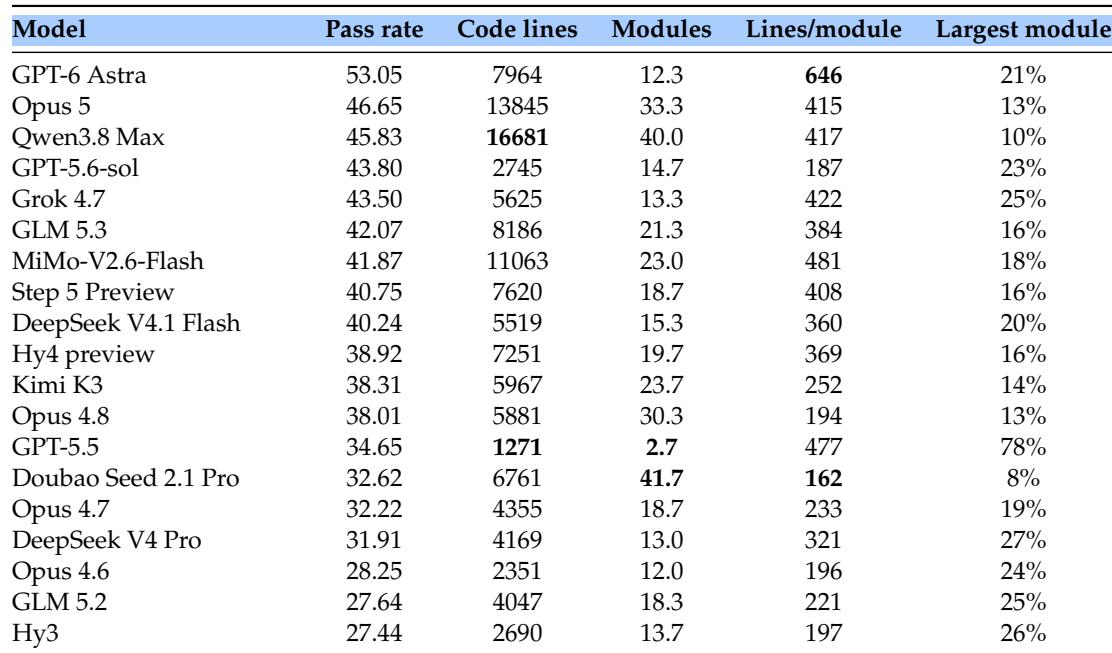
Architecture metrics vary mainly by model identity rather than among repeated builds of the same model. Larger harnesses by code line count tend to have higher pass rates, while fragmentation into more modules is associated with lower pass rates after controlling for code size. Harnesses with more lines per module tend to score better, suggesting cohesive larger modules are more effective. Implementation scale is driven primarily by model identity, with far less variation among builds of the same model. Controlling for code size, fewer modules and more lines per module are associated with higher pass rates, indicating fragmentation is costly.
The evaluation checks harnesses against clauses covering the deliverable and runtime interface, built-in tools, commands, access and role modes, global flags, in-session behavior, and persistent memory. The suite is not saturated: the strongest model passes just over half of the test cases while the weakest passes just over a quarter, and the top model gains its edge mainly on boundary scenarios, with interactive terminal tasks scoring highest and direct-drive tasks lowest. Category-level analysis shows permissions provides the strongest separation while artifact checks provide no spread and interactive terminal is nearly saturated, with floor cases concentrated in direct drive, session state, permissions, and headless. Architecture results indicate model identity drives implementation scale, and after controlling for code size, fewer and larger modules are associated with higher pass rates.