Command Palette
Search for a command to run...
VideoJev: 비디오 이해와 상호작용을 위한 System One 모델
VideoJev: 비디오 이해와 상호작용을 위한 System One 모델
초록
시각 에이전트는 진행 상황을 추적하고 다음 행동을 선택하기 위해 비디오 관찰을 적시의 결정으로 전환해야 한다. 최근 부상하는 System One 패러다임을 바탕으로, 본 연구는 비디오 이해와 상호작용을 구조화된 결정 과제로 정식화하는 모델군 VideoJev를 제안한다. 사전학습된 멀티모달 대규모 언어 모델(MLLM)을 적응시키되, 자기회귀적 답변 디코딩을 공유 헤드로 대체하여 비디오 증거를 기준으로 시간 구간과 텍스트 선택지에 점수를 매긴다. 이 점수는 이벤트 구간 또는 답변 선택지를 산출하여 시간적 접지와 객관식 비디오 질의응답을 통합한다. 이는 MLLM의 의미적 유연성과 에이전트가 직접 사용할 수 있는 효율적인 결정을 결합한다. 상호작용이 전개됨에 따라 새로운 목표와 중간 결과는 동일한 시각 이력에 대한 추가 질의를 유발한다. 따라서 VideoJev는 질의가 도착할 때는 Cached inference를, 여러 질의는 단일 순전파에서 Joint inference를 사용해 시각 계산을 재사용한다. 세 개의 시간적 접지 벤치마크에서 VideoJev-4B와 VideoJev-35B-A3B는 백본 대비 평균 mIoU를 각각 6.7포인트와 10.8포인트 개선했고, 측정된 추론 속도는 2.8–3.1배 향상되었다. 네 개의 비디오 QA 벤치마크에서는 두 모델 모두 Thinking mode에서 백본과 유사한 성능을 달성했으며, 측정된 추론 속도는 100배를 초과했다. 이러한 결과는 구조화된 시각적 판단을 복잡하고 개방적인 워크플로로 구성하기 위한 통합적이고 재사용 가능한 결정 인터페이스를 제공한다.
One-sentence Summary
NJU et al. propose VideoJev, a System One model family that replaces autoregressive decoding with a shared head scoring temporal intervals and textual options to unify temporal grounding and multiple-choice video QA, employs Cached and Joint inference for efficient visual reuse, and achieves 6.7 to 10.8 point mIoU gains over backbones with measured speedups of 2.8 to 3.1× for temporal grounding and over 100× for video QA.
Key Contributions
- VideoJev introduces a family of video System One models that replace autoregressive answer decoding in pretrained multimodal large language models with a shared scoring head for temporal intervals and textual options, unifying temporal grounding and multiple-choice video QA as direct candidate scoring.
- The models reuse visual computation across repeated queries through Cached inference for arriving queries and Joint inference for multiple queries processed together, supporting efficient structured judgments over the same visual history.
- Across three temporal grounding benchmarks and four video QA benchmarks, VideoJev-4B and VideoJev-35B-A3B improve mean mIoU over their backbones by 6.7 and 10.8 points with 2.8 to 3.1 times inference speedups on temporal grounding, while achieving QA performance comparable to their backbones in Thinking mode with over 100 times speedups.
Introduction
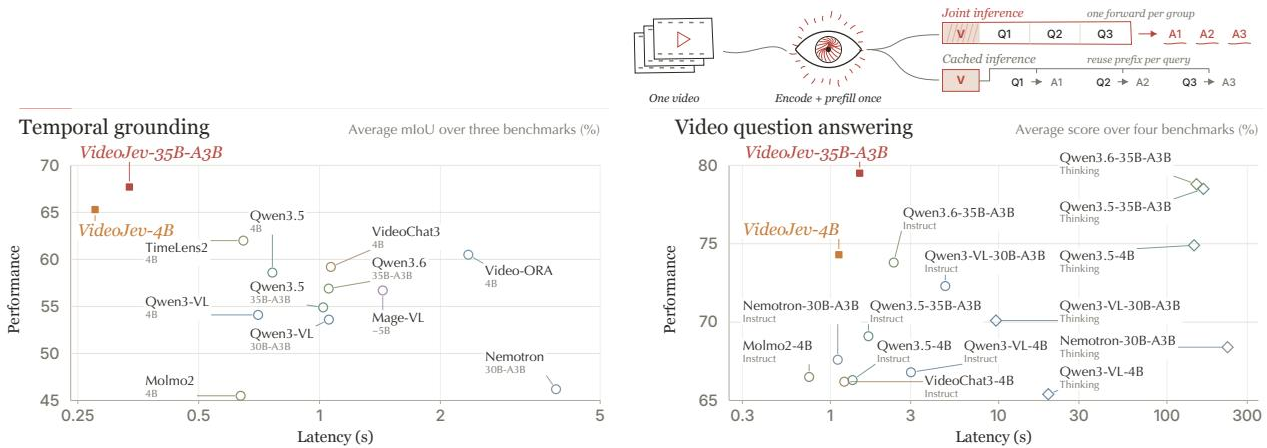
Video understanding for agents requires timely, structured decisions over shared visual history, such as verifying whether an ingredient was added before choosing the next cooking step. Prior work offers complementary but incomplete strengths: discriminative vision models make efficient predictions yet remain task-specific or tied to fixed label spaces, while video multimodal large language models provide flexible semantic understanding but rely on autoregressive generation even for compact outputs like temporal boundaries or multiple-choice answers. The authors introduce VideoJev, a family of video System One models that unifies temporal grounding and multiple-choice video question answering through direct candidate scoring. It reuses visual computation with cached inference for arriving queries and joint inference for batched queries, and the authors evaluate dense 4B and mixture-of-experts 35B-A3B models across seven benchmarks, reporting improved grounding and QA performance with substantial inference speedups.
Method
The authors propose VideoJev, a unified video decision framework that scores temporal intervals and textual options using a shared head over pretrained multimodal representations. As shown in the figure below, the architecture adapts a pretrained multimodal large language model with a causal language backbone and native video inputs.
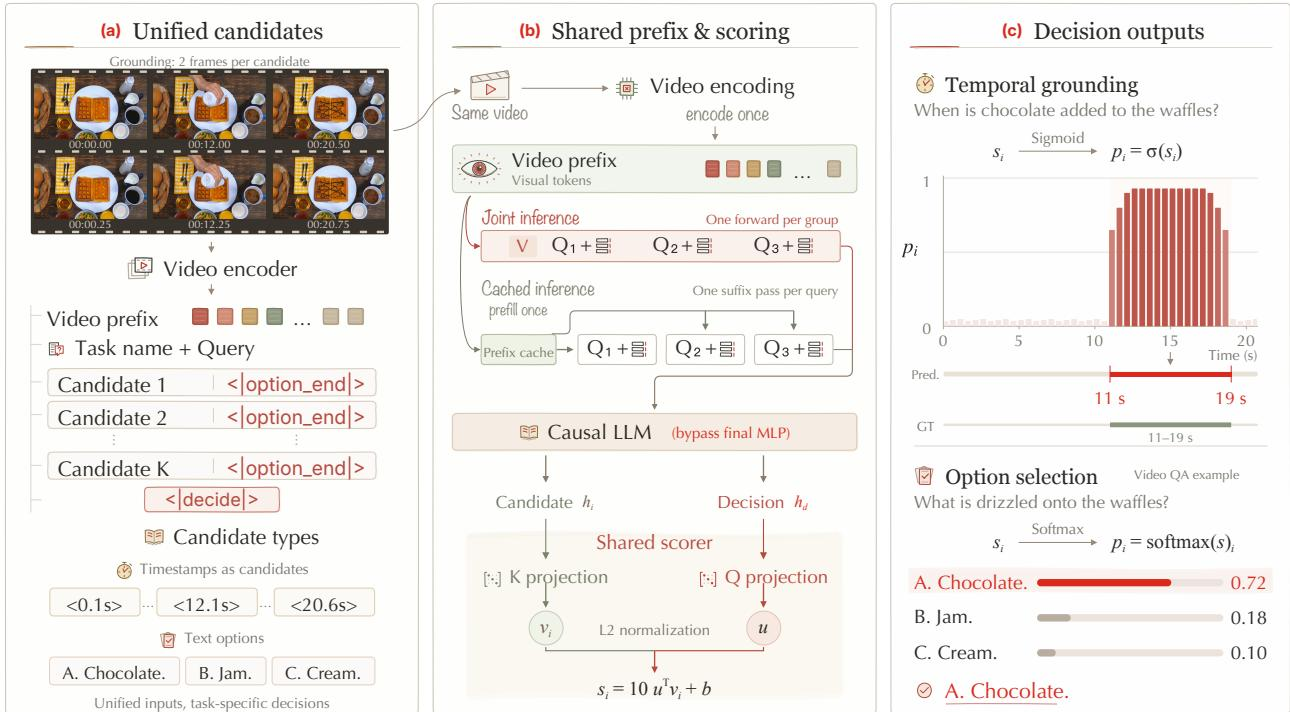
To leverage the semantic similarity supported by pre-MLP features, the authors remove the final MLP and replace the language-model output head with a candidate scorer. They introduce two new tokens, <|option_end|> and <|decide|>, which provide candidate readouts and a query-level decision readout, respectively. Both tokens are initialized from the pretrained <|im_end|> embedding. Separate linear projections map their hidden states to 512 dimensions and normalize them to unit length:
where hd and hi are the decision and candidate states, Wq,Wk,bq,bk are learned projection parameters, and ∥⋅∥2 is the Euclidean norm. The normalized similarity yields the logit si, scaled by a fixed factor of 10 and a learned scalar bias b.
Given a video V, a language query q, and K candidates C={c1,…,cK}, the model places video tokens first, followed by the task instruction, query, and candidate list. Each candidate ends with <|option_end|>, and the list ends with <|decide|>. Causal modeling allows candidate readouts to utilize the video, query, and preceding candidates, while the decision readout processes the full list. For temporal grounding, candidates are timestamp texts identifying frame-pair intervals, and their sigmoid scores indicate event membership to decode a contiguous span. For multiple-choice video QA, candidates are answer texts, and softmax normalizes their logits into probabilities to select the highest-scoring option.
To optimize computational efficiency, the authors design reusable video computation. Since causal modeling makes the video prefix independent of subsequent queries, its computation can be shared. In cached inference, the video is encoded and prefilled once, and each arriving query branches from the cached prefix. In joint inference, multiple queries and their candidate lists follow a single video prefix, with a separate <|decide|> readout for each query, allowing one causal language-model forward pass to yield all query scores.
For temporal grounding, the timeline is partitioned into K candidate intervals. The authors train local membership and coverage supervision to identify relevant intervals and cover the event as a whole. They employ multi-label binary cross-entropy to supervise each candidate independently:
LBCE=−K1i=1∑K[yilogpi+(1−yi)log(1−pi)]where yi is the ground truth label and pi=σ(si) is the membership probability. To directly reward event coverage, they add a soft intersection-over-union loss over the positive intervals:
LIoU=1−∑idi[yi+pi(1−yi)]∑idipiyiwhere di is the interval duration. To decode a continuous event span from interval scores, the authors adjust logits by a probability threshold τ and select the nonempty contiguous range with the largest sum using Kadane's algorithm in O(K) time:
(a⋆,b⋆)=arg1≤a≤b≤Kmaxi=a∑b[si−log1−ττ]For multiple-choice video QA, the shared head assigns a logit si to each option. Since exactly one answer is correct, the authors normalize the logits with softmax and train with cross-entropy:
pi=∑j=1Kexp(sj)exp(si),LCE=−logpywhere y is the index of the correct option. To reduce position bias, a reproducible, answer-independent permutation is applied to each eligible training question.
The training recipe follows a two-stage process. In the first stage, the authors train only the new scorer against fixed pretrained features on 30 percent of the videos, keeping the backbone and new marker embeddings frozen. The grounding and QA objectives are simply the binary cross-entropy and cross-entropy losses. In the second stage, they train the language backbone, marker embeddings, and aligned head on the remaining 70 percent of the videos. The grounding objective incorporates the soft intersection-over-union loss for event-level coverage supervision, while the QA objective retains cross-entropy. Task losses are averaged equally over questions, with the visual encoder and merger remaining frozen throughout.
Experiment
The experiments evaluate VideoJev on video temporal grounding and multiple-choice video QA, covering benchmarks such as Charades-STA, ActivityNet Captions, QVHighlights, LVBench, Video-MME, LongVideoBench, and MLVU. VideoJev improves grounding accuracy and localization precision while reducing inference latency compared with generative baselines, and it also raises QA scores over its instruction-tuned backbones while remaining competitive with reasoning models at much higher speed. Ablations confirm that the gains come from the architectural readout rather than data alone, that joint inference and joint grounding plus QA training are beneficial, and that auxiliary Soft IoU supervision helps grounding and QA. The analysis further shows that scoring many queries jointly scales efficiently and that model confidence tracks accuracy but tends to be overconfident.
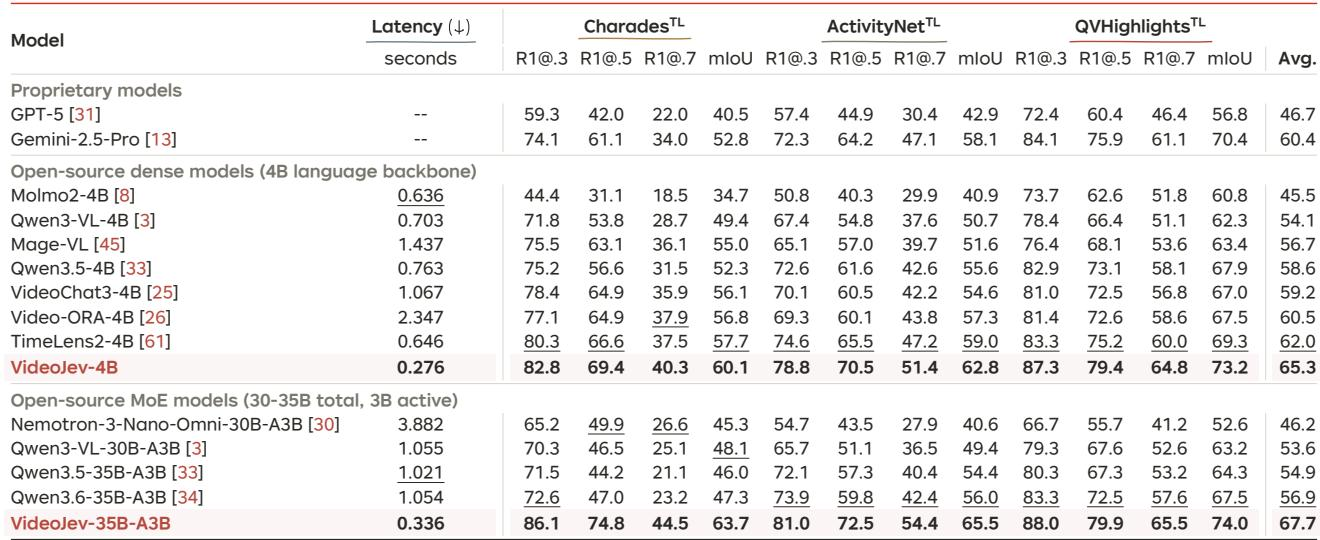
VideoJev models report consistent temporal grounding gains over generative and TimeLens-style baselines, with improvements concentrated at stricter overlap thresholds. The scoring architecture also yields the lowest measured latency among open-source grounding systems and several-fold speedups over generative backbones. Scaling from the 4B model to the 35B-A3B model adds only a small quality gain and a modest latency increase. VideoJev improves mean mIoU and R1 at stricter overlap thresholds relative to its generative backbones and TimeLens-style baselines. The larger VideoJev model adds a small mean mIoU gain while increasing measured latency only modestly. VideoJev models are several times faster than their generative backbones and have the lowest latency among open-source grounding models. Among listed open-source dense baselines, Qwen3-VL-4B outperforms Molmo2-4B across all three grounding datasets.
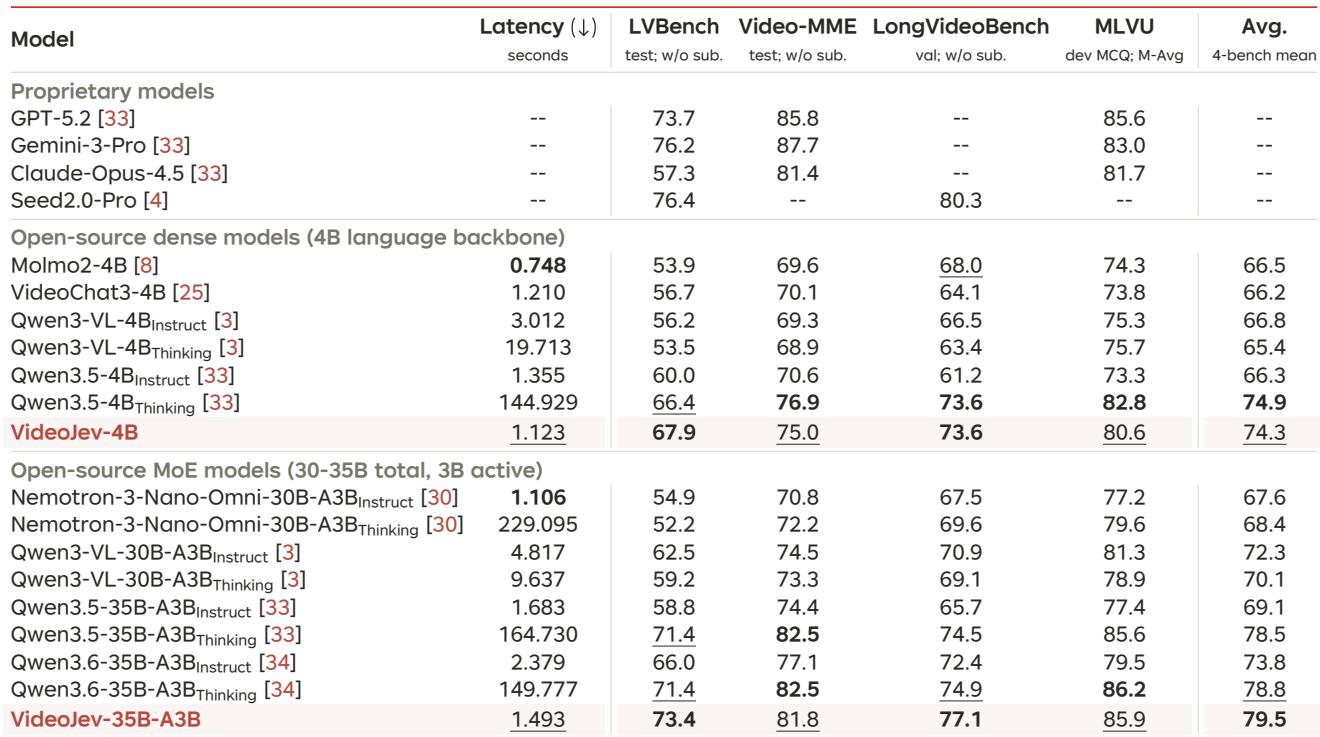
VideoJev models consistently outperform their instruct backbones on multiple-choice video QA, with gains on every evaluated benchmark and particularly strong LVBench results. Direct scoring is competitive with explicit reasoning models, surpassing them on LVBench and LongVideoBench while trailing on Video-MME and MLVU, and provides large latency reductions. Candidate confidence tracks accuracy, suggesting selective trust or escalation is feasible. VideoJev-4B and VideoJev-35B-A3B improve four-benchmark mean scores over their instruct backbones, with improvements on all QA benchmarks. Both VideoJev variants lead their open-source groups on LVBench, and the MoE model achieves the highest group mean. Direct scoring matches or exceeds reasoning counterparts on LVBench and LongVideoBench, while reasoning retains an edge on Video-MME and MLVU. Measured speedups over thinking baselines are roughly two orders of magnitude. Higher option probability is associated with higher accuracy, enabling more reliable high-confidence predictions.
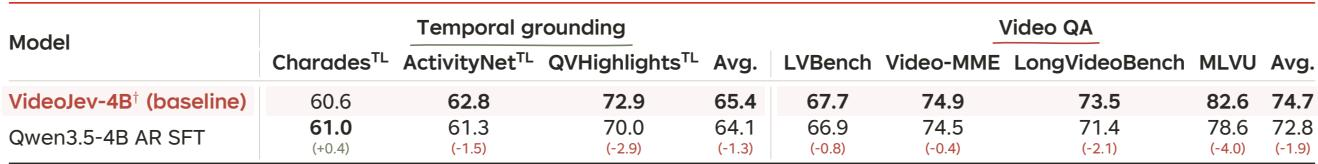
When fine-tuned on identical post-training data, VideoJev-4B attains higher average temporal grounding and video QA scores than an autoregressive Qwen3.5-4B control. The control only leads on Charades temporal grounding, while VideoJev-4B shows the clearest advantages on QVHighlights, LongVideoBench, and MLVU. Matched data and schedules support an architectural benefit from directly supervising structured decisions. VideoJev-4B improves mean grounding and QA performance over the autoregressive control under the same training data and schedule. The autoregressive control trails most on QVHighlights, LongVideoBench, and MLVU, with its only temporal grounding lead on Charades.
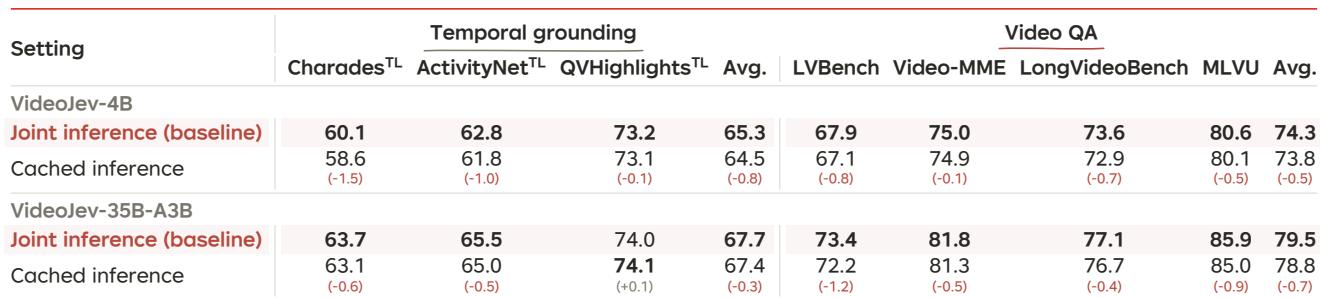
Joint inference generally outperforms cached inference on temporal grounding and video QA across both VideoJev model sizes, improving 13 of 14 model-benchmark comparisons. The only exception is a small cached-inference edge on QVHighlights for the larger model. Efficiency measurements indicate these quality gains come with only a small marginal cost as the number of queries grows. Joint inference improves mean grounding and QA scores over cached inference for both the 4B and 35B-A3B models. The benefit is broad, with 13 of 14 model-benchmark comparisons favoring joint inference and only one slight cached-inference advantage on QVHighlights for the larger model.
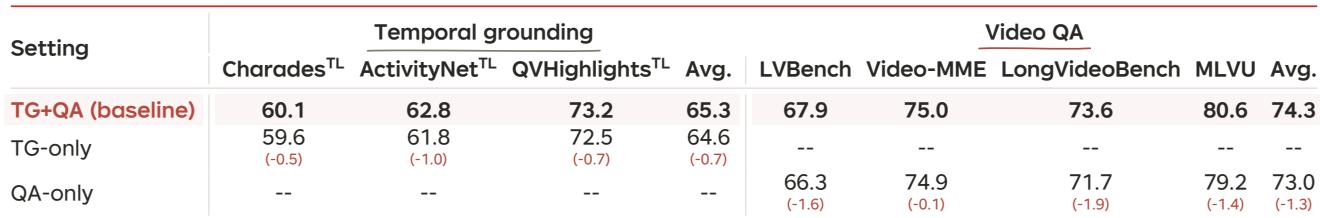
Joint training of VideoJev-4B on temporal grounding and video question answering improves both task families relative to training on either task alone. Temporal grounding performance rises across all three grounding benchmarks, and QA performance rises across all four QA benchmarks. The results indicate that the two tasks reinforce rather than interfere with each other. Joint training outperforms single-task training on every grounding and QA benchmark. Video QA benefits more than temporal grounding, with the largest QA improvement on LongVideoBench.
VideoJev is evaluated on temporal grounding and multiple-choice video question answering against generative, TimeLens-style, and autoregressive baselines. Direct structured scoring yields consistent grounding gains at stricter overlaps with lower latency, improves video QA over instruction backbones with confidence tracking accuracy, and shows architectural benefits over an autoregressive control trained on matched data. Joint training and joint inference further improve both task families, and scaling from the 4B to the 35B-A3B model adds only modest gains.