Command Palette
Search for a command to run...
Agent-Reflex: 언어 에이전트가 성찰적으로 행동하도록 학습시키기
Agent-Reflex: 언어 에이전트가 성찰적으로 행동하도록 학습시키기
초록
대규모 언어 모델은 단일 턴 챗봇에서 장기 지평 추론이 가능한 대화형 에이전트로 진화해 왔다. 실제 배포 환경에서는 MCP 도구 서비스가 노이즈가 포함된 피드백을 반환할 수 있고 사용자가 에이전트를 교정하기 위해 개입할 수 있으나, 기존 방법은 성찰 학습과 실패 복구를 위한 감독을 제한적으로만 제공한다. 이러한 격차를 해소하기 위해, 우리는 에이전트의 능동적 성찰을 장려하기 위한 범용 훈련 프레임워크인 Agent-Reflex를 제안한다. 구체적으로 Agent-Reflex는 세 단계로 구성된다. 첫째, Environment Reflection Skill Discovery(RSD)는 환경 스케일링에 근거된 도구 피드백 교란을 주입하고, 능력이 다양한 LLM 풀을 샘플링하며, 대응되는 성공-실패 쌍을 마이닝하고, 재사용 가능한 성찰 메타 스킬을 요약한다. 이 스킬 라이브러리를 바탕으로, 우리는 Reflective Supervised Fine-Tuning(ReSFT)을 적용하여 각 스킬을 자기 성찰, 스킬 복구, 사용자 중심 교정을 위한 감독 신호로 변환함으로써 상호보완적인 성찰 행동을 강화한다. 마지막으로, 우리는 On-Policy Reflective Policy Optimization(ORPO)을 제안하여 노이즈가 포함된 상호작용 환경에서의 에이전트 강화학습과 성찰 안내 온폴리시 증류를 결합함으로써 능동적 성찰을 더욱 촉진한다. Qwen3-8B를 기반으로 Agent-Reflex는 5개의 장기 지평 도구 사용 벤치마크에서 종합 58.6점, AgentNoiseBench에서 29.1점을 달성하여 강력한 환경 스케일링 및 성찰 기준선을 능가한다. 6개의 까다로운 에이전트 벤치마크 스위트에 대한 실험은 Agent-Reflex의 효과를 입증한다. 추가 분석은 Agent-Reflex가 안정적인 훈련 동역학을 유지하면서 에이전트의 노이즈에 대한 강건성을 향상시켜 확장 가능한 에이전트 훈련을 뒷받침함을 보여준다.
One-sentence Summary
Researchers from the Gaoling School of Artificial Intelligence, Renmin University of China, and the National University of Singapore propose Agent-Reflex, a training framework that combines Environment Reflection Skill Discovery, Reflective Supervised Fine-Tuning, and On-Policy Reflective Policy Optimization to teach proactive reflection under noisy feedback; built on Qwen3-8B, it reaches 58.6 on five long-horizon tool-use benchmarks and 29.1 on AgentNoiseBench.
Key Contributions
- The work identifies two deployment gaps, noisy tool feedback and limited user-guided correction during execution, and introduces Environment Reflection Skill Discovery (RSD), which injects grounded tool-feedback perturbations into environment scaling and mines reusable reflection meta-skills from matched success/failure trajectory pairs sampled across a capability-diverse LLM pool.
- Building on the discovered skill library, the work develops Reflective Supervised Fine-Tuning (ReSFT), which converts each meta-skill into supervision for self-reflection, skill recovery, and user-centric correction to strengthen complementary reflective behaviors.
- The work further proposes On-Policy Reflective Policy Optimization (ORPO), which combines agentic reinforcement learning under noisy interactions with reflection-guided on-policy distillation, and reports that Agent-Reflex with Qwen3-8B reaches 58.6 overall on five long-horizon tool-use benchmarks and 29.1 on AgentNoiseBench, outperforming environment-scaling and reflection baselines.
Introduction
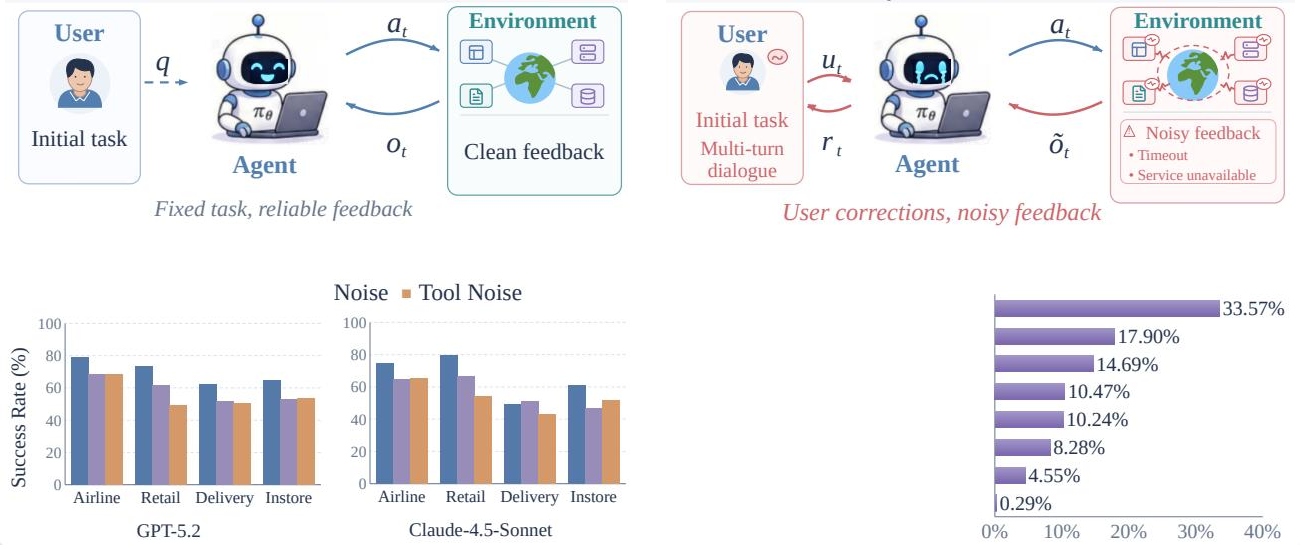
Recent advances in large language models have pushed agents toward long-horizon tool use, but scaling these agents requires realistic, stateful environments where they can learn transferable interaction experience. Prior environment-generation work either treats LLMs as implicit world models, which can produce hallucinated feedback, or builds executable tool environments that are still usually stable and noise-free. Existing training setups also lack realistic noisy tool returns and diverse user-guided corrections, and many reflection methods are trained in simplified or stateless settings. The authors address this by introducing Agent-Reflex, a training framework that mines reflection meta-skills from execution failures in noisy executable environments and internalizes them through reflective supervised fine-tuning and on-policy reflective policy optimization.
Dataset
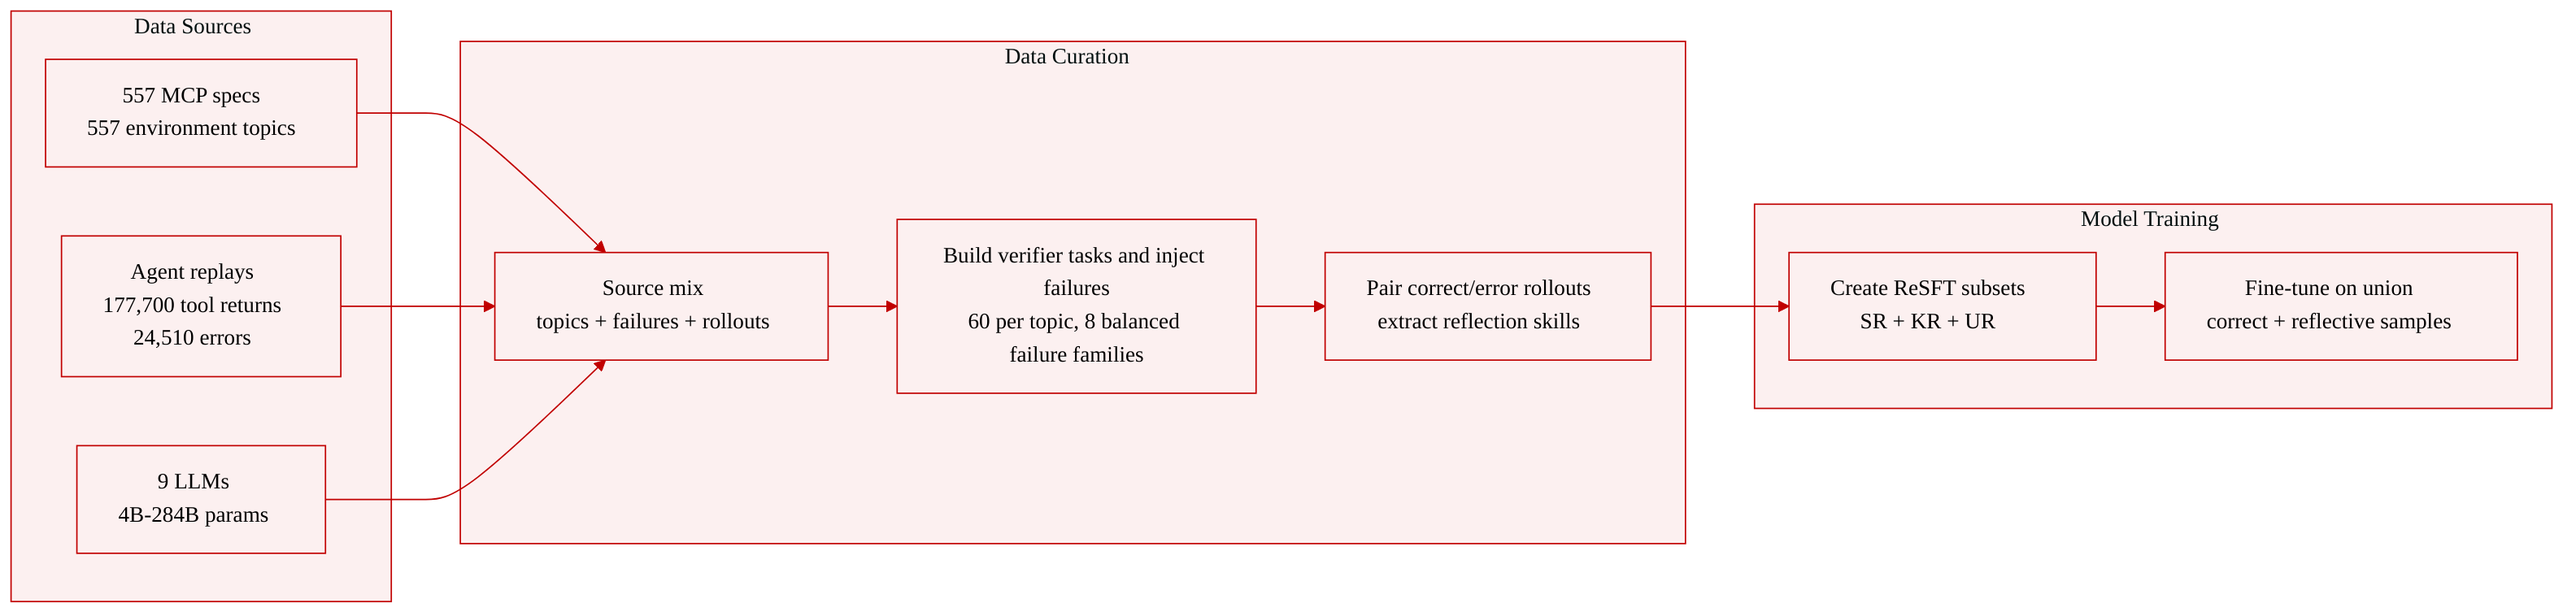
Dataset Description: Agent-Reflex Environment and Reflective Supervision Data
The authors build a verifier-backed environment ecosystem and then derive reflective supervision samples from it for supervised fine-tuning.
-
Main sources
- 557 high-usage MCP server specifications from Smithery, each defining an environment topic.
- 177,700 tool returns collected by replaying agents across nine public agentic benchmarks; 24,510 of these are error returns.
- A capability-diverse pool of nine LLMs spanning five model families, from 4B to 284B parameters.
-
Environment dataset construction
- For each topic, a research agent uses search, browser, coding, and operating-system tools to build and iteratively enrich a topic-grounded database.
- A coding agent generates candidate tools and unit tests from the topic and its database.
- Tools are kept only if they compile, pass all tests, satisfy state-transition constraints, and support executable task verification.
- Each environment therefore contains a database, a validated tool set, and verifiers.
- The resulting ecosystem has 60 verifier-backed tasks per topic across the 557 topics.
-
Failure mining and injection
- The observed error returns are grouped by surface form into eight actionable failure families.
- Failures are injected into tool returns probabilistically, balanced across the eight families so rare failures receive enough training instances.
- Clean and perturbed tasks are retained only when they admit verifiable solutions and verifiable recovery, respectively.
-
Trajectory and meta-skill data
- Each model in the nine-model pool interacts with every task in the noisy ecosystem under the same sampling protocol.
- An analyzer model and the environment verifier jointly label each rollout as correct or erroneous.
- Error data includes the diagnosed error rationale, the first erroneous turn, and the environment-state snapshot.
- Correct and erroneous trajectories from the same task are paired.
- Pair filtering limits the number of pairs contributed by each task and requires each environment to draw pairs from at least five distinct tasks.
- Paired samples use the schema
(q, τ+, τ−, e, t*, state snapshot). - The analyzer extracts recurring failure patterns and converts them into executable reflection skills.
- Each environment stores its description, tools, observed bad patterns, and extracted reflection skills.
-
ReSFT data construction and use
- The authors construct three reflective supervision subsets from the paired trajectory data:
- Self-Reflection Sampling (SR): restore to the first error state, append the matched skill, sample a continuation from the frozen behavior policy, and keep only verifier-success continuations. The privileged skill is removed from the stored input.
- Skill Recovery Sampling (KR): reset to the initial state, restart from the task plus matched skill, and keep only verifier-success continuations. The privileged skill is removed before storage.
- User-Centric Reflection Sampling (UR): a user simulator converts the matched skill into a natural-language correction. The correction is inserted after the error and remains in the stored input, while the privileged skill is removed.
- The final ReSFT dataset is the union of correct trajectories generated by the target behavior policy and the SR, KR, and UR subsets.
- Training uses next-token supervised fine-tuning over this union.
- The provided text does not specify exact trajectory subset sizes, training split, or mixture ratios for the ReSFT subsets.
- The authors construct three reflective supervision subsets from the paired trajectory data:
Method
The authors propose Agent-Reflex, a framework designed to convert environment failures into a robust reflection capability for agentic systems. The methodology comprises three sequential stages: Environment Reflection Skill Discovery, Reflective Supervised Fine-Tuning, and On-Policy Reflective Policy Optimization.
As shown in the figure below:
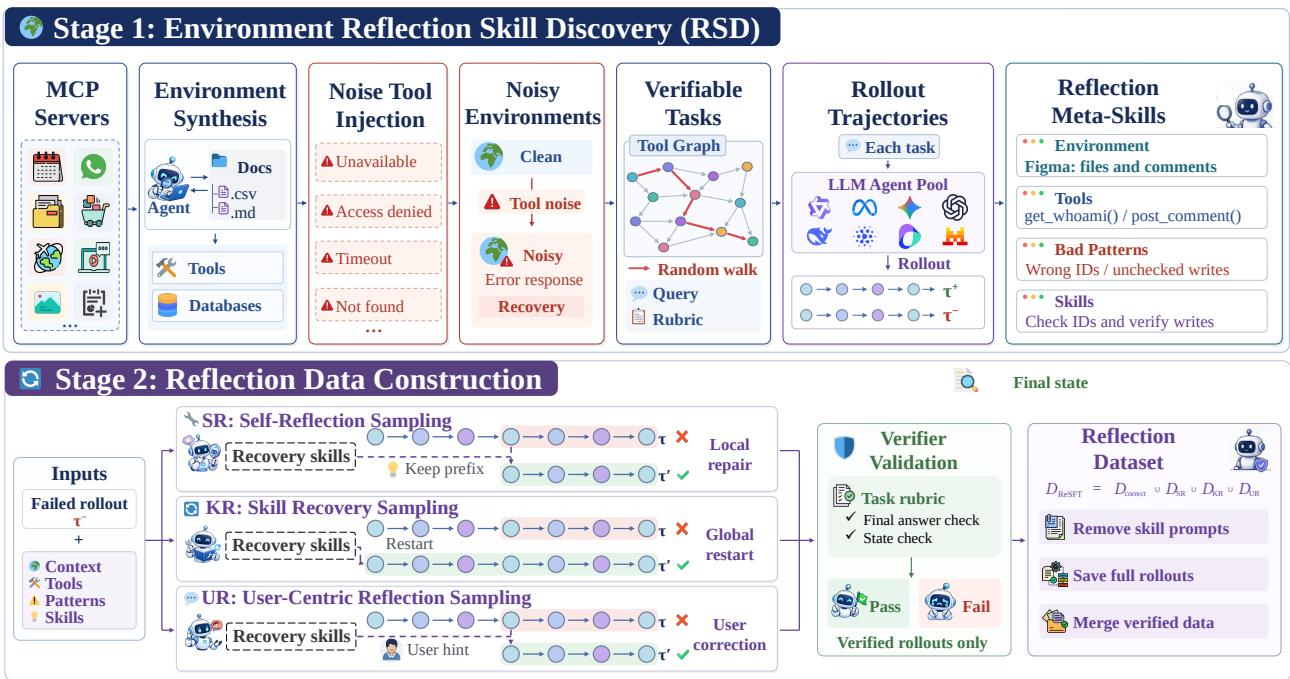
The first stage, Environment Reflection Skill Discovery, focuses on building failure-aware executable environments and mining verifier-matched trajectory pairs into an offline skill library. To construct realistic environments with tool failures, the authors select high-usage MCP server specifications and iteratively enrich topic-grounded databases. A coding agent then generates candidate tools and unit tests, retaining only those that compile, pass tests, and support executable task verification. To emulate unstable real-world deployments, the system injects perturbations grounded in observed failures. By replaying agents across public agentic benchmarks, the authors collect tool returns and group them into actionable failure families. These failures are injected probabilistically into tool returns to emulate real deployment:
ot+1train={J(ot+1),ot+1,bt+1inj=1,bt+1inj=0,bt+1inj∼Bernoulli(pinj)where the renderer replaces the true return with a compatible failure, balanced across the identified failure families.
Following environment construction, the authors perform Reflection Meta-Skill Extraction. To avoid concentrating trajectories around model-specific reasoning tendencies, they sample trajectories from a capability-diverse LLM pool interacting with the noisy ecosystem. An analyzer model and the environment verifier jointly label each rollout to identify correct and erroneous trajectories. By pairing successful and failed trajectories from the same task, the analyzer identifies recurring failure patterns and converts them into executable recovery rules. This process yields an offline library of reflection meta-skills, where each skill maps an agent's bad pattern to a corrective action, enabling reuse across tasks within the same environment.
The second stage, Reflective Supervised Fine-Tuning, converts these explicit reflection skills into policy behavior. Starting from a frozen behavior policy, the authors construct three complementary forms of reflective supervision. For Self-Reflection Sampling, the environment is restored to the state snapshot taken before the first erroneous turn. The corrective skill is appended to the deployment-visible history to teach failure awareness and local repair. The skill is then removed from the stored input, forcing the policy to learn recovery from its own error state. For Skill Recovery Sampling, which addresses failures originating from incorrect initial plans, the environment is reset to its initial state and restarted with the matched skill to teach global recovery. Finally, User-Centric Reflection Sampling teaches the agent to respond to user interventions. A user simulator converts the matched skill into a natural-language correction, which is inserted after the erroneous turn. Because the user message is deployment-visible, it remains in the stored input while the privileged skill is removed. All generated continuations are strictly filtered by the environment verifier, and the verified datasets are merged with correct trajectories to form the fine-tuning dataset, optimized via the standard negative log-likelihood loss:
LReSFT=−(x,y)∈DReSFT∑logπθ(y∣x)The third stage, On-Policy Reflective Policy Optimization, further elicits proactive reflection by combining outcome-based agentic reinforcement learning with token-level, reflection-guided on-policy distillation. In the Noisy Agentic Reinforcement Learning component, the policy generates trajectories in a mixed group of noisy and clean environments. The environment verifier assigns returns, which are normalized within the mixed group to keep genuine failures inside the on-policy distribution. A clipped Agent RL objective propagates this outcome supervision. To provide dense supervision for failure-causing decisions, the Reflection On-Policy Distillation component conditions on the reflection meta-skills of the corresponding environment. The current policy acts as a teacher, re-scoring the already sampled action tokens under a skill-augmented history. The detached skill-induced shift and its confidence weight are computed to optimize the distillation objective. This soft weighting emphasizes tokens with a positive skill-induced shift. The final optimization objective jointly optimizes the outcome-based Agent RL and reflection distillation losses:
LORPO=LRL+λopdLOPDThis combines trajectory-level outcome learning with token-level reflection supervision to sharpen the proactive reflection of the policy.
Experiment
These experiments evaluate Agent-Reflex on long-horizon tool-use benchmarks including BFCL-v4, ACEBench, ToolSandbox, τ²-Bench, and VitaBench, as well as noisy interaction settings built on τ²-Bench and VitaBench with user and tool noise, and they report the distribution of tool errors such as authentication failures, timeouts, resource errors, and rate limits. All trained methods share the Qwen3-8B backbone, with baselines spanning reflection, environment-scaling, and trajectory-level RL approaches. Agent-Reflex achieves the best overall long-horizon and noise-robustness performance, with gains attributed to internalized reflective supervision, reusable recovery skills, and complementary environment scaling. ORPO shows stable advantages over standard RL algorithms, and ablations confirm that every component contributes, with failure awareness and local repair causing the largest drops and token-level reflection signals rather than skill exposure driving the gains.
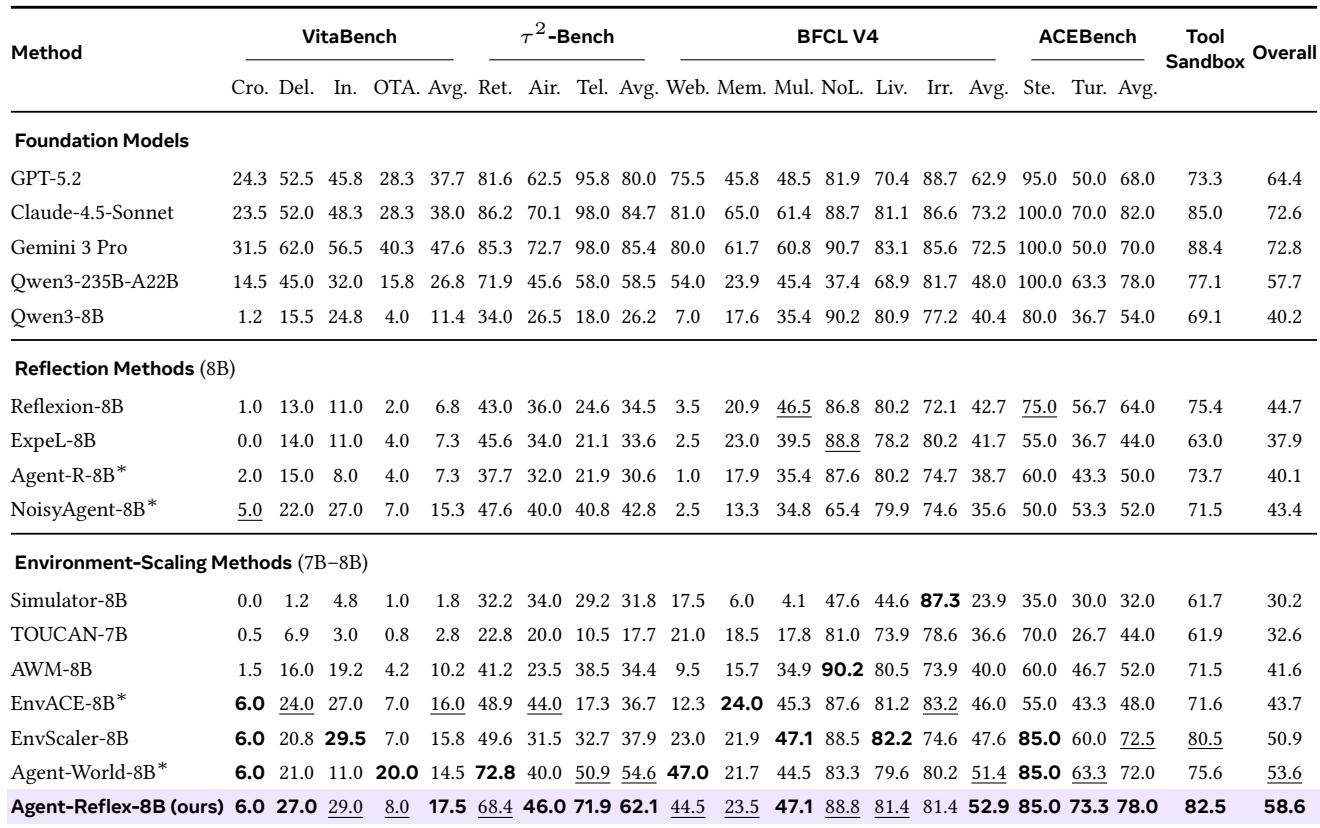
Across five long-horizon tool-use benchmarks, Agent-Reflex achieves the highest overall score among strong 7B-8B baselines. It consistently outperforms inference-time reflection, trajectory recovery, and environment-scaling methods, with particularly clear gains on VitaBench, ACEBench, and ToolSandbox. The results suggest that training on verified recovery behavior and reusable environment-level meta-skills improves multi-turn tool use beyond inference-time guidance or broader environment coverage. Agent-Reflex has the best overall performance among 7B-8B methods across the five benchmarks. It surpasses inference-time reflection baselines on VitaBench, ACEBench, and ToolSandbox, and outperforms trajectory-level recovery baselines on four benchmarks including BFCL V4. It improves over environment-scaling baselines on all five benchmark averages, with ACEBench gains driven mainly by better multi-turn interaction rather than step-level accuracy.
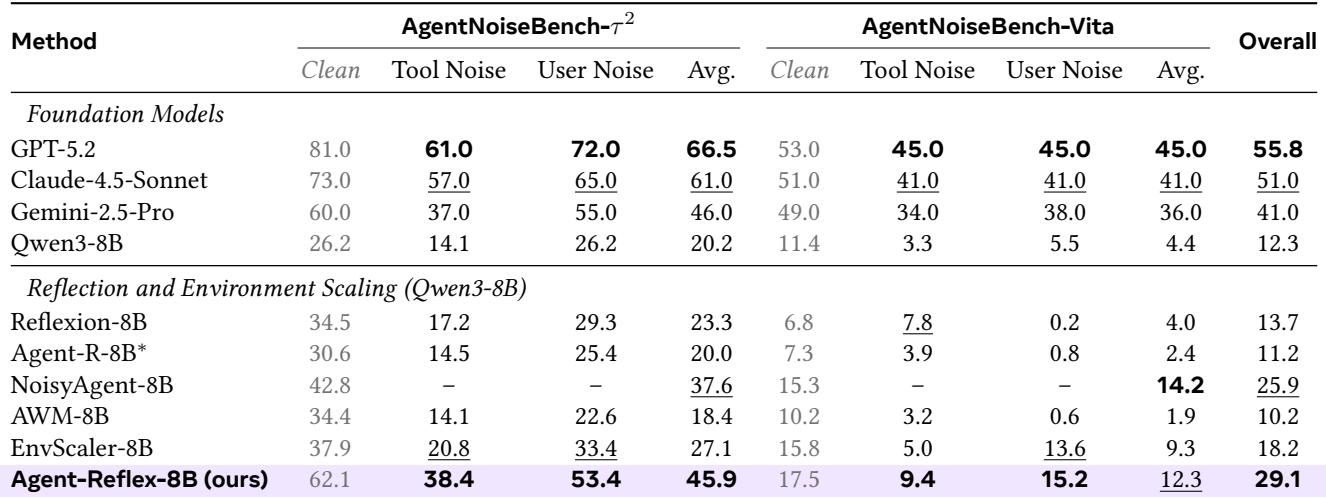
Foundation models show marked performance drops on AgentNoiseBench under both tool and user noise. Agent-Reflex achieves the strongest overall noise-robustness result among the compared 8B methods, outperforming NoisyAgent-8B and other baselines. This indicates its reflective supervision generalizes to unseen noisy interaction conditions. Foundation models degrade substantially when tool feedback or user interactions are perturbed. Agent-Reflex leads the compared 8B methods on overall noise robustness, ahead of NoisyAgent-8B and other strong baselines. The advantage appears across tool-noise and user-noise evaluations, indicating broader robustness to interaction noise.
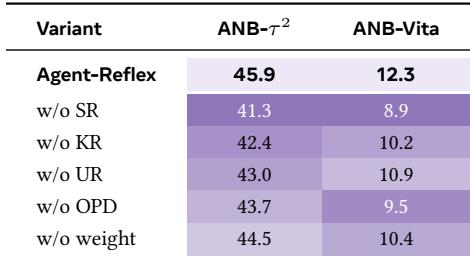
An ablation of Agent-Reflex on two AgentNoiseBench settings shows that removing any component lowers performance, indicating the modules are complementary. Among supervision components, removing SR causes the largest decline, followed by KR and UR. Keeping the skill library is not sufficient, since removing OPD or its confidence weighting still reduces scores, pointing to token-level reflection as the key source of gains. Removing any component degrades both settings, with SR removal producing the largest drop and supervision ordering SR, KR, UR. With the skill library retained, removing OPD or its confidence weighting still lowers scores, so token-level reflection rather than skill exposure drives the gains.
Agent-Reflex is evaluated across five long-horizon tool-use benchmarks and a noisy interaction benchmark, where it outperforms comparable 7B-8B baselines including inference-time reflection, trajectory recovery, environment scaling, and NoisyAgent-8B. The results indicate that training on verified recovery behavior and reusable environment-level meta-skills improves multi-turn tool use and robustness to tool and user noise. Ablations show that all components contribute, with token-level reflection supervision providing the largest gains while skill library exposure alone is insufficient.