Command Palette
Search for a command to run...
다중 스트림 어텐션 잔차
다중 스트림 어텐션 잔차
Xiaohan Qin Xiangdong Zhang Tuo Dai Sunan Zou Huaijin Wu Yebin Yang Zhuo Xia Lin Yao Yuliang Liu Junchi Yan
초록
어텐션 잔차(Attention Residuals, AttnRes)는 네트워크 깊이에 걸친 콘텐츠 의존적 검색을 가능하게 하며, 이는 깊이 축을 따라 수행되는 단일 스트림 소프트맥스 어텐션으로 볼 수 있다. 시퀀스 축에서의 멀티헤드 어텐션 성공에 영감을 받아, 우리는 AttnRes의 확장인 다중 스트림 어텐션 잔차(Multi-Stream Attention Residuals, MSAR)를 제안한다. MSAR은 이 메커니즘을 멀티헤드 깊이 어텐션으로 일반화하여 최소한의 추가 오버헤드로 상당한 성능 향상을 가져온다. MSAR은 다중 스케일 인과 합성곱을 통해 시퀀스 컨텍스트로부터 스트림 다양성을 이끌어 내며, 서로 다른 헤드가 은닉 표현의 무결성을 보존하면서도 서로 다른 컨텍스트 관점으로 과거 표현을 검색할 수 있게 한다. 검색된 스트림들은 경량의 적응형 혼합을 통해 결합되어 단일 스트림 계층 입력을 생성한다. MSAR은 단일 스트림 소스를 유지하고 필요할 때만 확장함으로써, 지속적인 다중 스트림 저장이나 통신 없이도 다중 스트림 연산을 지원한다. 18B 및 28B MoE 규모의 12개 다운스트림 벤치마크 전반에서 MSAR은 표준 잔차 연결, 다양체 제약 하이퍼커넥션(manifold-constrained Hyper-Connections, mHC), AttnRes를 포함한 기존 잔차 변형들을 일관되게 능가한다. 스케일링 법칙 실험에서는 표준 잔차 기준선 대비 1.58배의 동일 손실(iso-loss) 계산 속도 향상을 보였으며, AttnRes는 1.35배, mHC는 1.30배의 향상을 보였다. 이러한 결과는 MSAR이 대규모 사전학습을 위한 유망한 잔차 구조임을 보여준다.
One-sentence Summary
Researchers from Shanghai Jiao Tong University, Peking University, and collaborating institutions introduce Multi-Stream Attention Residuals (MSAR), an extension of AttnRes that employs multi-head depth attention with multi-scale causal convolutions to generate context-driven stream diversity and lightweight adaptive mixing, consistently outperforming residual variants, Hyper-Connections, and AttnRes across all 12 downstream benchmarks at 18B and 28B MoE scales, and achieving a 1.58× iso-loss compute speedup over the standard residual baseline.
Key Contributions
- Introduces Multi-Stream Attention Residuals (MSAR), an extension of AttnRes that generalizes depth-wise softmax attention to multi-head retrieval, with each head drawing diversity from sequence context via multi-scale causal convolutions and retrieving historical hidden states independently over depth.
- Keeps only single-stream persistent storage and expands retrieved streams on demand with adaptive scalar mixing, matching AttnRes’s storage and pipeline communication costs while supporting cross-stage caching and two-phase inference with minimal training FLOPs and parameter overhead.
- Consistently outperforms standard residual connections, manifold-constrained Hyper-Connections (mHC), and AttnRes across all 12 downstream benchmarks at 18B and 28B MoE scales, with scaling-law experiments yielding an iso-loss compute speedup of 1.58× over the standard residual baseline, compared with 1.35× for AttnRes and 1.30× for mHC.
Introduction
Scaling depth is a primary way to improve Transformer-based LLMs, but in modern PreNorm architectures, adding layers often yields diminishing returns. The residual stream aggregates computations along a single hidden-state trajectory with fixed additive updates, so as the stack deepens, features from early layers can become diluted and hard for later layers to retrieve. This depth-wise information dilution limits the effectiveness of additional layers, making depth scaling less efficient than its representational capacity suggests.
Prior work has tried to address this by redesigning residual connections. Hyper-Connections (HC) and its variant mHC expand the residual stream into multiple parallel streams with learned mixing, while Attention Residuals (AttnRes) replaces fixed accumulation with learned softmax retrieval over earlier representations. However, these approaches face limitations. AttnRes attempts multi-head depth aggregation by channel-splitting the hidden state, but this degrades performance because the retrieved value is the hidden state itself and must be treated as a coherent whole. Another route, deriving candidate streams from a single layer output via HC-style write-back, keeps candidates full-dimensional but results in scalar reweightings of the same vector; normalization removes magnitude differences, yielding nearly identical keys and limiting diversity across heads.
The authors propose Multi-Stream Attention Residuals (MSAR), a low-cost extension of AttnRes. MSAR draws diversity from the sequence axis by applying a small set of multi-scale causal depthwise convolutions to the layer output, producing full-dimensional streams with different local-context receptive fields. Each stream performs its own softmax retrieval over depth, and the retrieved states are fused with a lightweight mixer. This turns residual retrieval into multi-head depth attention, allowing different heads to select different depth histories through distinct sequence-context views while preserving representation integrity.
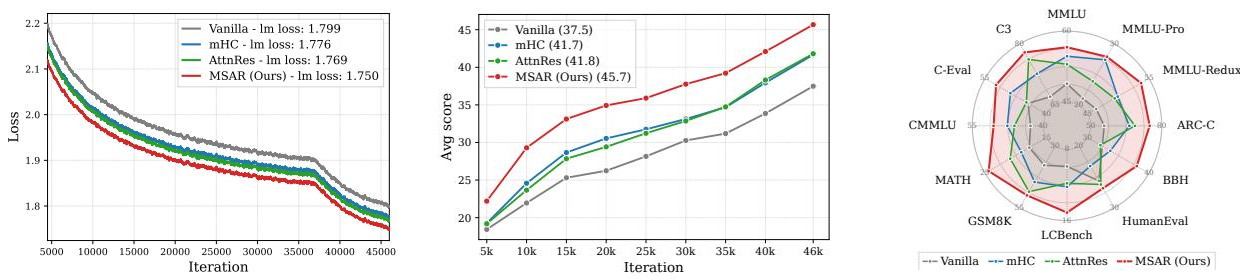
MSAR is system-efficient: in a 28B MoE setting, it adds only 0.5% training FLOPs and 0.3% activated parameters. It stores only single-stream summaries and expands streams on demand via a fused kernel, reducing pipeline communication and prefill activation storage to match AttnRes while supporting cross-stage caching and two-phase computation. Empirically, MSAR improves training loss and downstream performance at 18B and 28B scale, achieving a 1.58x iso-loss compute speedup over the vanilla baseline, compared with 1.35x for AttnRes and 1.30x for mHC.
Method
The authors frame residual connections as a depth mixing mechanism, where standard residual accumulation compresses all previous updates into a single running state via hl+1=hl+fl(hl). To overcome the limitations of this single-state constraint, they introduce Multi-Stream Attention Residuals (MSAR), which expands the residual path into multiple persistent streams to carry distinct depth histories.
In MSAR, the authors first perform Multi-Stream Source Expansion. Instead of using computationally expensive dense projections, they leverage lightweight causal depthwise 1D convolutions to expand each residual source into m streams. These convolutions apply different kernel sizes κr to capture varying local receptive fields, providing distinct contextual views of each source without exposing future information. Next, in the Per-Stream Depth Attention phase, each expanded stream acts as an independent depth-attention head. The model computes attention weights using layer-specific learned pseudo-queries ql(r) and RMS-normalized exponential kernels, aggregating the corresponding source representations across depth. Finally, for Stream Fusion, the retrieved streams are combined into a single input for the target layer using a lightweight mixer that generates input-dependent scalar weights via a sigmoid-activated projection.
To mitigate the memory and pipeline communication overhead associated with retaining every layer's hidden state, the authors propose Block MSAR. This approach partitions the residual branches into contiguous blocks and replaces individual layer outputs with block-level summaries as the depth-attention sources. Within each block, outputs accumulate into a single stream. For a target layer, the model retrieves from the embedding, completed block summaries, and the current partial sum of the active block.
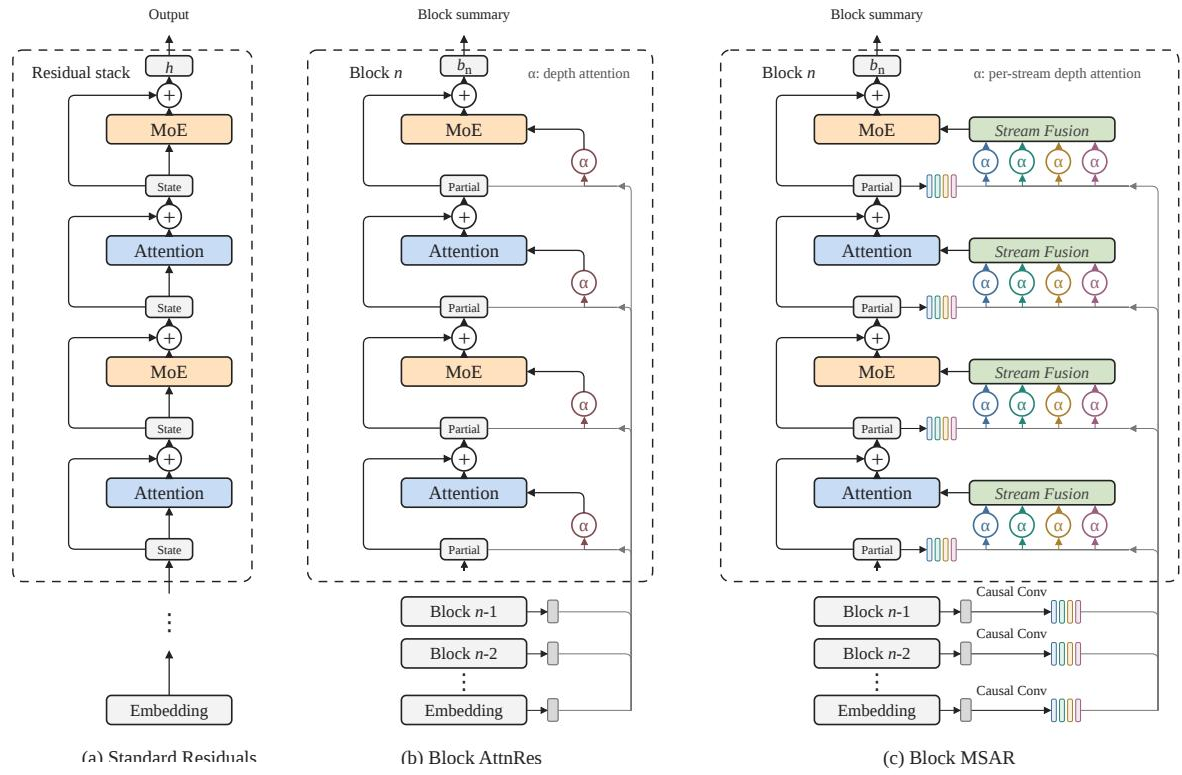
As illustrated in the framework diagram, Block MSAR contrasts with standard residuals and Block AttnRes by incorporating causal convolutions to expand block summaries into multiple streams, followed by per-stream depth attention and stream fusion before feeding the result into the Attention and MoE layers.
The authors also detail an efficiency analysis to ensure the method scales effectively. For Single-Stream Storage and Communication, MSAR only retains and communicates single-stream block summaries, expanding them on demand via causal convolutions. This reduces persistent source storage and pipeline communication payloads. Furthermore, they employ a Two-Phase Computation strategy. In the first phase, queries for all target layers in a block are batched against completed sources to compute retrieval results and softmax statistics, sharing source reads. In the second phase, each layer computes the contribution of its current partial and merges it with the precomputed result using online softmax. Finally, Fused Stream Expansion combines the causal convolutional expansion and per-stream attention into a single kernel. This avoids writing intermediate expanded streams to memory, significantly reducing memory traffic during the forward pass.
Experiment
Experiments were conducted on MoE Transformers at 18B, 28B, and 10B scales, with downstream evaluation across 12 benchmarks covering general, code/math, and Chinese tasks. MSAR outperformed all baselines (Vanilla, mHC, AttnRes) on every benchmark at both main model scales, adding only 0.3% activated parameters and 0.5% FLOPs in the 28B setting. Scaling law analysis showed MSAR consistently achieved lower training loss across four model scales, with an average iso-loss compute speedup of 1.58x over Vanilla. Ablations on a 10B model confirmed that both contextual source expansion and adaptive stream fusion contribute to MSAR's gains, that its advantage is not from simply combining prior residual designs, and that default hyperparameters (four streams, eight residual blocks per group) capture most of the benefit with diminishing returns beyond these settings.
MSAR consistently outperforms Vanilla, mHC, and AttnRes on all 12 evaluated benchmarks at both 18B and 28B MoE scales, with the largest average score gains over the Vanilla baseline. The method also achieves a substantially lower pre-training loss than prior residual approaches, and its design choices such as contextual source expansion and adaptive stream fusion contribute to these gains. MSAR achieves higher average scores than all baselines at both 18B and 28B scales, with the largest improvements over Vanilla. Representative gains on individual benchmarks include large increases on ARC-C and BBH compared to AttnRes at 18B scale. MSAR yields a lower pre-training loss than mHC, AttnRes, and a direct combination of those two approaches. Two streams already capture most of the benefit, with four streams providing a good default and eight giving only marginal further improvement. Retaining roughly eight blocks recovers most of the benefit of full depth access, with diminishing returns from finer partitioning.
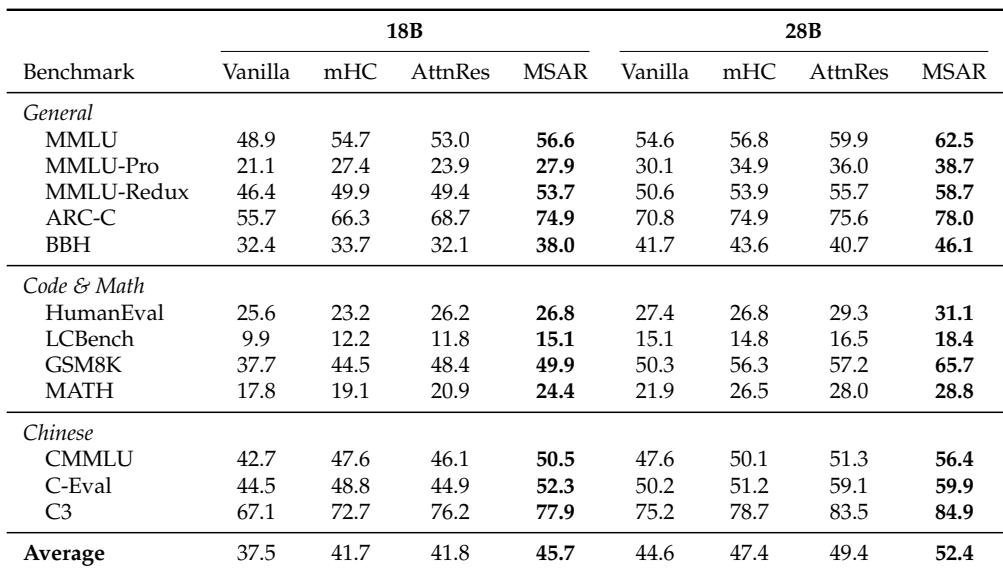
Ablations on a 10B MoE model show MSAR achieves the lowest Pile loss among residual designs, outperforming both prior methods and a direct hybrid of them. The gains come from contextual source expansion and adaptive stream fusion, while the number of streams has diminishing returns beyond four. MSAR reduces Pile loss to 1.847, below mHC (1.871), AttnRes (1.867), and a direct AttnRes+mHC hybrid (1.861). Removing convolutional source expansion raises loss from 1.847 to 1.862, showing that source diversity matters beyond query diversity. Replacing adaptive fusion with mean aggregation only slightly degrades loss to 1.851, indicating uniform averaging retains most of the benefit. Two streams already capture most of the improvement over Vanilla (1.850); increasing to four streams gives 1.847, while eight streams add only marginal gains. Using approximately eight residual blocks per group yields near-optimal performance (1.845), close to full depth access (1.843).
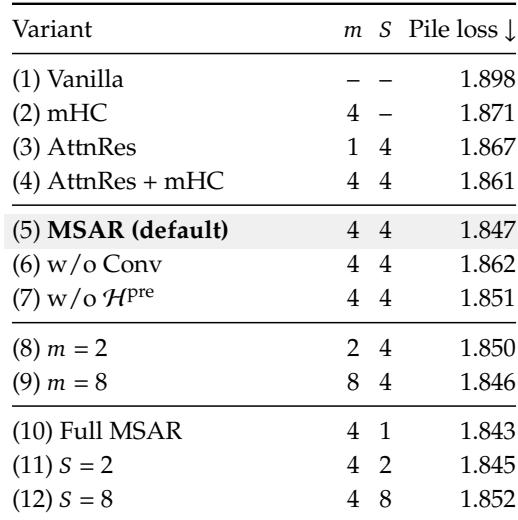
MSAR outperforms Vanilla, mHC, and AttnRes across all 12 evaluated benchmarks at both 18B and 28B MoE scales, achieving substantially lower pre-training loss and the largest average gains over the Vanilla baseline. Design choices such as contextual source expansion and adaptive stream fusion drive these improvements. Ablations on a 10B MoE model confirm MSAR achieves the lowest Pile loss among residual designs, where two streams capture most of the benefit, four provide a strong default, and eight yield only marginal gains. Retaining about eight residual blocks per group recovers most of the benefit of full depth access, with diminishing returns from finer partitioning.