Command Palette
Search for a command to run...
S-Space: 멀티모달 언어 모델의 공간 작업공간 탐구
S-Space: 멀티모달 언어 모델의 공간 작업공간 탐구
초록
멀티모달 언어 모델(MLLM)은 유망한 공간 추론 능력을 보이지만, 이를 뒷받침하는 내부 기제는 여전히 잘 알려져 있지 않다. 우리는 객체 토큰 표현이 수평, 수직, 거리 축을 따라 연속적인 좌표를 인코딩하는 선형 표현 부분공간인 S-Space를 발견한다. 우리는 공간 응답 점수를 객체 토큰 활성화에 대해 미분하여 이 축들을 식별하지만, S-Space는 특정 데이터나 프롬프트에 의해 유도된 것이 아니라 본질적이며 비공간적 질문에서도 판독 가능하다. 우리는 S-Space가 MLLM의 내부 공간 작업공간으로 기능함을 보인다. 지각은 객체 위치를 그 안에 인코딩하여 정확한 공간 판단을 지원하도록 직접 판독할 수 있는 공간 표상을 형성한다. 내부 추론은 시점 변화를 위해 이를 변환한다. 언어적 응답은 이를 선택적으로 접근하며, 공간 판단은 변경하되 비공간적 응답은 대체로 보존하는 인과적 개입이 이를 뒷받침한다. 사례 연구는 S-Space가 보이지 않는 개체와 관찰자에게 위치를 할당하고, 물리적 방향을 추상적 언어 의미와 연결함을 추가로 보여주며, 이는 대규모 언어 학습의 능력과 한계를 모두 시사한다. 마지막으로 우리는 S-Space를 공간 추론 실패의 진단 도구로 사용한다. 방향어 판독 결과는 절대 방위 기준틀과 이미지 상대 기준틀 사이의 체계적 결합을 드러낸다. 더 중요하게, 지각-계산 분해는 핵심 병목을 드러낸다. MLLM은 유능한 공간 표상을 형성할 수 있지만, 시점 변화 전반에서 신뢰성 있게 추론하는 데 필요한 공간 변환에는 부족하다.
One-sentence Summary
Researchers from MirroS, Tsinghua University, and Peking University uncover S-Space, an intrinsic linear representation subspace in multimodal language models where object-token activations encode continuous horizontal, vertical, and distance coordinates, and they demonstrate through activation gradients that this subspace serves as an internal spatial workspace and diagnostic tool, revealing that the models can form capable spatial representations but struggle with viewpoint transformations.
Key Contributions
- The paper identifies and characterizes S-Space, a three-dimensional linear subspace of intermediate multimodal language model representations that acts as an internal spatial workspace, explaining how spatial information is encoded, updated, and causally used.
- A gradient-based readout method is introduced to recover fixed left-right, above-below, and close-far axes, enabling accurate continuous coordinate readouts that generalize across datasets, tasks, and prompts and remain readable under non-spatial questions.
- S-Space is established as a diagnostic tool for spatial reasoning failures: causal interventions alter spatial judgments while largely preserving non-spatial responses, and perception-computation decomposition reveals that models can form capable spatial representations but struggle with the spatial transformations required for reliable viewpoint reasoning.
Introduction
Multimodal large language models are increasingly used for spatial intelligence tasks such as reconstruction, planning, navigation, and manipulation, but robust spatial reasoning remains a major weakness. End-to-end accuracy alone offers little insight into where these failures arise, and prior work on spatial encodings and representational biases has not provided a unified explanation of how spatial information is internally encoded, transformed, and used. The authors uncover S-Space, a three-dimensional linear subspace of intermediate representations that functions as an internal spatial workspace, with fixed axes for left-right, above-below, and close-far directions. They show that this subspace supports generalizable coordinate readouts, causally shapes spatial judgments, and can serve as a diagnostic tool by separating spatial perception from downstream reasoning failures.
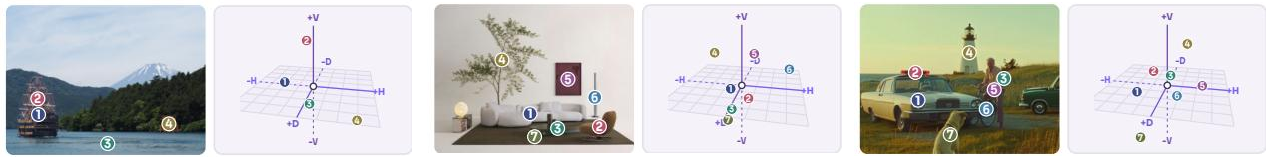
Method
S-Space: Formulation, Identification, and Readout
The authors introduce S-Space, a three-dimensional linear subspace of intermediate representations in multimodal large language models (MLLMs) in which object locations are linearly encoded and can be directly read out. The approach has three stages: formulating the subspace, identifying its axes, and reading out spatial coordinates through projection.
S-Space Formulation
Large language models are widely hypothesized to represent concepts linearly in their internal representations. The authors extend this idea to spatial reasoning by hypothesizing that an object’s spatial coordinates, defined in a viewer-centered or egocentric reference frame, are linearly encoded in the hidden representation of its object-name token.
For a given model and layer ℓ, S-Space is defined as a three-dimensional linear subspace of hidden representations
hℓ,t∈Rdmodel.S-Space is specific to the model and layer, but shared across all token positions t within that layer. The authors search for S-Space in the model’s middle layers because early layers remain relatively anchored to input representations, while later layers become increasingly aligned with next-token prediction for verbal response generation. For simplicity, the layer index is omitted in subsequent notation.
Identifying S-Space
The authors identify three S-Space directions corresponding to the horizontal, vertical, and distance axes by differentiating the model’s responses to relative spatial questions with respect to object-token activations.
Each relative spatial question example consists of an image and a prompt comparing a query object with a reference object along one axis g∈{x,y,z}, for example, “Is the apple to the left or right of the cup?” Let q and r denote the respective token positions of the query and reference object names. The answer contrast for each axis is defined as the corresponding logit difference:
sp,x=logit(right)−logit(left), sp,y=logit(above)−logit(below), sp,z=logit(close)−logit(far).The gradient ∇htsp,g indicates the direction along which perturbing the object representation would most increase the corresponding answer contrast. The authors then form a role-antisymmetric gradient difference and average it across prompt templates, original and swapped object orders, and examples:
ap,g=2∇hqsp,g−∇hrsp,g,vg=unit(Ep[ap,g]).The resulting unit vectors define the three S-Space directions:
S=span{vx,vy,vz}.The role-antisymmetric difference is motivated by the fact that relative spatial judgments treat the query and reference oppositely. A change that makes the query more to the right should favor the answer “right,” while the same change applied to the reference should favor “left.” Subtracting the reference gradient from the query gradient therefore reinforces oppositely acting spatial signals. Averaging across prompt templates, object orders, and examples further suppresses effects from object identity, prompt phrasing, token roles, and scene context that are not consistently associated with the queried spatial relation.
Reading Out S-Space
Once the three axes are identified, reading out S-Space requires only a forward pass. The readout is not restricted to the spatial question-answering prompts used for identification; the same fixed directions can be applied to object-token representations elicited by other prompts and tasks.
The authors stack the three direction vectors into a matrix V and project each object token t to obtain its coordinate in S-Space:
V=[vx,vy,vz]∈Rdmodel×3,ct=V⊤ht∈R3.For relative spatial judgments, the query and reference coordinates are compared along the queried axis:
mg=vg⊤(hq−hr)=cq,g−cr,g.The sign of the margin mg directly selects the predicted endpoint. A positive value indicates right, above, or close, while a negative value indicates left, below, or far.
Experiment
Using relative spatial questions constructed from COCO and readouts evaluated on CV-Bench, EmbSpatial, and Spatial-Tunnel, the experiments establish S-Space as an accurate, persistent internal spatial workspace in multimodal language models; editing its coordinates causally alters spatial judgments while largely preserving non-spatial answers. Case studies suggest that S-Space emerges from spatial language prediction and can reflect relations implied by visual evidence, language, and abstract concepts. Further diagnosis with SpinBench and MMSI-Bench shows that spatial reasoning failures often stem from imperfect viewpoint transformations and coupling between cardinal and image-relative directions rather than from missing perceptual information.
Direct answer generation on SpinBench perspective-taking remains limited across all evaluated models, and providing the correct source-view relation gives only selective improvement. Chain-of-thought reasoning improves accuracy but still leaves substantial errors, especially for smaller models. Reading spatial coordinates from S-Space followed by an explicit rotation yields consistently large gains and near-perfect accuracy when the source-view relation is provided. Across models and premise settings, the S-Space plus rotation pipeline outperforms direct answering and chain-of-thought reasoning by large margins. With the correct source-view relation supplied, the S-Space pipeline reaches near-perfect accuracy, while direct and reasoning modes still leave notable errors. Larger models benefit more from chain-of-thought reasoning, but even the strongest reasoning result falls short of the explicit S-Space transformation.
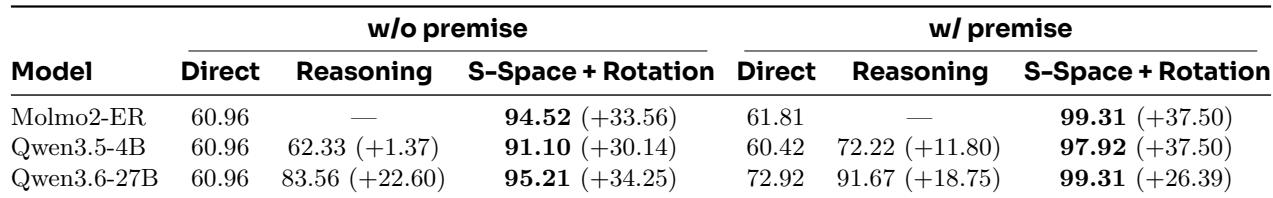
The evaluation on SpinBench perspective-taking compares direct answer generation, chain-of-thought reasoning, and an S-Space pipeline that reads spatial coordinates and applies an explicit rotation. Direct answering remains limited across all models and improves only selectively when the correct source-view relation is provided, while chain-of-thought reasoning reduces errors but still leaves substantial gaps, especially for smaller models. The S-Space plus rotation approach consistently yields large gains and near-perfect accuracy when the source-view relation is available, outperforming the other modes by wide margins across models and premise settings. Even the strongest chain-of-thought results from larger models fall short of the explicit S-Space transformation.