Command Palette
Search for a command to run...
Reflex
Reflex
Taoyang Jia Weikai Huang Linxin Song Jared Darlington Jieyu Zhao Yue Wang Jiafei Duan Zhongzheng Ren Ranjay Krishna
초록
인간은 세상에 별다른 노력 없이 반응한다. 능숙하게 테니스 샷을 리턴하고, 떨어지는 컵을 잡으며, 지나가는 수레를 옆으로 피하거나, 트럭 하역 중 던져진 상자를 받아 넘긴다. 이러한 일상 동작은 움직이는 표적을 예측하고 약 1초 이내에 전신으로 반사적으로 대응해야 한다. 이러한 시각적 반응형 전신 제어는 휴머노이드에게 여전히 어려운 과제인데, (1) 전신 제어를 조정하고, (2) 물체 동역학에 실시간으로 반응하며, (3) 지각의 근거를 자기중심 시각에 두어야 하기 때문이다. 우리는 던져진 상자 받기를 이 세 가지 능력을 모두 요구하는 대표적인 과제로 연구한다. 기존 시스템은 말단 장치(end-effector), 모션 캡처 또는 마커가 부착된 물체에 의존하여 그중 일부만 다룬다. 우리는 물체 동역학의 간결한 표현을 통해 이 능력들을 연결하면서 단계별로 학습하는 3단계 프레임워크인 Reflex를 제안한다. 첫째, 상태 기반 정책이 강화학습으로 상자를 전신으로 받아내는 방법을 학습한다. 둘째, 이 정책은 지연되고 불완전한 관측으로부터 움직이는 상자의 동역학을 추론하는 방법을 학습한다. 셋째, 자기중심 RGB-D 인코더는 전신 제어기를 고정한 채 시각 관측으로부터 이 동역학 표현을 직접 복원하도록 학습한다. 이러한 분해는 각 능력에 직접적인 학습 신호를 제공하고 시각 학습의 확장성을 크게 높인다. 시뮬레이션에서 Reflex는 자기중심 RGB-D로 85.7%의 상자 받기 성공률을 달성하며, 이는 특권적 상자 관측이 주어졌을 때의 87.9%와 비교된다. 시간적 시각 이력은 중요하다. 이를 제거하면 중앙 던지기와 측면으로 치우친 던지기에서 성공률이 각각 35.6%p와 39.8%p 하락한다. 실제 Unitree G1에서 Reflex는 2.5m와 5m 거리에서 사람이 던진 상자를 각각 65%와 40% 성공률로 받아내며, 이는 같은 거리에서 인간 포수 성공률의 76%와 59%에 도달한다.
One-sentence Summary
Researchers from the University of Washington, Stanford University, University of Southern California, et al. propose Reflex, a three-stage framework for visual reactive whole-body catching that separately trains a reinforcement-learning controller, a dynamics inference module, and an egocentric RGB-D encoder while keeping the controller frozen, achieving 85.7% simulation success and 65% real Unitree G1 catch success at 2.5m.
Key Contributions
- Reflex is a three-stage framework for humanoid box catching that learns whole-body control, object-dynamics inference, and egocentric RGB-D perception while connecting them through a compact representation of object dynamics.
- The method trains a state-based reinforcement learning policy for 29-DoF whole-body catching, then learns to infer moving-box dynamics from delayed and incomplete observations, and finally trains an egocentric RGB-D encoder to recover this dynamics representation from visual history and camera ego-motion while keeping the whole-body controller fixed.
- In simulation, Reflex achieves 85.7% catch success from egocentric RGB-D versus 87.9% with privileged box observations, and removing temporal visual history reduces success by 35.6 and 39.8 points on centered and laterally offset throws. On a real Unitree G1, Reflex catches human-thrown boxes at 65% and 40% success for 2.5 m and 5 m, reaching 76% and 59% of human catcher success.
Introduction
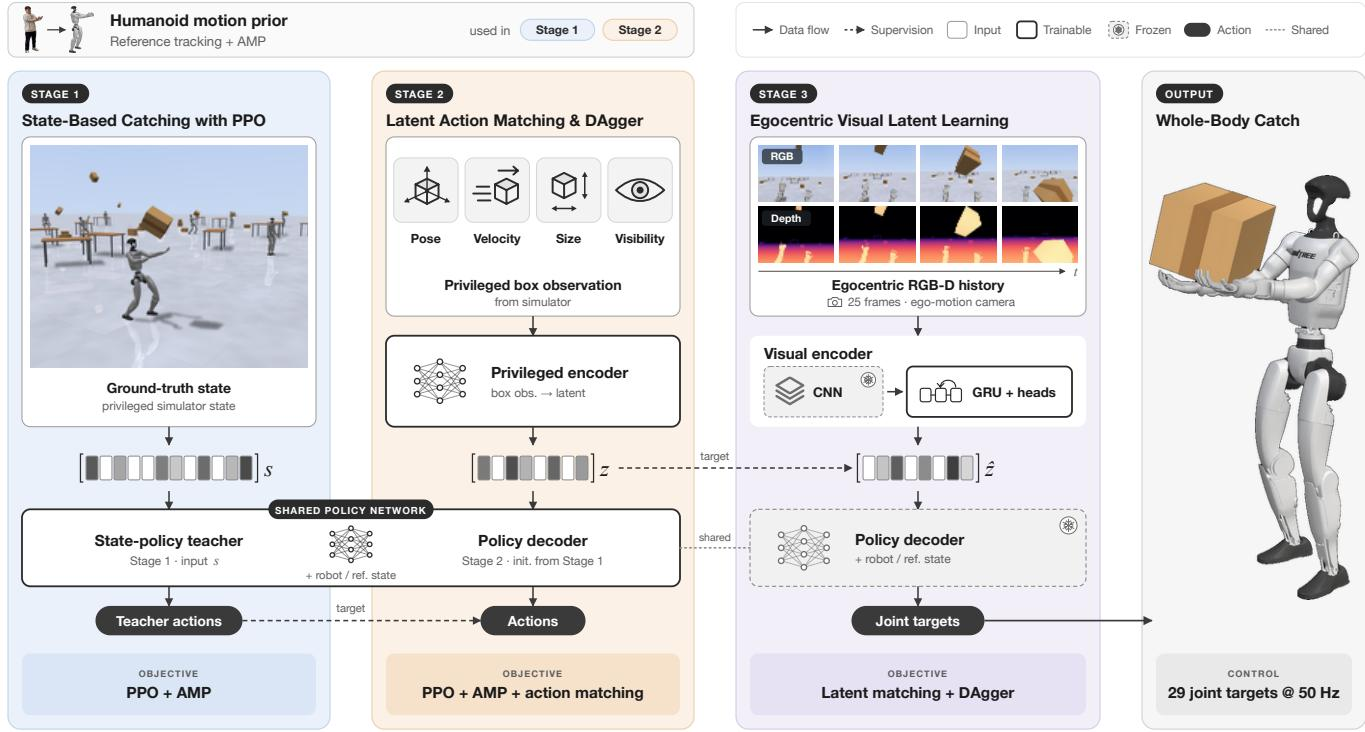
The authors study catching human-thrown boxes on a humanoid as a representative visually reactive whole-body control task. This capability matters because robots must predict where a fast-moving object will go, decide how to meet or avoid it, and coordinate the arms, torso, feet, and balance before contact, often within about a second, using only onboard sensing. Prior work addresses parts of this problem: manipulators catch from fixed or wheeled bases, while humanoid catching systems often rely on motion capture or retroreflective markers rather than onboard vision. As a result, whole-body control, fast object dynamics prediction, and egocentric visual grounding are rarely combined on a real humanoid. The authors introduce Reflex, a three-stage framework that learns whole-body catching from privileged simulation with reinforcement learning and human motion priors, learns a latent representation of moving-box dynamics from delayed and incomplete observations, and then trains a visual model to recover that latent from egocentric RGB-D history and camera egomotion while keeping the whole-body controller fixed.
Method
The authors decompose the deployed policy into a visual perception function Vψ and a whole-body control function πθ. Given a history of K egocentric RGB-D observations and camera ego-motion, Vψ predicts an eight-dimensional object-dynamics latent. The controller combines this latent with the robot and reference observation rt∈R160 to produce a normalized 29-DoF action:
zt=Vψ(It−K+1:t,et−K+1:t),at=πθ(rt,zt).The action is converted to nominal joint-position targets as qtnom=q0+s⊙at, where q0 is the nominal joint configuration and s contains per-joint action scales. To avoid the computational expense and optimization difficulties of joint end-to-end training, the authors organize learning into three distinct stages.
Stage 1 isolates the motor skill by learning whole-body control from box state using Proximal Policy Optimization (PPO). A state-based catching policy πstate is trained with a 170-dimensional observation combining the robot input with ten box-state channels. The actor is a multilayer perceptron producing the 29 outputs. The catching objective includes approach shaping, hold shaping, and a sustained-catch bonus, guided by tracking retargeted human reference motion and an adversarial motion prior (AMP). After training, the teacher policy is frozen to provide action supervision for the next stage.
Stage 2 learns the object dynamics by compressing delayed, partially observed box observations into a latent representation. A privileged encoder Eϕ maps a 26-channel box observation pt to an 8-dimensional latent zt=Eϕ(pt). The encoder processes the freshest visible sample in a delayed window. Initialization is performed via behavior cloning to match the teacher actions:
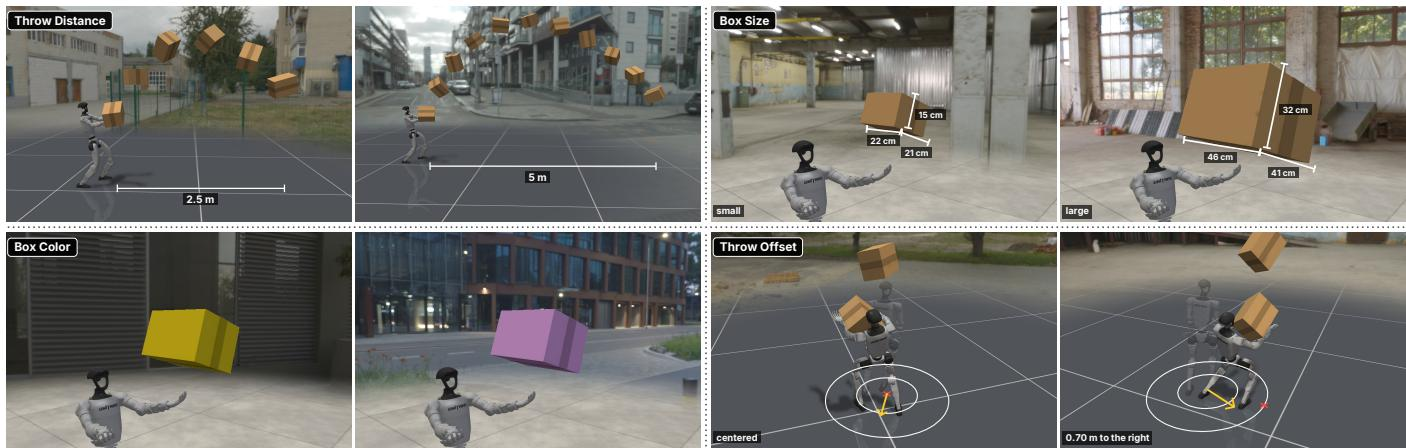
LBC=EDA[wtvisπθ(rt,Eϕ(pt))−atT22].Following action matching and DAgger-style data aggregation, PPO jointly optimizes the privileged encoder and the full decoder. The training incorporates randomized throw distances, box sizes, colors, and landing locations to ensure robustness across varying operating conditions.
Stage 3 grounds the dynamics latent in egocentric vision through supervised regression from RGB-D and ego-motion histories, while keeping the controller fixed. The visual encoder Vψ uses a history length of K=25. A convolutional neural network predicts a box-localization heatmap, from which a fixed geometric layer forms an 8-dimensional feature vector. A gated recurrent unit (GRU) processes these features along with ego-motion vectors to infer object motion. Training occurs in two steps. First, the CNN and heatmap head are trained using Gaussian targets. Second, the GRU is trained to predict the dynamics latent and auxiliary box position and velocity. The temporal-training objective is:
LV=EDV[ωt(ℓz(t)+λauxℓstate(t))]where ℓz(t) measures the normalized latent error and ℓstate(t) measures the auxiliary state error. A second DAgger-style procedure aggregates data from visual controller rollouts to refine the GRU.
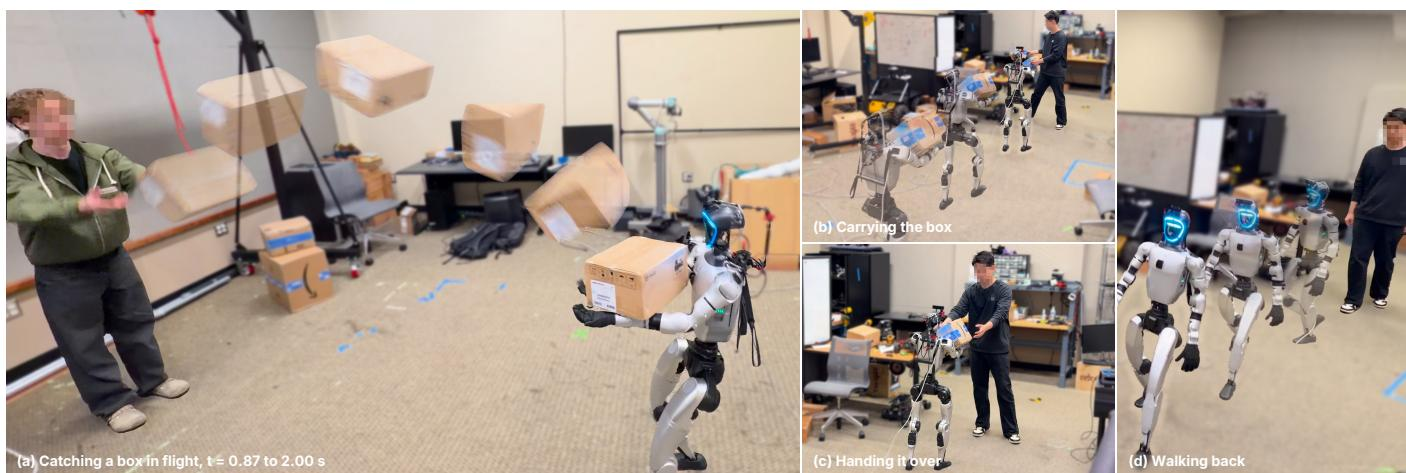
The downstream carrying and handover module connects the catching policy to a pretrained motion controller. A supervisor transfers command authority once a settled hold is established, switching gains and observations to the walking controller. The reference holds the current posture before transitioning to a standing cradle for walking and handover, with visual human detection identifying the recipient.
Experiment
The experiments evaluate Reflex in simulation and on a real Unitree G1 humanoid using separate success criteria for interception, catch retention, and post-catch stability, with comparisons to privileged state inputs, ablations, and human catchers. Whole-body ablations show that task rewards and motion priors are essential, object-dynamics experiments show that behavior cloning initialization and latency randomization improve latent prediction and robustness, and visual-grounding experiments show that temporal history and ego-motion cues matter while color augmentation reduces appearance sensitivity. Overall, visual control preserves most privileged catch performance in simulation and the robot tracks human success at shorter ranges, though long-range visual grounding and out-of-distribution box sizes remain the main limitations.
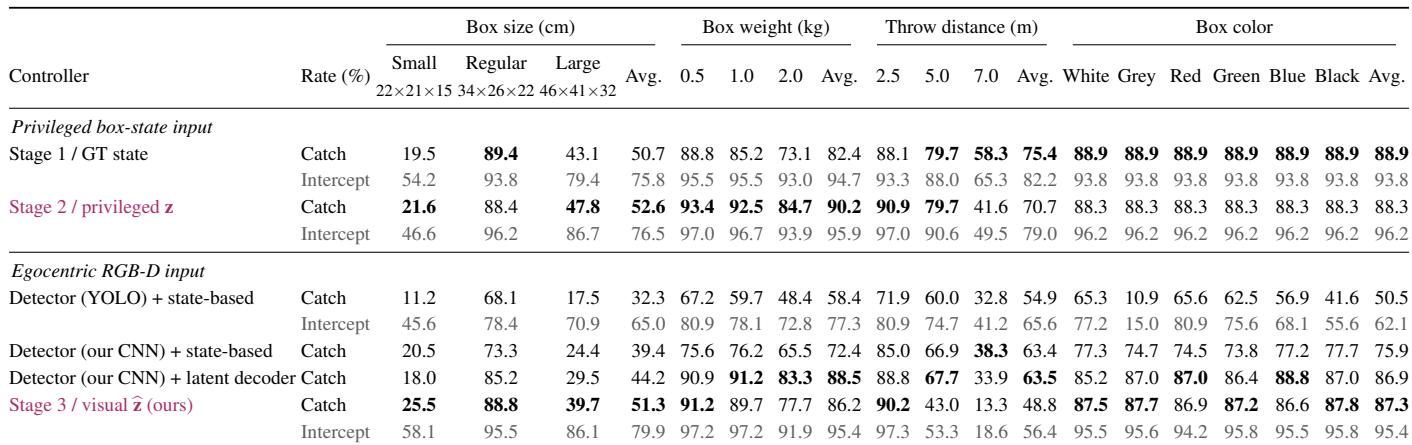
Under privileged box-state input, success is highest for the regular box size and lighter weights, while small boxes, heavier boxes, and longer throws reduce catch and interception. Interception rates are consistently higher than catch rates, and box color does not affect the privileged policies. Visual latent control exceeds detection plus filtering with the same detector within its visual training range. The regular training box size is the strongest condition, while the small box is hardest and the large box is intermediate. Heavier boxes and longer throw distances reduce success, with the longest distance producing the largest decline. Interception is consistently more frequent than catching under the same privileged state input. Box color does not change privileged policy performance, with identical rates across all tested colors. With the same detector, visual latent control outperforms detection plus filtering within its visual training range.
The real-robot catcher performs best with the regular box, a moderate box weight, and a 2.5 m throw distance. Success drops for small or large boxes, the heaviest box, and longer throws. Human reference catch rates are consistently higher, and the robot reaches about three-quarters of human success at 2.5 m and just over half at 5 m. Box size influences the robot strongly, with the regular box yielding the highest catch rate and small boxes causing the largest drop; human success varies less across sizes. For box weight, robot success peaks at 1 kg and declines at 2 kg, while human catch rates remain relatively flat. Throw distance creates a steep decline for the robot from 2.5 m to 7 m, with human performance also dropping but remaining higher. At 2.5 m and 5 m, the robot reaches 76% and 59% of human success, respectively.
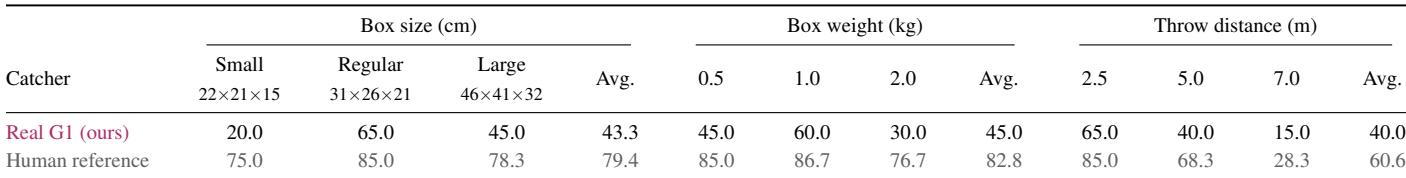
The privileged box-state experiments validate that regular box size and lighter weights give the highest success, while small boxes, heavy boxes, and longer throws reduce catching and interception; interception rates are consistently higher than catches, and box color has no effect. Visual latent control also outperforms detection plus filtering with the same detector within its visual training range. Real-robot tests confirm these trends, with best performance for a regular box, moderate weight, and 2.5 m throws, while small or large boxes, the heaviest weight, and longer distances degrade success. Compared with human reference catches, the robot reaches about three-quarters of human success at 2.5 m and just over half at 5 m.