Command Palette
Search for a command to run...
SuperNav: 모든 작업과 모든 장면을 위한 에이전틱 내비게이션 시스템
SuperNav: 모든 작업과 모든 장면을 위한 에이전틱 내비게이션 시스템
Jinkai Zhang Jingyi Xu Yuanhong Yu Jiarui Guo Ruizhen Hu Hujun Bao Xiaowei Zhou Sida Peng
초록
범용 서비스 로봇은 낯선 환경에서 다양한 인간의 요청을 처리할 수 있는 내비게이션 시스템이 필요하며, 이는 작업 일반성과 장면 일반성을 결합해야 한다. 기존 일부 방법은 멀티모달 대규모 언어 모델(MLLM)을 미세 조정하여 내비게이션 행동을 예측하게 하는데, 이로 인해 행동이 내비게이션 훈련 데이터의 포괄 범위에 의존하게 되고 새로운 요청과 환경에 대한 일반화가 제한될 수 있다. 우리의 핵심 통찰은 MLLM이 범용 능력을 유지하면서 요청 해석, 장면 이해, 의사 결정에 집중하고, 동작 실행은 내비게이션 도구에 위임하도록 하는 것이다. 이 아이디어를 구현하기 위해, 우리는 사전 훈련된 MLLM에 내비게이션 특화 미세 조정 없이 전문 에이전트 하네스를 장착한 SuperNav를 제안한다. 우리 하네스는 내비게이션 스킬, 물리적 상호작용을 위한 에이전트 지향 도구, 그리고 작업 진행 및 컨텍스트 관리를 통해 이러한 결정을 지원한다. 통합된 비주얼 포인트 인터페이스는 모델이 이미지에서 직접 목적지를 지정하고 실행 피드백을 통해 결정을 수정할 수 있게 함으로써 의사 결정과 동작을 연결한다. 이러한 구성 요소들은 함께 다양한 작업 요구 사항과 환경 전반에서 지속적인 내비게이션을 지원한다. SuperNav는 인스턴스 수준, 다중 객체, 수요 기반 작업에서 평가된 네 가지 베이스라인을 능가한다. HM3D에 대한 카테고리 수준 평가와 실제 사족 보행 로봇에 대한 배포는 다양한 환경에서의 적용 가능성을 추가로 입증한다. 프로젝트 페이지: https://zju3dv.github.io/SuperNav/
One-sentence Summary
Zhejiang University, Shenzhen University, and Causa Robotics propose SuperNav, an agentic navigation system that equips a pretrained MLLM with a specialized harness, Navigation Skills, agent-oriented tools, and a unified visual-point interface, enabling task- and scene-general navigation without navigation-specific fine-tuning, outperforming four baselines on instance-level, multi-object, and demand-driven tasks, and demonstrating applicability through category-level HM3D evaluation and real quadruped deployment.
Key Contributions
- The paper presents SuperNav, a navigation harness that enables a pretrained multimodal large language model to interpret requests, understand scenes, and make navigation decisions without navigation-specific fine-tuning, while delegating motion execution to external tools.
- The method introduces agent-oriented tools and optional Navigation Skills, supported by task-progress tracking and context management, and uses a unified visual-point interface to specify destinations in images and revise decisions from execution feedback.
- Experimental results show that SuperNav outperforms four evaluated baselines on instance-level, multi-object, and demand-driven navigation, with further evidence from category-level evaluation on HM3D and deployment on a real quadruped robot.
Introduction
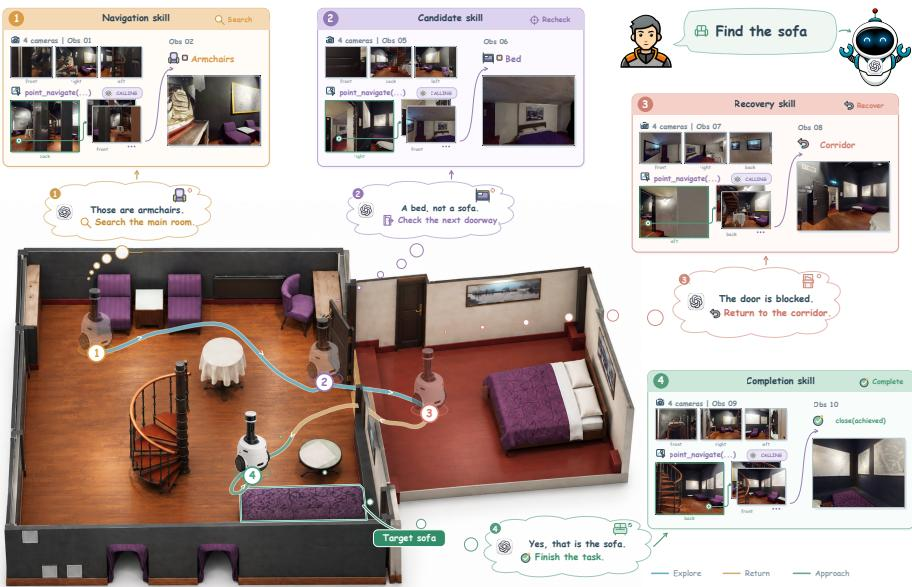
General-purpose service robots need navigation that can handle diverse requests in unfamiliar environments, from finding a specific object and visiting multiple targets to satisfying abstract needs such as finding a place to rest. These variations change how the robot interprets goals, explores, tracks progress, and decides when to stop, so both task generality and scene generality are important for practical deployment.
Prior work has limitations. Modular zero-shot navigation systems use pretrained vision-language models to measure semantic relevance, but task-specific logic still determines how exploration transitions to confirmation and when execution ends. Changing the request type often requires changing the workflow. End-to-end navigation methods fine-tune vision-language models on navigation data, but their transfer depends on training coverage and often breaks under new visual appearances, spatial layouts, and interaction conditions.
The authors introduce SuperNav, an agent harness that enables a pretrained multimodal large language model to direct navigation without navigation-specific fine-tuning. The MLLM interprets requests, understands visual observations, and reasons about actions, while the harness provides observation, motion, and task management tools, optional navigation skills, progress tracking, and context management. A unified visual-point interface lets the MLLM specify destinations directly in an image, and the navigation tool executes movement and returns feedback. The authors evaluate SuperNav on category-level, instance-level, multi-object, and demand-driven navigation, plus real-robot deployment, and report substantial improvements over action-prediction baselines.
Method
The authors present SuperNav, a system that combines a pretrained Multimodal Large Language Model (MLLM) with a navigation-specific harness to create an embodied navigation agent. This architecture sustains decisions and actions across diverse requests, ranging from specific targets to high-level needs. The MLLM handles interpretation and decision-making, while the harness organizes execution and context through a continuous agent loop. Within this framework, agent-oriented tools provide callable operations for observation, motion, and state management, and navigation skills offer procedural guidance for search, verification, and recovery.
As shown in the figure below:
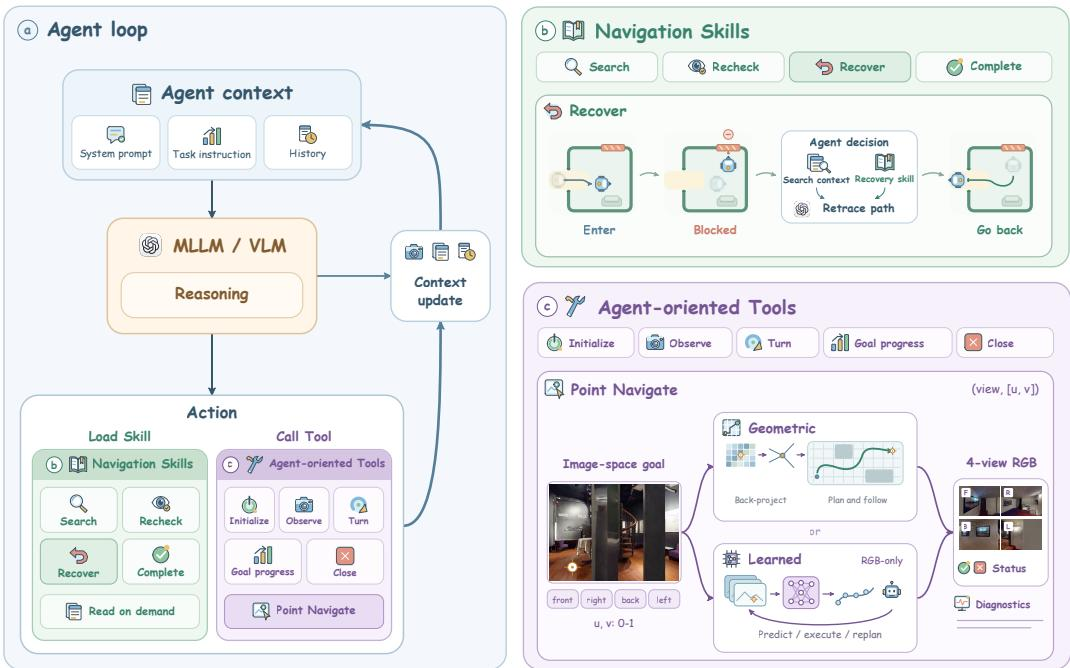
The agent loop coordinates these capabilities by organizing the request, visual observations, and interaction history into a continuous navigation process. Upon initialization, the system opens a session and returns the first observation, allowing the MLLM to interpret the requested goals and completion conditions. At each subsequent step, the model uses the current context and task progress to select an operation, such as observing, moving, updating the goal state, or reading relevant skill guidance. The returns from these tools and retrieved instructions update the context for the next decision, enabling execution feedback to dynamically alter the plan.
To manage long-horizon execution, the harness maintains goal records for pending and completed items alongside a textual interaction history that retains inspected areas, candidate clues, and failed attempts. To control the growing image context, the system employs a media-only pruning strategy. It removes the media payload of an image from subsequent requests once it has been processed and superseded by newer observations, while preserving the textual history, task state, and image paths. The MLLM can still request earlier images from the workspace when necessary. Finally, the MLLM judges whether the request is satisfied or if execution is blocked, selecting a termination tool to record the outcome and close the session.
Agent-oriented tools connect the MLLM navigation decisions to executable environment operations. The suite includes initialization, observation, turning, visual-point navigation, goal-progress management, and termination. The central observation and motion interface pairs visual destinations with updated observations and execution feedback. An observation returns four RGB images labeled front, right, back, and left relative to the robot heading. These labels allow the MLLM to associate a candidate or passage with a specific view and select a destination using the PointNav function:
PointNav(d,[u,v]),u,v∈[0,1]where d identifies the view and u,v are normalized horizontal and vertical coordinates. The tool executes the movement internally and returns new four-view images, execution status, and concise diagnostics.
This visual-point interface separates destination selection from the execution mechanism, supporting interchangeable motion backends. The geometric backend, or Geo-based Executor, uses depth, camera calibration, and pose to associate the selected point with an environment location, then plans and follows a path. The learned backend, or Learned Executor, replaces destination-image goals with marked points in reference observations. It predicts local displacement increments and a stopping signal from the selected image-point pair and recent RGB observations, repeatedly executing short predicted motion segments within a single tool call. Both backends accept visual destinations and return observations with execution feedback, ensuring the agent retains a consistent decision workflow.
Navigation skills organize reusable navigation experience into procedural guidance that the MLLM can read on demand. Each skill is structured as a Markdown package describing applicable situations, evidence to inspect, recommended steps, and linked references. The bundle includes a main navigation skill, backend-specific tool-use instructions, and references for exploration, recovery, and entrance search. The harness exposes skill names and descriptions so the MLLM can discover the relevant package and load its instructions into the decision context.
This guidance addresses three recurring decisions: where to search, how to recover, and when to finish. Search guidance prompts the MLLM to record inspected areas and visible openings, preserving alternatives for later exploration. Recovery guidance recommends changing the point or route after failed motion, stepping back when a candidate is difficult to inspect, or seeking an entrance when glass blocks access. Completion guidance calls for checking the candidate appearance, requested relations, and surrounding context before recording verified goals. These skills influence decisions by entering the context but do not programmatically enforce action sequences, leaving the final operational choices to the MLLM based on the current request and feedback.
Experiment
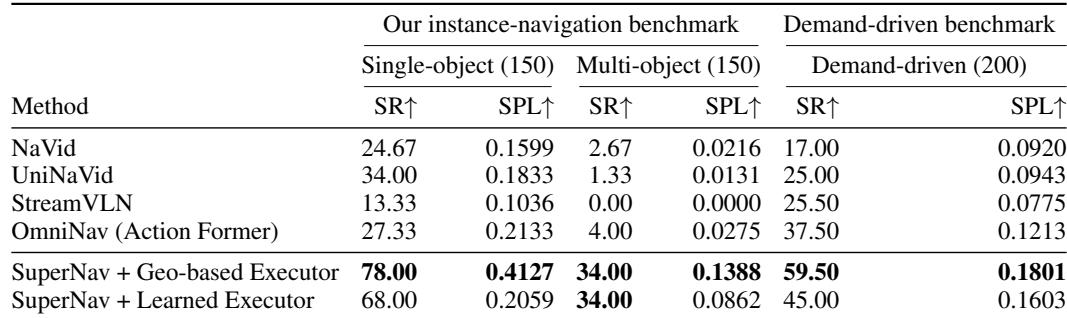
SuperNav is evaluated with GPT-5.6 Terra and either a Geo-based or Learned Executor across Habitat-GS instance navigation, AI2-THOR demand-driven navigation, HM3D category navigation, harness ablations, and real-world deployment, with comparisons to NaVid, UniNaVid, StreamVLN, and OmniNav. The framework improves over baselines on multi-object and inferred-goal tasks, and the Geo-based executor generally preserves success while producing more efficient paths than the Learned executor. Ablations indicate that Navigation Skills are particularly important, external grounding does not beat direct point selection, and replacing the decision model can improve success and path efficiency, while real-world tests show route revision and goal transitions.
SuperNav with the Geo-based Executor leads all evaluated methods across single-object, multi-object, and demand-driven navigation, with especially large gains in single-object tasks. Ordered multi-object navigation remains difficult for every method, with success rates falling sharply relative to single-object results. Demand-driven navigation shows clear improvements over baselines in both success and path efficiency, though long sequences remain challenging. SuperNav with Geo-based Executor achieves the best success and path efficiency in every reported benchmark setting. Single-object success more than doubles the strongest baseline, while multi-object performance drops substantially across all methods. In demand-driven navigation, SuperNav with Geo-based Executor clears the best baseline by a wide margin in both success rate and SPL.
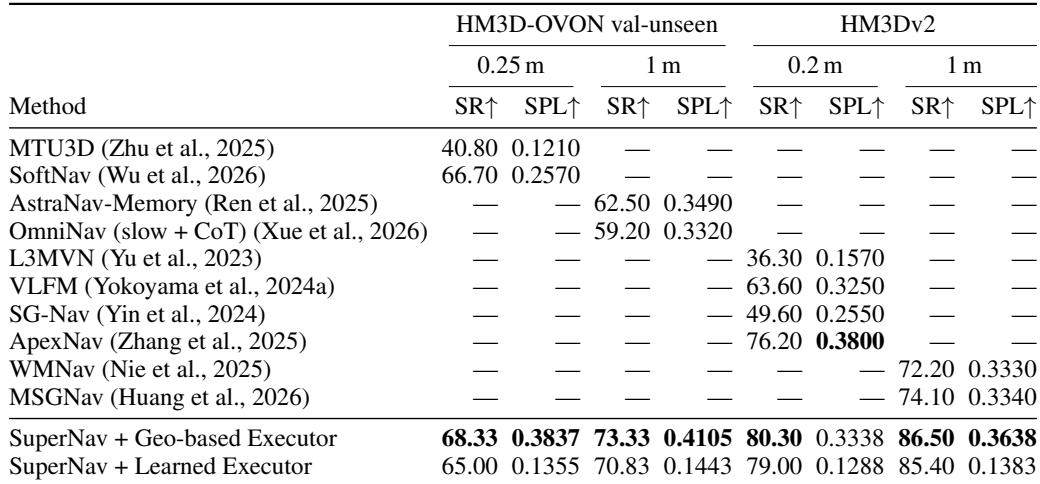
On HM3D-OVON val-unseen, SoftNav leads the listed external methods in both success and SPL, while MTU3D is substantially lower. In HM3Dv2 comparisons, AstraNav-Memory edges out OmniNav in both success and path efficiency under the same threshold. The accompanying text reports that the Learned Executor preserves much of the Geo-based Executor's success but sacrifices path efficiency, and the Geo-based Executor remains competitive with these published baselines. SoftNav attains the highest HM3D-OVON val-unseen success and SPL among listed external results, with MTU3D notably lower. AstraNav-Memory slightly outperforms OmniNav in success rate and SPL on the shared HM3Dv2 threshold. Learned Executor keeps much of Geo-based Executor's success but is less path-efficient, while Geo-based Executor is competitive with published methods.
Ablations with the Geo-based Executor show that removing navigation skills reduces success rate more than restricting the interface to a front view, especially at the stricter distance threshold. The full SuperNav harness performs best overall, and substituting the Astra medium decision model for Terra high improves both success rate and path efficiency. Removing navigation skills lowers success rate more than front-only interaction, with the largest gap at the stricter 0.25 m threshold. The full SuperNav configuration achieves the highest success rate and SPL under both distance thresholds. Substituting the Astra medium decision model for Terra high improves both success rate and SPL while keeping the harness fixed. External grounding does not outperform the agent's direct point selection.
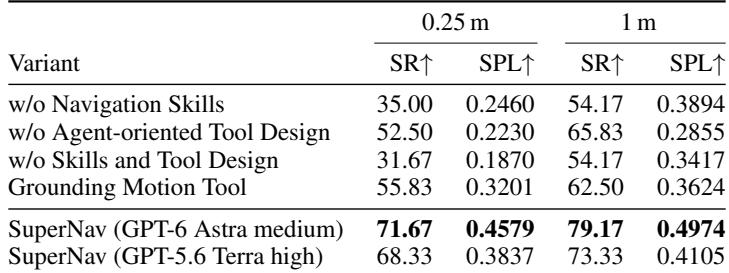
The experiments evaluate SuperNav with a Geo-based Executor across single-object, multi-object, and demand-driven navigation, and compare it with external methods on HM3D-OVON and HM3Dv2 benchmarks. SuperNav with the Geo-based Executor consistently leads in success and path efficiency, with single-object success more than doubling the strongest baseline, while ordered multi-object navigation remains difficult for every method. In external comparisons, SoftNav leads HM3D-OVON results and AstraNav-Memory slightly outperforms OmniNav on HM3Dv2, whereas the Learned Executor retains much of the Geo-based Executor's success but is less path-efficient. Ablations show that removing navigation skills hurts success more than front-only interaction, the full configuration performs best, and substituting the Astra medium decision model for Terra high improves both success and path efficiency.