Command Palette
Search for a command to run...
사고 관성: LLM은 사고하지 말라고 지시해도 계속 사고한다
사고 관성: LLM은 사고하지 말라고 지시해도 계속 사고한다
Dianqiao Lei Kevin Qinghong Lin Pan Lu Philip Torr James Zou
초록
대규모 언어 모델(LLM)은 명시적인 ‘사고 모드’를 점점 더 기본 탑재하고 있지만, 그 반대 개념인 ‘무사고(no-thinking)’는 훨씬 덜 주목받아 왔다. 본 연구에서는 LLM의 ‘무사고’ 행동을 두 가지 축으로 연구한다. a. 무사고를 어떻게 측정할 것인가? 기존 연구는 대개 사고 모드 비활성화나 긴 추론 흔적의 부재 같은 대리 지표를 통해 무사고를 정의한다. 그러나 이러한 대리 지표는 신뢰할 수 없다. 사고 모드를 비활성화해도 여전히 확장된 추론을 내보내거나, 긴 추론 흔적이 실제 추론보다 정보성이 낮은 군더더기를 포함하는 경우가 많다. 이에 본 연구는 모든 LLM 응답을 답변 이전 추적(pre-answer trace)과 최종 답변으로 정규화하고, 세 가지 수준에서 평가한다: (i) 엄격한 답변만 출력(answer-only) 준수를 측정하는 빈 사고 비율(Empty-Thinking Rate); (ii) 질문과 답변 이전 추적 간 유사도를 계산하는 지시 인지형 질문–답변 전 추적 관련성(Question–Pre-answer Relevance); (iii) 가시적인 명시적 추론을 측정하는 LLM 심판 방식의 명시적 추론 비율(Explicit Inference Rate). 이 세 수준을 함께 사용하면 답변만 출력, 관련성은 있으나 추론이 아닌 텍스트, 명시적 추론을 구분할 수 있다. 인간 평가 연구는 이 지표들의 효과를 입증한다. b. 무사고 행동은 과제와 모델에 따라 어떻게 달라지는가? 우리는 6개의 널리 사용되는 LLM(오픈소스 및 상용 모델 포함)을 대상으로 세 가지 질문 유형(참거짓, 객관식, 개방형)에 걸쳐 6가지 프롬프트 개입 설정을 평가한다. 그 결과 명시적인 무사고 통제는 가시적인 명시적 추론을 신뢰성 있게 제거하지 못하는 것으로 나타났다. 모델은 대신 ‘사고 관성(Thinking Inertia)’을 보인다. 즉, 엄격한 무사고 통제 하에서도 가시적인 명시적 추론이 지속되며, 답변 공간이 열릴수록 점점 더 빈번해진다. 반면 참거짓 및 객관식 과제에서는 정확도가 비교적 안정적으로 유지되지만, 개방형 과제에서는 답변만 출력하는 준수율과 과제 정확도 사이의 상충이 드러난다. 마지막으로, 동일한 질문을 답변 공간별로 다시 작성한 실험에서는 후보 답안을 제공하는 것이 답변만 응답을 훨씬 쉽게 만들어 준다는 것을 보여준다. 종합하면, 이러한 발견은 무사고가 LLM의 결코 사소하지 않은 능력임을 확립한다. 명시적 추론의 중단은 모델 설정이나 지시만으로 가정할 수 없으며, 추론 능력 자체와 함께 체계적으로 평가되어야 한다.
One-sentence Summary
Researchers from Tsinghua University, University of Oxford, and Stanford University replace unreliable no-thinking proxies with three metrics, Empty-Thinking Rate, Question–Pre-answer Relevance, and LLM-as-judge Explicit Inference Rate, and show across six LLMs that visible "Thinking Inertia" persists under strict no-thinking controls, especially for open-ended tasks where answer-only compliance trades off against accuracy.
Key Contributions
- A response-level measurement framework normalizes each model output into a pre-answer trace and a final answer, then scores it with three metrics: Empty-Thinking Rate for strict answer-only compliance, instruction-aware Question-Pre-answer Relevance, and an LLM-as-judge Explicit Inference Rate; human studies support these metrics.
- Evaluations across six prompting intervention settings, six open-source and commercial LLMs, and Boolean, multiple-choice, and open-ended questions show that explicit no-think controls cannot reliably eliminate visible explicit inference. The results identify “Thinking Inertia,” where visible explicit inference persists under strict controls and becomes more prevalent as the answer space opens, while accuracy remains relatively stable on Boolean and multiple-choice tasks but trades off with answer-only compliance on open-ended tasks.
- Same-question rewrites across answer spaces show that providing candidate answers makes answer-only responses substantially easier, and the findings frame no-thinking as a measurable, non-trivial capability that should be evaluated separately from reasoning rather than assumed from model settings or instructions.
Introduction
LLMs gain accuracy from extended reasoning, but this imposes latency and token costs, and human-like adaptive reasoning requires knowing when to answer directly. Prior work typically infers no-thinking from surface proxies such as absent reasoning traces, short outputs, or disabled thinking modes, which conflates instruction compliance with actual suppression of task-relevant pre-answer content. The authors address this gap by defining no-thinking as an observable response behavior and introducing three metrics: Empty-Thinking Rate, Question-Pre-answer Relevance, and Explicit Inference Rate. Their main contribution is a behavioral evaluation framework and a multi-model study showing that explicit no-think controls are unreliable, models exhibit thinking inertia organized by answer space, and stricter answer-only constraints can create a trade-off between compliance and task accuracy.
Method
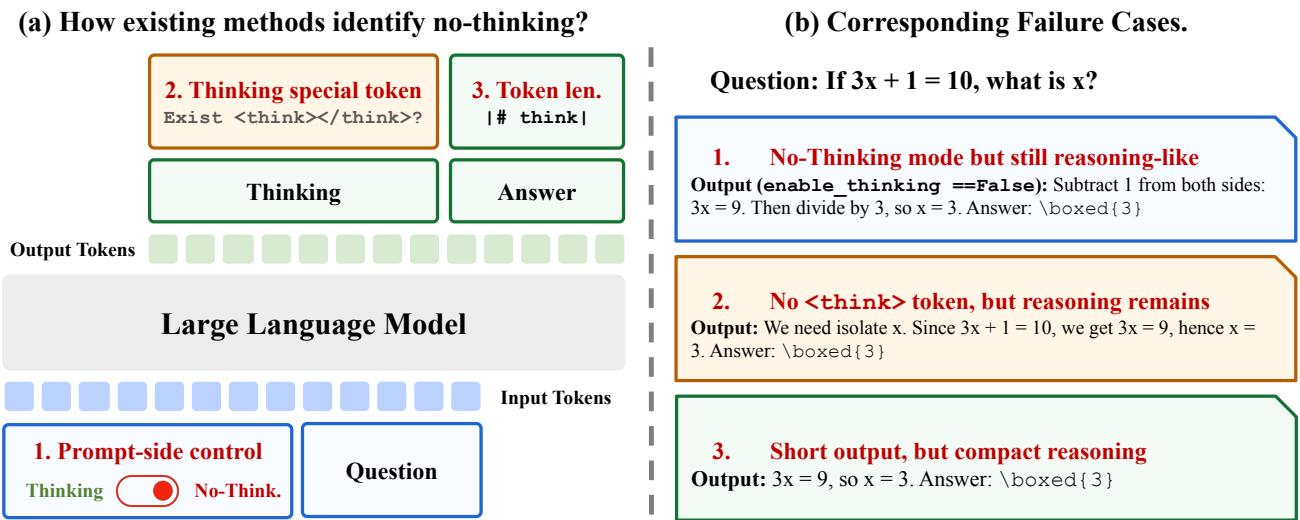
The authors first argue that existing definitions of no-thinking usually rely on surface proxies. These include prompt-side control, such as running a model without a step-by-step instruction; visible-format control, such as checking whether a special reasoning block is absent; and length-based control, such as treating a short response as reduced reasoning. The authors note that each proxy can fail. A no-think instruction can still produce question-dependent explanation before the final answer, deleting special tokens only removes a format while reasoning may remain in ordinary text, and a compact output can still contain a necessary inferential step.
To avoid these confounds, the authors model no-thinking at the observable response level rather than at the prompt or format level. Formally, let π denote a language model and Q a task sample. An intervention S(⋅) wraps the question before generation, and the model produces a visible response
π(S(Q))=(T,A),where A is the last parseable final answer and T is all readable visible text that precedes it. The authors treat (T,A) only as a decomposition of the observable output, without making claims about latent computation inside the model. The task sample is written as Q=(q,c,A), where q is the question, c is optional context, and A is the admissible answer space. This allows the evaluation to cover Boolean, multiple-choice, and open-ended tasks. Interventions are divided into question-irrelevant interventions, which modify instructions or output constraints while keeping the task content fixed, and question-relevant interventions, which change the task instance itself, such as its surface form or answer space.
The overall measurement framework is illustrated below.
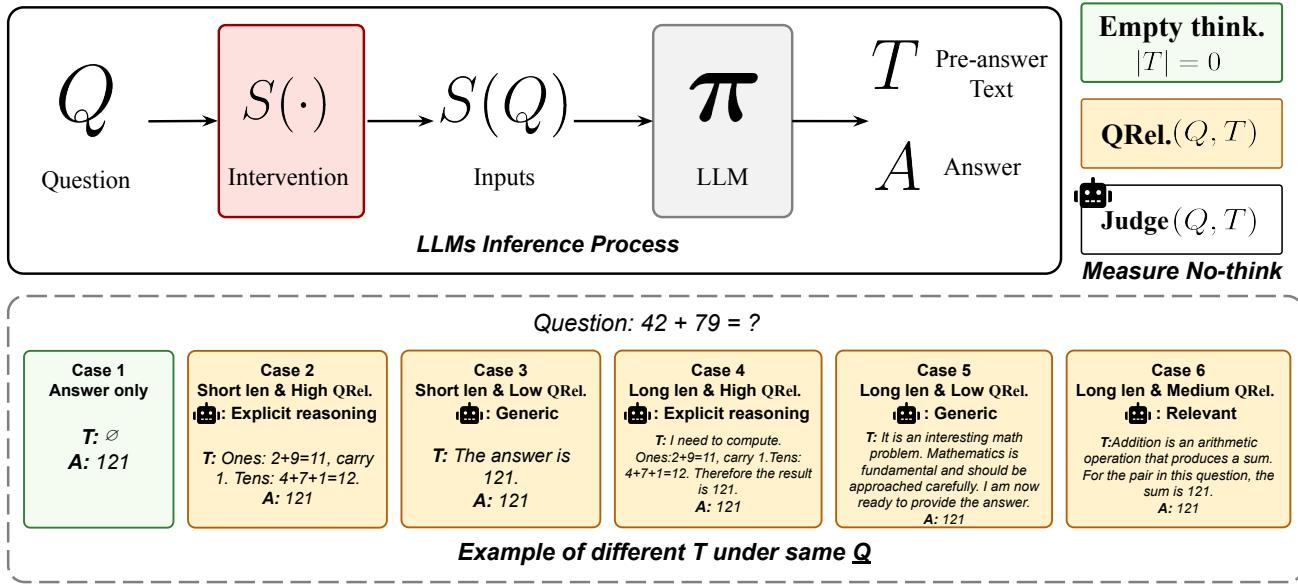
The authors evaluate the visible pre-answer text T through three progressively stricter response-level criteria. The final answer A is evaluated separately for task accuracy.
The first level is strict answer-only compliance. For output i, the response-level empty-thinking indicator is defined as
ei=1{∣Ti∣=0},and the benchmark-level Empty-Thinking Rate is
ETR=100%×N1i=1∑Nei.This indicator is 1 only when the final answer is parseable and the complete visible output contains no substantive text outside a permitted answer wrapper. Substantive text after A also violates strict compliance. The authors use ETR as the cleanest operational boundary, although it cannot distinguish generic templates, paraphrases, or explicit inference once Ti is nonempty.
The second level measures question-to-pre-answer relevance. Let ϕ be an embedding encoder, instantiated with the instruction-aware Qwen3-Embedding-4B model. The question Qi is encoded under an instruction that asks for pre-answer text relevant to answering the question, while Ti is encoded as the candidate passage. After ℓ2 normalization, the response-level Question–Pre-answer Relevance score is
QRel.(Qi,Ti)={0,cos(ϕ(Qi),ϕ(Ti)),∣Ti∣=0,∣Ti∣>0.The benchmark-level QRel. is the arithmetic mean over all responses, including zeros for empty Ti. This level captures relevance but does not by itself distinguish inferential reasoning from a relevant restatement or answer assertion.
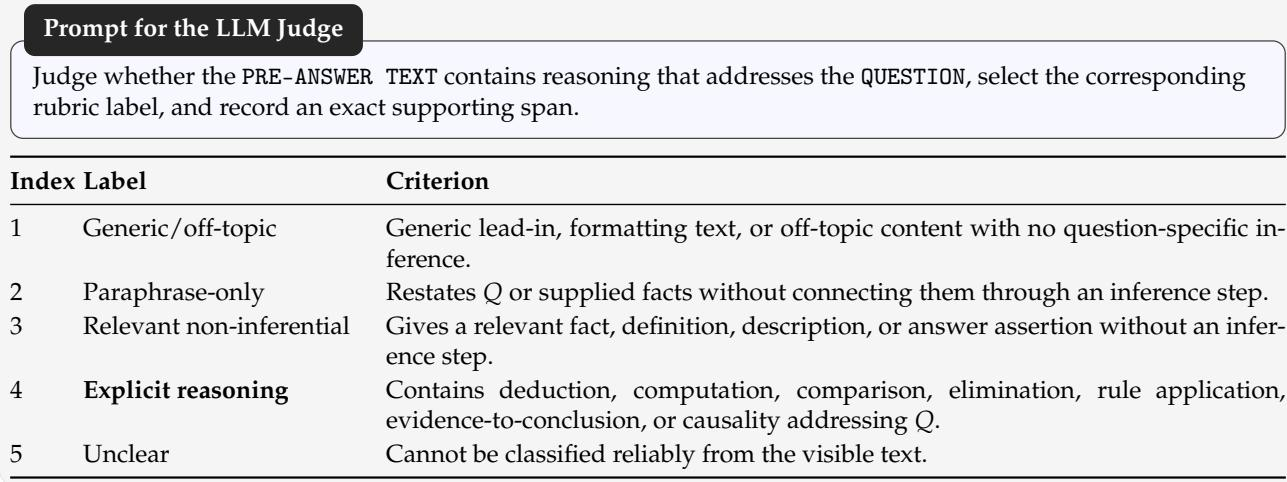
The third level targets visible explicit inference. A blinded LLM judge receives only (Qi,Ti), without model identity, intervention mode, final answer, correctness, or QRel. score. For each nonempty Ti, the judge selects one of five mutually exclusive labels and returns an exact supporting span as evidence. A relevant restatement or answer assertion alone is not treated as reasoning, whereas one concrete inferential step can qualify even if it is short, shallow, or incorrect. The judge score is 1 only for the explicit reasoning label and 0 otherwise. Empty Ti is assigned a score of 0. The benchmark-level Explicit Inference Rate is
EIR=100%×N1i=1∑NJudge(Qi,Ti).The authors further validate the automated metrics with a blinded human study. Human annotators audit the strict visible boundary behind ETR, provide graded relevance judgments for QRel., and produce explicit-inference labels for comparison with the LLM judge. A second judge from a different model family is also used to check judge-specific effects.
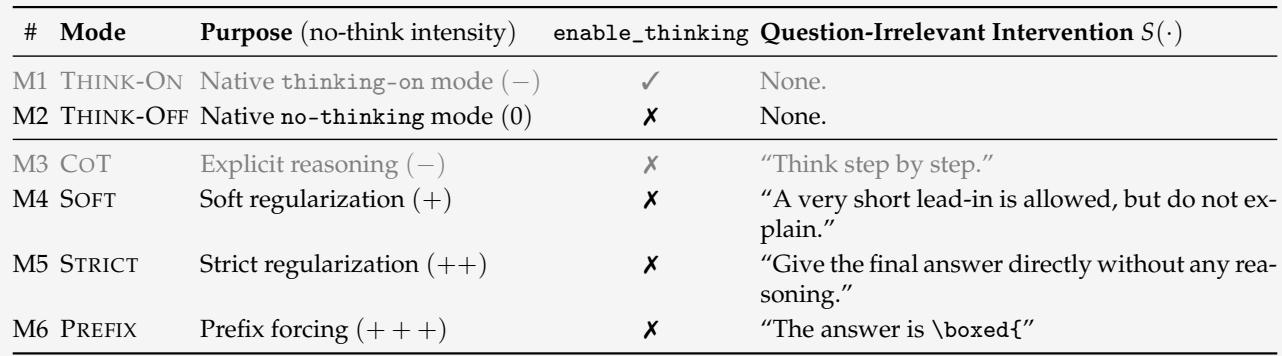
Finally, the authors design a six-mode control spectrum to study how visible thinking behavior changes under different interventions. All modes share the same task stem and final-answer request, and only the thinking switch or the question-irrelevant instruction changes. THINK-ON keeps the official thinking interface enabled, while COT disables it but adds the instruction "Think step by step" to re-elicit reasoning in the ordinary answer channel. These serve as thinking-encouraging references. THINK-OFF disables the native thinking interface without additional output control, serving as the baseline no-thinking condition. SOFT and STRICT keep the native interface disabled and add progressively stronger natural-language constraints, while PREFIX bypasses instruction following by pre-filling an answer template at the start of generation. This design lets the authors compare native no-think behavior, reasoning re-elicitation, semantic suppression, and structural prefix forcing under a unified response-level evaluation framework.
Experiment
The study evaluates no-thinking behavior across six models and six benchmarks spanning Boolean, multiple-choice, and open-ended answer spaces, using empty-thinking rate, question-pre-answer relevance, explicit inference rate, and task accuracy. Native think-off controls often leave visible pre-answer reasoning, and this thinking inertia increases from Boolean to multiple-choice to open-ended tasks, while step-by-step prompts can restore visible inference. Stronger answer-only constraints reduce explicit inference but can lower accuracy on open-ended tasks, and answer-space rewrites of identical questions confirm that the required answer interface shapes direct answering. Blinded human annotations largely agree with the automated metrics and reproduce these main trends.
The rubric classifies non-empty pre-answer text into five categories: generic/off-topic, paraphrase-only, relevant non-inferential, explicit reasoning, and unclear, while empty pre-answer text is handled separately and treated as no visible explicit inference. This supports a three-level response evaluation covering strict answer-only compliance, pre-answer relevance, and visible explicit inference. Across models and tasks, visible explicit inference remains difficult to suppress and persists on open-ended tasks even under strict natural-language constraints. Non-empty pre-answer text is separated into generic/off-topic, paraphrase-only, relevant non-inferential, explicit reasoning, and unclear categories, with empty text counted as no visible explicit inference. Explicit reasoning covers deduction, computation, comparison, elimination, rule application, evidence-to-conclusion, and causality that address the question. Visible explicit inference becomes harder to suppress as the answer space opens and remains common on open-ended tasks under strict no-think instructions.
A six-mode intervention spectrum separates thinking-encouraging modes from a no-think space that ranges from a native no-thinking baseline to increasingly strong semantic suppression. THINK-ON and CoT serve as thinking-side references by enabling or re-eliciting reasoning, while THINK-OFF, SOFT, STRICT, and PREFIX constrain the output channel in different ways. PREFIX is a distinct branch that pre-fills the answer template, bypassing instruction-following rather than strengthening a natural-language constraint. The no-think space moves from THINK-OFF, the native no-thinking baseline, through SOFT and STRICT natural-language constraints to PREFIX, which forces an answer template. THINK-ON keeps the thinking interface enabled, whereas CoT disables it but adds a step-by-step instruction to re-elicit reasoning in the ordinary answer channel. SOFT allows a short lead-in but forbids explanation, while STRICT asks for the final answer directly without any reasoning. PREFIX is qualitatively different from STRICT because it pre-fills the answer template 'The answer is \boxed{' at the start of generation, bypassing instruction-following entirely.
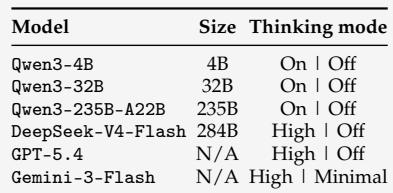
The baseline suite spans open Qwen3 checkpoints at several scales, DeepSeek-V4-Flash, and proprietary OpenAI and Google models, all selected for explicit thinking-mode controls. Evaluation covers Boolean verification, multiple-choice answering, and open-ended generation, with an easier and harder benchmark in each family. Reported metrics combine task accuracy with three response-level no-thinking measures computed over the full output set. Selected models provide paired native controls or comparable explicit thinking-mode settings, allowing direct intervention rather than inference from output length or format. Benchmarks progress from binary judgments through fixed-choice selection to open-ended generation, supporting answer-space comparisons under the same evaluation metrics.
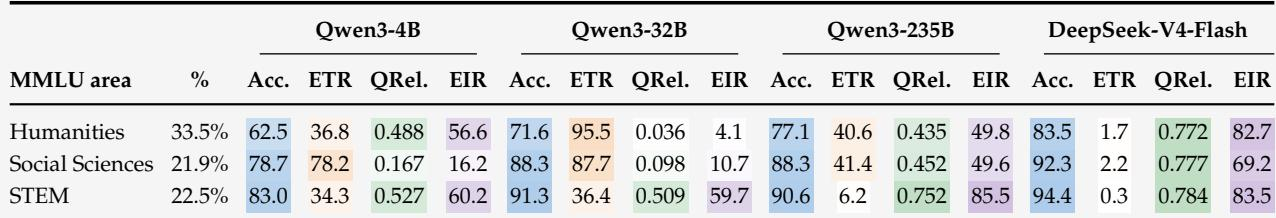
Under a fixed four-choice multiple-choice interface, no-thinking behavior still varies across MMLU subject areas. STEM tasks consistently combine the highest accuracy with the lowest ETR and the highest QRel and EIR across all model sizes. This suggests answer-only compliance is not simply tied to task success and that domain remains a source of variation. STEM shows the highest accuracy but the lowest ETR in every model block, while also showing the highest QRel and EIR. Humanities and social sciences exhibit higher or more variable ETR than STEM across the compared models, despite often high accuracy. The domain pattern is visible beyond ETR, with STEM also leading in pre-answer relevance and explicit-inference measures.
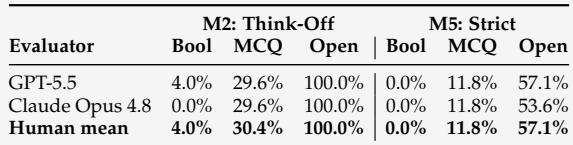
Explicit-inference rates are strongly organized by answer space: Boolean prompts show almost no visible inference, multiple-choice prompts show moderate rates, and open-ended prompts show the highest rates, reaching universal visible inference in one condition. Stricter instruction reduces explicit inference in multiple-choice and open-ended settings, yet the majority of open-ended responses still contain explicit inference. Human mean judgments align closely with the LLM-judge estimates across all conditions. Explicit inference increases as the answer space opens, from near zero in Boolean prompts to moderate in multiple-choice and highest in open-ended prompts. Stricter constraints reduce explicit inference substantially in multiple-choice and open-ended settings, but open-ended responses still show explicit inference more than half the time. Human annotator averages closely match the LLM-judge rates across all sampled answer-space conditions.
The experiments evaluate how well models can suppress visible explicit inference under no-thinking instructions by using a rubric for pre-answer text and a six-mode intervention spectrum across open Qwen3, DeepSeek, OpenAI, and Google models on Boolean, multiple-choice, and open-ended benchmarks. The studies validate that no-thinking behavior varies by instruction strength, domain, and answer space, with stricter constraints reducing but not eliminating explicit reasoning, while STEM tasks show comparatively high answer-only compliance and relevance. Explicit inference increases as the answer space opens, and human judgments closely match LLM-judge estimates across conditions.