Command Palette
Search for a command to run...
VIS-Ground: 맥락적 그라운딩을 통한 비디오 인터랙티브 스토리텔링
VIS-Ground: 맥락적 그라운딩을 통한 비디오 인터랙티브 스토리텔링
초록
비디오 인터랙티브 스토리텔링은 시청자가 비디오가 전개되는 방식을 능동적으로 조정할 수 있게 한다. 그러나 생성 과정 중에 시청자가 개입할 수 있게 되면 새로운 문제가 발생한다. 시청자의 요청은 그라운딩 소스와 현재 렌더링된 비디오 상태 모두에 대한 잠재적 의존성을 가질 수 있다. 이러한 의존성은 개별 입력 어디에도 명시적으로 드러나지 않을 수 있으며, 소스와 렌더링 이력, 새로운 시청자 의도를 함께 고려할 때에만 나타난다. 기존의 인터랙티브 비디오 생성 시스템은 주로 시청자 지시를 따르는 데 중점을 두는 반면, 소스에 그라운딩된 비디오 생성 방법은 생성된 콘텐츠를 외부 내러티브나 지식 소스에 정렬하는 데 초점을 맞춘다. 이로 인해 근본적인 질문이 충분히 탐구되지 않았다. 인터랙티브 연속 생성에서 생성 모델이 무엇을 맥락으로 삼아 그라운딩해야 하며, 이질적이고 비정형적인 입력을 어떻게 그러한 그라운딩 맥락으로 변환할 수 있는가? 본 연구에서는 맥락적 그라운딩을 비디오 생성을 위한 실행 가능한 제약 모델로 이질적인 입력 맥락을 변환하는 과정으로 정식화한다. 이 문제를 해결하기 위해 VIS-Ground를 제안한다. VIS-Ground는 구조적 맥락 추상화(Structured Context Abstraction)를 수행하여 그라운딩된 상태와 맥락 간 의존성을 복원하고, 생성 제약 조건 도출(Generation Constraints Induction)을 통해 관련 의존성을 후보별 제약 조건으로 투영하며, 제약 기반 비디오 생성(Constrained Video Generation)을 통해 계획, 검증, 수정, 렌더링 과정으로 이러한 제약 조건을 강제한다. 세 가지 비디오 생성 백본 전반에서 VIS-Ground는 일관되게 가장 높은 전체 종합 점수를 달성했으며, 백본별 가장 강력한 기준 모델 대비 평균 10.3점의 절대 향상을 보였다. 세부 분석은 내러티브 그라운딩과 지식 그라운딩 모두에서 향상이 있었음을 보여주며, 의존성 추출과 비디오 렌더링 중 충실한 실현에서 남아 있는 과제를 드러낸다.
One-sentence Summary
Researchers from Google, the University of Illinois at Urbana-Champaign, and the University of California, Los Angeles introduce VIS-Ground, which performs Structured Context Abstraction, Generation Constraints Induction, and Constrained Video Generation to transform heterogeneous context into executable constraints that jointly handle source, rendered history, and viewer intent, achieving an average absolute improvement of 10.3 points over the strongest per-backbone baselines across three video generation backbones.
Key Contributions
- The paper formalizes contextual grounding as transforming heterogeneous inputs such as the grounding source, video prefix, and viewer request into an executable constraint model for interactive video continuation.
- The paper introduces VIS-Ground, a framework comprising structured context abstraction to recover grounded states and cross-context dependencies, generation constraints induction to derive candidate-specific constraints, and constrained video generation to enforce these constraints through planning, verification, revision, and rendering.
- The paper introduces VIS-Bench, a benchmark for narrative- and knowledge-grounded interactive video storytelling, and experiments across Omni-1.1-Flash, Veo 3.1, and MiniMax-H3 show VIS-Ground achieves the highest composite score, with an average absolute improvement of 10.3 points over the strongest per-backbone baselines.
Introduction
Video storytelling is useful for explaining complex ideas through language, imagery, motion, and sound, but viewers often want to redirect a video after seeing earlier frames, such as by asking for consequences or concrete examples. Prior systems either generate long-form video from a fixed story or script or allow prompt-driven interactive generation, yet they do not explicitly check whether a new viewer request remains compatible with the grounding source and the already rendered video. The authors formulate this as Video Interactive Storytelling with Contextual Grounding and propose VIS-Ground, which performs structured context abstraction, induces generation constraints, and uses an iterative plan-verify-revise-render process to keep continuations source-faithful, story-consistent, and request-aligned. They also introduce VIS-Bench, a benchmark for evaluating these properties across narrative- and knowledge-grounded settings.
Dataset
-
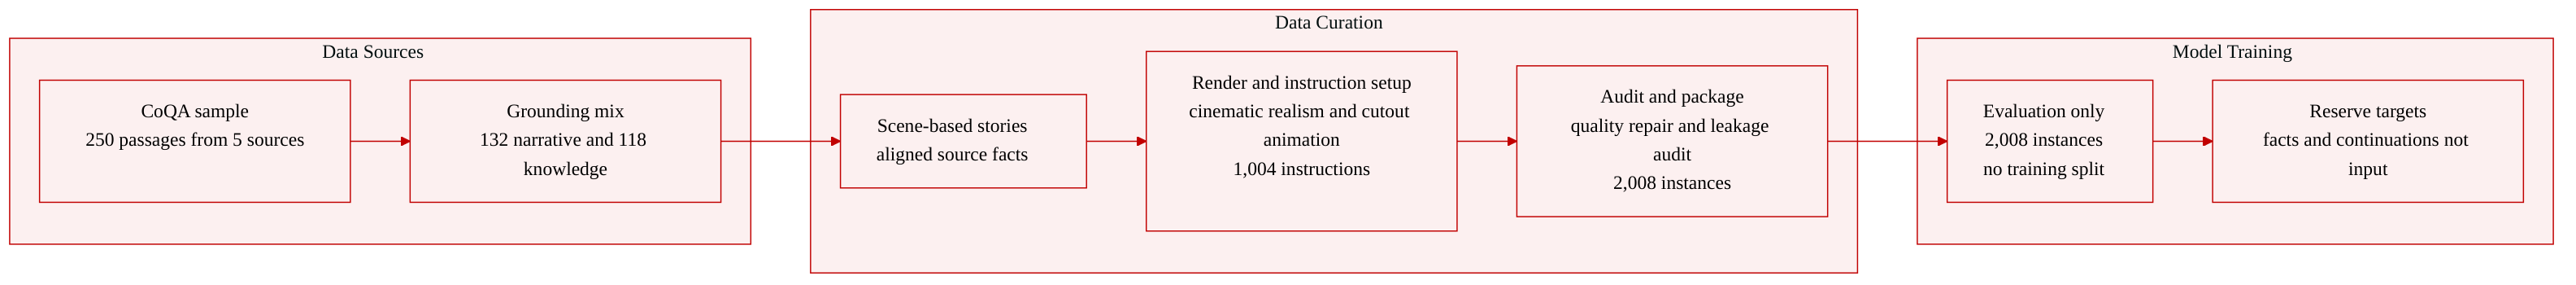
Dataset composition and sources The authors build VIS-Bench from CoQA by sampling 250 source passages from MCTest, Gutenberg, RACE, CNN, and Wikipedia. The benchmark covers two grounding settings: narrative grounding, where a core narrative such as a story outline, script, or plot description guides important characters and events, and knowledge grounding, where an external source such as a scientific paper, Wikipedia article, or document must be faithfully communicated. Of the sampled sources, 132 are narrative-grounded and 118 are knowledge-grounded.
-
Key details for each subset Each source passage is converted into a scene-based story with aligned source facts. The resulting stories are rendered in two visual styles: cinematic realism and cutout animation. The authors generate 1,004 interaction instructions at designated interruption points, producing 2,008 planned instruction-style instances. All instances are assigned to evaluation, so no training split is used.
-
How the paper uses the data VIS-Bench is used strictly for evaluation. Each sample includes the source passage, video prefix, viewer instruction, and relevant reference assets. Target facts and continuation requirements are reserved for evaluation rather than included as input.
-
Processing details Generated videos undergo quality checks and repair. Instruction alignment and information leakage are audited before packaging. The final packaged samples include the source passage, video prefix, viewer instruction, and relevant reference assets.
Method
The authors introduce VIS-Ground, a framework for video interactive storytelling that treats contextual grounding as a context compilation problem. The main idea is to compile heterogeneous inputs into a grounded dependency model and use that model to control subsequent planning, generation, and repair.
The overall pipeline is illustrated below:
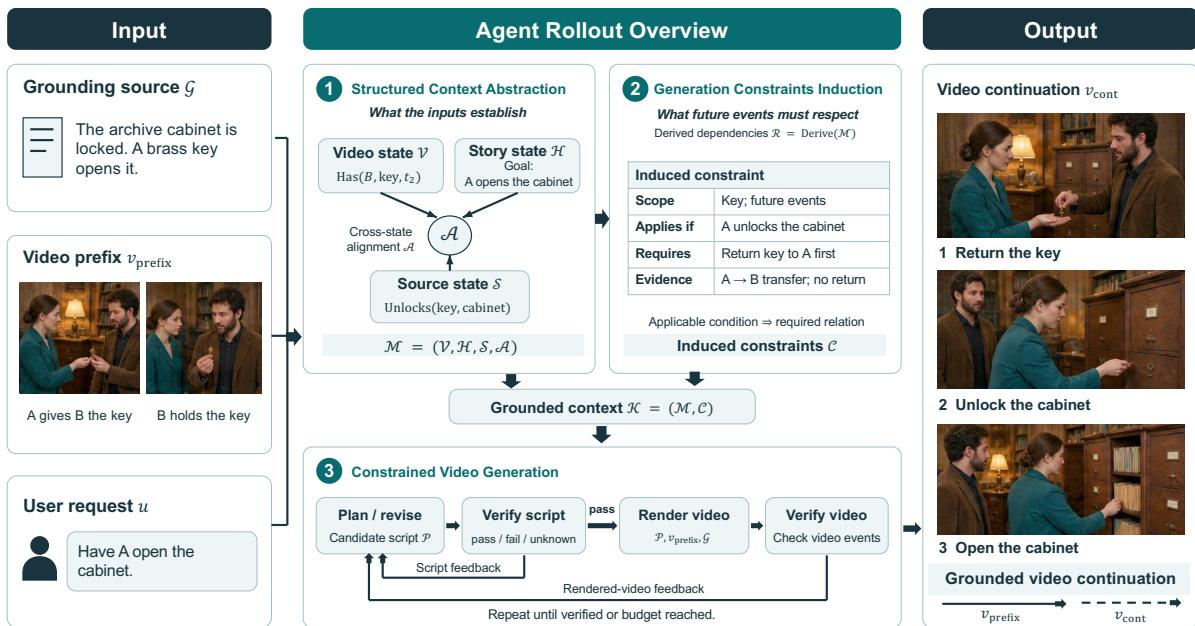
VIS-Ground proceeds in three stages. First, the grounding source, rendered video prefix, and viewer request are converted into grounded facts and cross-context dependencies. Second, these dependencies are projected onto a candidate continuation, where only the relations made relevant by the proposed future become generation constraints. Third, the activated constraints guide planning, script repair, rendering, and output-level correction.
Compiling Context into Grounded Dependencies
The grounding source, video prefix, and viewer request provide different views of an evolving situation. The source may establish factual or narrative relations, the rendered prefix determines the currently visible state, and the viewer request specifies how the story should continue. Instead of summarizing each input independently, VIS-Ground extracts structured grounded facts and recovers dependencies that emerge from their interaction.
The framework first transforms each input into typed predicates with arguments, temporal scopes, and evidence links. These predicates are organized into three complementary states:
- Video state V represents what has been visually established in the rendered prefix, including entities, attributes, locations, possession, actions, and state transitions.
- Story state H represents the evolving narrative state, including completed events, active goals, unresolved relations, causal dependencies, and information already conveyed.
- Source state S represents atomic claims, events, definitions, and relations supported by the grounding source, while preserving qualifications, conditions, and supporting evidence.
The aligned states are compiled into a grounded dependency model
M=(V,H,S,A),where A contains cross-context alignments. From this aligned model, the method derives a dependency set
R=Derive(M).Each dependency expresses how one established fact constrains another event or state. These dependencies include temporal precedence, causal prerequisites, state-transition requirements, persistence relations, compatibility conditions, and source-supported dependencies. Many of these relations are not explicitly stated in any individual input. They emerge only after the video state, story state, and source state are jointly grounded.
Projecting Dependencies into Generation Constraints
VIS-Ground induces constraints from the derived dependency set R. The method does not directly optimize final-video evaluation metrics, and those metrics are not used as predefined categories for constraint induction.
Let P(k) denote a candidate continuation script. For each dependency, the framework determines whether the candidate introduces an event, relation, or state transition for which that dependency becomes relevant. An activated dependency is represented as a generation constraint
cj=(sj,aj,bj,ej),where sj specifies the entity and temporal scope, aj is an applicability condition, bj is the relation that must hold, and ej contains the grounded evidence supporting the dependency. The constraint is activated when
aj(P(k),M)=1,and once activated it requires
bj(P(k),M)to hold within scope sj.
This formulation makes constraints candidate-conditioned. For example, a possession dependency need not constrain a continuation unless the proposed script introduces an action that requires a particular character to possess a corresponding object. Similarly, a source-defined prerequisite is activated only when the candidate attempts an event whose validity depends on that prerequisite.
Each activated constraint is evaluated and returns one of three outcomes: pass, fail, or unknown. A pass means the continuation is compatible with the dependency. A fail identifies a conflicting event, state transition, or missing prerequisite. An unknown indicates that the available evidence is insufficient to determine compatibility. Because every constraint retains links to its supporting predicates and evidence, failures can be traced back to the contextual dependency that caused them and used to generate targeted revision feedback.
Constrained Video Generation
The grounded dependency model remains active throughout generation. It is not used merely as additional conditioning for the video generator. Instead, it provides a common basis for proposing, checking, and repairing the continuation.
The planner first proposes a candidate script conditioned on the grounded context:
P(0)∼pθ(P∣M,u).The dependencies activated by P(0) are then instantiated as constraints and evaluated. When a constraint fails, VIS-Ground identifies both the conflicting portion of the script and the grounded dependency that it violates. This produces targeted feedback for revision rather than regenerating the continuation from scratch.
The revised script is generated as
P(k+1)=Reviseθ(P(k),M,F(k)),where F(k) contains the failed or unresolved dependencies and their supporting evidence. Because revision may introduce new events or state transitions, constraint activation is recomputed after each update. Planning and verification therefore form an iterative dependency-guided repair process in which the relevant obligations evolve together with the candidate continuation.
Once a candidate script P∗ satisfies the activated script-level constraints, it is passed to the video generator:
νcont∼pψ(νcont∣P∗,νprefix,G).Script-level validity, however, does not guarantee that the rendered video realizes the intended events or state transitions. The framework therefore extracts the realized relations from νcont and projects the same grounded dependencies onto the generated output. If the video fails to realize an activated dependency, such as an omitted object transfer, an incorrectly changed persistent attribute, or a visually absent prerequisite event, the corresponding evidence is converted into output-level feedback. The planner then repairs the script or makes the missing dependency more explicit before rendering again.
In this way, VIS-Ground uses a single grounded dependency model across both reasoning and generation. Context is first compiled into dependencies, dependencies are instantiated as constraints only when a proposed future makes them relevant, and violations are used to repair either the planned continuation or its rendered realization. The process terminates when the generated continuation satisfies the applicable grounded dependencies or the computation budget is exhausted.
Experiment
The paper introduces VIS-Bench, a benchmark for video interactive storytelling with narrative and knowledge grounding, and evaluates generated continuations on semantic and perceptual dimensions using automated judges across three video backbones. Results show that the proposed VIS-Ground approach improves contextual grounding over direct generation and agent-based baselines in both grounding settings and across backbones, while visual quality remains largely bounded by the underlying generator. Ablations indicate that structured state representations and instance-specific planning play complementary roles, and failure analysis shows the method sometimes prioritizes consistency with prior context over literal instruction following.
VIS-Ground achieves the highest composite score with every tested video-generation backbone, with the clearest gains concentrated in grounding-related metrics such as source faithfulness, story continuity, interaction fulfillment, and joint constraint satisfaction. These advantages appear in both narrative and knowledge grounding settings and average roughly ten percentage points over the strongest competing result. The method also shows much lower cross-backbone composite variation than Direct Generation, while not being uniformly best on every individual visual or interaction metric. Across grounding-related metrics, VIS-Ground improves over the strongest competing result by roughly 10 percentage points on average across backbones and settings. The composite score of Direct Generation spans more than 30 points across the three backbones, while VIS-Ground spans below 6 points, an approximate 82% reduction in cross-backbone variation. VIS-Ground is not best on every individual metric; some interaction fulfillment, visual consistency, and video quality comparisons favor other methods. Ablations show that replacing structured context with a free-form summary or using one-pass planning lowers the mean of narrative source faithfulness, story continuity, and interaction fulfillment.
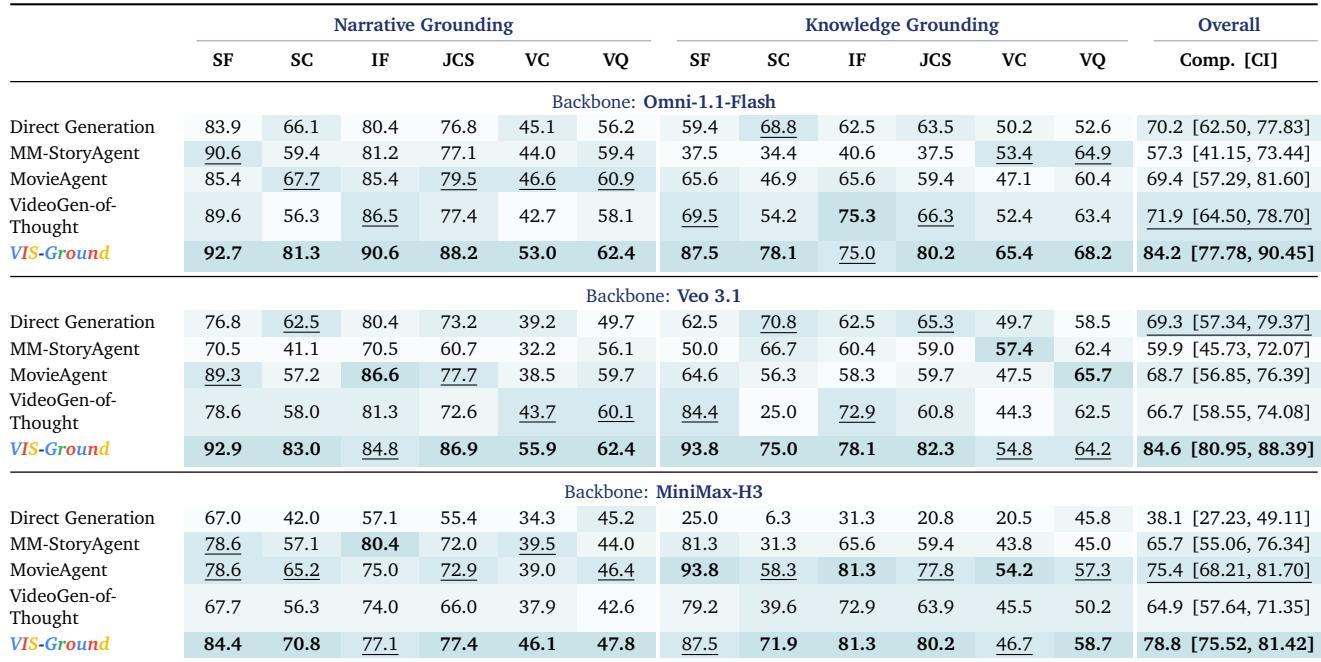
VIS-Ground was evaluated across multiple video-generation backbones in both narrative and knowledge grounding settings, where it consistently achieved the highest composite score with the largest gains on grounding-related measures such as source faithfulness, story continuity, interaction fulfillment, and joint constraint satisfaction. It also reduced cross-backbone composite variation by roughly 82 percent compared to Direct Generation, indicating much more stable behavior across backbones, though it was not uniformly best on every individual visual or interaction metric. Ablations further show that replacing structured context with a free-form summary or using one-pass planning weakens narrative source faithfulness, story continuity, and interaction fulfillment.