Command Palette
Search for a command to run...
VisionWeave: MLLM의 네이티브 능력으로서 탄력적 시각 표현 직조
VisionWeave: MLLM의 네이티브 능력으로서 탄력적 시각 표현 직조
초록
멀티모달 대규모 언어 모델은 시각 이해의 지배적 패러다임이 되었지만, 입력을 조밀한 고정 크기 패치 토큰으로 인코딩함으로써 상당한 비용을 초래한다. 그러나 시각 정보는 불균등하게 분포되어 있다. 일부 영역은 세밀한 디테일을 요구하는 반면, 다른 영역은 압축된 표현으로 충분하다. 다운샘플링은 이러한 세부 정보를 희생하며, 기존 토큰 가지치기 및 적응형 접근법은 콘텐츠 적응적 세분성, 과제 일반화, 최신 MLLM 및 서빙 인프라와의 통합 측면에서 여전히 한계를 지닌다. 이러한 한계를 극복하려면 파운데이션 모델이 시각 표현을 어디에, 그리고 어떤 세분성으로 할당할지를 종단 간(end-to-end) 학습해야 하며, 우리는 이 네이티브 능력을 탄력적 시각 표현 직조(elastic visual representation weaving)라고 부른다. 우리는 VisionWeave를 제안하고, 대규모 학습을 통해 프런티어 수준 MLLM에서 이 능력을 확립한다. 이는 두 가지 구성 요소를 결합한다. 게이트형 공간 풀러(gated spatial pooler)는 공유 MRoPE 좌표 안에서 네이티브 세밀 표현과 함께 거친(coarse-grained) 표현을 구성하고, 세분성 라우터(granularity router)는 콘텐츠 적응형 할당을 학습한다. 자기 증류(self-distillation)만으로 Qwen3.5-4B에서 이 능력을 검증하고, 3만 A100 GPU 시간 이상을 사용하여 Qwen3.8-27B로 확장한다. Qwen3.8-27B를 기반으로 Vision-Weave는 토큰 절약을 시각 콘텐츠에 맞게 적응적으로 조정하여, 8개 벤치마크에서 평균 43.0%의 토큰을 절약하면서 네이티브 성능의 98.9%를 유지한다. 반면, 50% 고정 절약 목표를 적용한 토큰 가지치기 기준은 네이티브 성능의 88%만을 보존한다. 다양한 과제, 해상도, 비디오 프레임에 걸친 광범위한 평가는 견고한 효율성-품질 트레이드오프를 확인해 준다. SGLang 서빙 엔진에 배포했을 때, 우리 방법은 종단 간 처리량을 2.30배 향상시키고 평균 TTFT를 54.4%, 평균 TPOT를 60.6% 감소시켰다. 이러한 결과를 종합하면, 탄력적 시각 표현 직조가 정보 내용에 따라 계산 노력을 네이티브하게 조절하는 차세대 멀티모달 파운데이션 모델의 유망한 능력으로 자리매김한다고 우리는 믿는다. SGLang 코드 및 기타 세부 사항은 https://github.com/FFY0/VisionWeave에서 제공될 예정이다.
One-sentence Summary
Researchers at the University of Science and Technology of China, Alibaba Token Hub, and other affiliated institutions introduce VisionWeave, which learns elastic visual representation weaving as a native MLLM capability through a gated spatial pooler and a granularity router trained by self-distillation, achieving 43.0% token savings while retaining 98.9% native performance on Qwen3.8-27B and a 2.30× end-to-end throughput gain on the SGLang serving engine.
Key Contributions
- VisionWeave establishes elastic visual representation weaving as a native MLLM capability by combining a gated spatial pooler for coarse-grained representations with a granularity router for content-adaptive allocation within a shared MRoPE coordinate.
- The method learns adaptive visual token allocation end to end through self-distillation alone, validating on Qwen3.5-4B and scaling to Qwen3.8-27B with over 30K A100 GPU-hours.
- On Qwen3.8-27B, VisionWeave saves 43.0% of visual tokens on average while retaining 98.9% native performance across eight benchmarks, and in SGLang serving it achieves a 2.30× end-to-end throughput gain, with mean TTFT reduced by 54.4% and mean TPOT by 60.6%.
Introduction
Multimodal large language models (MLLMs) are now the dominant approach for visual understanding tasks, but processing high-resolution images and long video sequences generates very long visual token sequences that increase computational and memory costs. Prior work on visual downsampling sacrifices fine-grained detail, while visual token pruning and merging methods often suffer from training-inference mismatch, lose task-specific information, degrade on information-dense or grounding tasks, and are difficult to integrate with modern serving engines such as SGLang and vLLM. Existing content-adaptive methods such as ViCO use tile-level resolution assignment, which is too coarse for interleaved detail-rich and low-information regions and is not aligned with native-resolution MLLM architectures like Qwen and Kimi. The authors introduce VisionWeave, a method that enables MLLMs to natively use elastic visual representations by adaptively weaving fine-grained and learned coarse-grained tokens through a gated spatial pooler and a granularity router. Trained via self-distillation on Qwen3.5-4B and scaled to Qwen3.8-27B, VisionWeave achieves content-adaptive token savings while preserving near-native performance and translates these savings into about 2x serving throughput in SGLang.
Method
The authors realize elastic visual representation weaving through two complementary components: a gated spatial pooler and a granularity router, which together enable native elastic visual processing in multimodal large language models.
The gated spatial pooler constructs learned coarse-grained representations that complement native fine-grained tokens. It maps each 2×2 neighborhood of Vision Transformer (ViT) patch features to a single pooled feature. For each neighborhood, the four patch features are normalized using learnable layer normalization and aggregated into a shared global context. A gating mechanism then computes channel-wise scores from the patch feature and its context, followed by a value network that refines each feature. The final pooled output is the gated sum of these refined features. This design offers a favorable starting point, as zero-initializing the final layers reduces the pooler to mean pooling over normalized patch features.
To determine the granularity for each spatial block, the granularity router probes intermediate ViT features at multiple depths. It employs a learnable query state for each spatial block, initialized from a shared learnable vector. Each query sequentially probes specific depths of the ViT, utilizing a local cross-attention block to attend to the spatial block's own patch features, followed by a global cross-attention block to incorporate information from the entire frame. Both attention mechanisms use residual connections and layer normalization. Finally, a linear head maps the normalized query state to logits, yielding the probability of using the coarse-grained representation. During inference, if this probability exceeds a threshold, the coarse-grained token is used; otherwise, the native fine-grained tokens are retained.
The authors develop this elastic visual weaving capability through a three-stage self-distillation process. In the first stage, coarse-grained self-distillation, the pooler is trained with routing bypassed, using the coarse-grained representation for every block. The native forward pass of the model serves as the teacher, providing output-distribution supervision via a Kullback-Leibler divergence objective.
In the second stage, soft-mixing self-distillation, the granularity router is trained using a differentiable soft-mixing surrogate for hard routing. The authors interpolate feature directions and magnitudes separately to prevent norm differences from biasing the mixture. A per-sample balance loss is added to encourage a target coarse-routing fraction, preventing larger inputs from dominating the estimate.
The third stage performs mixed-granularity self-distillation on the hard-routed mixed-granularity sequences used at inference. The router head includes an offline-calibrated scalar coarse-routing bias, and the student gathers visual tokens using the same selection and positional embedding coordinates as during inference.
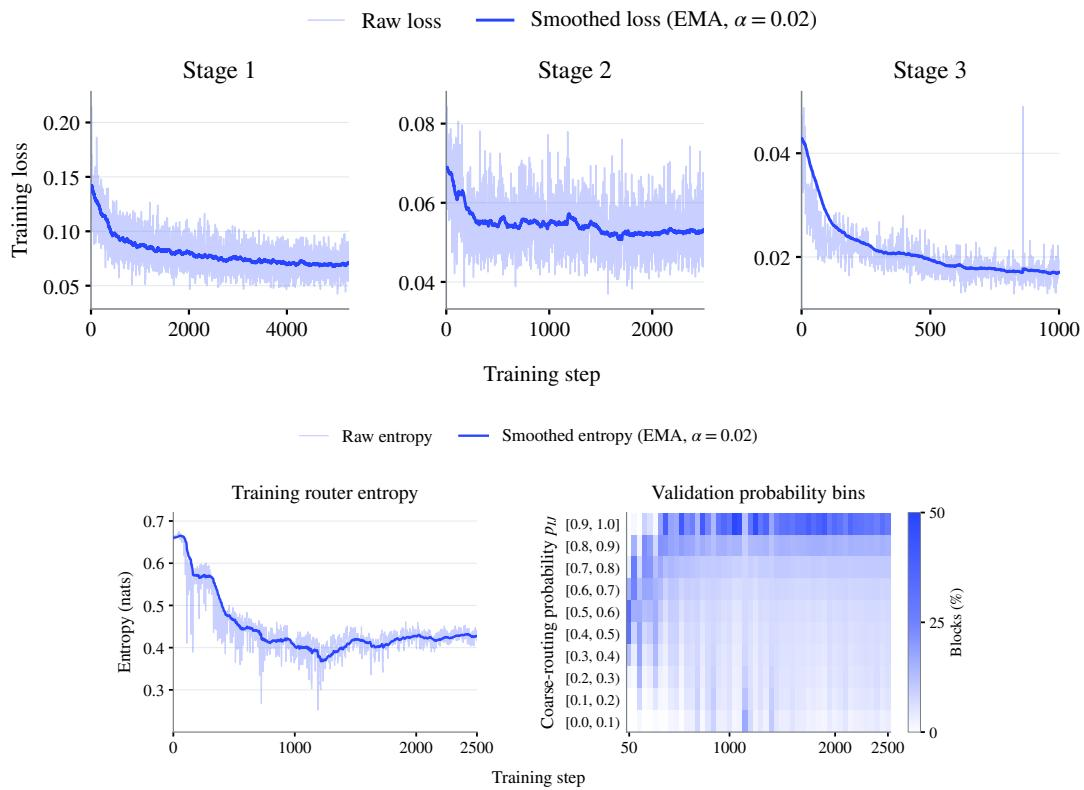
The training dynamics of this three-stage process reveal how granularity decisions develop over time. As shown in the figure below, the training losses steadily decrease across all three stages. During the soft-mixing stage, the mean router entropy falls significantly, indicating increasingly decisive allocation. Furthermore, the validation probability distributions show a clear shift, with the share of blocks having high coarse-routing probability reaching substantial levels, demonstrating the model's ability to learn content-adaptive granularity allocation effectively.
Experiment
The evaluation validates VisionWeave on two open-source Qwen MLLMs across eight benchmarks spanning natural images, documents, GUI grounding, hallucination, and video understanding, comparing against heuristic token merging and pruning baselines and using SGLang for serving tests. VisionWeave maintains near-native quality through content-adaptive token savings and shows stable efficiency-quality tradeoffs across spatial resolutions and video frame budgets, unlike fixed-saving baselines that degrade sharply on grounding and information-dense tasks. Serving experiments demonstrate higher end-to-end throughput and lower latency, while inference-time thresholding allows quality-cost control without retraining. Ablations confirm the gated spatial pooler and learned granularity allocation matter, and visual analysis shows the approach preserves spatial coverage rather than dropping task-critical tokens.
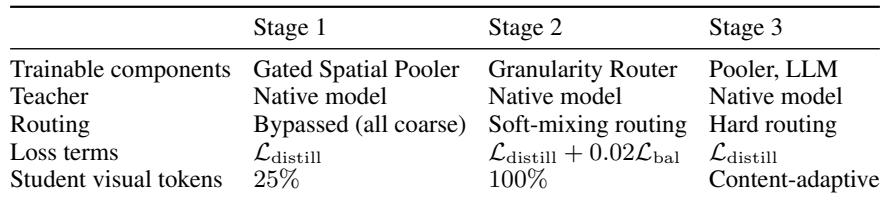
Elastic visual processing is trained in three stages: first a gated spatial pooler learns coarse representations with all routing bypassed, then a granularity router is trained with soft-mixing and a balance loss, and finally the pooler and LLM are trained with hard content-adaptive routing. This curriculum moves student visual tokens from a fixed 25% through full tokens to content-adaptive allocation. Ablations show the learned pooler outperforms a pixel-unshuffle projector at high token savings, and shuffling routing scores reduces performance, indicating that content-dependent granularity allocation is important. The three-stage procedure moves from coarse-only pooling to soft-mixed routing and finally hard content-adaptive routing with trainable pooler, router, and LLM components. Ablations show the gated spatial pooler outperforms a pixel-unshuffle projector at high token savings, and shuffling learned routing scores reduces performance, indicating content-dependent allocation matters.
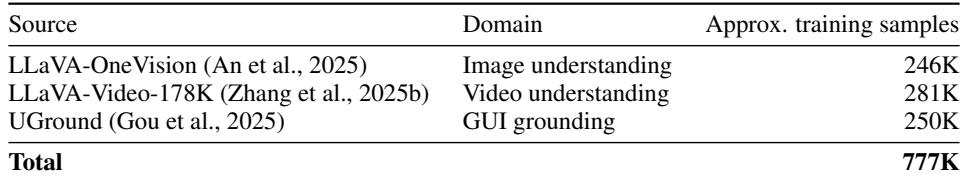
The training mixture for Qwen3.8-27B contains about 0.78 million samples spanning image understanding, video understanding, and GUI grounding. The three domain contributions are nearly balanced, with video understanding as the largest source and image understanding as the smallest. All three training stages use this same mixture before sequence packing. Image understanding, video understanding, and GUI grounding each account for roughly one third of the total training samples. Video understanding contributes the largest share, while image understanding contributes the smallest. The same data composition is shared across all three training stages.
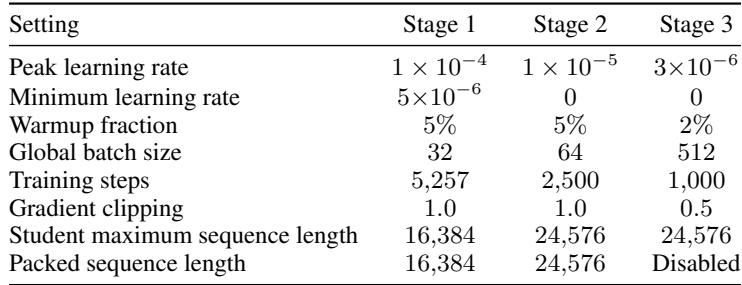
Qwen3.8-27B training moves through three stages with progressively lower peak learning rates, zero minimum learning rates after the first stage, and larger global batch sizes. The first stage uses the most training steps and a shorter student maximum sequence length, while later stages use longer sequences and fewer steps. Later stages use lower peak learning rates and zero minimum learning rates, indicating more conservative optimization. The global batch size increases across stages while training steps decrease, shifting from many small-batch updates to fewer large-batch updates.
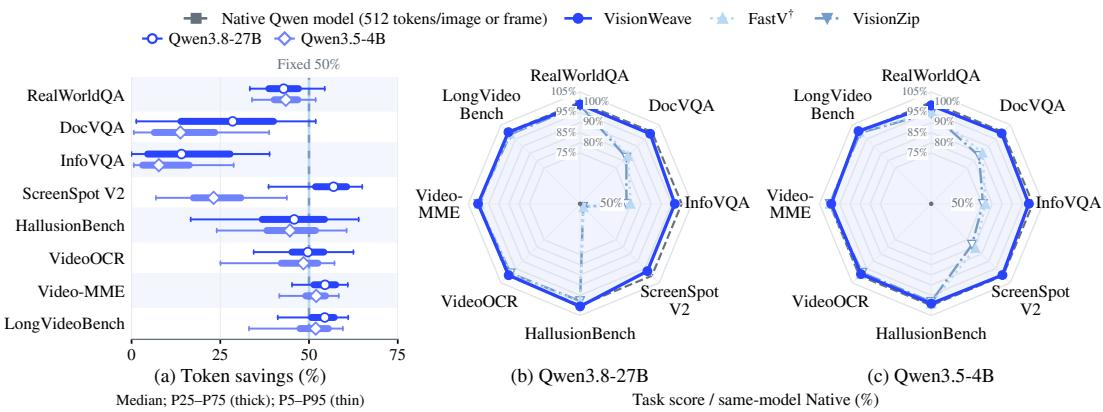
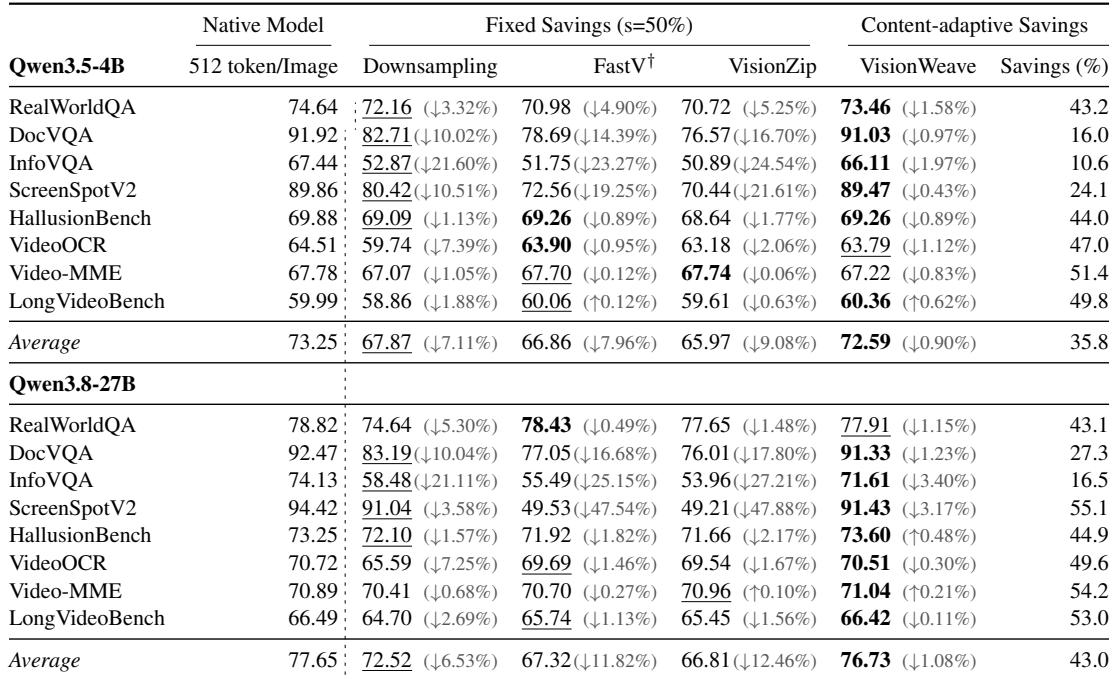
VisionWeave provides content-adaptive token savings while keeping quality close to native models. Document and grounding tasks receive more conservative savings with only small accuracy drops, while video tasks allow much higher savings with minimal loss. Fixed-savings baselines degrade more sharply on information-dense and grounding benchmarks even when matched for dataset-level savings. VisionWeave limits average performance loss to roughly one percent across benchmarks on both model scales. Token savings are content-adaptive, with much higher reduction on video benchmarks and more conservative reduction on document and grounding tasks. FastV and VisionZip show sharp drops on ScreenSpotV2 and DocVQA, while VisionWeave preserves quality by adapting token allocation to input demands.
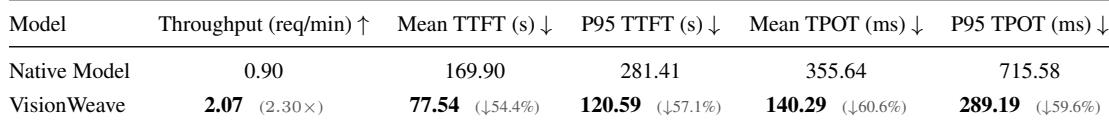
Under the long-video serving workload, VisionWeave more than doubles throughput relative to the native model while reducing latency across mean and tail metrics. The improvements are especially strong for per-token generation time, and tail latency also falls substantially, indicating higher serving capacity and better responsiveness. VisionWeave delivers a 2.30x end-to-end throughput speedup over the native model on the same two-GPU serving setup. P95 time to first token falls by 57.1%, and P95 time per output token falls by 59.6%. Mean TTFT and mean TPOT also drop by over half, with mean TPOT improving by 60.6%.
The experiments evaluate VisionWeave's three-stage training procedure, which progresses from coarse pooling through soft-mixed routing to hard content-adaptive routing, with ablations showing that learned content-dependent token allocation outperforms fixed projectors and shuffled routing baselines. They further document a balanced multimodal training mixture spanning image, video, and GUI grounding, and a progressive optimization schedule with lower learning rates and larger batches in later stages. Benchmark results indicate that content-adaptive token savings preserve quality across document, grounding, and video tasks, while fixed-savings baselines degrade more sharply on information-dense inputs. Serving evaluations also show substantial throughput and latency improvements for long-video workloads.