Command Palette
Search for a command to run...
TRACE: MoE 언어 모델의 FP4 강화학습을 위한 롤아웃 유도 양자화 인지 학습
TRACE: MoE 언어 모델의 FP4 강화학습을 위한 롤아웃 유도 양자화 인지 학습
초록
대규모 언어 모델(LLM)의 사후 훈련을 위한 강화학습(RL)은 롤아웃 생성 중 상당한 계산 및 메모리 오버헤드를 유발하며, 이는 효율적인 RL 훈련을 위한 저정밀 롤아웃의 동기가 된다. 그러나 기존 FP4 RL 방법들은 핵심적인 한계를 가진다. 즉, 두 양자화 실행 경로 간의 불일치를 직접 줄이기보다는 훈련 경로와 롤아웃 경로 각각에서 양자화 정확도를 독립적으로 최적화한다는 점이다. 본 연구에서는 기존 FP4 RL 방법들의 한계를 해결하는 전문가 혼합(MoE) 언어 모델의 RL 훈련을 위한 FP4 양자화 프레임워크인 TRACE(Train-Rollout Quantization Alignment via Compact GuidancE)를 제안한다. TRACE는 롤아웃 측 양자화 결과를 활용하여 훈련 측 FP4 반올림 결정을 안내함으로써 훈련-롤아웃 불일치를 직접 줄이는 롤아웃 유도 양자화 인지 학습을 포함한다. 또한 TRACE는 롤아웃 유도로 인해 발생하는 저장 및 통신 오버헤드를 줄이기 위해 심층 레이어에서 가수(mantissa)와 스케일 정보를 선택적으로 유지하는 효율적인 양자화 정보 캐싱 기법을 채택한다. 우리는 추론, 코딩 및 장기 지평 RL 작업 전반에 걸쳐 네 개의 대규모 MoE 언어 모델에서 TRACE를 평가한다. 실험 결과, TRACE는 FP4 가중치/활성화 및 FP4 KV-캐시를 동시에 사용하는 롤아웃을 가능하게 하여 BF16 롤아웃에 필적하는 RL 성능을 제공하면서, BF16으로 훈련된 정책의 사후 FP4 양자화와 비교하여 최대 5.4배의 롤아웃 속도 향상과 우수한 최종 FP4 성능을 달성한다.
One-sentence Summary
Researchers at Alibaba Token Hub, Alibaba Group, and Ohio State University propose TRACE, an FP4 quantization framework for RL training of Mixture-of-Experts language models that uses rollout-guided quantization-aware training to align train-rollout rounding decisions and selectively caches deeper-layer mantissa and scale information, enabling joint FP4 weight/activation and FP4 KV-cache rollout with up to 5.4× speedup and BF16-comparable RL performance.
Key Contributions
- TRACE is an FP4 quantization framework for RL training of Mixture-of-Experts language models that uses rollout-side quantization outcomes to guide training-side FP4 rounding decisions, directly reducing train-rollout discrepancy instead of independently optimizing quantization accuracy on each path.
- TRACE incorporates a quantization-information caching scheme that selectively retains mantissa and scale information from deeper layers, reducing the storage and communication overhead caused by rollout guidance.
- Evaluation on four large-scale MoE language models (Qwen3.5-35B-A3B, Qwen3.5-122B-A10B, Qwen3.8-Flash-Next, Qwen3.8-2.4T-A95B) across reasoning, coding, and long-horizon RL tasks shows that TRACE supports joint FP4 weight/activation and FP4 KV-cache rollout with performance comparable to BF16 rollout, achieves up to 5.4× rollout speedup over BF16 rollout, and delivers stronger final FP4 performance than post-hoc FP4 quantization of BF16-trained policies.
Introduction
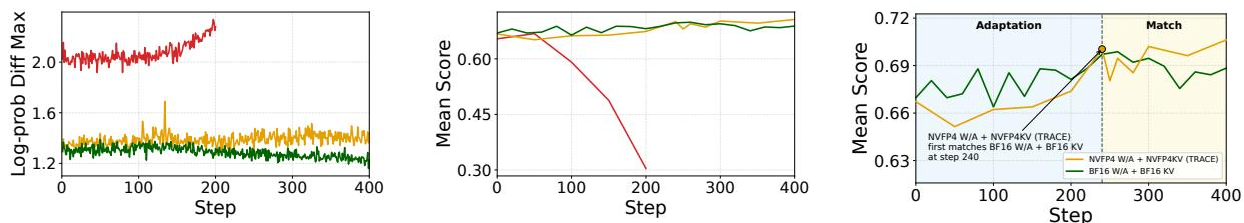
Reinforcement learning has become a key post-training approach for improving reasoning and coding in large language models, but rollout generation is computationally expensive. Aggressive FP4 quantization can reduce rollout cost, yet its coarse numerical space creates a train-rollout policy mismatch, which is especially problematic for Mixture-of-Experts models where small differences can shift expert routing and destabilize training. Existing FP4 RL methods mainly improve quantization accuracy on each path independently, but this does not directly reduce the discrepancy between the quantized train and rollout paths. The authors propose TRACE, an FP4 quantization framework for MoE RL training that uses rollout-side quantization outcomes to guide training-side FP4 rounding and caches only selected deeper-layer mantissa and scale information to limit storage and communication overhead.
Method
The authors propose TRACE, an FP4 quantization framework designed for efficient reinforcement learning (RL) training of Mixture-of-Experts (MoE) language models. The core objective of TRACE is to directly align the quantized computation paths utilized during rollout generation and the subsequent training phase.
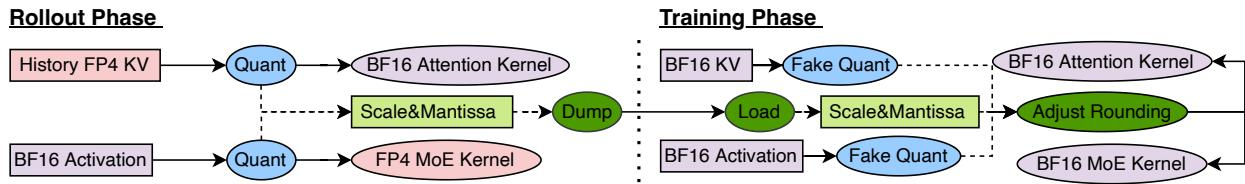
At a high level, the framework operates in two distinct phases. During the rollout generation phase, TRACE records the quantization outcomes of FP4 routed expert activations and FP4 Key-Value (KV) states. In the following quantization-aware training (QAT) phase, this recorded rollout-side information is leveraged to guide the corresponding training-side rounding decisions. To mitigate the substantial overhead associated with transferring this guidance information, TRACE incorporates an efficient quantization-information caching scheme that retains only the mantissa and scale information from selected deeper layers.
Rollout-Guided Quantization-Aware Training
Low-precision rollout introduces numerical discrepancies between the training and rollout execution paths. Simply combining standard FP4 QAT, where fake quantization is applied during the forward pass while the backward pass remains in BF16, with FP4 rollout generation can lead to significant policy divergence. The authors characterize the local train-rollout discrepancy for paired activations as:
Dact=QFP4train(Xtrain)−QFP4rollout(Xrollout)FExisting methods often attempt to mitigate this discrepancy indirectly by improving the quantization accuracy of each path independently relative to high-precision representations. However, minimizing per-path quantization error does not necessarily minimize the cross-path discrepancy.
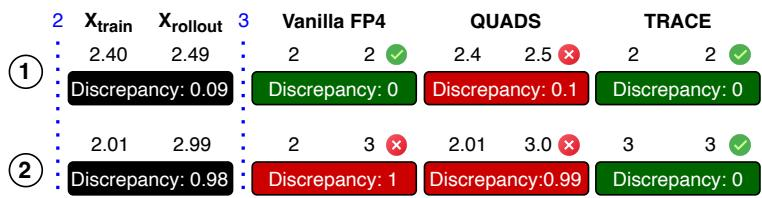
As illustrated in the examples above, methods like QUADS reduce per-path quantization error but can actually increase the train-rollout discrepancy. For instance, in the first example, QUADS reconstructs the rollout activation to reduce its own error, but this increases the discrepancy between the training and rollout values from 0 to 0.1.
The primary source of this discrepancy is that small differences between BF16 training and rollout activations can be substantially amplified when rounded to different FP4 codewords.
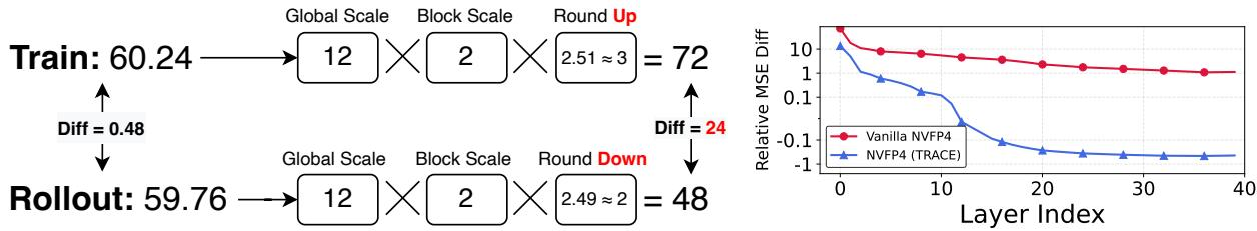
The figure on the left demonstrates how an original difference of 0.48 in BF16 (60.24 vs 59.76) is amplified to a difference of 24 after FP4 quantization (72 vs 48) because the normalized values fall on opposite sides of a rounding boundary. The chart on the right further quantifies this, showing that vanilla NVFP4 introduces substantial additional discrepancy across model layers compared to the proposed method.
To address this, TRACE uses the rollout-side quantization outcome to guide training-side rounding. For a captured training-side activation, let {q−,q+} denote its two neighboring normalized FP4 codewords under the rollout-side scale, and let qrollout denote the exact FP4 codeword produced by the corresponding rollout-side activation. Instead of applying standard round-to-nearest (RTN), TRACE selects:
qTRACE=argq∈{q−,q+}min∣q−qrollout∣By construction, this ensures that ∣qTRACE−qrollout∣≤∣qRTN−qrollout∣, effectively reducing unnecessary amplification caused by inconsistent FP4 rounding without increasing local quantized discrepancy.
Mantissa-Only Train-Rollout Communication
While rollout-guided QAT effectively reduces discrepancy, preserving complete rollout-side quantization information introduces massive data-movement overhead.
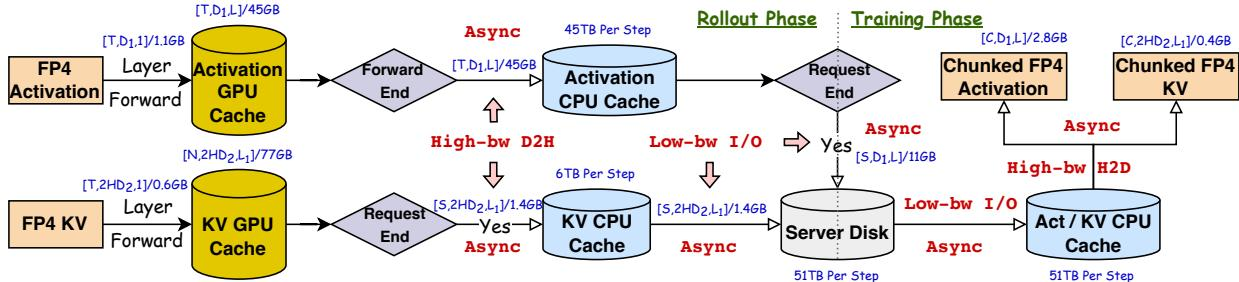
The diagram illustrates the data communication pipeline. Activation-side and KV-side quantization records follow different collection paths. Activation guidance is written to a temporary GPU buffer and asynchronously offloaded, while KV states are gathered from the persistent cache. For a model like Qwen3.5-35B-A3B, a single RL step with 4,096 trajectories can generate up to 51 TB of rollout-side quantization information. Transferring and storing this volume of data creates a severe bottleneck, far exceeding the wall-clock time of a typical RL step.
To resolve this, TRACE communicates only the rollout-side quantization information necessary to determine the desired training-side rounding direction.
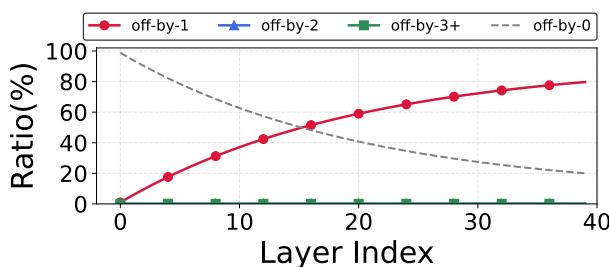
The authors observe that for over 99% of mismatched quantized values across layers, the training and rollout results differ by only one adjacent FP4 codebook entry (off-by-1). Because the quantized values are overwhelmingly adjacent in the FP4 codebook, the training-side activation combined with the rollout scale strongly constrains the candidate codewords. Consequently, communicating the complete quantized value is unnecessary.
TRACE further observes that rounding corrections toward lower FP4 codewords occur predominantly in deeper layers. Based on this, the framework communicates only the mantissa and scale information from the latter half of the model layers. During rollout generation, this compact information is cached and transferred to the training engine to reconstruct a compact rollout-side reference, substantially reducing storage and communication overhead while preserving alignment effectiveness.
Experiment
The experiments evaluate TRACE, a rollout-guided quantization method that jointly applies FP4 weight and KV-cache quantization during RL rollout for MoE language models, comparing it with QAT, QaRL, QUADS, score centering, MXFP4, and post-training quantization baselines across reasoning, coding, and long-horizon tasks on several Qwen models. TRACE consistently matches BF16 rollout performance and outperforms baselines by reducing train-rollout discrepancy, which stabilizes RL training and lets policies adapt to low-precision execution. Efficiency and ablation studies show that this benefit comes with limited throughput and training overhead, extends to microscaling FP4 formats, and requires only compact quantization metadata from deeper layers; further comparisons confirm TRACE is more effective than score centering and post-hoc FP4 quantization.
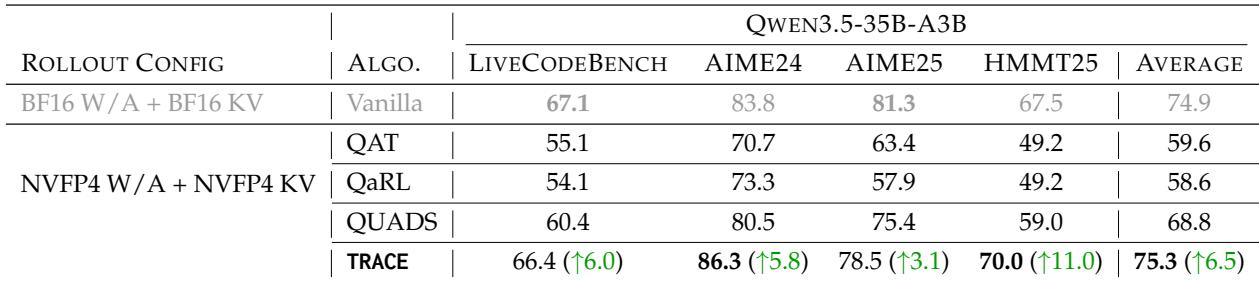
Under joint NVFP4 weight, activation, and KV cache rollout on Qwen3.5-35B-A3B, TRACE outperforms QAT, QaRL, and QUADS across all four reasoning benchmarks. It raises the average score above the best FP4 baseline and matches BF16 rollout performance, with particularly large gains on HMMT25. The results indicate TRACE recovers much of the degradation caused by FP4 quantization. TRACE is the only FP4 method to match the BF16 rollout average on these reasoning tasks. The largest improvement over the strongest baseline appears on HMMT25, where TRACE gains roughly 11 points. Compared with QAT, QaRL, and QUADS, TRACE achieves the highest average performance across all evaluated benchmarks.
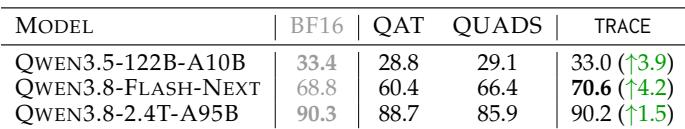
Across the three larger-scale MoE models, TRACE consistently outperforms QAT and QUADS under the same FP4 rollout configuration. It reaches BF16-level performance on the coding and long-horizon benchmarks, with the largest gains on coding tasks and a smaller positive gain on the long-horizon model. TRACE closes most of the gap to BF16 across all three models and scores slightly above BF16 on Qwen3.8-Flash-Next. On the coding-oriented models, TRACE improves over the strongest FP4 baseline by roughly 4 points, while the long-horizon task shows a smaller gain. QUADS underperforms QAT on the long-horizon model, while TRACE still exceeds both low-precision baselines.
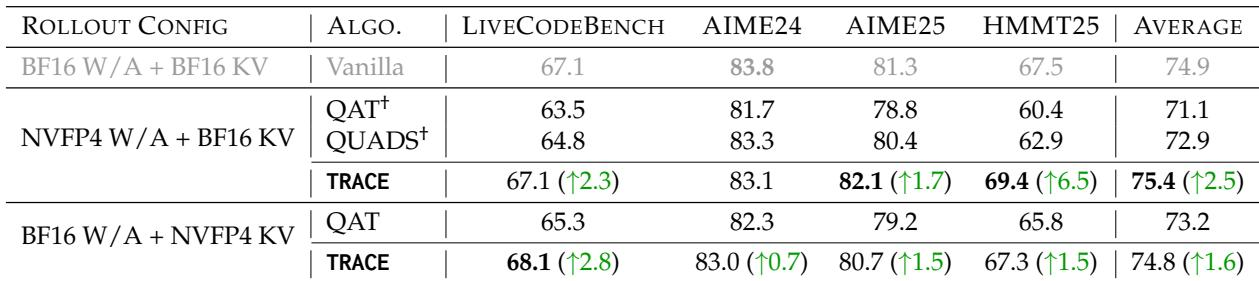
Isolated NVFP4 weight quantization with BF16 KV cache reduces average reasoning benchmark performance for QAT and QUADS baselines, while TRACE recovers the loss and slightly exceeds the BF16 baseline. Isolated NVFP4 KV cache quantization with BF16 weights also lowers the QAT baseline, but TRACE nearly closes the gap to full BF16 rollout. The largest recovery occurs on HMMT25 for weight-only quantization. Under NVFP4 weights with BF16 KV, TRACE improves average performance over the strongest listed baseline and surpasses the BF16 vanilla rollout. Under BF16 weights with NVFP4 KV, TRACE improves on QAT across all four benchmarks and approaches the BF16 vanilla average. The largest single-benchmark gain for TRACE in the weight-only ablation is on HMMT25, where it substantially outperforms both QAT and QUADS.
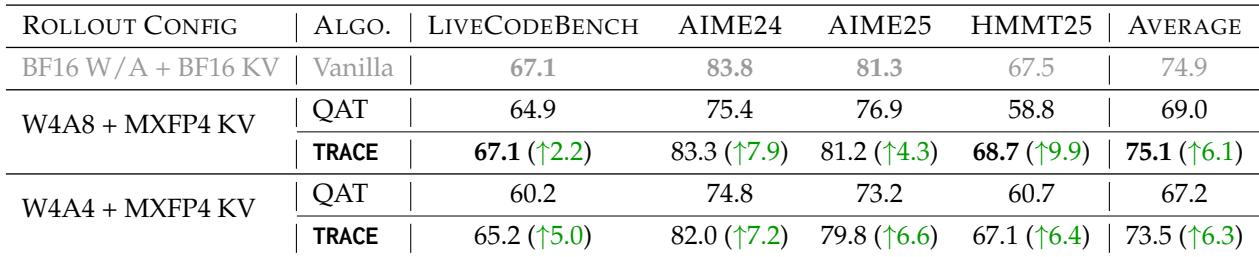
TRACE consistently outperforms QAT across MXFP4 rollout configurations on the reasoning RL task. Under W4A8 MXFP4 with FP4 KV cache, TRACE nearly matches the BF16 rollout baseline, while under the more aggressive W4A4 MXFP4 setting it still recovers most of the performance gap. The gains appear across all evaluated benchmarks. Under W4A8 MXFP4 with FP4 KV cache, TRACE raises the average score from 69.0 to 75.1, close to the 74.9 BF16 baseline. The W4A4 MXFP4 configuration is more difficult for QAT, but TRACE still improves the average score from 67.2 to 73.5. TRACE shows the largest QAT-relative gains on HMMT25 and AIME24 under the W4A8 MXFP4 setting.
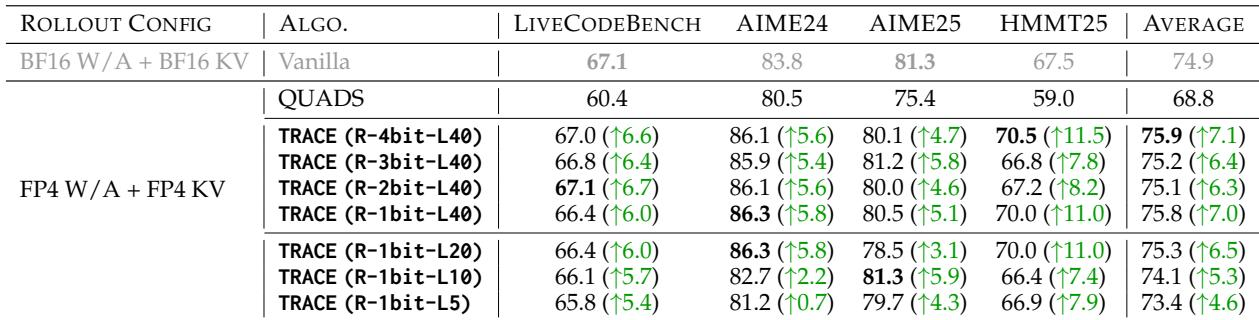
A modular sensitivity study on Qwen3.5-35B-A3B under reasoning RL tasks shows TRACE consistently recovers most of the BF16 rollout performance under joint FP4 weight/activation and FP4 KV cache, whereas the QUADS baseline drops substantially. Retaining quantization information with a single mantissa bit across all 40 layers yields one of the strongest averages, close to the best multi-bit variant, and limiting this information to the later 20 layers produces only a small decline. Further reducing layer coverage to 10 or 5 layers leads to a modest but clearer drop in average reasoning performance. All TRACE FP4 configurations improve over the QUADS FP4 baseline by roughly six to seven points on average and approach the BF16 rollout average. A compact single mantissa bit retained across all 40 layers performs nearly as well as the stronger multi-bit variant, while using only the later 20 layers causes a minor decrease. Reducing the retained rollout quantization information to the last 10 or 5 layers lowers average performance further but remains well above the FP4 QUADS baseline.
These experiments evaluate TRACE under joint FP4 weight, activation, and KV cache quantization, isolated weight and KV cache ablations, MXFP4 rollout settings, and sensitivity to retained quantization information on reasoning and coding benchmarks. TRACE consistently recovers most of the performance lost to low-precision rollout, often matching or slightly exceeding BF16 baselines and outperforming QAT, QaRL, and QUADS across model scales. Gains are especially large on challenging reasoning tasks like HMMT25 and on coding-oriented models, and retaining quantization information across all layers or the later layers largely preserves this advantage.