Command Palette
Search for a command to run...
질문에 대한 질문: 추론 모델에서 자기 진화 지속하기
질문에 대한 질문: 추론 모델에서 자기 진화 지속하기
Jinyuan Li Chengsong Huang Langlin Huang Donghong Cai Shiping Gao Yuyi Yang Jiaxin Huang
초록
자기 진화 추론 모델은 스스로 생성한 질문으로부터 학습하지만, 반복적인 자기 학습은 성능 붕괴로 이어질 수 있다. 본 논문에서는 연속적인 라운드에 걸쳐 성능이 저하되는 이유와 자기 진화를 지속하는 방법을 조사한다. 우리의 분석은 자체 생성된 질문에서 두 가지 반복적인 품질 문제, 즉 유효하지 않은 질문과 동일한 수학 질문의 반복 변형을 식별한다. 첫째, 유효하지 않은 질문은 라운드가 진행될수록 더 흔해지며, 답변 일관성 필터링은 훈련 데이터에서 그 비율을 더욱 높인다. 둘째, 어휘적 유사성에 기반한 기존 질문 다양성 제어는 서로 다른 방식으로 표현된 수학적으로 동등한 질문을 놓칠 수 있으며, 이는 후반 훈련 라운드에서 질문 다양성 붕괴로 이어진다. 이러한 발견을 바탕으로 우리는 질문 유효성과 신규성 피드백을 사용하여 자기 진화를 안내하는 R-Quest를 제안한다. 먼저 솔버가 유효하지 않은 질문을 인식하고 거부하도록 학습시킨 다음, 그 판단을 질문자 보상을 안내하고 솔버 훈련 데이터를 필터링하는 데 사용한다. 질문 반복을 피하기 위해 동결된 기본 모델을 사용하여 샘플링된 질문 쌍을 비교하고 신규성 피드백을 제공한다. 실험적으로 우리의 방법은 두 모델 계열에 걸쳐 수학적 추론, 일반 영역 추론, 코드 생성의 12개 벤치마크에서 일관되게 가장 높은 평균 성능을 달성한다. 또한 R-Quest는 자기 진화의 10회 라운드 동안 안정적인 성능 향상을 유지하며, 마지막 라운드에서 정점에 도달하고 R-Zero보다 17.32포인트 높은 성능을 보인다.
One-sentence Summary
Researchers from Washington University in St. Louis and the University of Michigan propose R-Quest, a method that uses validity and novelty feedback to sustain self-evolution in reasoning models by rejecting invalid questions and detecting mathematically equivalent repeated questions, achieving the highest average performance on 12 mathematical, general-domain, and code-generation benchmarks and outperforming R-Zero by 17.32 points.
Key Contributions
- An empirical analysis identifies invalid questions and repeated mathematically equivalent questions as two recurring bottlenecks in self-evolving reasoning models, showing that invalid questions increase across rounds and answer-consistency filtering further increases their proportion in training data.
- R-Quest trains the solver to recognize and reject invalid questions, uses the solver’s validity judgments to guide questioner rewards and filter solver training data, and provides task-level novelty feedback by comparing sampled question pairs with a frozen base model.
- Across two model families and 12 benchmarks in mathematical reasoning, general-domain reasoning, and code generation, R-Quest achieves the highest average performance; it also sustains gains over ten self-evolution rounds on Qwen3-4B-Base, peaking in the final round and outperforming R-Zero by 17.32 points.
Introduction
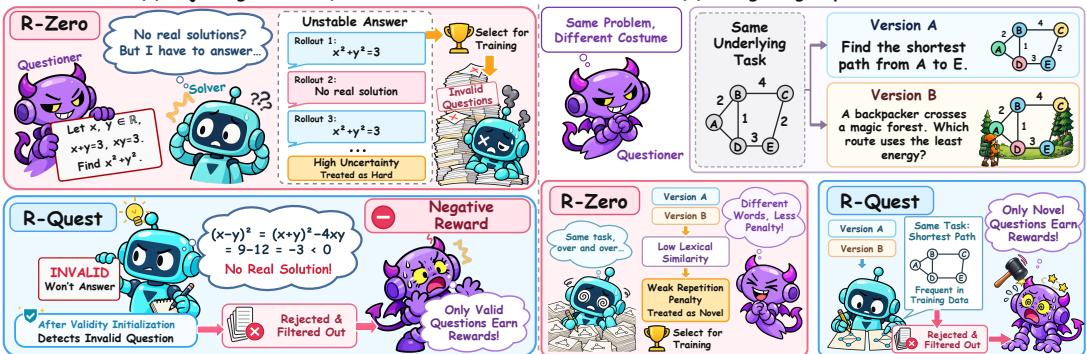
Self-evolving reasoning models that learn by generating and solving their own training tasks can reduce reliance on human-curated data, but prior questioner-solver frameworks such as R-Zero often lose early gains and eventually collapse. The authors identify two bottlenecks in self-generated questions: invalid problems with missing or contradictory conditions, and superficial repeats of the same mathematical tasks that bypass lexical repetition penalties. To address this, they introduce R-Quest, which trains the solver to reject invalid questions and uses validity and task-level novelty feedback to restrict the questioner’s difficulty rewards. R-Quest sustains improvements over ten rounds across two model families and 12 benchmarks, outperforming R-Zero without requiring stronger external models during self-evolution.
Dataset
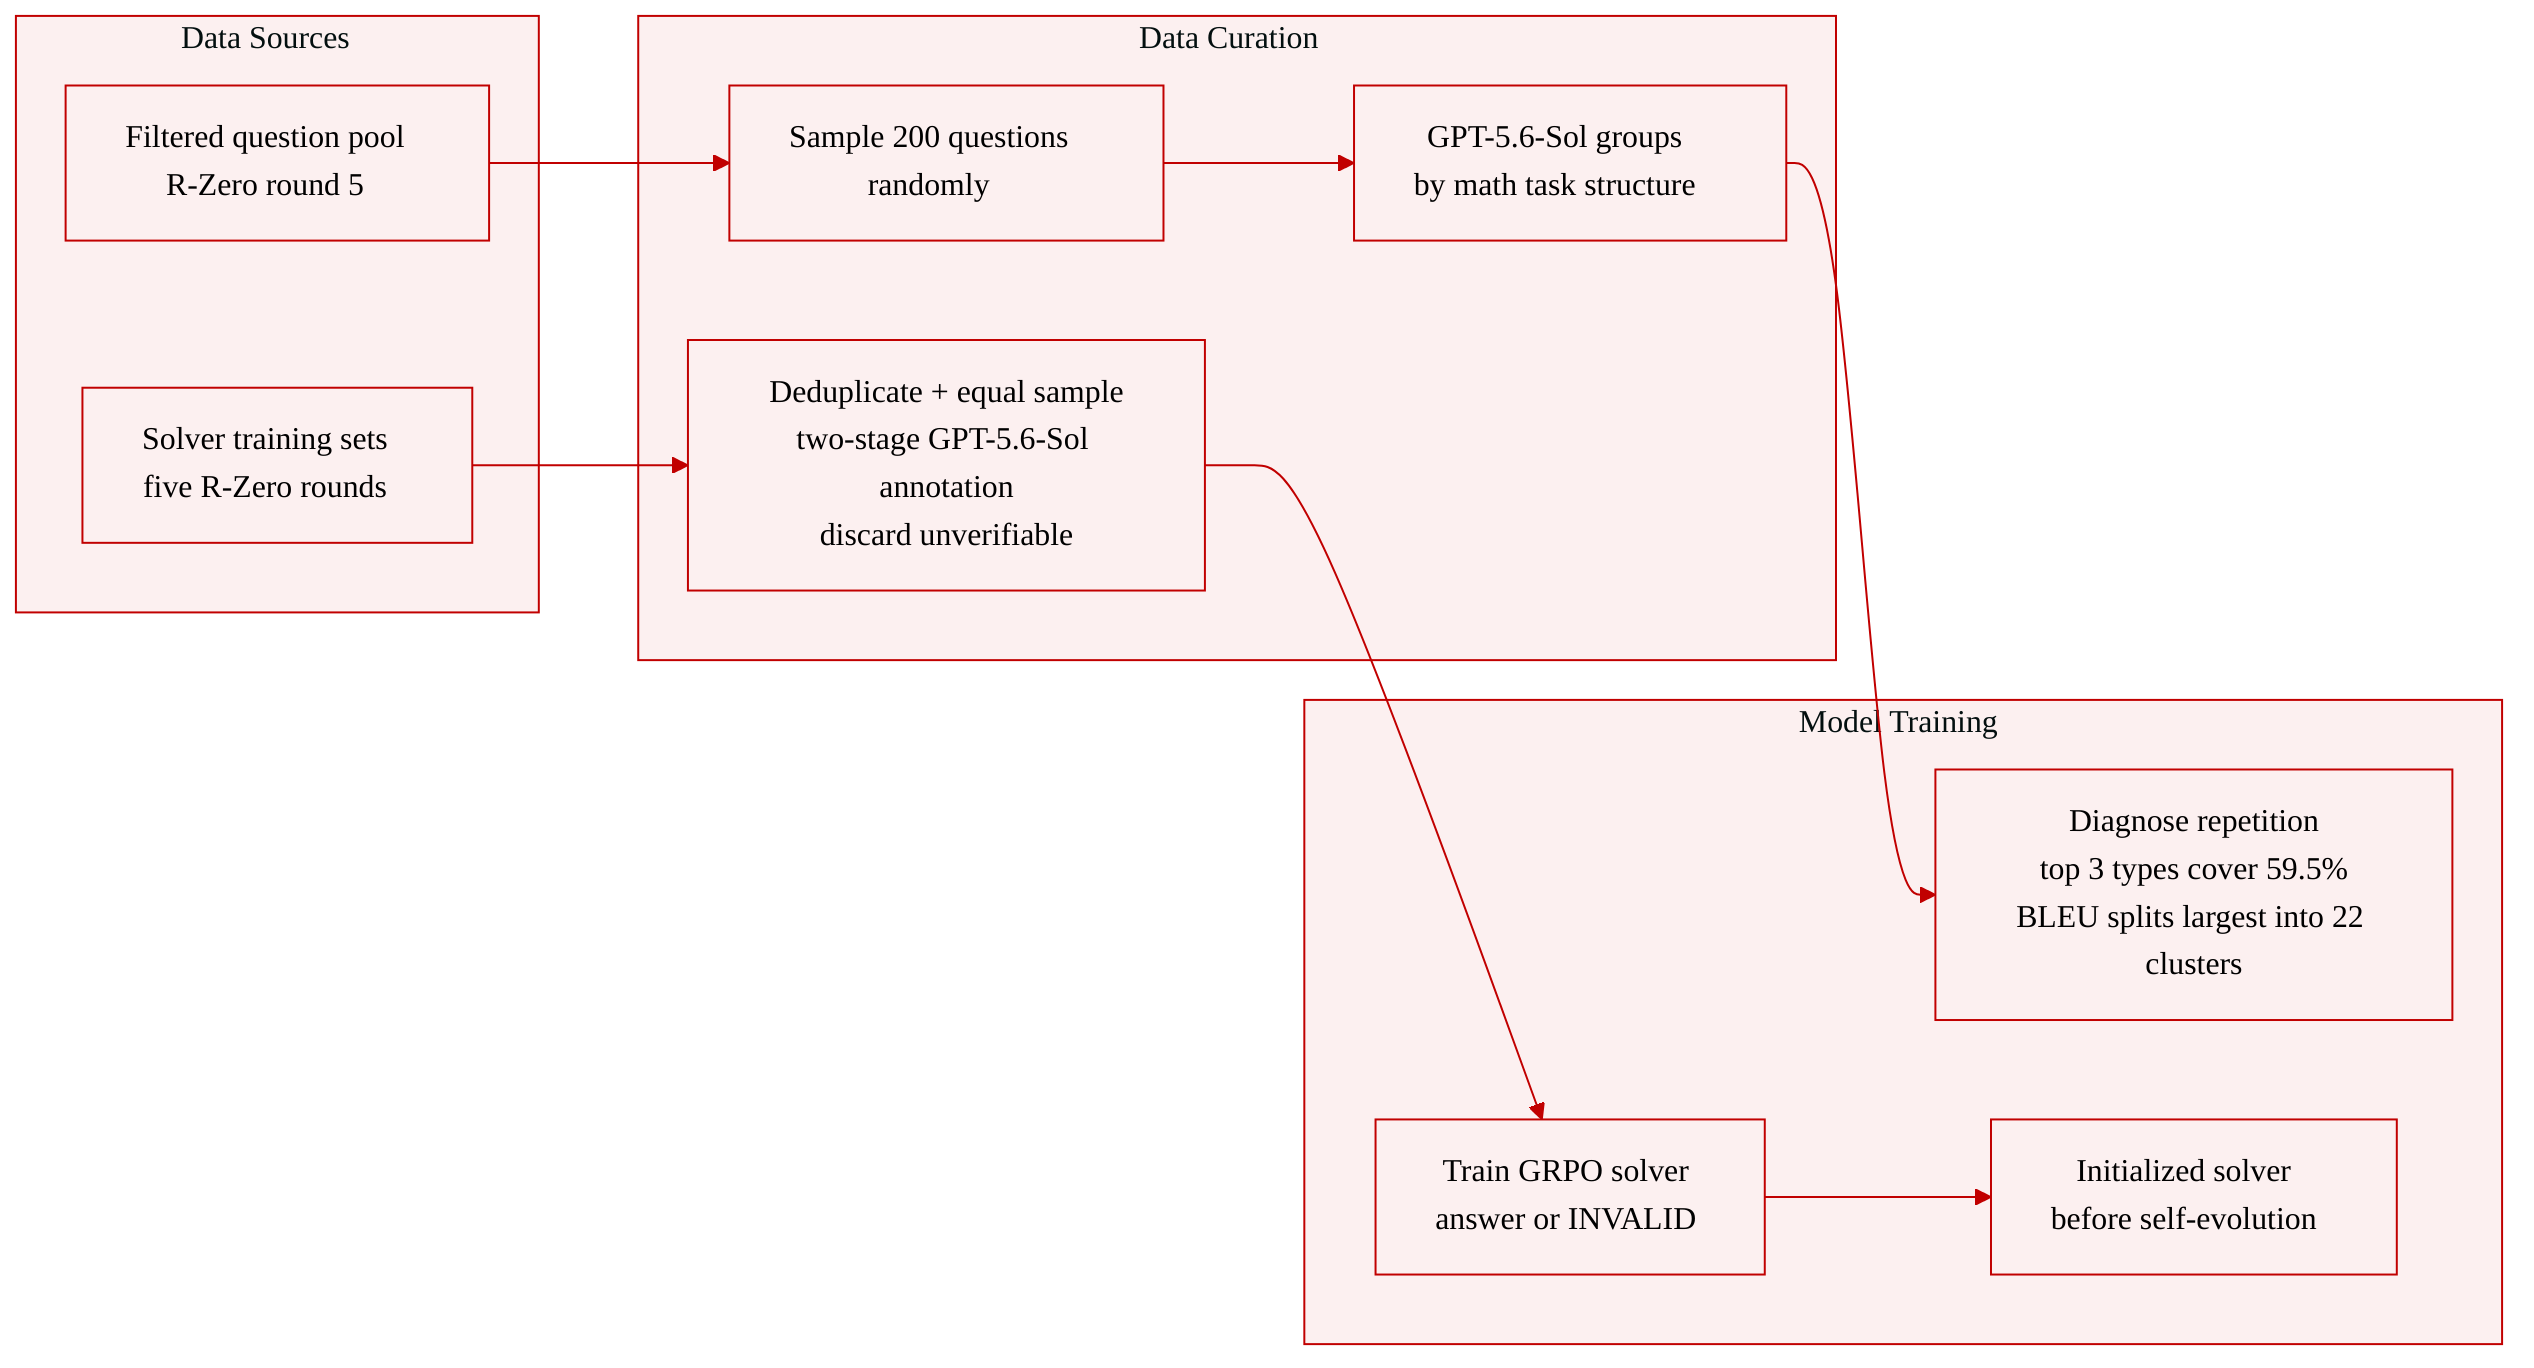
The paper uses two dataset components: a diagnostic sample of generated questions and a validity-aware solver initialization set.
-
Diagnostic repetition sample
- Source: Filtered question pool generated in the fifth round of R-Zero.
- Composition: 200 randomly sampled questions.
- Processing: GPT-5.6-Sol groups the questions by underlying mathematical task structure to identify repeated question types. The grouping protocol is given in Appendix B.3.
- Statistics: The three largest question types account for 59.5% of the sample. Under BLEU-based clustering, the largest question type is split into 22 clusters, showing that lexical clustering can fragment structurally identical questions.
- Use: Diagnoses repetition in self-evolution and motivates assessing repetition based on task structure rather than surface similarity.
-
Validity-aware initialization dataset
- Source: Solver training sets from five R-Zero iterations.
- Composition: Deduplicated questions, with an equal number randomly sampled from each iteration.
- Processing: Two-stage annotation with GPT-5.6-Sol: first, the annotator attempts to solve each question and judges whether it is valid; second, it solves only the valid questions to generate reference answers. Examples whose answers cannot be reliably verified are discarded.
- Schema: Valid questions have reference answers; invalid questions are labeled as invalid.
- Use: Trains the base model with GRPO to answer valid questions or return INVALID for invalid ones. The reward rewards correct answers and penalizes rejecting valid questions, controlled by a penalty factor. The resulting model is used as the initialized solver before self-evolution.
Method
The authors introduce R-Quest, a framework designed to sustain self-evolution in reasoning models by addressing performance collapse caused by invalid questions and repetitive tasks. The system introduces two core feedback mechanisms: validity feedback from a specialized solver and novelty feedback from a frozen base model. These signals guide the reinforcement learning rewards during alternating updates between the questioner and solver roles.
As shown in the figure below:
To prevent the solver from being misled by flawed prompts, the authors implement a validity-aware solver initialization. They construct a dataset of deduplicated questions from previous self-evolution iterations, which are annotated to distinguish valid from invalid prompts. The base model is then trained using Group Relative Policy Optimization (GRPO) to return a mathematical answer for valid questions or an explicit INVALID token for invalid ones. The training utilizes a specific reward function:
Rinit(q,a)=1[a=a∗(q)]−λ1[a=INVALID∧a∗(q)=INVALID]where a∗(q) is the reference answer for a valid question, and λ penalizes excessive refusal of valid questions. This initialization equips the solver to explicitly recognize and reject flawed questions before the main self-evolution loop begins.
To maintain question diversity and prevent the generation of repetitive task variants, the authors employ a frozen base model to assess novelty. Two questions are deemed identical if they share the same mathematical setup and task objective. While an exhaustive pairwise comparison of a batch of size B incurs an O(B2) computational cost, the authors optimize this by uniformly sampling K reference questions per candidate. A candidate is rejected if it matches any of the K references, reducing the complexity to O(BK) and effectively suppressing repeated task types.
During the alternating self-evolution process, the questioner and solver are updated using these integrated feedback signals. For a generated question q, the solver first assesses its validity. Let u(q) be the fraction of solver responses returning INVALID. The validity gate is defined as gvalid(q)=21−u(q). If gvalid(q)<0, the question is classified as invalid. For valid questions, the system calculates an uncertainty reward Runcertainty(q)=min{s(q),1−s(q)}, where s(q) is the proportion of responses in the largest answer cluster. The final questioner reward integrates the novelty gate gnovel(q):
Rquestion(q)={gvalid(q),gnovel(q)Runcertainty(q),gvalid(q)<0,gvalid(q)≥0.The questioner is updated via GRPO using this reward structure. Subsequently, the updated questioner generates new candidate questions, which undergo a majority-vote validity check. Passing questions are solved to generate pseudo-labels via answer-consistency filtering. The solver is then updated using GRPO on this filtered dataset. Crucially, this training data is mixed with a fixed proportion of the initial validity-aware dataset to ensure the solver retains its ability to reject invalid prompts throughout the continuous update cycle.
Experiment
The experiments evaluate R-Quest against base models and self-evolution baselines including R-Zero, OCNR, and R-Diverse across mathematical, general reasoning, and code generation benchmarks, using alternating questioner and solver training with validity and novelty feedback. A preliminary study shows that R-Zero generates increasingly invalid questions and that training on repaired questions reduces solver degradation, confirming invalid supervision as a contributor to collapse. Main results indicate that R-Quest sustains gains over extended self-evolution while R-Zero declines, and ablations confirm that both validity and novelty feedback are necessary for stable improvement. Further analyses show R-Quest improves validity assessment, produces more valid questions with more reliable pseudo-labels, and limits recurring question-pattern concentration, although overly strict diversity control can suppress useful challenging variants.
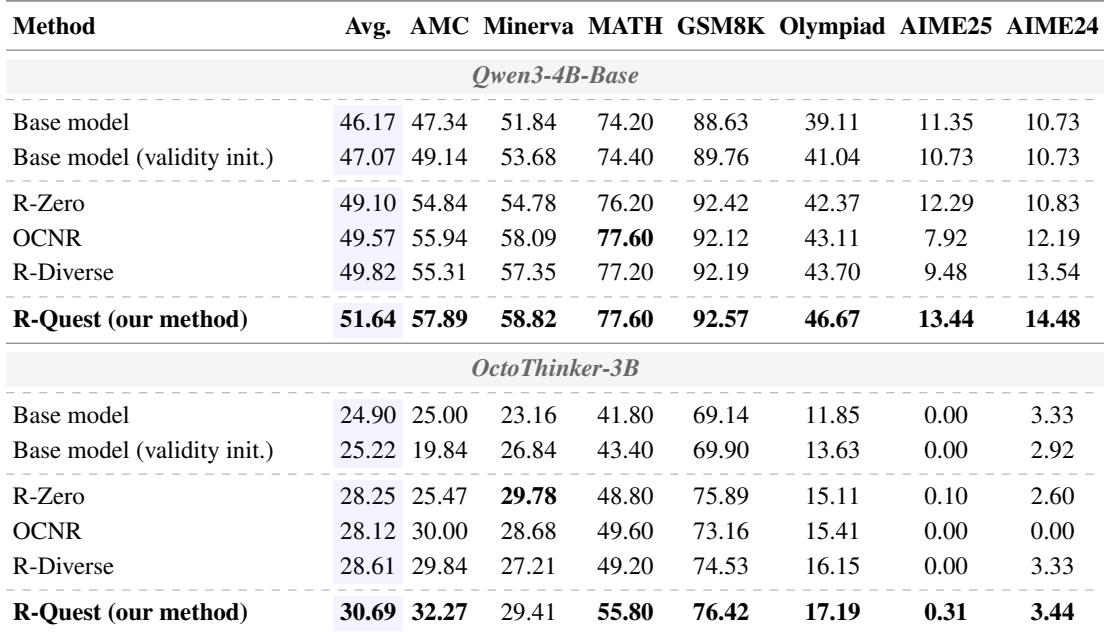
R-Quest achieves the highest average mathematical reasoning performance across seven benchmarks on both evaluated backbones, surpassing R-Zero, OCNR, and R-Diverse. Validity-aware initialization alone yields scores close to base models, while most gains emerge during subsequent self-evolution. In extended self-evolution, R-Quest sustains its advantage over ten rounds, whereas R-Zero declines below its base model. R-Quest records the highest average across all seven mathematical reasoning benchmarks for both backbones. It improves over base models by more than five average points and further outperforms R-Zero. Validity-aware initialization provides near-base performance, indicating later self-evolution drives most of the final gains. During extended training, every R-Quest checkpoint exceeds the best R-Zero score, while R-Zero eventually falls below the base model.
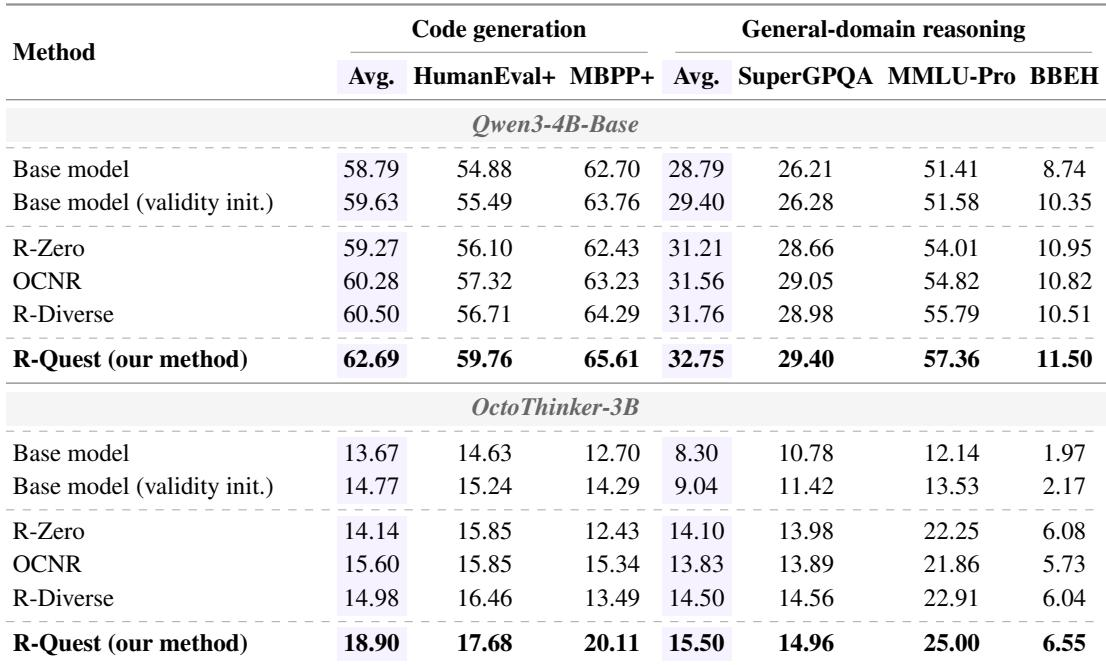
Mathematics-focused self-evolution transfers to code generation and general-domain reasoning. R-Quest is reported to improve average code generation over base models on both tested backbones, and on Qwen3-4B-Base all listed variants raise general-domain reasoning above the base model. Among the listed Qwen3-4B-Base baselines, R-Diverse achieves the highest code generation average, while OCNR and R-Diverse lead general-domain reasoning. Validity-aware initialization brings only small improvements over the base model, whereas subsequent self-evolution baselines show clearer broad reasoning gains.
The full R-Quest configuration records the highest scores across math, code, and general domains on Qwen3-4B-Base. Removing either novelty or validity feedback lowers performance in all three domains, and removing both feedback signals produces the weakest overall results. A frozen validity judge also trails the full setup, reinforcing the benefit of continuous validity training. The full R-Quest variant outperforms all ablated variants across math, code, and general domains. Ablating novelty or validity feedback alone reduces scores in every domain, with larger combined losses when both are removed. Using a frozen validity judge underperforms the full R-Quest configuration in all three domains.
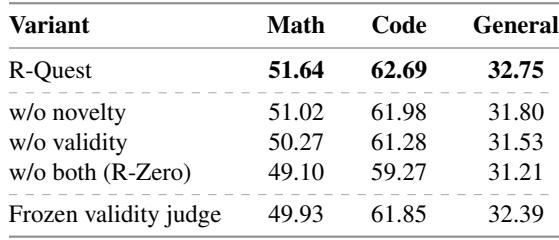
R-Quest is evaluated across seven mathematical reasoning benchmarks on two backbones, where validity-aware initialization alone yields near-base performance and subsequent self-evolution drives most of the improvement, with sustained gains over extended rounds while R-Zero falls below its base model. The approach also transfers to code generation and general-domain reasoning, improving average performance over base models on both tested backbones. Ablation studies show that removing novelty or validity feedback lowers performance across math, code, and general domains, and a frozen validity judge underperforms the full configuration, confirming that both feedback signals and continuous validity training contribute to the strongest overall results.