Command Palette
Search for a command to run...
GroundingPI: 시각 프리미티브를 활용한 물리 지능을 향한 그라운딩 파운데이션 모델
GroundingPI: 시각 프리미티브를 활용한 물리 지능을 향한 그라운딩 파운데이션 모델
초록
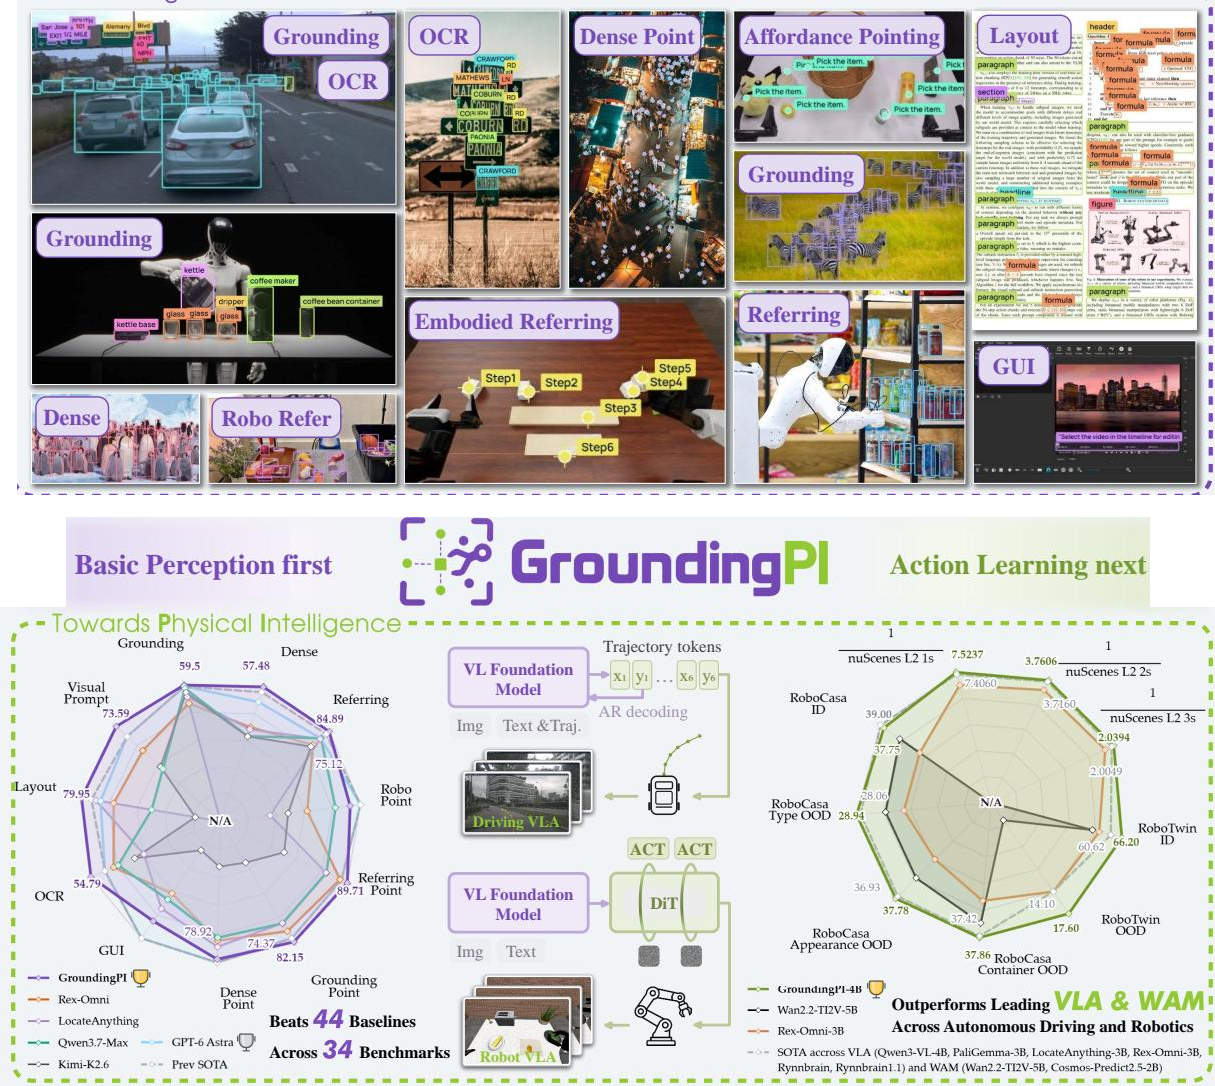
정밀한 그라운딩은 중요하다. 그라운딩은 어떤 객체가 대상이고 그 객체가 어디에 있는지를 지정하며, 혼잡한 장면과 매우 작은 객체에서도 그러해야 하고, 폐루프 제어에 충분히 빨라야 한다. 그러나 비전-언어-행동(VLA) 및 세계-행동(WAM) 모델은 범용 비전-언어 및 비디오 생성 백본에서 지각을 가져오는데, 이들은 이러한 설정에서 여전히 실패한다. 본 연구는 공유 어휘 안에서 양자화된 좌표로 점과 박스를 생성하는 4B 규모의 그라운딩 파운데이션 모델인 GroundingPI를 소개한다. 훈련은 멀티모달 및 공간 사전훈련, 지도식 미세조정, GRPO를 활용한 강화학습을 결합하며, 공개 데이터셋과 전용 데이터 엔진의 감독을 사용한다. 11가지 지각 능력을 포괄하는 34개의 그라운딩 벤치마크에서 44개의 기준 모델과 비교한 결과, GroundingPI는 평균 73.68%를 기록하며 더 큰 GPT-6 Astra(71.54%)를 능가하여 새로운 최고 성능을 달성했다. 다운스트림 시각 백본으로서 GroundingPI는 로봇 조작과 자율주행 성능을 향상시킨다. RoboTwin 2.0에서는 평가한 모든 주류 백본을 네 가지 분포 외 설정 모두에서 능가하며, 가장 강력한 백본 대비 최대 24.8% 향상된다. RoboCasa-GR1에서는 시연의 50%로 훈련한 GroundingPI가 75%로 훈련된 기준 모델들을 능가한다. nuScenes에서 시각 백본으로 사용된 GroundingPI는 평균 개루프 L2 오차 0.296m를 달성한다. 우리는 GroundingPI의 사전훈련을 규모와 데이터 구성 측면에서 체계적으로 분석한다. 사전훈련 규모를 확장함에 따라 다운스트림 자율주행과 로봇 조작 성능이 향상된다. 이 11가지 지각 능력에 걸친 데이터 레시피 분석은 두 분야 모두에 대한 고밀도 그라운딩의 상당한 이점과 지각 학습의 촉매로서 OCR의 잠재력을 보여준다. 이러한 결과는 그라운딩이 지각 기반의 역할을 할 수 있음을, 그리고 전용 지각 사전훈련이 물리 지능 파운데이션 모델의 유망한 방향임을 뒷받침한다.
One-sentence Summary
Researchers at XPeng Inc., Peking University, and other institutions introduce GroundingPI, a 4B grounding foundation model that represents points and boxes as quantized coordinates in a shared vocabulary and is trained through multimodal and spatial pretraining, supervised fine-tuning, and GRPO reinforcement learning, thereby achieving state-of-the-art grounding while improving downstream robotic manipulation and autonomous driving.
Key Contributions
- The paper introduces GroundingPI, a 4B grounding foundation model that generates points and boxes as quantized coordinates in a shared vocabulary and is trained with multimodal and spatial pretraining, supervised fine-tuning, and GRPO reinforcement learning. GroundingPI establishes a new state of the art across 34 grounding benchmarks, averaging 73.68% and exceeding the larger GPT-6 Astra at 71.54%.
- The paper demonstrates transfer to physical intelligence as a downstream visual backbone. On RoboTwin 2.0, GroundingPI outperforms mainstream backbones in all four out-of-distribution settings by up to 24.8% relative to the strongest backbone; on RoboCasa-GR1, training with 50% of demonstrations outperforms baselines trained with 75%; on nuScenes, it attains an average open-loop L2 error of 0.296 m.
- The paper systematically analyzes pretraining scale and data composition. Scaling pretraining improves downstream autonomous driving and robotic manipulation, dense grounding substantially benefits both domains, and OCR may act as a catalyst for perceptual learning, supporting grounding as a perceptual foundation and dedicated perceptual pretraining for System 1 physical intelligence.
Introduction
Visual grounding is central to physical intelligence because models must localize objects, handles, and task-relevant structures before planning how to act. Existing vision-language-action and world-action models often inherit general-purpose vision-language or video-generation backbones that are not optimized for precise grounding, and evaluations reveal weaknesses in dense scenes and tiny objects; recent policy-level perceptual objectives are often task-specific and hard to scale. To close this perceptual gap, the authors introduce GroundingPI, a 4B-parameter grounding foundation model built on visual primitives such as points and bounding boxes, using a shared quantized-coordinate vocabulary to unify grounding, referring, pointing, OCR, GUI and layout grounding, and visual prompting. GroundingPI is trained with multimodal and spatial pretraining, supervised fine-tuning, and reinforcement learning, and it achieves state-of-the-art grounding across 34 benchmarks while transferring effectively to autonomous driving and robotic manipulation.
Dataset
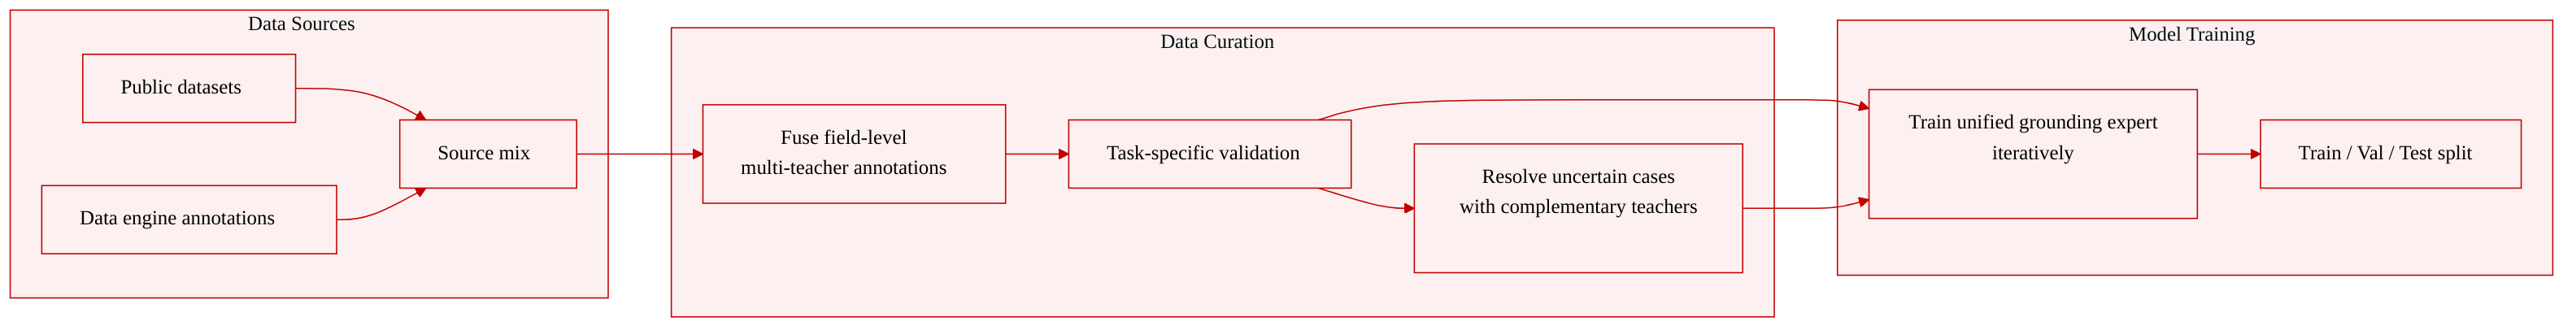
The authors describe GroundingPI data as a hybrid training set built from public datasets and model-generated annotations.
- Sources: Public datasets are combined with annotations produced by the authors’ data engine.
- Composition: The excerpt does not list specific public datasets, dataset sizes, or mixture ratios.
- Annotation processing: The data engine fuses multi-teacher annotations at the field level and applies task-specific validation.
- Label refinement: Accepted labels train a unified grounding expert for iterative annotation. Complementary teachers and local observations resolve uncertain cases to expand supervision and refine existing labels.
- Model usage: The resulting labels are used to train the grounding expert iteratively, improving supervision and label quality.
- Additional processing details: Field validation, task dependencies, and label revision are documented in Section A.3. The excerpt does not specify cropping strategies or metadata schema.
Method
GroundingPI is designed as an autoregressive grounding foundation model for language-conditioned perception and serves as a shared perceptual backbone for downstream physical intelligence tasks.
At its core, the authors couple a MoonViT-V2 visual encoder with a Qwen3-4B language decoder. A learnable projector aggregates adjacent 2×2 visual features and maps them into the language embedding space through a two-layer MLP with GELU and output normalization.
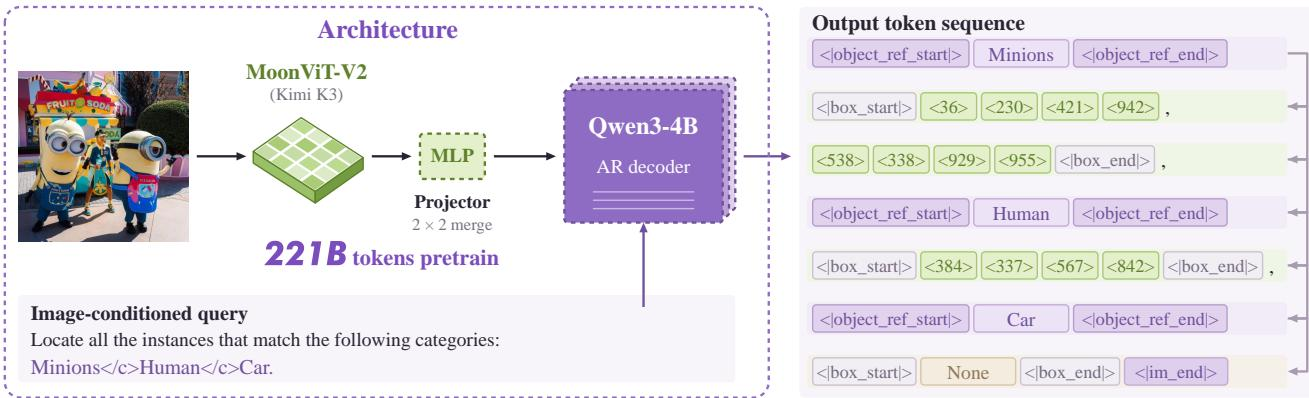
Given an image I and a query P, the encoder Eψ and projector Cϕ produce visual embeddings
V=Cϕ(Eψ(I)).The decoder then generates a variable-length response Y autoregressively:
pθ(Y∣I,P)=i=1∏∣Y∣pθ(yi∣V,P,y<i).Semantic labels, protocol markers, and 1,000 quantized coordinate tokens, written as <0> to <999>, share the output vocabulary. Responses are variable-length, and an absent queried category is emitted as None.
The training data combine public datasets with annotations produced by a dedicated data engine. The engine fuses multi-teacher annotations at the field level and applies task-specific validation.
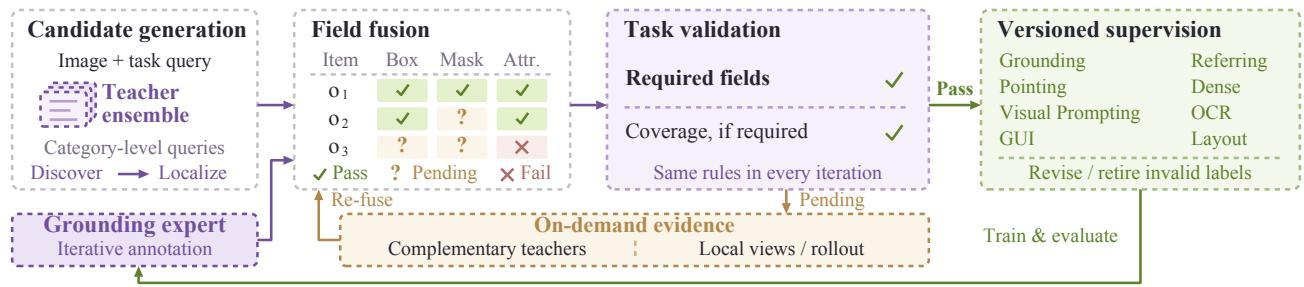
Accepted labels train a unified grounding expert for iterative annotation. Complementary teachers and local observations resolve uncertain cases, expanding supervision and refining existing labels over successive rounds.
The training process consists of base VLM training, supervised fine-tuning, and reinforcement post-training. Base training first aligns the projector using image-caption supervision while freezing both backbones. It then updates all modules in two stages: joint multimodal pretraining on text and image-text supervision, followed by general visual and video understanding through question answering and captioning. All stages use causal next-token prediction.
Supervised fine-tuning aligns coordinates with visual locations and learns the shared output protocol. Under teacher forcing, the authors minimize
LSFT=−∣S∣−1t∈S∑logpθ(yt∣I,P,y<t),where S contains assistant-response labels, protocol markers, and coordinates, while excluding prompt and visual positions. Supervised adaptation first updates all modules and then freezes the vision encoder and projector for language-side refinement.
The final stage applies group relative policy optimization.
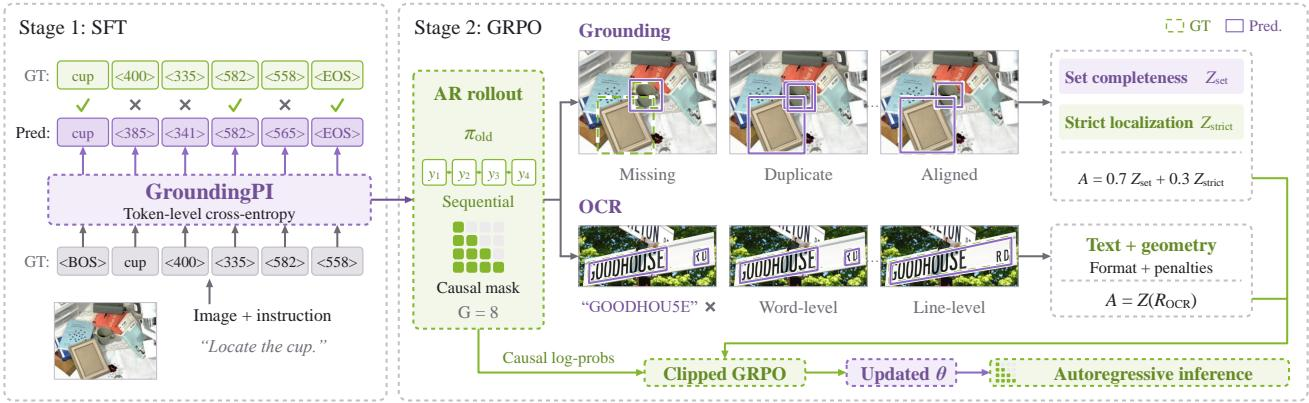
GRPO samples G=8 autoregressive responses per image-query pair. For grounding, Rset measures coverage through reference-wise maximum-IoU matching with class validation. The complementary Rstrict combines multi-threshold F1, localization, format, count, and ordering scores, penalizing duplicate and oversized boxes. The independently standardized rewards are combined as
Ai=0.7Z(Rset,i)+0.3Z(Rstrict,i).For OCR, Hungarian one-to-one matching evaluates text and geometry across complete word or line views and complementary references. Format gating and output penalties produce a composite reward:
Ai=Z(ROCR,i).Here Z standardizes each active reward within a prompt, and the combined advantages are then standardized across the response batch. The authors optimize a clipped GRPO objective with a frozen SFT reference and update only the language parameters.
For physical intelligence, GroundingPI provides a perceptual interface for action learning. In autonomous driving, the task is formulated as language-conditioned trajectory prediction. Given the current front-camera image and historical ego states, the model represents the future trajectory as six ordered waypoints at 0.5-second intervals over a three-second horizon. Each waypoint specifies a cumulative position in the current ego frame, with forward and left axes measured in meters. Fixed metric ranges map these coordinates to the existing <0> to <999> vocabulary. The language head generates the trajectory autoregressively, and response-only cross-entropy provides the adaptation objective. Decoding recovers metric waypoints while preserving temporal order.
For robot manipulation, the authors adopt a π-style flow-matching policy with layer-wise connections. The pretrained foundation encodes the visual observation and language instruction once. Its intermediate features are projected and resampled, then injected into the corresponding cross-attention layers of an Action DiT. Conditioned on these features and the robot state, the action expert denoises a noisy action chunk into continuous controls. In controlled comparisons, the Action DiT, robot data, action representation, optimization budget, and inference procedure are kept fixed while only the pretrained foundation is varied.
Experiment
The experiments evaluate GroundingPI, a compact grounding foundation model, on broad perception benchmarks and on downstream physical-intelligence tasks including autonomous driving and robot manipulation. Benchmark results show strong dense detection, spatial and GUI grounding, OCR, layout, and object pointing relative to comparable models, though some challenging settings remain limited. Transfer tests with fixed action learners indicate that stronger grounding perception supports lower driving error, higher manipulation success, better out-of-distribution generalization, and more data-efficient action learning. Ablations further show that scaling grounding pretraining improves both perception and manipulation, dense grounding provides a core spatial signal, auxiliary OCR, layout, and GUI supervision amplifies transfer when combined with the full mixture, and perception-native foundations may be better suited to fast execution while broader reasoning models serve planning.
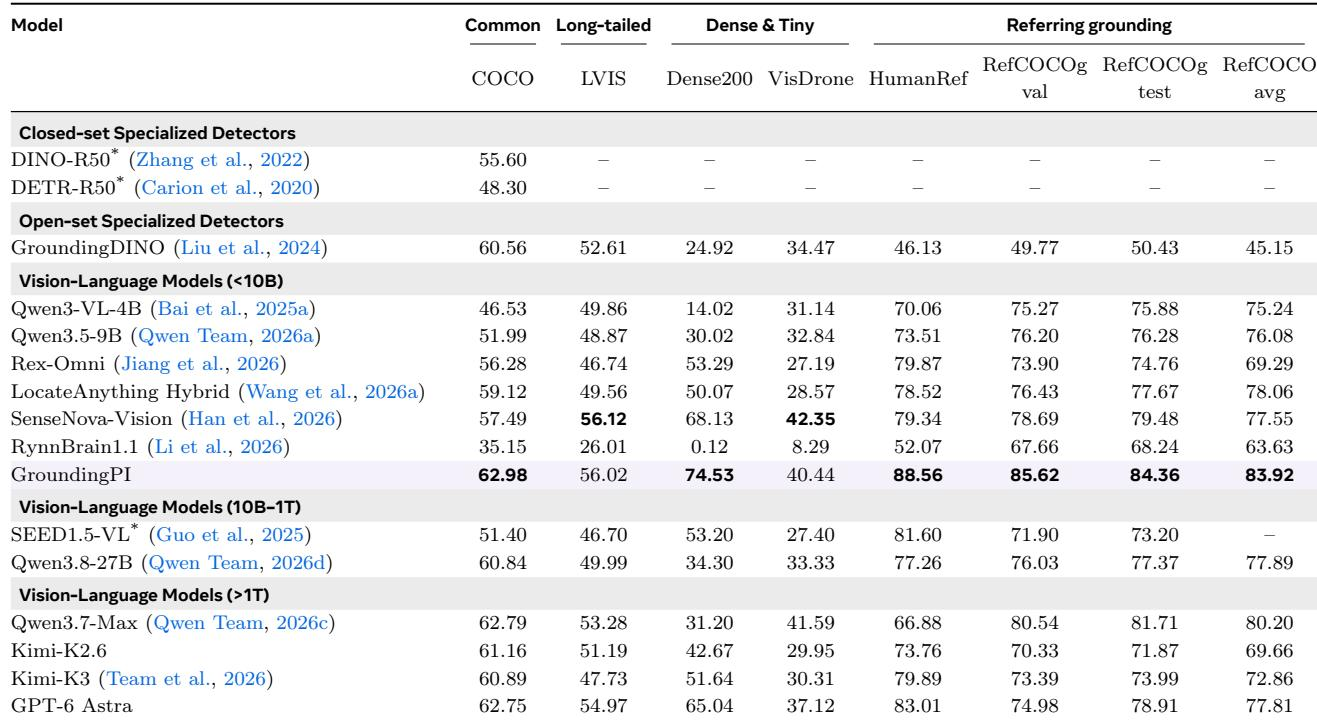
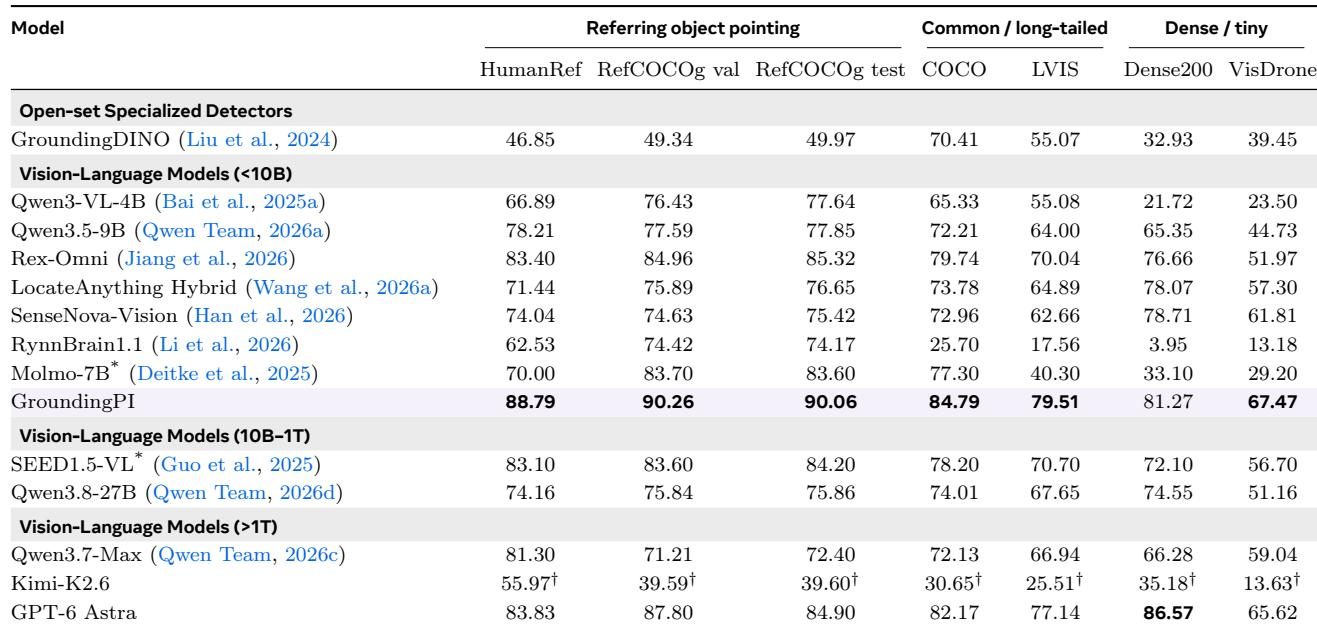
GroundingPI reaches a 73.68% average across the detection and referring grounding suite, ahead of similarly sized models and competitive with a frontier reference at 71.54%. The open-set detector shown has stronger common-object and long-tailed detection than dense and tiny-object detection, where scores are notably lower. Referring grounding results fall between common detection and dense detection, indicating broad coverage with remaining localization challenges. GroundingPI's overall grounding average exceeds similarly sized models and is competitive with the frontier reference. Open-set specialized detection improves reported COCO performance over closed-set detectors but remains much weaker on dense and tiny-object benchmarks. The open-set detector scores higher on RefCOCOg than on HumanRef, suggesting referring grounding varies by benchmark difficulty. Quantized coordinates and the MoonViT-V2 encoder help lift the model's average over alternative design choices.
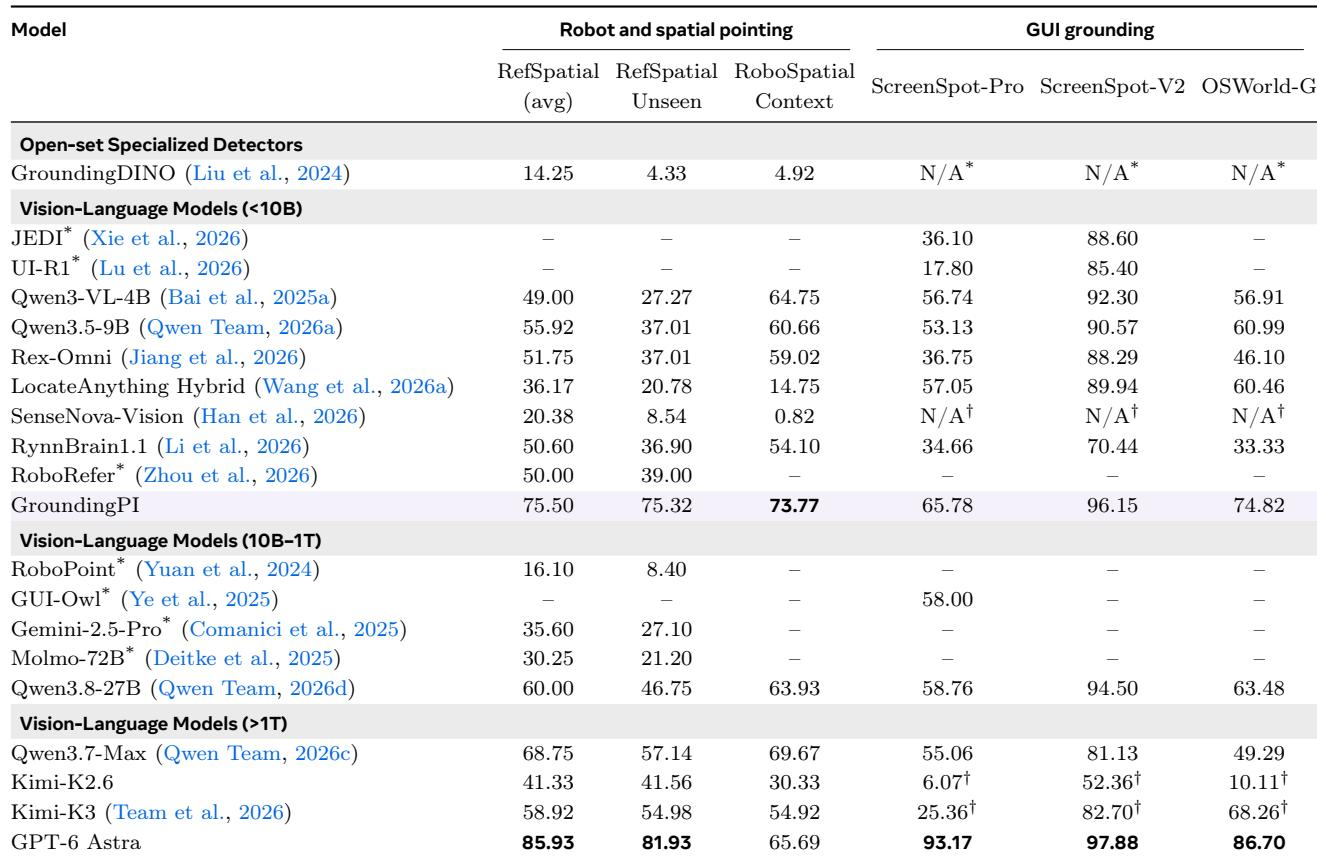
Grounding performance differs sharply across model types and benchmark difficulty. A specialized detector is limited on spatial pointing and lacks GUI grounding coverage, while a general small vision-language model provides the broadest coverage and leads the listed subsets. GroundingPI improves over similarly sized baselines and remains competitive with the frontier reference. A specialized detector trails general vision-language models on spatial pointing and cannot be evaluated on the listed GUI grounding benchmarks. Among sub-10B vision-language models, Qwen3-VL-4B is the only listed model covering both robot/spatial and GUI grounding, and it leads the reported subsets. GUI-focused models perform relatively well on ScreenSpot-V2 but show substantially lower ScreenSpot-Pro accuracy, indicating difficulty on the harder screen grounding benchmark. GroundingPI achieves the highest reported overall average, outperforming similarly sized models and remaining competitive with the frontier reference.
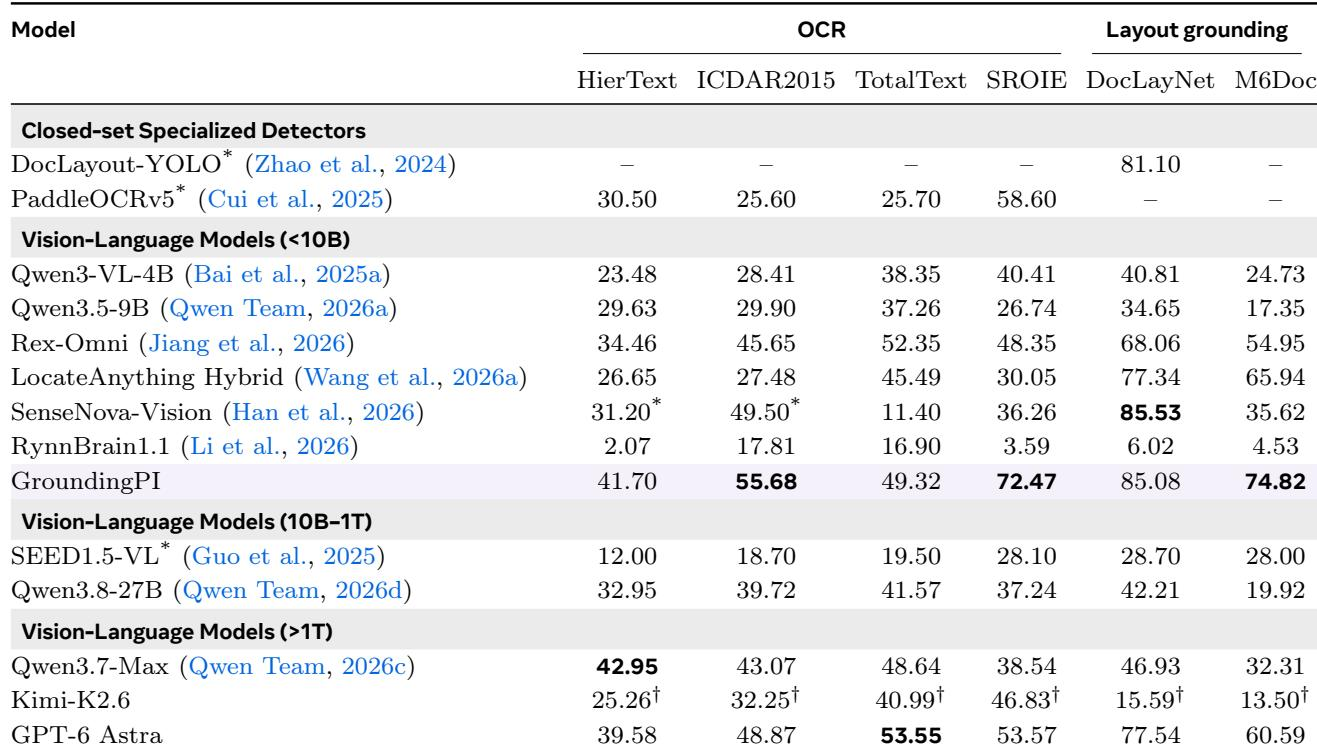
Among the listed OCR and document layout results, DocLayout-YOLO leads document layout by a wide margin, and PaddleOCRv5 has its strongest OCR result on SROIE but lower text detection scores elsewhere. The sub-10B Qwen VLMs trail on document layout, with Qwen3-VL-4B generally outperforming Qwen3.5-9B on SROIE, DocLayNet, and M6Doc while Qwen3.5-9B is slightly stronger on HierText and ICDAR2015. Broader evaluation context reports GroundingPI as competitive with GPT-6 Astra on average grounding performance. DocLayout-YOLO reports the highest listed document layout score and greatly exceeds the Qwen VLM results. PaddleOCRv5 shows its strongest listed OCR result on SROIE, with comparatively low text detection scores on HierText, ICDAR2015, and TotalText. Qwen3-VL-4B outperforms Qwen3.5-9B on SROIE, DocLayNet, and M6Doc, while Qwen3.5-9B performs slightly better on HierText and ICDAR2015.
The listed object pointing results show Rex-Omni ahead of the other baselines on every reported benchmark column, with its largest gap over Qwen3.5-9B in the Dense200 scenario. Qwen3-VL-4B is competitive on HumanRef and RefCOCOg but has much lower dense and tiny-object scores. In the broader evaluation, GroundingPI reaches a 73.68% average, outperforming similarly sized models and remaining competitive with GPT-6 Astra at 71.54%. Rex-Omni leads all listed benchmark columns, with Dense200 showing its largest advantage over Qwen3.5-9B among the reported categories. Qwen3-VL-4B performs well on HumanRef and RefCOCOg but trails substantially on Dense200 and VisDrone relative to other listed VLMs.
GroundingPI shows much more compact output serialization than SEED1.5-VL while reporting comparable or higher boxes per image. Its token cost per box is more than an order of magnitude lower on both COCO and Dense200, and total tokens per image remain far smaller even in denser scenes. The pattern indicates efficient per-box encoding with output overhead spread across many boxes. GroundingPI uses more than an order of magnitude fewer tokens per box than SEED1.5-VL on COCO and Dense200. GroundingPI predicts comparable or more boxes per image while keeping total tokens per image substantially lower. Dense outputs amplify the efficiency advantage, with large reductions in serialized tokens per image relative to SEED1.5-VL.
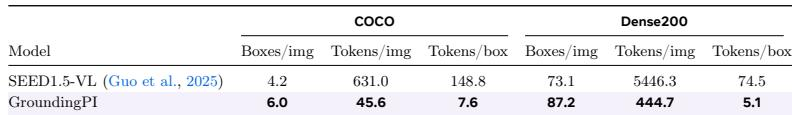
The experiments evaluate GroundingPI across detection and referring grounding, spatial and GUI grounding, OCR and document layout, object pointing, and output token efficiency. GroundingPI reaches a 73.68% average grounding score, outperforming similarly sized models and remaining competitive with the frontier reference, with quantized coordinates and the MoonViT-V2 encoder improving performance. Baseline comparisons show task-specific strengths such as Rex-Omni leading object pointing and DocLayout-YOLO leading document layout, while specialized detectors struggle on dense, tiny-object, and GUI grounding benchmarks. GroundingPI also produces far more compact serialized outputs than SEED1.5-VL, using more than an order of magnitude fewer tokens per box while retaining comparable or higher box predictions.