Command Palette
Search for a command to run...
허위 프런티어: 자기 진화형 검색 에이전트의 공동 치팅(co-cheating) 진단 및 완화
허위 프런티어: 자기 진화형 검색 에이전트의 공동 치팅(co-cheating) 진단 및 완화
초록
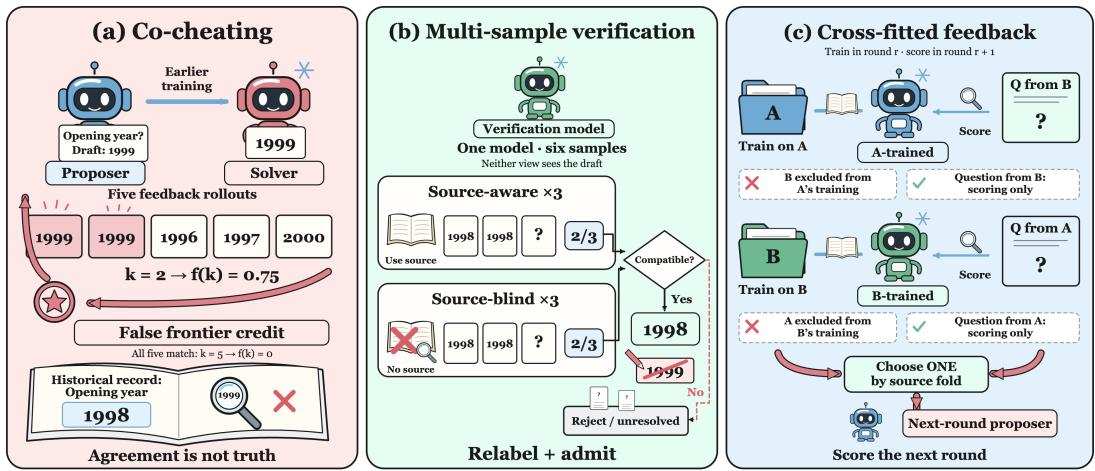
자기 진화형 검색 에이전트는 질문을 생성하는 제안자(proposer)와 그 질문에 답하는 해결자(solver)를 공동 최적화함으로써 자신만의 훈련 커리큘럼을 구성할 수 있다. 이러한 폐루프는 우리가 공동 치팅(co-cheating)이라 부르는 실패 모드를 초래한다. 제안자와 해결자가 공유된 오류에 점점 더 동의하게 되어, 외부 정확성의 상응하는 증가 없이 내부 보상만 향상된다. 소스 증거에 대한 사후 참조 감사(post-hoc reference audit)에 따르면, 자기 진화의 연속적인 라운드가 거듭될수록 공동 치팅은 점점 더 심각해지며, 루프 내 훈련 신호는 개선되더라도 의사 라벨(pseudo-label) 정확성은 정체되거나 하락한다. 가장 직접적인 완화책은 훈련 전에 각 제안을 검증하는 것이다. 따라서 우리는 다중 샘플 검증(multi-sample verification, MSV)을 도입한다. MSV는 자기 진화에 사용된 동일한 모델에 소스와 함께 세 번, 소스 없이 세 번 질의하여 과제 허용 여부를 결정하고 신뢰할 수 없는 의사 라벨을 대체한다. MSV는 허위 동의를 부분적으로 줄이지만 상당한 잔여 공동 치팅을 남기며, 모든 후보에 대해 여섯 번의 추가 라벨러 생성을 필요로 한다. 이러한 한계는 우리의 주요 방법인 CrossFit의 동기가 된다. CrossFit은 제안자의 소스 문서를 그룹 A와 B로 분할한다. A에서 생성된 질문은 B로만 훈련된 보조 해결자에 의해 채점되고, 그 반대도 마찬가지이다. 그 결과로 얻은 교차 적합 일치도(cross-fitted agreement)가 제안자 보상을 결정하며, 원래 해결자의 갱신 규칙은 변경하지 않은 채 동일 소스 의사 라벨이 피드백 해결자를 통해 직접 재생산되는 것을 방지한다. 우리는 Qwen3.5-4B와 Qwen3.5-9B를 사용하여 전체 자기 진화 루프를 다시 실행함으로써 두 개입을 평가한다. 자기 진화 후, MSV는 Qwen3.5-4B에서 허위 동의 질량(false-agreement mass)을 6.1%에서 5.7%로, Qwen3.5-9B에서 8.8%에서 7.2%로 줄인 반면, CrossFit은 각각 3.0%와 3.7%로 줄인다. 동일한 제안을 소스가 배제된 피드백으로 다시 실행하면 허위 동의가 각각 0.4%와 0.1%로 더 감소하여, 생성된 커리큘럼의 변화로부터 피드백 계보(ancestry)를 분리할 수 있다. 7개의 다운스트림 검색 벤치마크에서 CrossFit은 표준 결합 자기 진화 대비 평균 성능을 4B에서 8.8포인트, 9B에서 8.4포인트 향상시키고, Search-R1 대비 각각 8.7포인트와 7.8포인트 향상시킨다.
One-sentence Summary
Researchers from Rutgers University; University of California, San Diego; University of Michigan; McGill University; and King Fahd University of Petroleum and Minerals diagnose co-cheating in self-evolving search agents and propose CrossFit, a cross-fitted verification scheme that scores proposals with an auxiliary solver trained on disjoint source partitions, reducing false-agreement mass to 3.0% on Qwen3.5-4B and 3.7% on Qwen3.5-9B while improving average performance over standard coupled self-evolution on seven downstream search benchmarks by 8.8 and 8.4 points, respectively.
Key Contributions
- The paper identifies and empirically characterizes a failure mode called co-cheating in self-evolving search agents, where the proposer and solver increasingly agree on shared errors so internal reward improves while source-audited pseudo-label correctness stagnates or declines over successive rounds.
- It proposes multi-sample verification (MSV), which queries the same model three times with source evidence and three times without it to decide task admission and replace unreliable pseudo-labels; MSV lowers false-agreement mass from 6.1% and 8.8% to 5.7% and 7.2% on Qwen3.5-4B and Qwen3.5-9B but leaves substantial residual co-cheating and requires six labeler generations per candidate.
- It proposes CrossFit as the main method, partitioning source documents into groups A and B so questions generated from A are scored by an auxiliary solver trained only on B, and vice versa; CrossFit reduces false-agreement mass to 3.0% and 3.7% and improves seven-benchmark average performance over coupled self-evolution by 8.8 and 8.4 points and over Search-R1 by 8.7 and 7.8 points at 4B and 9B.
Introduction
Search-augmented language models improve answering by interleaving reasoning with retrieval or browser actions, but self-evolving proposer-solver systems create their own training questions and pseudo-labels, using solver agreement as a reward signal. The authors show that this setup can produce “co-cheating”: an incorrect pseudo-label teaches the solver to repeat the same error, and the proposer is then rewarded for generating questions that reinforce that false agreement. Multi-sample verification reduces this problem only partially and adds inference cost. The authors’ main contribution is CrossFit, which splits proposer source documents into groups A and B, trains auxiliary scoring solvers on complementary groups, and uses cross-fitted agreement to shape proposer rewards, preventing a same-source error from directly reinforcing itself. In experiments with Qwen3.5-4B and Qwen3.5-9B, CrossFit lowers false-agreement mass and improves seven-benchmark question-answering accuracy over coupled self-evolution and Search-R1.
Method
The authors introduce two key interventions within the self-evolution loop to mitigate error reinforcement: Multi-Sample Verification (MSV) and Cross-Fitted Proposer Feedback (CrossFit).
First, MSV acts as an admission-time test to ensure a proposed question yields a stable answer independent of the proposer's draft. Given a source document x and a question q, the model M generates three source-aware answers aisrc∼M(⋅∣x,q) and three source-blind answers aiblind∼M(⋅∣q) for i∈{1,2,3}. A majority function Maj returns an answer if at least two samples agree under an answer matcher ≃, and ∅ otherwise. Defining yv=Maj(a1:3v) for v∈{src,blind}, the admission criterion is formulated as:
IMSV=1[ysrc=∅∧yblind=∅∧ysrc≃yblind].When IMSV=1, the compatible majority replaces the draft as the training label; otherwise, the task is rejected. This step improves the quality of supervision entering the training phase.
While MSV refines the training labels, CrossFit prevents this supervision from being directly recycled into the proposer's reward. The overall pipeline for this cross-fitted feedback mechanism is detailed in the framework diagram below.
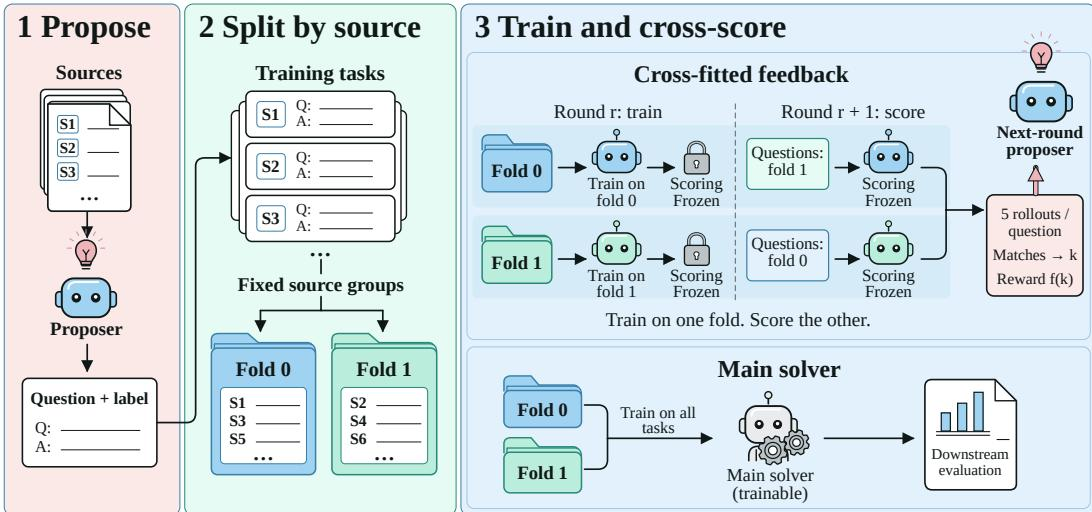
In this architecture, the proposer first generates questions and pseudo-labels from source documents. The authors then partition the source documents into two distinct groups, fold 0 and fold 1. This split is performed at the source level to prevent related examples from the same document from being placed on both sides, which would preserve the data reuse path they aim to eliminate.
The system maintains two auxiliary feedback solvers corresponding to these folds. During round r, one auxiliary solver trains exclusively on admitted questions from fold 0, while the other trains only on fold 1. In the subsequent round r+1, their evaluation roles are crossed: questions originating from fold 0 are scored by the solver trained on fold 1, and questions from fold 1 are scored by the solver trained on fold 0. This ensures that the solver evaluating a specific question has not been trained on pseudo-labels derived from that question's source.
The feedback rule calculates the reward based on the complementary solver's responses. Let h denote the source fold, Sr,1−h the auxiliary solver trained on the complementary fold, and y~ the adopted label. The proposer receives a reward based on five rollouts z1,…,z5:
RP(q)=f(j=1∑51[zj≃y~]),zj∼Sr,1−h(⋅∣q).Here, the function f(k)=(5−k)/4 for 0<k<5 (and zero otherwise) serves as the frontier reward. Consequently, the original training objective is preserved, as questions still receive credit based on their perceived difficulty to the solver, but the direct self-reinforcing error path is broken.
Distinct from the auxiliary solvers, the main solver is not split. It continues to train on all admitted questions from both folds, utilizing the refined feedback to shape the proposer's curriculum for the next round without inheriting the localized source-derived errors.
Experiment
The experiments evaluate self-evolution on seven open-domain question answering benchmarks using Qwen3.5-4B and Qwen3.5-9B, comparing the coupled Dr. Zero loop with multi-sample verification and source-excluded CrossFit feedback over three rounds. Audits of the coupled loop show that proposer-solver agreement becomes increasingly optimistic as false agreement accumulates while correctness does not, revealing a co-cheating dynamic. CrossFit markedly improves downstream search over Dr. Zero and Search-R1, especially on multi-hop tasks, whereas verification alone adds little, indicating that feedback provenance matters more than pseudo-label quality alone. Ablations with fixed question banks and source-level splits confirm that excluding the evaluated source from the feedback solver, rather than evaluator duplication, partitioning, or extra updates, prevents shared same-source errors and accounts for most of the learned search improvement.
Cross-fitted feedback improves downstream search performance at both Qwen3.5 scales, with every evaluated benchmark gaining over the comparison methods. Gains are largest on multi-hop tasks, while verification alone provides only a small average improvement and adds little beyond cross-fitting alone. The results point to feedback provenance as the main factor in the improved search policy. CrossFit improves over Dr. Zero and Search-R1 at both 4B and 9B scales, with all benchmarks gaining. Multi-hop benchmarks show larger average gains than single-hop datasets. MSV alone adds less than one point over Dr. Zero, and combining MSV with CrossFit yields only a small additional improvement.
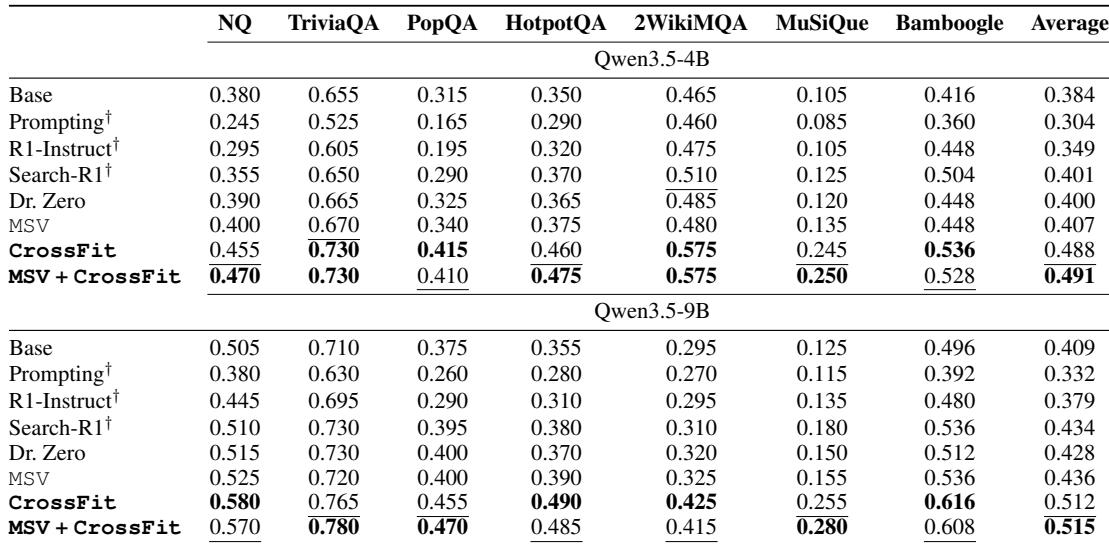
The experiments assess cross-fitted feedback in downstream search using Qwen3.5 at 4B and 9B scales, comparing CrossFit against Dr. Zero and Search-R1. CrossFit consistently improves performance on all benchmarks at both scales, with the largest gains on multi-hop tasks, indicating that feedback provenance is the main driver of the improved search policy. Verification alone provides only marginal average improvement over Dr. Zero and adds little beyond cross-fitting alone, suggesting its contribution is limited.