Command Palette
Search for a command to run...
단백질 접힘 학습은 더 광범위한 추론으로 일반화되는가?
단백질 접힘 학습은 더 광범위한 추론으로 일반화되는가?
Yong Liu Zhanpeng Shi Yizhou Dang Zhongyue Zhang Xiaoliang Shi Zhijian Wei Shuangjia Zheng
초록
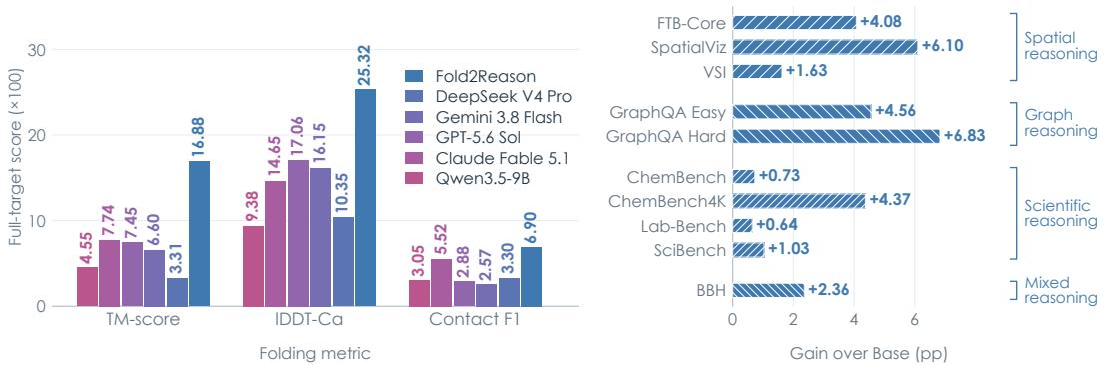
대규모 언어 모델은 인간이 작성한 텍스트에 크게 의존하는데, 그러한 텍스트는 흔히 그 이면의 공간적·구조적 논리보다는 표면적인 답을 전달한다. 단백질 접힘은 하나의 해석된 구조가 정확히 검증 가능한 수천 개의 공간적·위상적 명제를 산출하므로 자연스러운 시험대가 된다. 우리는 단백질 접힘을 학습하는 것이 일반 모델에 재사용 가능한 추론 능력을 가르칠 수 있는지 묻는다. 이에 답하기 위해 단백질 유래 질의응답 데이터셋인 FoldingCorpus와, 두 가지 상호보완적 신호를 통해 이를 사후 학습하는 방법인 Fold2Reason을 구축한다. 두 신호는 모델 고유의 언어 헤드를 통해 예측되는 이산적 구조 답과, 동일한 공유 표현으로부터 디코딩되는 연속적 3D 기하 정보이다. FoldBench에서 Fold2Reason은 Qwen3.5-9B 대비 2.7배에서 3.5배에 달하는 구조 예측 점수를 달성한다. 단백질 구조 예측을 넘어, 공간·그래프·과학·일반 추론을 아우르는 10개 벤치마크 모두에서 성능을 향상시켜 매크로 평균 정확도를 45.09%에서 48.33%로 끌어올렸으며(+3.23%p), 10개 벤치마크 전부에서 긍정적 향상을 보였다. 반면 무작위·합성·셔플 구조로 구축한 대응 대조군은 훨씬 작거나 부정적인 향상을 보였다. 우리의 연구는 비언어적이고 구조 밀도가 높은 과학 데이터가 언어 모델의 광범위한 추론을 체계적으로 향상시킬 수 있으며, 해결된 과학 문제를 실용적인 사후 학습 감독의 원천으로 만들 수 있음을 보여준다.
One-sentence Summary
Researchers from Shanghai Jiao Tong University, Fudan University, Shanghai Innovation Institute, and Northeastern University propose Fold2Reason, a post-training recipe built on the FoldingCorpus protein question-answer dataset that combines discrete structural answers predicted via the model’s native language head with continuous 3D geometry decoded from shared representations, improving structure prediction scores 2.7 to 3.5 times those of Qwen3.5-9B and raising macro-average accuracy across 10 reasoning benchmarks by 3.23 percentage points.
Key Contributions
- FoldingCorpus is a question-answer dataset built from existing protein structures, containing 1,200 proteins and 14,400 records across 12 structural operators, with cluster-disjoint core partitions and independently recomputed answers for auditability.
- Fold2Reason is a post-training recipe that uses two complementary signals from shared representations: discrete structural answers supervise the model's native language head, while a frozen coordinate decoder constrains the same LoRA-adapted residue states; downstream evaluation uses the adapted base model alone.
- On FoldBench, Fold2Reason achieves structure prediction scores 2.7 to 3.5 times those of Qwen3.5-9B. Across 10 general reasoning benchmarks, it raises macro-average accuracy from 45.09% to 48.33% with positive gains on all 10 benchmarks, while matched controls built from random, synthetic, and shuffled structure yield substantially smaller or negative gains.
Introduction
The authors tackle the open question of which supervision properties enable language model training to transfer beyond its source domain. Finite human-written text and code motivate alternative supervision, but specialized training often leaves broader behavior unchanged or worse. Protein folding provides a compelling testbed because solved Protein Data Bank coordinates yield deterministic, automatically verifiable contact, distance, orientation, and coordinate targets at scale without extra annotation. The authors build FoldingCorpus from 1,200 proteins and 12 structural operators, and propose FOLD2REASON, which post-trains Qwen3.5-9B with discrete structural answers plus continuous geometry supervision through a shared LoRA workspace, then removes all protein-specific components at evaluation. Across three seeds, this improves the General-10 macro-average from 45.09% to 48.33% (+3.23 pp), with positive mean changes on all ten general reasoning datasets, supporting behavioral transfer rather than uniform improvement.
Method
Training targets: known answers, hidden evidence
For a protein of length L, let x contain the amino-acid sequence and optional MSA or template evidence, let Y∈RL×4×3 contain the known backbone coordinates, and let m denote the residue-validity mask. Coordinates are used to generate targets and losses, but they are not part of the model input. The language model processes a prompt containing one marker per residue and produces residue states
H=fθ(x)res∈RL×4096,where the base weights are frozen and θ includes the trainable LoRA parameters.
Each protein yields one packed set of 12 questions. Programs computed over Y create labels for contact, distance comparison, segment orientation, center proximity, local direction, chirality, multi-constraint, and global-summary tasks. Nine answers are binary, two are three-way, and one is a 32-way textual summary match. Every option is represented by one vocabulary token. The authors construct these question packs once, independently recompute the answers, and retain the numerical evidence in an audit record rather than placing it in the prompt. Independent hash salts determine label sampling, option order, and question order, and the frozen packs are reused across epochs. The 32-way question selects among one target summary and 31 hard-negative summaries, but it remains ordinary answer-token supervision rather than a separate retrieval objective.
One workspace, two readouts
The workspace module Wϕ reduces the marker states to 256 dimensions, exchanges messages over sequence-local pairs and sampled long-range pairs, and returns two readouts:
(E,M)=Wϕ(H),E∈RL×4096,M∈R16×4096.Here E is residue aligned. Sixteen learned queries pool the residue set and project it back to the language model width, producing evidence tokens M. The workspace refers only to these training-time residue and pooled tensors.
Message-passing pairs connect sequence offsets 1 to 4 and evenly spaced longer-range indices, with at most 2,048 pairs per protein. Target contacts do not select the edges. Symmetric features combine absolute differences and elementwise products of the reduced states. Messages are averaged at incident residues followed by residual updates. Learned-query pooling forms the fixed-size prefix M, while E preserves residue-level correspondence.
The FoldingCorpus path prepends M to the packed question sequence q. Prefix and prompt positions are ignored, and only the 12 answer tokens and the end-of-sequence token are supervised. The answer loss is
Lqa=−∣S∣1t∈S∑logpθ,ϕ(yt∣M,q,y<t).The geometry path passes E to a frozen coordinate and distogram decoder gψ. Its loss combines coordinate, pair-distance, contact, distogram, local-frame, torsion, and radius-of-gyration terms:
Lgeo=Lcoord+Lpair+Lcontact+Ldist+Llocal+Ltorsion+LRg.Freezing ψ prevents a new coordinate head from absorbing the objective. Gradients must instead change the shared workspace and the LoRA parameters. The canonical objective is L=Lqa+Lgeo. Each training example uses two forward passes through the same LoRA-adapted model: the protein forward pass produces H, and the answer forward pass consumes the concatenation of M with the embedded question-answer sequence. The computation graph is retained between the two forward passes, so the answer loss updates both the answering parameters and the protein-to-workspace path. Freezing the decoder means excluding ψ from the optimizer, not detaching E. Geometry gradients therefore still reach ϕ and the shared LoRA parameters.
Only LoRA and the active workspace parameters are optimized. In the canonical run, four workers accumulate two one-protein microsteps, giving eight proteins per update. The authors average the answer cross-entropy over the 12 labels and the end-of-sequence token, combine it with the geometry loss, and clip the accumulated gradient norm to 1.0 before each AdamW update. At transfer evaluation, the workspace Wϕ and decoder gψ are discarded, and only the learned LoRA adapter is applied to the model's native benchmark interface. Thus, any measured transfer must reside in the adapted language model rather than in protein-specific modules.
Experiment
The study trains LoRA adapters on a protein FoldingCorpus that combines verified question-answer targets with geometry supervision through a frozen structural reader, then evaluates transfer on the General-10 reasoning suite and FoldBench structural metrics. Matched controls show that format copying and shuffled labels do not yield reliable gains, while hidden geometry targets transfer only partially, and scaling experiments indicate broad improvements across dataset families with diminishing returns at larger protein coverage. Ablations attribute most general reasoning transfer to FoldingCorpus answer supervision, with geometry contributing mainly to 3D-oriented tasks and local structural readouts, and cross-model tests find gains for several Qwen scales and InternVL but not Gemma.
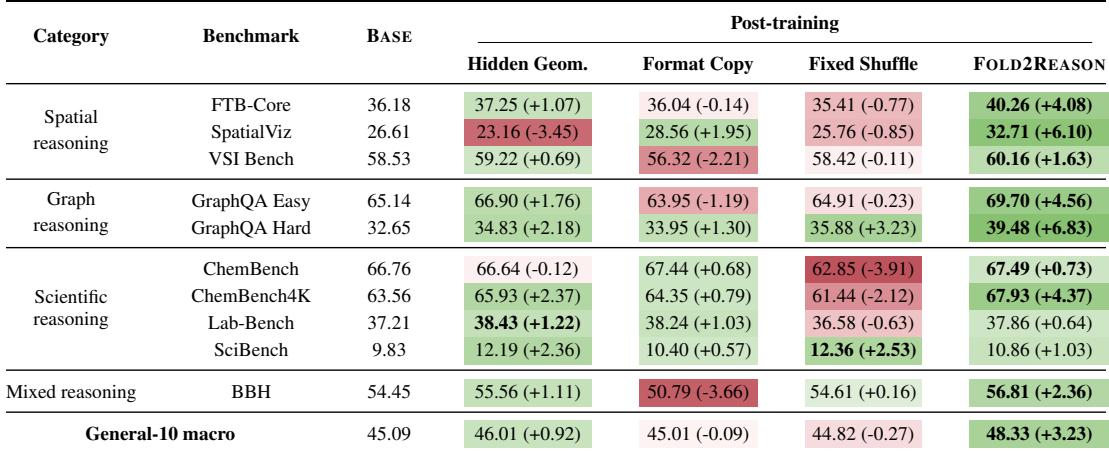
FOLD2REASON lifts the General-10 macro from 45.09% to 48.33%, a gain of 3.23 percentage points, with positive mean changes on all ten datasets. Matched controls show a small aggregate gain from hidden geometry targets, while format copying and fixed shuffled labels stay near zero. The full recipe surpasses the strongest control by more than twofold, indicating the improvement is tied to protein-derived supervision rather than answer formatting or fixed label mismatches. FOLD2REASON improves the General-10 macro by 3.23 percentage points over the base model. Gains are broad, with positive mean changes across all ten General-10 datasets and the largest improvements concentrated in graph and spatial reasoning benchmarks. Among matched controls, only Hidden Geometry produces a modest aggregate gain; Format Copy and Fixed Shuffle remain near zero. The FOLD2REASON gain is more than twice the strongest control, so answer formatting or fixed shuffled supervision alone cannot explain the improvement.
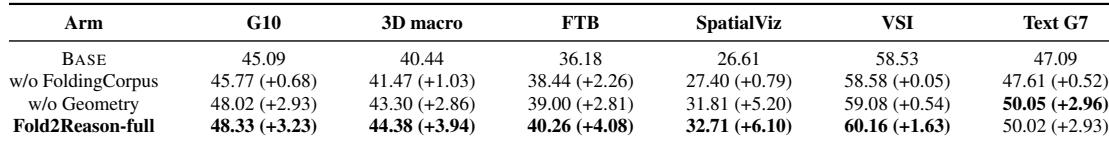
The full Fold2Reason configuration improves General-10 accuracy over the base model by just over three percentage points, with larger gains on the 3D macro than on the text-only aggregate. FoldingCorpus supervision accounts for most of the broad and text-heavy gains, while the added geometry signal provides a further modest boost concentrated in spatial tasks such as FTB-Core, SpatialViz, and VSI. Removing FoldingCorpus leaves only small overall improvement, confirming answer supervision as the main driver of behavioral transfer. The full configuration gains about 3.2 points on General-10 and about 3.9 points on the 3D macro relative to base. The w/o Geometry arm already supplies most of the overall General-10 and text aggregate gains, indicating FoldingCorpus supervision is the dominant contributor. Adding geometry on top of FoldingCorpus improves the 3D macro by about one point and each 3D-oriented dataset while leaving the text aggregate essentially unchanged. Without FoldingCorpus, gains are much smaller, especially for SpatialViz and VSI, while FTB-Core still shows a moderate improvement.
The evaluation measures transfer to the General-10 and 3D benchmarks. The full Fold2Reason method improves General-10 accuracy by about 3.2 points over the base model, with broad positive changes across all ten datasets and larger gains on spatial and 3D tasks. Control experiments show hidden geometry gives only a modest aggregate gain while format copying and fixed shuffled labels stay near zero, indicating the improvement is tied to protein-derived supervision rather than formatting or label mismatches. Ablations confirm that FoldingCorpus answer supervision is the main driver of broad and text-heavy gains, with the added geometry signal providing a further modest boost concentrated in 3D-oriented benchmarks such as FTB-Core, SpatialViz, and VSI.