Command Palette
Search for a command to run...
MotorMind: 제로샷 로봇 조작을 위한 범용 비전-언어 모델 스캐폴딩
MotorMind: 제로샷 로봇 조작을 위한 범용 비전-언어 모델 스캐폴딩
Bingxuan Li Siqi Song Yizhuo Wu Jiarui Yao Tong Zhang Huan Zhang
초록
비전-언어-행동(VLA) 모델은 로봇 조작을 발전시켜 왔지만, 새로운 작업과 환경에서의 제로샷 일반화는 여전히 제한적이며, 전문적인 훈련에 의존하기 때문에 빠르게 발전하는 범용 비전-언어 모델(VLM)의 혜택을 직접적으로 받지 못한다. 이와 병행하여, 최근 에이전트형 로봇 시스템은 고수준 추론을 위해 VLM을 활용하거나 로봇 제어를 위해 코딩 에이전트를 활용하지만, 종종 광범위한 외부 모델과 도구에 의존하여 추가적인 복잡성과 비용을 초래한다. 이는 다음과 같은 질문을 제기한다: 범용 VLM 자체가 학습된 행동 전문가, 코딩 에이전트, SAM3와 같은 그라운딩 도구 등의 외부 모델에 의존하지 않고, 관찰로부터 직접 추론하고 행동을 생성하며 실행 피드백에 지속적으로 적응함으로써 인간 원격 조작자와 더 유사하게 로봇을 조작할 수 있는가? 본 연구에서는 VLM이 제안하는 중간 수준 행동을 결정론적 로봇 제어 및 피드백과 연결하고, 비동기 모니터링과 백그라운드 메모리 갱신을 제공하는 로봇 조작 하네스인 MotorMind를 소개한다. 작업 특화 정책 훈련, 코딩 에이전트, SAM3와 같은 추가적인 그라운딩 도구 없이도 MotorMind는 기본 LIBERO-PRO 스위트에서 66.7%, 교란 상황에서 53.8%의 성공률을 달성하는 반면, 우리가 평가한 이전 제로샷 방법들은 각각 최대 13.3%와 19.2%에 그쳤다. 동일한 인터페이스는 실제 xArm6 로봇에서 직접 조작 및 인간 교란 설정 전반에 걸쳐 평균 95%의 성공률에 도달한다. 백본을 더 강력한 VLM으로 교체하면 성능이 추가로 향상되며, 주로 시각적 그라운딩, 체화된 추론, 행동 지식에서 비롯된 나머지 실패들은 VLM 능력이 향상될수록 감소한다. 이러한 결과는 적절한 중간 수준 행동 표현과 비동기 실행 하네스를 갖춘 범용 VLM이 효과적인 제로샷 로봇 조작을 수행할 수 있음을 보여준다.
One-sentence Summary
Researchers from the University of Illinois Urbana-Champaign introduce MotorMind, a robot manipulation harness that connects VLM-proposed mid-level actions to deterministic robot control and feedback with asynchronous monitoring and background memory updates, enabling zero-shot manipulation without task-specific policy training, coding agents, or grounding tools such as SAM3 and achieving 66.7% success on the base LIBERO-PRO suites, 53.8% under perturbations, and 95% average success on a real xArm6 robot.
Key Contributions
- The paper introduces MotorMind, a zero-shot robotic manipulation harness that connects a frozen general-purpose VLM to deterministic robot control through a mid-level action representation, with asynchronous execution monitoring, background memory updates, and outcome verification.
- MotorMind achieves 66.7% success on the LIBERO-PRO base suite and 53.8% under perturbations, compared with at most 13.3% and 19.2% for the prior zero-shot methods evaluated, and reaches 95% average success on a real xArm6 robot across direct manipulation and human-perturbation settings.
- Replacing the Qwen3.8-Flash-Next backbone with GPT-6 Sol improves success on the LIBERO-PRO base suite from 66.7% to 83.3%; failure analysis identifies visual grounding, embodied reasoning, and action knowledge as the main remaining bottlenecks.
Introduction
Vision-language-action robotics foundation models map visual observations and language instructions directly to robot actions, but their zero-shot transfer is limited under changes in object appearance, spatial configuration, task semantics, and environment structure. They are also trained on specialized robotics data and cannot directly benefit from emerging general-purpose vision-language models. Agentic approaches that use general VLMs for planning often depend on external components such as learned action experts, segmentation models, skill libraries, and motion planners, which limits simplicity and generality. To address these gaps, the authors study whether a general-purpose VLM can handle local manipulation decisions and introduce MotorMind, a VLM-centric control harness that exposes a compact mid-level action representation for translations, rotations, and gripper commands, coordinates execution with background monitoring and outcome assessment, and transfers across robot embodiments without task-specific policy training. This design achieves strong zero-shot performance in simulation and on a real robot, and improves further with a stronger VLM backbone, suggesting that gains in general-purpose multimodal models can translate directly into more capable robot control.
Dataset

The authors construct an embodied question-answering benchmark for diagnosing vision-language models for robotic manipulation. The excerpt describes it as an evaluation dataset, not a training dataset.
-
Composition and scale: 240 questions total, evenly split across three capabilities:
- Action selection: 80 questions
- Progress assessment: 80 questions
- Subgoal completion: 80 questions
-
Underlying source: The provided text does not describe the raw robot observation data, collection procedure, or environment source. It only states that the authors constructed the benchmark.
-
Action selection subset:
- Requires the model to use past and current observations plus the instruction.
- Task: choose the next action.
- Reported accuracy is lowest for all evaluated models, suggesting this is the hardest diagnostic capability.
-
Progress assessment subset:
- Requires the model to determine whether an observed transition advances the task.
- Uses past and current observations.
- Task: decide whether progress toward the current subgoal has been achieved.
-
Subgoal completion subset:
- Requires the model to judge whether the current observation satisfies the stated subgoal and success criterion.
- Uses the current observation.
- Task: decide whether the active subgoal is complete or requires further actions.
-
Processing and usage:
- The benchmark assesses local visual decision making rather than closed-loop control of a complete task.
- It is used diagnostically to evaluate VLM capabilities before designing a robotic policy.
- The excerpt does not describe a training split, mixture ratios, or training use; the data are used for model evaluation.
-
Example diagnostic results reported in the paper:
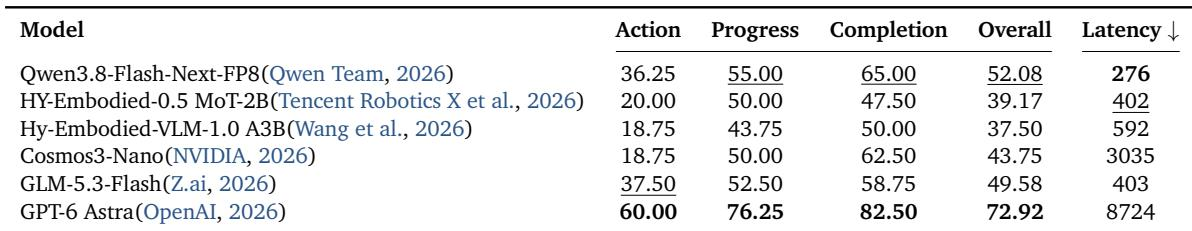
- Qwen3.8-Flash-Next: 36.25% action selection accuracy, 55.00% progress assessment accuracy, and 65.00% subgoal completion accuracy.
- GPT-6 Astra: highest accuracy on all three capabilities, but much higher query latency, with 8.724 seconds per query compared with 0.276 seconds for Qwen3.8-Flash-Next.
- These findings motivate a revisable, feedback-driven control interface for the downstream robotic system.
Method
The authors design MotorMind to connect a frozen general-purpose Vision-Language Model (VLM) to physical robot feedback through a structured harness. Given a natural-language instruction ℓ, the system aims to produce a sequence of robot actions that achieves the requested physical outcome. At each decision cycle t, the harness observes ot=(Tt,rt), where Tt contains available camera images and rt contains the measured robot state, including tool pose and gripper status. To bridge task-level instructions with physical interaction, the Planner constructs an ordered sequence of subgoals G=(g1,…,gM). Each subgoal specifies an intended state change, a target description, and a success criterion.
Instead of generating low-level joint commands, the system exposes parameterized mid-level actions in the robot's base frame. For each cycle, the Executor returns a structured proposal containing an assessment of the current subgoal, a completion signal, an optional action batch, and an expected outcome. An action batch is represented as:
At=(at,1,…,at,Kt),at,k=(τt,k,ηt,k)where τt,k denotes the action type and ηt,k its parameters. The core manipulation primitives include move, rotate, and gripper actions. A deterministic Controller validates these commands, resolves their parameters into Cartesian motion, and records the actual executed movements, ensuring that subsequent proposals are conditioned on fresh observations and measured feedback rather than assumed outcomes.
As shown in the figure below:
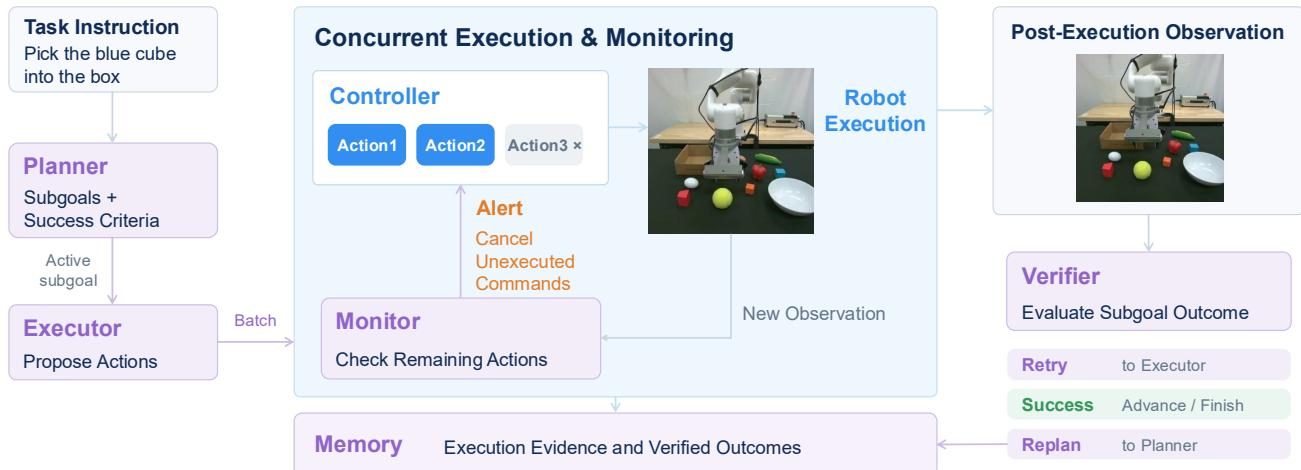
MotorMind assigns five distinct reasoning roles to the same VLM: Planner, Executor, Monitor, Verifier, and Memory. These roles share model capabilities but receive different contexts and possess different output authorities. The Planner translates the instruction into subgoals and revises the unfinished plan when execution evidence necessitates a change. The Executor uses current images, robot measurements, and recent cycle history to propose short action batches for the active subgoal. The Controller then validates and executes the batch, closing the local decision loop.
To evaluate whether the interaction remains consistent with the task, the Monitor watches the running subgoal and reports events such as a wrong target, a dropped object, or a changed scene. Its output is an alert rather than a replacement action. At the end of an attempt, the Verifier assesses the success criterion using observations and robot-state evidence. Directly measured outcomes, such as a lost grasp, can settle an attempt before a model verdict is required. The resulting assessment determines whether the harness advances, retries the subgoal, or requests a revised plan. Finally, Memory condenses execution evidence and assessed outcomes into a compact note for subsequent planning and verification, carrying information across attempts.
The authors implement an asynchronous scheduling mechanism to ensure that background checks do not block the robot. The main execution loop remains sequential, as each proposal depends on the current observation and the next cycle depends on the measured outcome of the batch. However, asynchrony is introduced around this decision loop. The Monitor runs on a background thread throughout a subgoal attempt, examining updated observations periodically. If it detects a critical issue, it issues a STOP alert to cancel the running batch at the next action boundary, discarding pending commands. This interruption prompts a reassessment rather than an immediate failure verdict. Furthermore, after each outcome assessment, the harness requests a memory summary on a background writer. The next subgoal can begin while this summary is still being generated, preserving a sequential chain of motion decisions while allowing scene monitoring and evidence summarization to overlap with ongoing execution.
Experiment
The evaluation combines a diagnostic embodied question-answering benchmark, LIBERO-PRO manipulation suites, adaptive execution scenarios, and physical xArm6 trials. The diagnostic experiment shows that action selection is the weakest VLM capability and that progress and completion judgments remain imperfect, motivating a revisable feedback-driven control interface. Main and adaptive experiments find that this interface enables a frozen general-purpose VLM to outperform zero-shot baselines, match task-fine-tuned policies, and adapt to moving objects, scene shifts, and revised instructions without task-specific training. Real-robot deployment confirms reliable physical execution and error correction, while ablations indicate that planning and replanning are essential and grounding errors remain the dominant failure mode.
MotorMind differs from prior manipulation methods by using a VLM directly for semantic action generation, avoiding learned action policies, generated robot code, and external perception or IK modules. It achieves high pooled success across direct perception and human perturbation settings, with direct perception near perfect and human perturbations only slightly lower. Ablations show the planner is essential, replanning strongly supports recovery, and a stronger reasoning backbone improves success at the cost of longer execution time. Existing methods rely on learned action policies, generated robot code, or extra perception and control modules; MotorMind instead uses the VLM directly for semantic action generation. Removing the planner eliminates task success and removing replanning causes the largest drop among remaining components, while a stronger backbone improves average success but increases wall time.
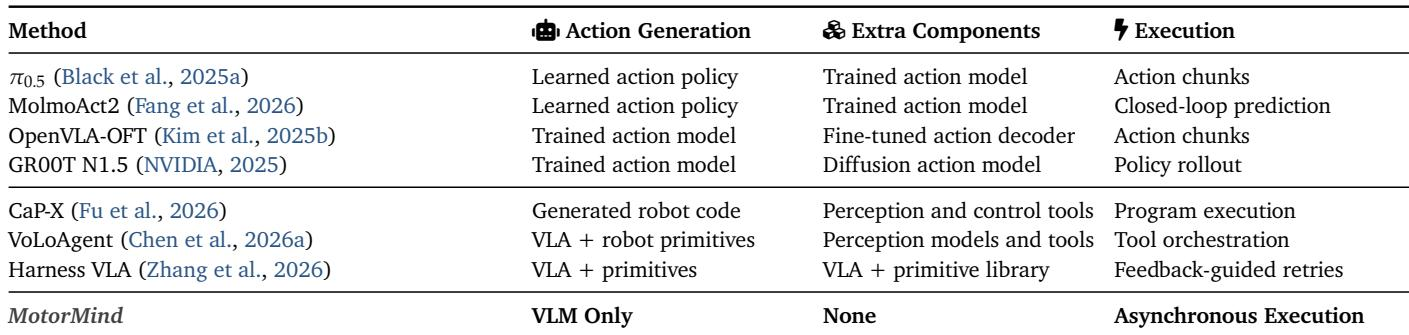
GPT-6 Astra leads all diagnostic categories and overall accuracy, but its mean inference latency is much higher than any other evaluated model. Among faster models, Qwen3.8-Flash-Next and GLM-5.3-Flash offer moderate overall accuracy and comparable performance, while embodied-focused models generally trail in action selection and overall results. Action selection is the weakest capability across most models. GPT-6 Astra achieves the highest accuracy on action selection, progress verification, subgoal completion, and overall questions, but is far slower per query than the other models. Qwen3.8-Flash-Next and GLM-5.3-Flash are the strongest lower-latency models, while embodied-focused models lag particularly on action selection and overall accuracy.
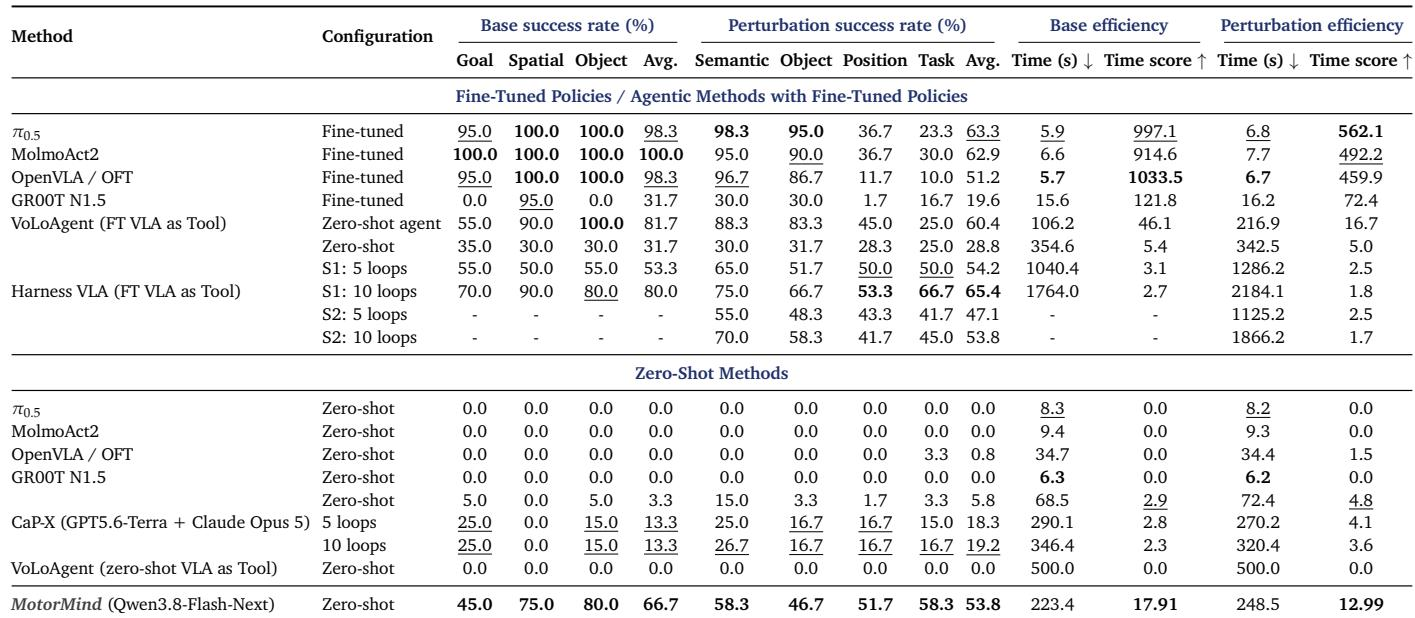
Direct fine-tuned VLA baselines such as π0.5, MolmoAct2, and OpenVLA/OFT achieve near-perfect base success and finish base episodes in under seven seconds, leading to very high time-normalized success scores. Under perturbations, success declines across methods, with Position and Task perturbations causing the largest drops while Semantic and Object perturbations stay comparatively robust; GR00T N1.5 is a clear low-performing exception among direct fine-tuned policies. VoLoAgent with a fine-tuned VLA as a tool reaches moderate success but much longer wall times, so its time-normalized score is far lower than the fast direct fine-tuned VLAs. The top direct fine-tuned VLA policies achieve near-perfect base success and complete base episodes in under seven seconds. Position and Task perturbations cause the steepest declines, while Semantic and Object perturbation success remains relatively high for the strongest fine-tuned VLAs. VoLoAgent with a fine-tuned VLA tool produces moderate success but wall times above 100 seconds, yielding time-normalized scores far below the fastest direct fine-tuned VLAs.
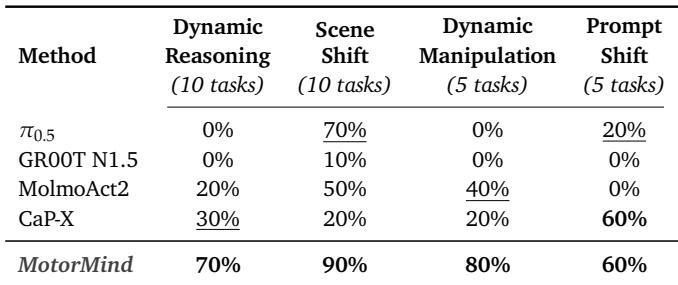
MotorMind leads most adaptive reasoning task groups, achieving the highest success rates in Dynamic Reasoning, Scene Shift, and Dynamic Manipulation. Baseline methods are more uneven, with several near zero on dynamic tasks and only CaP-X matching MotorMind on Prompt Shift. MotorMind records the top success rate in three of four adaptive task groups and ties for the top result in Prompt Shift. Several baseline methods score zero on Dynamic Reasoning and Dynamic Manipulation, while MotorMind reaches substantially higher success in those groups. CaP-X is the only baseline to match MotorMind on Prompt Shift, but it underperforms MotorMind in Scene Shift and Dynamic Manipulation.
MotorMind achieves high zero-shot placement success on a physical robot across explicit object and destination pairings. Performance remains strong under human perturbations, with only modest declines for some object and destination combinations. Semantic understanding tasks are more variable, with some instruction types solved perfectly and others notably lower. Direct perception tasks are highly reliable, with average success near ceiling for both bowl and box destinations. Human perturbation causes only a limited overall drop, though certain placements such as corn to a box and battery to a bowl are more affected. Semantic understanding performance varies widely across instruction types, ranging from perfect success on some tasks to substantially lower success on others.
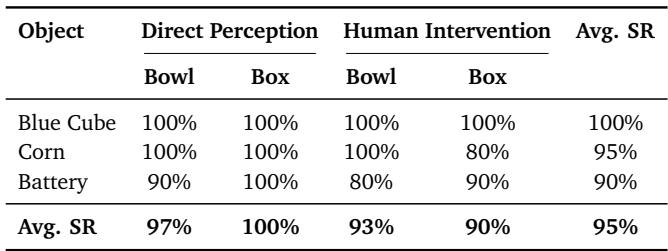
The experiments evaluate MotorMind, a VLM-driven semantic action generator that avoids learned action policies, generated robot code, and external perception or IK modules, across simulated direct perception, human perturbation, adaptive reasoning, and physical robot placement settings. MotorMind achieves near-perfect direct perception success and remains strong under perturbations and dynamic reasoning tasks, while ablations confirm the planner and replanning are essential and that a stronger reasoning backbone improves success at the cost of longer execution time. Direct fine-tuned VLA baselines are fast and accurate on base tasks but decline sharply under position and task perturbations, whereas MotorMind maintains greater robustness. Physical robot tests show highly reliable zero-shot direct placement with only modest perturbation effects, though semantic understanding varies notably across instruction types.