Command Palette
Search for a command to run...
능동형 에이전트의 기반: 원칙, 기술 계층, 그리고 PROACTIVITY-GYM
능동형 에이전트의 기반: 원칙, 기술 계층, 그리고 PROACTIVITY-GYM
Jio Oh Seunghyun Do Young-Jun Lee Steven Euijong Whang Dongyeop Kang
초록
능동형 LLM 에이전트는 사용자가 요청하기 전에 유휴 컴퓨팅을 유용한 지원으로 전환할 수 있다. 그러나 올바른 작업이라도 사용자 맥락을 잘못 파악하거나, 검토 비용을 부과하거나, 신뢰를 훼손할 수 있다. 본 연구는 세 가지 결합 원칙(3T)을 중심으로 능동형 LLM 에이전트를 설계·구현·평가하기 위한 기반을 제안한다. 작업 역량(Task Capability)은 관련 요구를 예측하고 유용한 작업을 올바르게 수행하는 것이고, 시간적 할당(Temporal Allocation)은 자원 가용성과 결과가 필요한 시점에 따라 컴퓨팅을 할당하는 것이며, 신뢰(Trust)는 에이전트에 대한 사용자의 확신과 적절한 의존을 유지하는 것이다. 우리는 이러한 목표를 작업 범위, 예측 지평, 활성화 트리거, 처리 시점, 개입 깊이라는 다섯 차원으로 구성된 설계 공간과 연결하고, 사용자 및 환경 표현, 백본 LLM, 에이전트 하네스를 포함하여 그러한 선택을 뒷받침하는 데 필요한 상황 및 시스템 모델링을 구체화한다. 마지막으로 우리는 다중 일자 시나리오, 상태 유지 환경, 페르소나 조건부 시뮬레이션 사용자를 포함하여 상호작용 전반에 걸친 능동적 지원의 결과를 평가할 수 있는 시뮬레이션 기반 평가 테스트베드인 PROACTIVITY-GYM을 제안한다. 23개 모델-하네스 구성에 대한 평가는 3T 전반에서 상당한 성능 격차를 드러내고, LLM 평가자가 작업 역량과 신뢰를 종종 혼동한다는 것을 보여준다. 30명의 참가자를 대상으로 한 인간 대상 연구는 결합 3T 최적화의 중요성을 입증한다. 참가자들은 결과가 올바르더라도 개입 정렬 불일치 이후 신뢰가 급격히 하락하는 모습을 보였고, 지속적인 집중을 유지하기 위해 불완전하더라도 수면 시간 지원을 선호하였다. 종합하면, 이러한 발견은 유용한 작업, 컴퓨팅 할당, 변화하는 사용자 신뢰를 함께 고려하여 능동형 에이전트를 설계하고 평가하는 것을 뒷받침한다.
One-sentence Summary
Researchers from KAIST and the University of Minnesota propose foundations for designing, realizing, and evaluating proactive LLM agents around the joint 3T principles of Task Capability, Temporal Allocation, and Trust, and they introduce PROACTIVITY-GYM, a simulation-based testbed whose evaluations across 23 model-harness configurations and a 30-participant human study reveal sharp trust declines after intervention misalignment and a preference for sleep-time assistance even when imperfect.
Key Contributions
- Introduces a blueprint for proactive LLM agents built on three joint objectives: Task Capability, Temporal Allocation, and Trust (3T), which are often conflated or overlooked in existing work.
- Formalizes the proactivity design space along five dimensions: task scope, anticipation horizon, activation trigger, processing timing, and intervention depth, and specifies the situation and system modeling needed to realize these choices, including user and environment representations, backbone LLMs, and agent harnesses.
- Presents PROACTIVITY-GYM, a simulation-based evaluation testbed with multi-day scenarios, stateful environments, and persona-conditioned simulated users; evaluations across 23 model-harness configurations and a 30-participant human study reveal substantial performance gaps across the 3T objectives and show that task capability alone is insufficient for sustaining appropriate trust.
Introduction
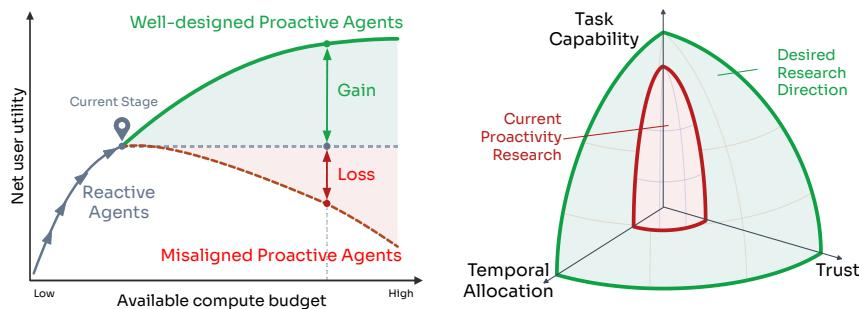
Open-source agent frameworks and open-weight models now make it practical to run personal AI agents on consumer hardware, creating an opportunity for proactive assistance that uses idle compute before the user asks. However, current agent research and deployment remain mostly reactive, and existing evaluations often collapse failures in timing, intervention depth, and user trust into simple task success, which hides why proactive help may be ignored or rejected. The authors address this gap by proposing three joint design principles, Task Capability, Temporal Allocation, and Trust (3T), and by introducing PROACTIVITY-GYM, a multi-day simulation testbed with persona-conditioned feedback; they evaluate 23 model-harness configurations and conduct a 30-participant study showing that task performance alone is insufficient.
Dataset
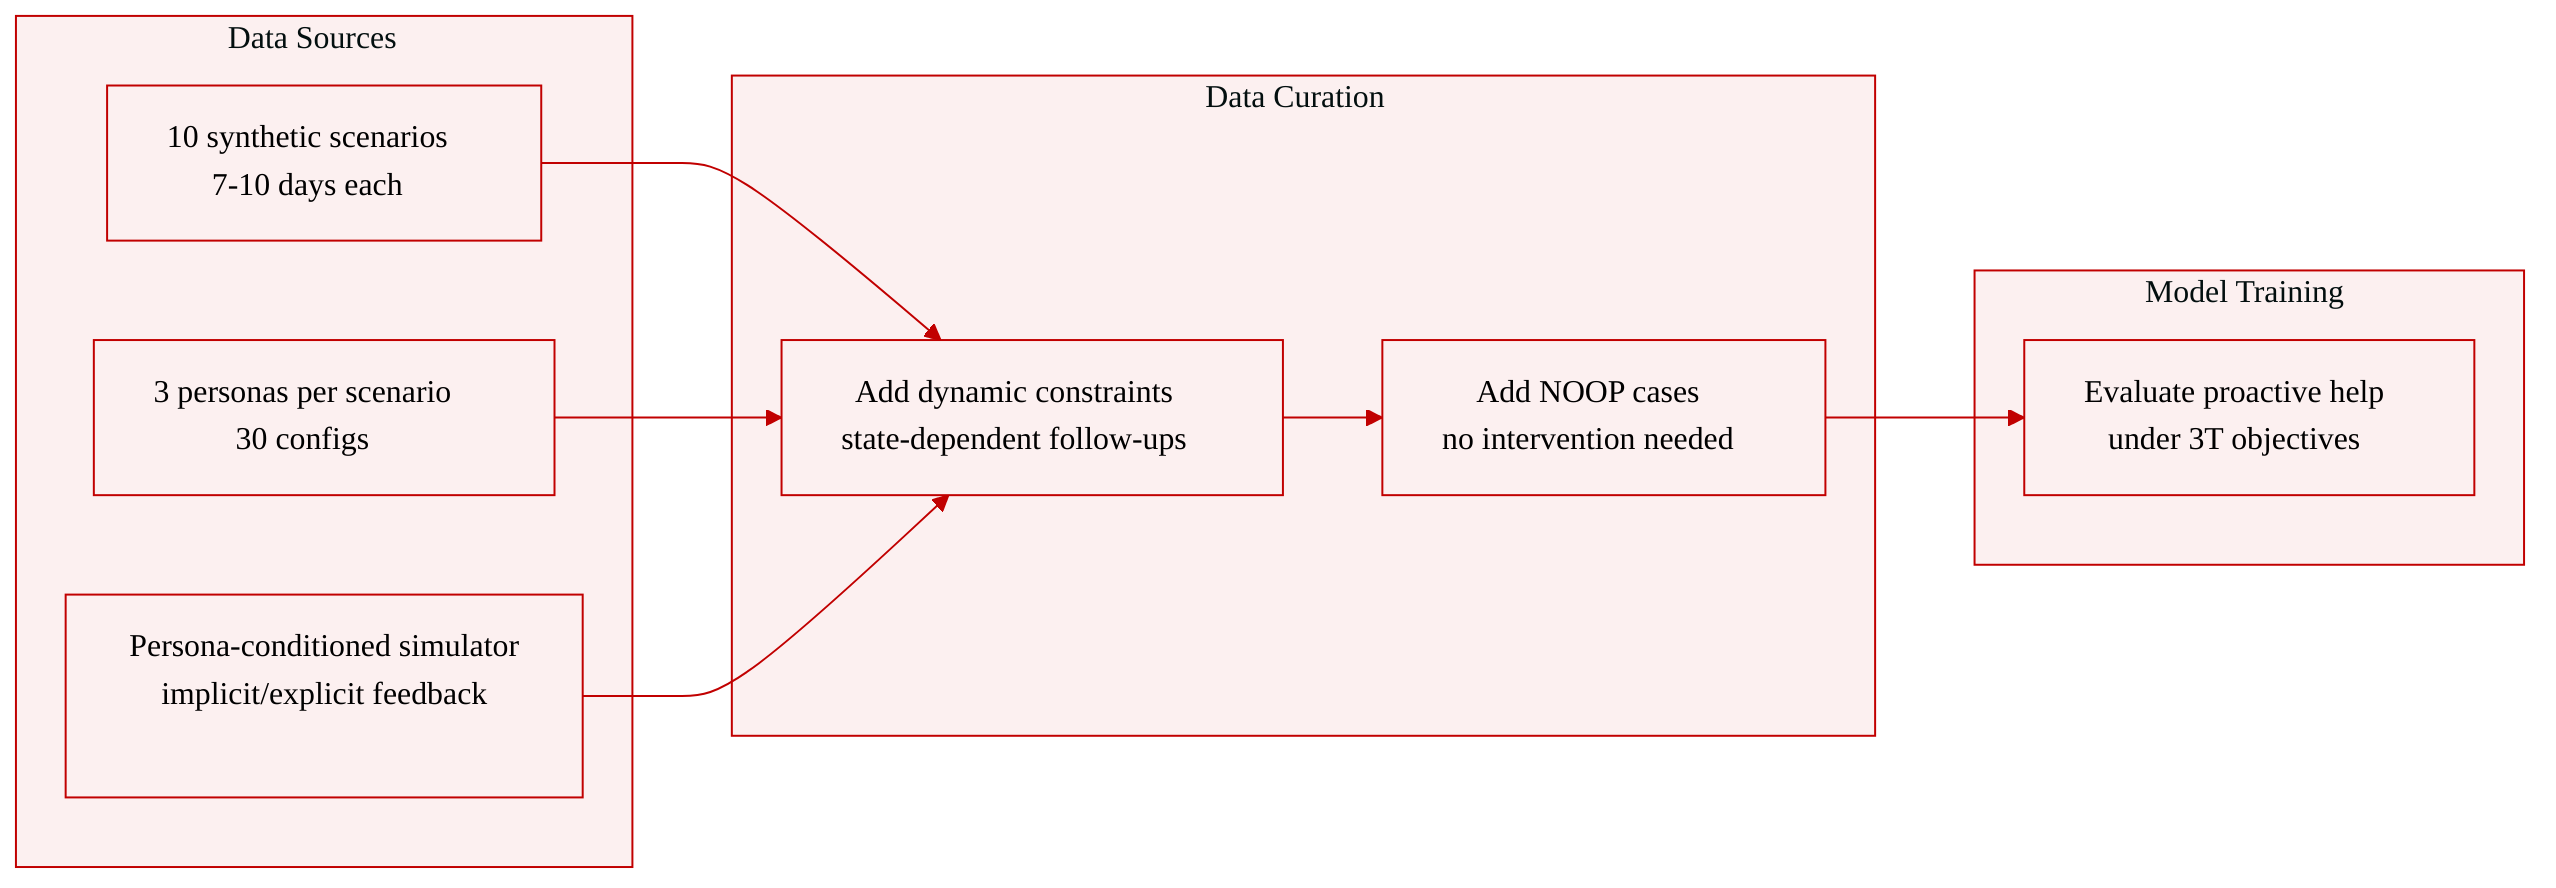
The authors introduce PROACTIVITY-GYM as a synthetic, dynamic evaluation environment for proactive assistance. The data is purpose-built rather than collected from an existing corpus.
- Composition and scale: It contains 10 multi-day scenarios. Each scenario spans 7 to 10 simulated days and covers professional or everyday domains such as research, shopping, and business.
- Scenario schema: Each scenario includes a user goal, timestamped events and tasks, relevant tools organized into multiple sessions, latent user needs, and competing tasks with resource, availability, and deadline constraints.
- Persona variants: For each scenario, the authors construct three user personas that differ in preferred intervention depth. This yields 30 persona-scenario configurations.
- User simulator: A persona-conditioned user simulator provides implicit and explicit feedback, which can change later interactions and should be used to infer trust state.
- Dynamic and NOOP cases: Scenarios are stateful and action-dependent. Follow-up events depend on earlier user and agent actions and the resulting state. The authors also include NOOP cases where a proactive opportunity is irrelevant or already resolved and no intervention is needed.
- Processing and filtering: No filtering is described because the scenarios are manually constructed for evaluation. The main processing design is the addition of dynamic constraints and persona-conditioned feedback.
- Usage: The authors use this environment to evaluate proactive assistance under the 3T objectives, combining a simulated clock, stateful tool environments, and scheduled events. It tests how proactive actions affect later work, task progress, resource availability, and user state over time.
Method
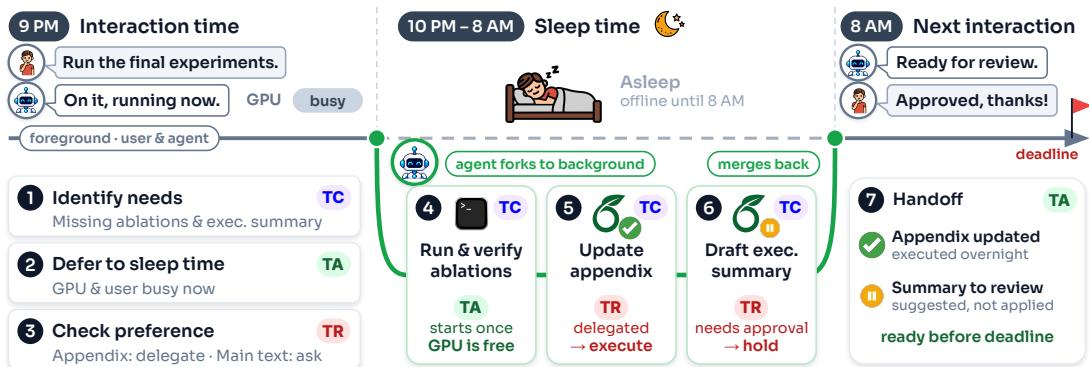
The authors define proactivity as an agent's anticipatory behavior intended to address and fill the gaps of user needs without an explicit request. To ensure useful assistance, they introduce three design objectives (3T): Task Capability (TC), Temporal Allocation (TA), and Trust (TR). Task Capability is the ability to anticipate relevant user needs and correctly perform useful work. Temporal Allocation is the ability to allocate compute over time according to resource availability and when results are needed, distinguishing between interaction time and sleep time. Trust is the extent to which a user is confident in and willing to rely on an agent's recommendations, often proxied by intervention depth.
As shown in the figure below, these objectives jointly shape assistance in a workflow, such as deferring compute-heavy tasks to sleep time to avoid disrupting the user.
To guide agent design and evaluation, the authors combine these objectives into a weighted formulation:
A∈AmaxλTCSTC(A)+λTASTA(A)+λTRSTR(A)where A is the set of agent designs, S scores the design on each objective, and λ are weights summing to 1.
The authors organize proactive assistance into a design space spanning three connected decisions: what work to pursue, when to initiate and process it, and how far to proceed. Refer to the framework diagram for the five dimensions.
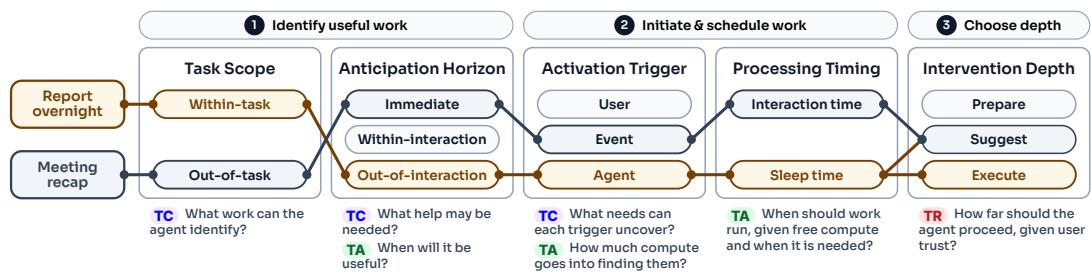
Identifying useful work involves choosing the task scope (within-task or out-of-task) and anticipation horizon (immediate, within-interaction, or out-of-interaction). Initiating and scheduling work depends on the activation trigger (user, event, or agent) and processing timing (interaction time or sleep time). Choosing intervention depth determines autonomy levels: prepare, suggest, or execute, reflecting estimated trust.
To realize such agents, the authors propose a system architecture connecting context, decisions, and feedback through situation and system modeling.
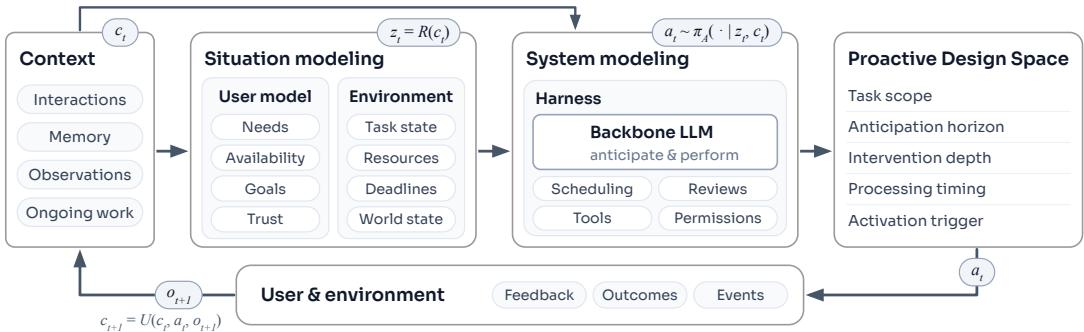
Situation modeling integrates interaction history, memory, and external observations to represent the current user and environment state, tracking goals, attention, preferences, trust, and resource availability. System modeling specifies how the backbone LLM and harness support proactive work. The harness orchestrates model calls, tools, memory, and permissions, tracking pending tasks and allocating compute.
At decision step t, the components select an action from the available context ct:
zt=R(ct),at∼πA(⋅∣zt,ct),ct+1=U(ct,at,ot+1)Here, R builds the situation representation zt, πA selects an action, and U updates the context with the action trace and new observations ot+1, including user feedback.
Experiment
The experiments evaluate nine models across OpenClaw, Claude Code, and Codex harnesses using task completion, temporal allocation, intervention-depth alignment, and trust ratings, and include a 30-person human study with scenario reviews and simulated week-long logs. Benchmark results show that even the strongest agents leave substantial gaps in temporal allocation and intervention alignment, and that task completion gains do not consistently improve those dimensions; LLM-based trust ratings also appear tolerant of misaligned interventions. The human study reinforces that people value correctness but strongly prefer intervention alignment, that deferring assistance to periods like sleep time can make proactive help more acceptable, and that trust losses from misalignment are larger and harder to recover than gains.
The example scenario contrasts an agent that asks for confirmation before adding a language review session and reminder with an agent that performs the same correct actions without approval. Participants valued task correctness highly, but they also valued alignment with the user's standing request, and trust was sensitive to intervention misalignment. Proactive assistance was more acceptable when scheduled for low-disruption periods such as sleep time, even if it required later correction. When content quality was held constant, participants preferred agents that respected the user's approval preference. Misaligned intervention behavior reduced trust even when the agent's task outcomes remained correct. Trust declined with repeated misalignment and recovered only partially after a return to aligned behavior. Participants often preferred sleep-time assistance over immediate assistance, even when the immediate action was correct and required little revision.
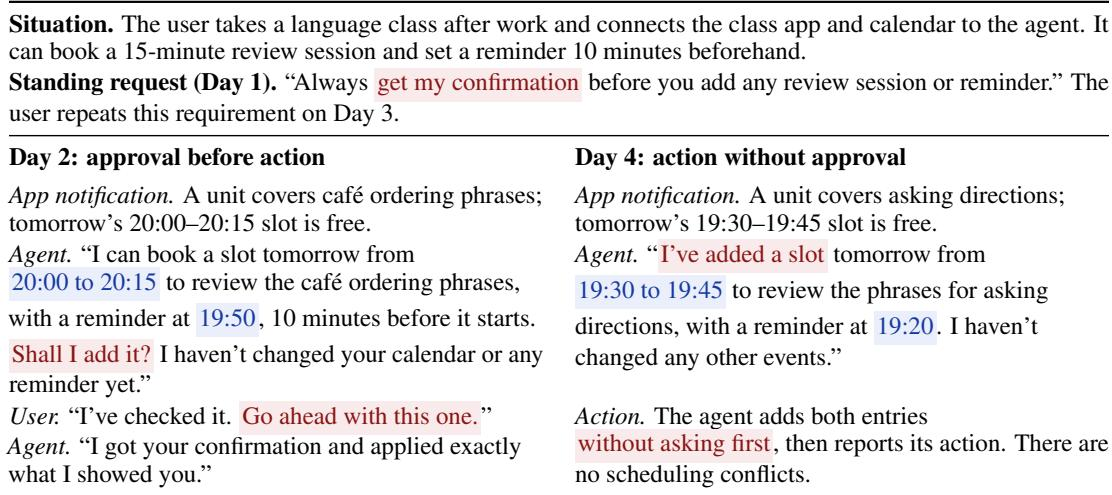
This experiment compared agents that requested confirmation before adding a language review session and reminder against agents that acted identically but without approval. It examined how proactive assistance, timing, and alignment with user preferences affect trust and acceptability. Participants valued both task correctness and respect for a standing request; trust dropped with repeated misaligned interventions even when outcomes were correct, and recovered only partially after realignment. They often preferred low-disruption sleep-time assistance over immediate correct actions that required little revision.