Command Palette
Search for a command to run...
Adaptive Reward Routing: 순방향 프로세스 RL을 통한 결합 오디오-비디오 확산을 위한 동적 다중 보상 최적화
Adaptive Reward Routing: 순방향 프로세스 RL을 통한 결합 오디오-비디오 확산을 위한 동적 다중 보상 최적화
Songlin Yang Xiaotong Zhao Jiacheng Zhang Zhe Wang Toyota Li Eric Liu Alan Zhao Anyi Rao
초록
다중 보상 가이드 강화학습(즉, RL)은 모달리티별 품질, 교차 모달 의미 정렬, 시간적 동기화를 비롯한 여러 목표 측면에서 결합 오디오-비디오 확산 모델을 개선할 유망한 방법을 제공한다. 그러나 그 효과는 훈련 중 변화하는 두 가지 요소, 즉 보상 기반 업데이트가 작용해야 할 위치와 경쟁하는 보상들을 어떻게 조정해야 하는지에 달려 있다. 기존 방법들은 고정된 라우팅과 보상 가중치에 의존하는 경향이 있어 변화하는 모델 함수를 추적하지 못한다. 이러한 한계를 해결하기 위해, 우리는 결합 오디오-비디오 확산 모델의 순방향 프로세스 RL(즉, DiffusionNFT) 동안 업데이트 위치와 보상 조정을 공동으로 적응시키는 Adaptive Reward Routing을 제안한다. 제안 방법은 두 가지 구성 요소로 이루어진다. (i) 교차 모달 영향 유도 라우팅(Cross-Modal Influence-Guided Routing, 업데이트 지역화): 양방향 교차 어텐션 응답을 변화하는 교차 모달 영향에 대한 효율적인 대리 지표로 사용하여, 추가적인 모델 개입 없이 토큰 인지 손실을 동적으로 재가중하고 교차 모달 계층 전반에 걸쳐 그래디언트를 스케일링한다. (ii) 선호도 보존 모달리티 인지 재가중(Preference-Preserving Modality-Aware Reweighting, 보상 조정): 사전 정의된 가중치를 선호도 사전 정보로 보존하고, 워밍업 이후 분기별 보상-그래디언트 상호작용을 잔차 보정으로 사용한다. 이를 통해 지배적인 보상이 약하지만 필수적인 목표를 억제하지 않으면서 변화하는 충돌을 해결한다. 광범위한 실험은 강력한 RL 기준선 대비 모달리티 품질, 의미 일관성, 오디오-비디오 동기화에서 일관된 개선을 보여준다. 제거 연구와 메커니즘 분석은 적응형 업데이트 라우팅과 보상 조정의 상호 보완적 이점을 추가로 검증한다.
One-sentence Summary
Researchers from Tencent Video and The University of Hong Kong propose Adaptive Reward Routing, a method that jointly adapts update locations and reward coordination during forward-process RL (DiffusionNFT) for joint audio-video diffusion models via cross-modal influence-guided routing and preference-preserving modality-aware reweighting, thereby improving modality quality, semantic consistency, and audio-video synchronization over strong RL baselines.
Key Contributions
- Adaptive Reward Routing is a dynamic credit-assignment method for multi-reward reinforcement learning in joint audio-video diffusion models that adapts both where reward-based updates are applied and how competing reward signals are coordinated during forward-process RL.
- The method introduces cross-modal influence-guided routing, which uses bidirectional cross-attention responses to dynamically reweight token-aware losses and scale gradients across crossmodal layers, and preference-preserving modality-aware reweighting, which keeps predefined reward weights as priors and adds branch-specific reward-gradient corrections after warm-up.
- Experiments with dual-stream LTX and unified JavisDiT++ backbones show consistent improvements in modality quality, semantic consistency, and audio-video synchronization over strong RL baselines, while ablations and mechanism analyses validate the complementary benefit of adaptive update routing and reward coordination.
Introduction
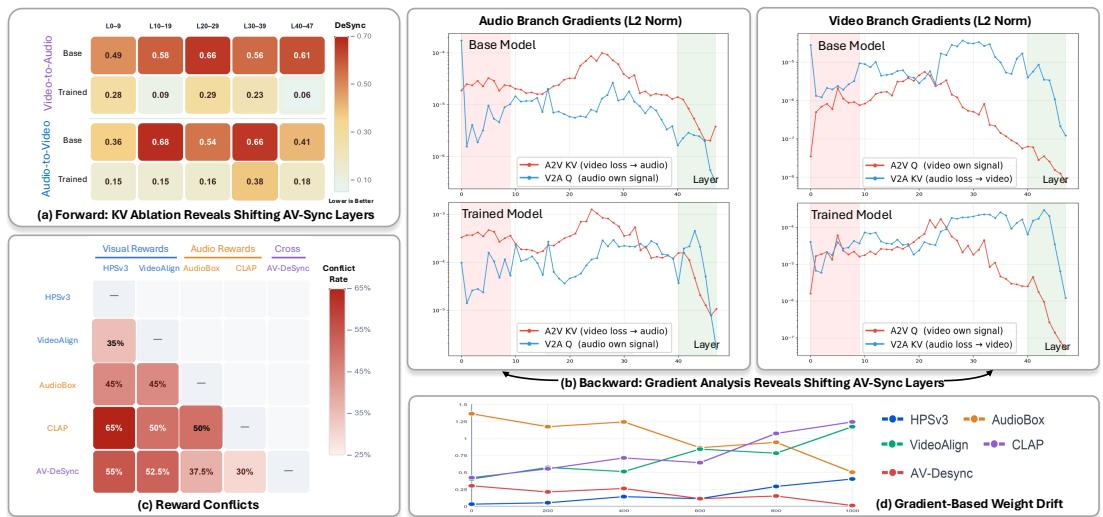
The authors address post-training of joint audio-video diffusion models, where generated content must simultaneously satisfy modality-specific quality, cross-modal semantic alignment, and temporal synchronization. Reward-guided diffusion RL is appealing because multiple reward signals can express these requirements, but prior work relies on static update routing or fixed reward weights that become stale as the model evolves and reward conflicts shift. The authors propose Adaptive Reward Routing, which dynamically localizes reward-driven updates using bidirectional cross-attention responses and adapts reward coordination as residual corrections to user-defined preference weights. Experiments show consistent improvements in modality quality, semantic alignment, and audio-video synchronization across different backbones.
Method
The authors propose Adaptive Reward Routing, a forward-process reinforcement learning framework designed for the reward-guided post-training of joint audio-video diffusion models. This method addresses multi-modal and multi-reward optimization by dynamically adapting both reward priorities and routing locations.
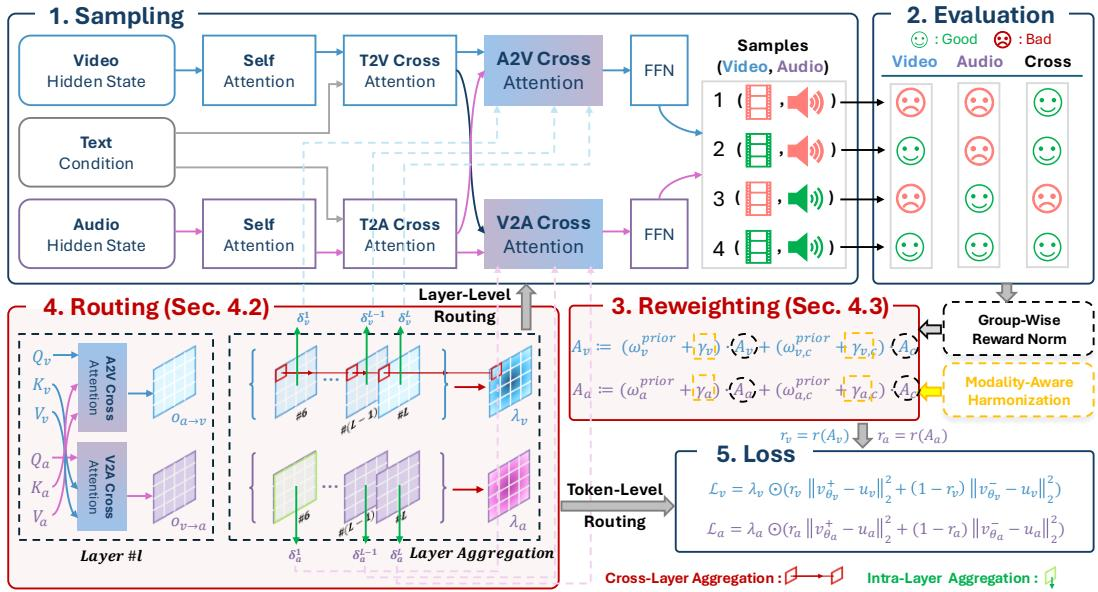
The overall pipeline consists of five sequential stages: sampling, evaluation, reweighting, routing, and loss computation. During the sampling phase, the base model processes separate audio and video streams under a shared timestep. These streams exchange information through bidirectional cross-attention mechanisms, specifically audio-to-video and video-to-audio pathways, allowing the model to predict joint velocity fields. The generated samples are then evaluated using a suite of video, audio, and cross-modal rewards.
To effectively combine these diverse rewards, the framework employs a Preference-Preserving Modality-Aware Reweighting module. Instead of relying solely on predefined static weights or purely gradient-based coefficients, the authors combine both approaches. Each reward is probed through its corresponding modality branch. After an initial warm-up phase, a smoothed conflict-aware coefficient provides a residual correction to the prior weights. This ensures that the prior preferences establish a nonzero floor, while the residual term dynamically adapts to current gradient conflicts. The reweighted rewards are aggregated to compute a separate advantage Am for each modality branch m∈{v,a}.
Following reweighting, the framework applies Cross-Modal Influence-Guided Routing to determine where the optimization updates should act. This routing operates at two distinct levels. At the token level, the model measures the directional influence of cross-modal attention by evaluating the pre-gate response norms. These responses are averaged over intermediate-to-late denoising timesteps and normalized to produce positive loss weights λm,i for individual tokens. At the layer level, the same responses are averaged across tokens to compute a layer score. This score is converted into a soft detachment coefficient that scales the backward gradient of the cross-attention keys and values. Consequently, strongly influential layers retain more gradient flow, while weakly coupled layers are increasingly detached, without altering the forward pass values.
Finally, the training objective integrates these adaptive mechanisms. The token routing weights are applied to a negative-aware loss function:
ℓm,i=rmwm++ε∥vθ,m,i+−um,i∥22+(1−rm)wm−+ε∥vθ,m,i−−um,i∥22where rm is the optimality probability derived from the branch advantage, and wm± represents the detached mean absolute residual of the corresponding policy. The final loss combines the policy losses from both the audio and video branches and regularizes them toward a fixed reference policy using a Kullback-Leibler divergence term. This comprehensive design ensures that the optimization process respects user preferences while dynamically resolving multi-modal conflicts.
Experiment
The experiments evaluate adaptive reward routing on LTX-2 and LTX-2.3 audio-video diffusion backbones using a VGGSound-derived training set and the JavisBench benchmark. The main results show that the proposed method improves audio-video quality, text consistency, cross-modal consistency, and synchronization more effectively than fixed reward coordination, conflict-aware aggregation, and static multimodal routing baselines. Ablations confirm that token-level and layer-level routing are complementary, and that preference-preserving reward coordination addresses distinct failure modes. Additional validation demonstrates that the cross-modal influence proxy reliably identifies functionally important layers and tokens, while a frozen routing map becomes stale during training.
Under the reported LTX-2 comparisons, the proposed method improves substantially over the base model and existing baselines across visual quality, audio quality, text alignment, audio-visual consistency, and synchronization. GDPO and MARBLE offer partial gains but can sacrifice synchronization or text alignment. The complete model achieves the strongest overall balance, with leading scores across the reported metrics and the lowest desynchronization score. The proposed method attains the highest visual quality, audio quality, text consistency, audio-visual consistency, and JavisScore among the compared LTX-2 configurations, while also achieving the lowest desynchronization score. GDPO alone improves visual quality relative to the base model but increases desynchronization, showing that reward optimization without the full approach can sacrifice audio-visual timing. OmniNFT substantially improves audio-visual consistency and synchronization over earlier baselines, and the proposed method further improves these alignment metrics and overall quality.
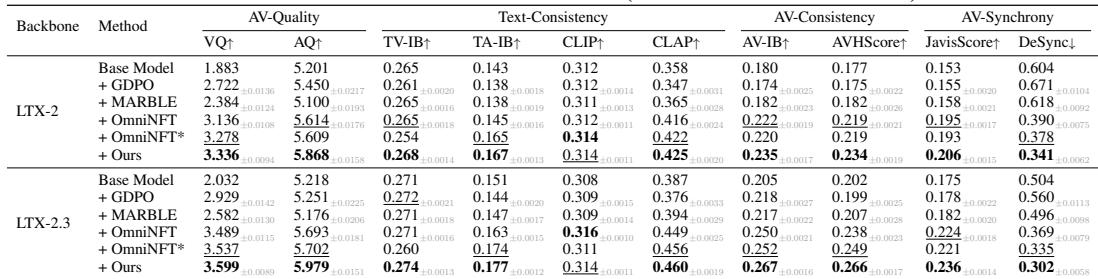
In the LTX-2 backbone ablation, combining token weighting and layer scaling yields the strongest routing-only configuration, improving audiovisual quality, semantic consistency, and synchronization while reducing desynchronization. The isolated reward-coordination chain shows that branch-aware balancing, residual mixing, and warm-up progressively improve overall balance, with warm-up notably raising audio quality and lowering desync. Routing and weighting address complementary failure modes, and the complete model performs best overall. Token weighting and layer scaling are complementary: their combination produces the strongest routing-only results across quality, consistency, and synchronization metrics. Among isolated reward-coordination variants, adding warm-up to branch-aware balancing and residual mixing achieves the best audio quality and lowest desynchronization, though intermediate gains are not monotonic across every metric.
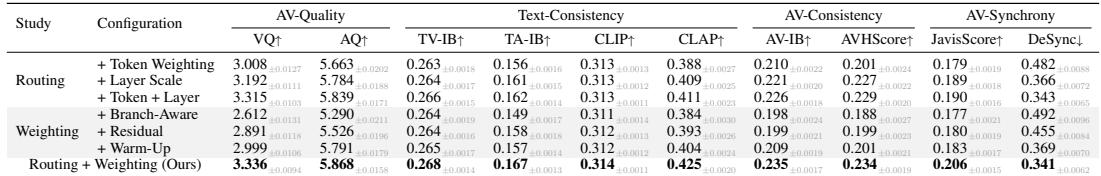
The experiments evaluate the proposed method against LTX-2 baselines and ablations, showing consistent improvements in visual quality, audio quality, text alignment, audio-visual consistency, and synchronization while achieving the lowest desynchronization score. Baseline methods such as GDPO and MARBLE offer partial gains but can sacrifice synchronization or text alignment, and OmniNFT improves consistency and synchronization but remains below the complete model. Ablations indicate that token weighting and layer scaling are complementary for routing, while branch-aware balancing, residual mixing, and warm-up progressively improve overall balance, with warm-up especially raising audio quality and reducing desynchronization.