Command Palette
Search for a command to run...
LLM 포스트 트레이닝의 일반화를 뒷받침하는 온폴리시 파라미터 업데이트 방향
LLM 포스트 트레이닝의 일반화를 뒷받침하는 온폴리시 파라미터 업데이트 방향
Shufan Shen Zhongni Hou Junshu Sun Yufei Zhang Wei Lin Guojun Yin Qingming Huang Shuhui Wang
초록
온폴리시 포스트 트레이닝 패러다임의 뛰어난 일반화 성능은 이러한 패러다임의 파라미터 업데이트 양상에 대한 연구들을 촉진해 왔다. 그러나 기존 연구들은 관찰된 양상을 온폴리시 학습의 부산물로만 취급할 뿐, 지도형 미세 조정(supervised fine-tuning, SFT)과 같은 다른 패러다임의 일반화를 개선하기 위한 최적화 원리로 활용될 가능성을 간과한다. 이러한 한계를 해결하기 위해, 우리는 그러한 개선을 달성할 수 있는 특정 온폴리시 업데이트 양상이 존재하는지 조사한다. 먼저, 우리의 이론적·실험적 분석은 SFT가 일관된 방향으로 파라미터를 업데이트하는 반면, 온폴리시 패러다임은 학습 중에 방향을 지속적으로 조정한다는 것을 보여준다. 이러한 차이에 착안하여, 우리는 유망한 양상으로서 각 파라미터의 누적 업데이트 방향에 주목한다. 이어서, SFT 업데이트를 온폴리시 패러다임이 식별한 방향으로 제한하는 온폴리시 방향 제약형 지도 미세 조정(On-Policy direction-constrained Supervised Fine-Tuning, OPSFT)을 제안하여 일반화 개선 효과를 평가한다. OPSFT의 강력한 성능은 온폴리시 패러다임의 일반화 이점이 파라미터 업데이트 방향을 통해 SFT로 전이될 수 있음을 시사한다. 그러한 방향이 식별되면, SFT조차도 이 방향으로 업데이트를 제한한 채 일반화할 수 있다. 이 발견은 온폴리시 패러다임의 강력한 일반화와 높은 학습 효율성 및 고품질 궤적 활용 능력을 포함한 SFT의 장점을 결합함으로써 두 가지 실용적 이점을 제공한다. 효율성을 위해, 우리는 소수의 온폴리시 학습 단계를 사용하여 강력한 일반화를 지원하는 업데이트 방향을 식별하고, 이후 OPSFT를 적용하여 높은 학습 효율성을 달성한다. 고품질 궤적 활용 측면에서, OPSFT는 이러한 궤적을 활용하여 온폴리시 학습에서 학습된 능력을 저해하지 않으면서 해당 업데이트 방향을 따라 사후 학습된 모델을 계속 개선할 수 있다.
One-sentence Summary
Researchers at the Chinese Academy of Sciences, the University of Chinese Academy of Sciences, and Meituan propose On-Policy direction-constrained Supervised Fine-Tuning (OPSFT), which constrains supervised fine-tuning (SFT) updates to the cumulative parameter update directions identified by on-policy paradigms, transferring on-policy generalization to efficient SFT while enabling the use of high-quality trajectories.
Key Contributions
- The paper identifies a distinguishing parameter-update behavior: supervised fine-tuning updates parameters along consistent directions, whereas on-policy post-training continuously adjusts update directions during training.
- The paper proposes On-Policy direction-constrained Supervised Fine-Tuning (OPSFT), which constrains SFT updates to the cumulative direction identified by on-policy training; OPSFT achieves performance comparable to the corresponding on-policy paradigm, indicating that the on-policy generalization advantage transfers through update direction.
- The paper demonstrates two practical benefits: a few on-policy training steps identify directions that support strong generalization for efficient OPSFT training, and OPSFT uses newly acquired high-quality trajectories to improve a post-trained model without disrupting previously learned on-policy behavior.
Introduction
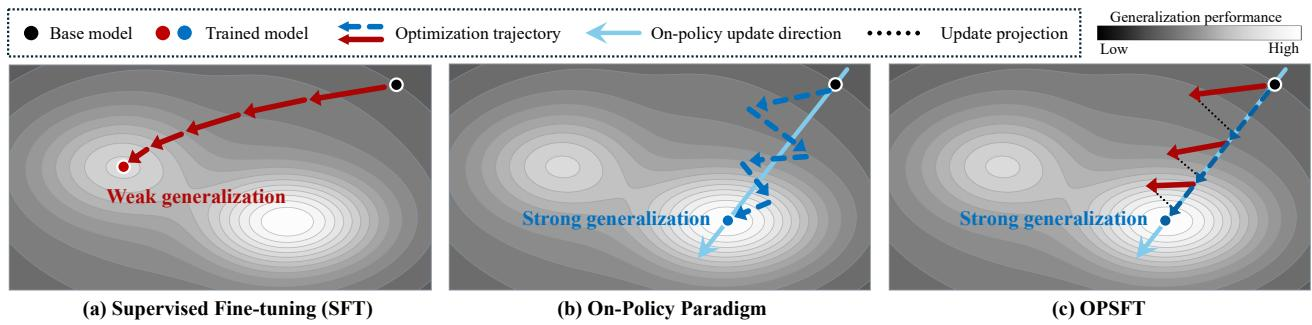
On-policy post-training has become an important approach for improving large language model reasoning because it optimizes models on their own generated responses rather than fixed supervised fine-tuning (SFT) targets, and it often generalizes more strongly across tasks. Prior work has examined isolated components such as reverse KL divergence, negative samples, and sparse update locations, but these studies generally treat on-policy update behavior as a byproduct instead of testing whether it can become an optimization principle. That leaves a gap between explaining on-policy generalization and translating those explanations into practical improvements for SFT. The authors bridge this gap by analyzing parameter update direction and find that on-policy training keeps adjusting update directions while SFT stays directionally consistent. They propose On-Policy direction-constrained SFT (OPSFT), which retains SFT but restricts each parameter update to the direction identified by on-policy training. Experiments show that OPSFT substantially outperforms vanilla SFT and reaches performance comparable to the on-policy paradigm, indicating that on-policy update direction can transfer generalization benefits to more efficient SFT.
Method
The authors explore whether an on-policy parameter update behavior can transfer the generalization advantage of on-policy paradigms to Supervised Fine-Tuning (SFT). They investigate the direction, specifically the sign, of parameter updates and its evolution throughout training.
To understand the different behaviors in parameter update direction, the authors compare the gradient formulations of on-policy paradigms and SFT. Given an input prompt x, a response trajectory τ, and the current policy πθ with parameters θ∈Rd, the gradient of the trajectory log-probability with respect to parameters θ is computed as:
sθ(x,τ)=∇θlogπθ(τ∣x)For every input prompt x, sθ(x,τ) has zero conditional expectation:
Eτ∼πθ(⋅∣x)[sθ(x,τ)]=τ∑πθ(τ∣x)∇θlogπθ(τ∣x)=∇θτ∑πθ(τ∣x)=0dwhere 0d∈Rd denotes the zero vector. The policy gradient of on-policy paradigms is represented as:
gon(θ)=Ex,τ∼πθ(⋅∣x)[Aθ(x,τ)sθ(x,τ)]where Aθ(x,τ)∈R is the advantage of trajectory τ for prompt x. The projection of gon(θ) onto an arbitrary sign vector v∈{−1,0,1}d can be formulated as the projection onto v of the covariance between Aθ(x,τ) and sθ(x,τ):
v⊤gon(θ)=Ex[v⊤Covτ∼πθ(⋅∣x)[Aθ(x,τ),sθ(x,τ)]]For SFT, the projection of their gradients along v is:
v⊤gsft(θ)=−Ex[v⊤Eτ∼πteacher(⋅∣x)[sθ(x,τ)]]By comparing these equations, the authors find that SFT updates parameters along the direction of sθ(x,τ) where trajectories are typically sampled from a fixed distribution πteacher. In contrast, on-policy paradigms update parameters toward the direction of the covariance matrix between the advantages and the trajectory gradients. Since trajectories are sampled from the current policy πθ that evolves during training, the distribution of advantages changes with πθ. Consequently, the parameter update direction of on-policy paradigms changes with the evolving advantage distribution throughout training.
To verify this theoretical analysis, the authors measure the cosine similarity among update directions at different training steps. As shown in the figure below:
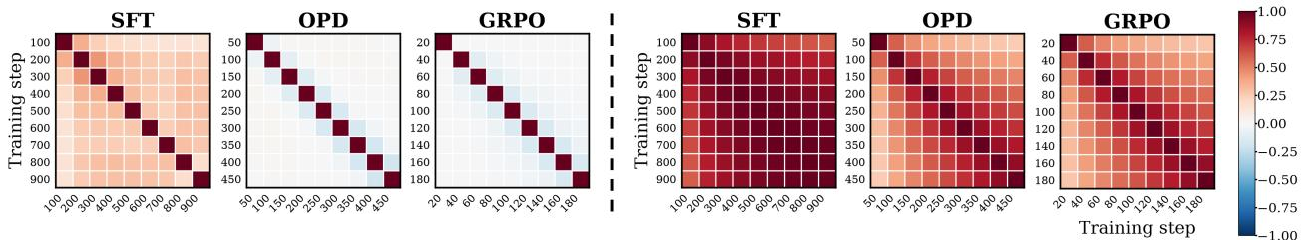
For interval updates, SFT optimizes towards positively correlated directions, while on-policy paradigms explore nearly orthogonal directions at different training stages. The accumulation of these interval updates leads to substantially different cumulative update directions. For cumulative updates, SFT exhibits highly similar directions throughout training with cosine similarity close to 1.0, whereas on-policy paradigms exhibit positive yet substantially lower correlation with cosine similarity around 0.5. These analyses suggest that unlike SFT, which updates parameters along nearly consistent directions, on-policy paradigms tend to continuously adjust their cumulative parameter update directions throughout training.
Inspired by the continuous efforts to adjust update directions in on-policy paradigms, the authors investigate whether the resulting cumulative on-policy update direction can serve as an effective optimization principle for transferring their generalization advantage to SFT. Specifically, they constrain parameter updates in SFT to the directions identified by on-policy paradigms. Given the parameters before and after on-policy training (θbase,θon), they obtain the sign vector v=sign(θon−θbase)∈{−1,0,1}d that determines the direction of the cumulative update. They constrain the gradient g∈Rd of SFT according to v as follows:
gs=I(sign(−g)=v)⊙gwhere ⊙ denotes the Hadamard product, sign(⋅) is the element-wise sign operator, and I(⋅) represents the indicator function that retains gradient elements whose signs match v while discarding others. The constrained gradient gs is then passed to the optimizer for gradient descent. By constraining the gradient at each training step, the parameter updates consistently follow the directions identified by the on-policy paradigm. In practice, considering that the regularization terms inherent to the optimizer may affect the imposed constraint, the authors further constrain the update direction after each optimizer step. They refer to this On-Policy direction-constrained SFT as OPSFT.
Motivated by the ability of the on-policy update direction to support strong generalization, the authors further leverage this direction to combine the generalization advantage of on-policy paradigms with the advantages of SFT. First, they perform a small number of GRPO steps to identify an update direction that supports strong generalization, and then apply OPSFT to achieve efficient training. Second, given a model post-trained by an on-policy paradigm, they conduct OPSFT along its original update direction, thereby leveraging newly acquired high-quality trajectories to further improve the model without disrupting the capabilities learned during on-policy training.
Experiment
The experiments evaluate whether the generalization benefits of on-policy post-training can be transferred to supervised fine-tuning by sharing parameter update directions, using Qwen and DeepSeek models on math and code reasoning datasets. Compared with vanilla SFT and constraints based only on update locations, constraining SFT updates along on-policy directions achieves performance comparable to or better than GRPO while reducing training time and transferring reasoning capabilities to in-domain and out-of-domain tasks. The identified direction is reusable across datasets within the same domain but not across domains, and it enables further improvement of already post-trained models without the degradation caused by direct SFT. Ablations further show that later-stage directions provide diminishing gains, sparse updates along the constrained direction remain effective, and the resulting reasoning behavior more closely resembles that of on-policy paradigms.
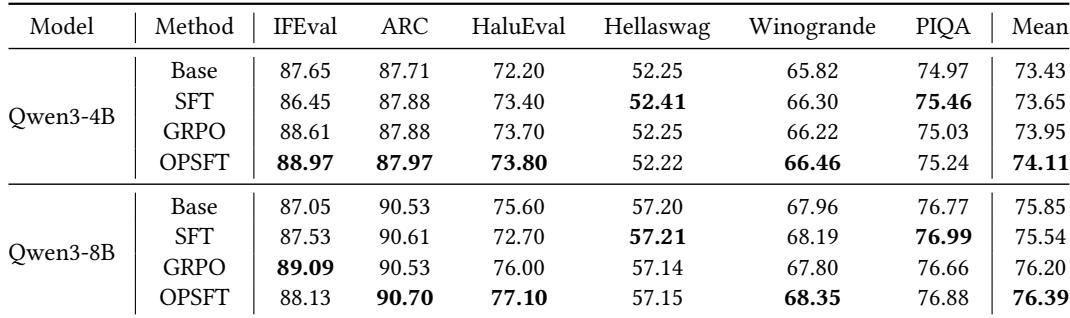
In the out-of-domain evaluations summarized here, OPSFT achieves the highest average performance where it is reported, slightly above GRPO and ahead of vanilla SFT and the base model. Vanilla SFT shows only mixed gains over the base model, and its average can slightly decline at the larger scale, while GRPO improves the average at both shown scales. The paper links these improvements to using the on-policy update direction during SFT. OPSFT leads the Qwen3-4B mean out-of-domain score, with GRPO close behind and vanilla SFT lower. Gains are concentrated in benchmarks like IFEval and HaluEval, while results on ARC, Hellaswag, Winogrande, and PIQA are smaller or mixed.
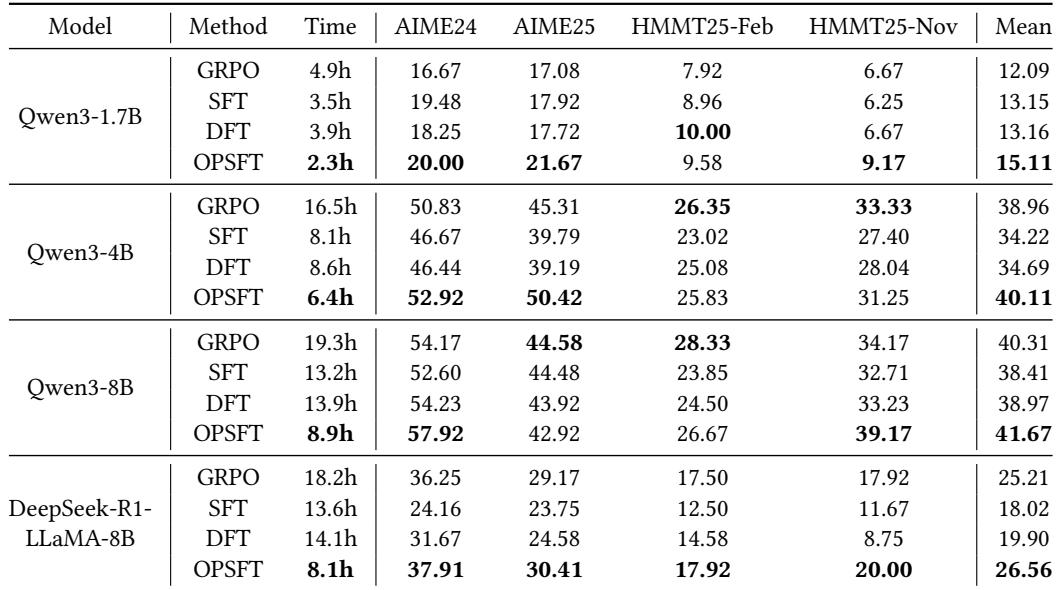
Across DeepMath benchmarks, OPSFT tends to outperform SFT and DFT in mean accuracy while requiring less training time. It also reduces training time compared with GRPO, often by more than half, while achieving better or comparable generalization. These trends hold across different model scales and architectures reported in the experiments. On Qwen3-1.7B, OPSFT achieves a mean accuracy of 15.11 in 2.3h, improving over SFT, DFT, and GRPO while using the least training time. On DeepSeek-R1-Distill-LLaMA-8B, OPSFT reaches 26.56 mean accuracy in 8.1h, substantially outperforming DFT at 19.90 in 14.1h. Compared with GRPO on Qwen3-8B, OPSFT cuts training time from 19.3h to 8.9h and raises mean accuracy from 40.31 to 41.67.
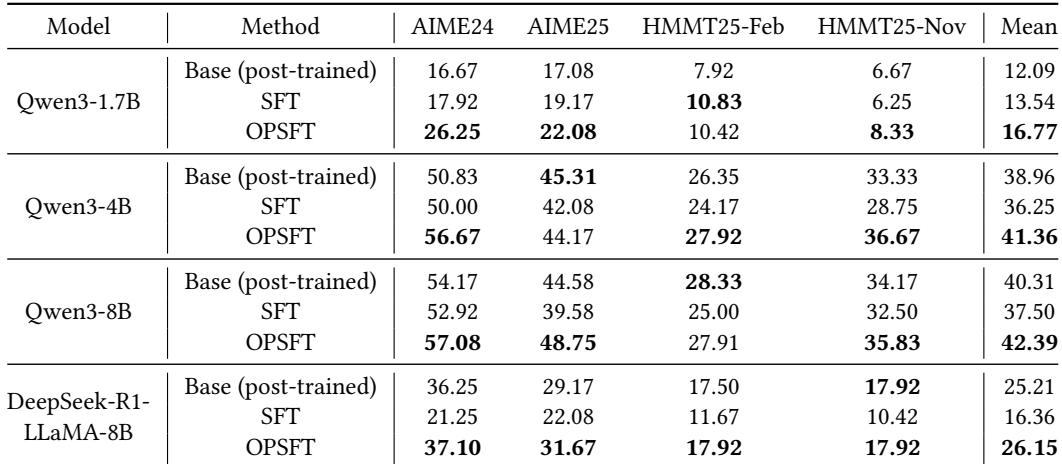
For Qwen3-1.7B and Qwen3-4B post-trained by GRPO, OPSFT improves mean benchmark accuracy over both the post-trained baseline and vanilla SFT on math reasoning tasks. Vanilla SFT does not reliably preserve post-trained capabilities and can reduce accuracy, as seen with Qwen3-4B, while OPSFT further improves the same model. Results on code tasks are reported as consistent with this trend. OPSFT achieves higher mean accuracy than vanilla SFT across the reported AIME and HMMT reasoning benchmarks. Vanilla SFT can fall below the post-trained baseline, whereas OPSFT improves over it, with the pattern extending to code tasks.
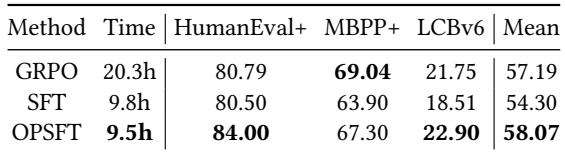
On code tasks with Qwen3-4B and the Eurus dataset, OPSFT achieves the highest mean accuracy while also having the shortest training time among GRPO, SFT, and OPSFT. It improves over SFT on all reported code benchmarks and slightly exceeds GRPO on average despite training in less than half the time. OPSFT reaches the best mean score and the lowest training time across the compared methods. Compared with SFT, OPSFT delivers consistent accuracy gains on HumanEval+, MBPP+, and LCBv6 with slightly shorter training time.
This ablation examines how BF16 and FP32 parameter precision affect update sparsity and accuracy for SFT and OPSFT. OPSFT produces much sparser updates than vanilla SFT under BF16, yet it still improves mean accuracy over vanilla SFT. With FP32 precision, updates become denser and OPSFT achieves the highest mean accuracy, slightly surpassing GRPO while updating a comparable fraction of parameters. Under BF16, OPSFT updates 0.408% of parameters compared with 2.702% for vanilla SFT, but its mean accuracy is higher and substantially above the base model. Under FP32, vanilla SFT becomes dense with about 90% of parameters updated, while OPSFT updates about 9.45%, similar to GRPO's update proportion. FP32 OPSFT attains the highest mean accuracy and edges out GRPO, suggesting that the constrained update direction remains effective at higher precision.
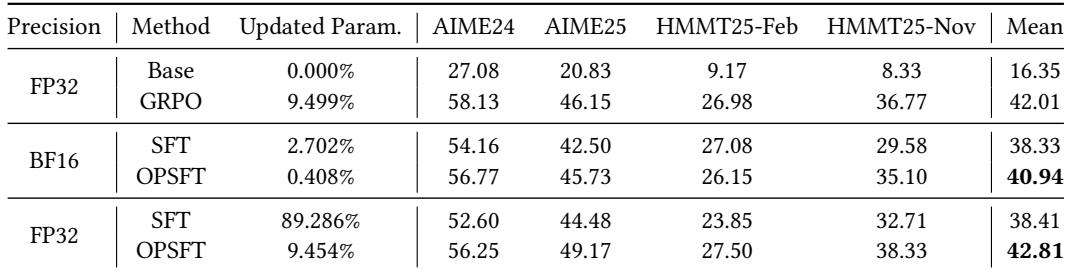
Across out-of-domain, math reasoning, and code evaluations, OPSFT consistently improves over vanilla SFT and the base model while matching or slightly exceeding GRPO, often with substantially shorter training time and sparser updates. Gains are strongest on benchmarks such as IFEval, HaluEval, and math or code tasks, while effects on standard knowledge benchmarks are smaller or mixed. Precision ablations show OPSFT remains effective under BF16 and FP32, updating far fewer parameters than vanilla SFT while achieving the highest mean accuracy and a comparable update density to GRPO under FP32.