Command Palette
Search for a command to run...
비주얼 인코더 제거까지 우리는 얼마나 멀리 있는가? 인코더-프리 멀티모달 사전학습을 위한 스케일링 법칙
비주얼 인코더 제거까지 우리는 얼마나 멀리 있는가? 인코더-프리 멀티모달 사전학습을 위한 스케일링 법칙
Lin Chen Bolin Ni Qi Yang Lan Jiang Kun Ding Xiaoran Fan Hower Yang Ying Wang Shiming Xiang
초록
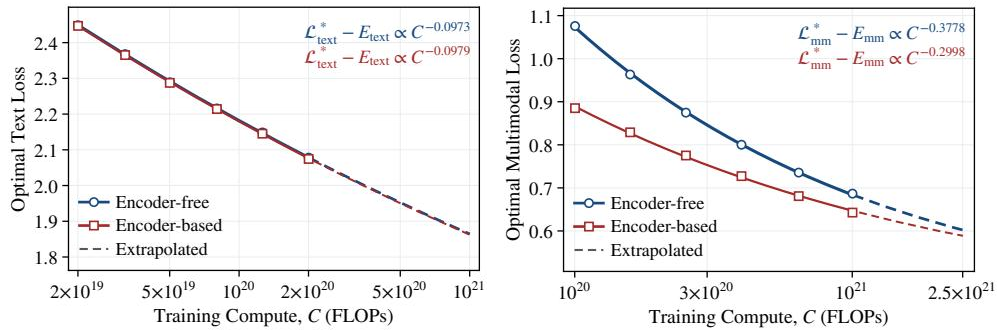
대부분의 현대 멀티모달 대규모 언어 모델(MLLM)은 강력한 시각적 사전 정보를 제공하는 사전학습된 비주얼 인코더에 의존한다. 인코더-프리 MLLM은 대신 원시 픽셀로부터 직접 시각 표현을 학습하여 단순하고 통합된 구조를 제공하지만, 그 스케일링 동작은 체계적으로 규명되지 않았다. 이 공백을 메우기 위해 우리는 인코더-프리 및 인코더 기반 MLLM의 스케일링 법칙을 비교하고 세 가지 주요 발견을 보고한다. (1) 비주얼 인코더를 제거하면 멀티모달 목적함수에 대한 계산-최적 할당이 더 큰 모델 쪽으로 이동하는 반면, 텍스트에 대한 할당은 거의 변하지 않는다. (2) 두 구조는 텍스트 목적함수에서 거의 겹치는 손실-계산 프런티어를 보이지만, 멀티모달 목적함수에서는 갈라진다: 인코더-프리 모델은 소규모에서는 성능이 낮지만 약 10^22 FLOPs에서 따라잡을 것으로 예측되며, 이는 실질적인 사전학습 예산 내에 충분히 있다. (3) 비주얼 인코더가 없으면 언어 모델이 시각 특화 적응을 통해 그 역할을 대신하게 된다: 훈련 계산이 증가할수록 시각 토큰 간 양방향 상호작용의 이점이 커지고, 시각 처리가 더 이른 계층으로 이동하며, 시각 토큰에 대한 전문가 라우팅이 더 집중된다. 전반적으로 우리의 결과는 사전학습된 인코더가 제공하는 시각적 사전 정보의 이점이 규모에 따라 감소함을 보여주며, 인코더-프리 구조를 멀티모달 사전학습의 유망한 방향으로 위치시킨다.
One-sentence Summary
Researchers from CASIA, UCAS, and Tencent compare scaling laws for encoder-free and encoder-based multimodal large language models, finding that removing the visual encoder shifts compute-optimal allocation for the multimodal objective toward larger models and that encoder-free models catch up at around 1022 FLOPs through vision-specific adaptation.
Key Contributions
- A systematic scaling-law comparison between encoder-free and encoder-based multimodal LLMs shows that removing the visual encoder shifts compute-optimal decoder allocation toward larger models for the multimodal objective while leaving text-optimal allocation nearly unchanged.
- Encoder-free and encoder-based architectures have nearly overlapping loss-compute frontiers on text, but encoder-free models underperform on the multimodal objective at small scales and are predicted to catch up around 10^22 FLOPs under compute-optimal allocation.
- Encoder-free decoders take over visual encoding as training compute grows, strengthening bidirectional visual-token interactions, shifting visual processing to earlier layers, and concentrating expert routing for visual tokens.
Introduction
Most modern multimodal large language models rely on a pretrained visual encoder to supply the language model with rich visual representations. Encoder-free MLLMs remove this encoder and feed image patches directly into the decoder, which simplifies the architecture but forces the decoder to learn visual representations from raw pixels. Prior encoder-free work has shown feasibility, but its scaling behavior had not been systematically characterized. The authors address this gap with a controlled scaling study comparing encoder-free and encoder-based models that share the same sparse decoder ladder, data mixture, optimization setup, and visual-token granularity. They fit separate scaling laws for text and multimodal objectives and probe decoder internals to show that compute-optimal encoder-free training favors larger models, predict a multimodal efficiency crossover around 10^22 FLOPs, and reveal that the decoder develops vision-specific adaptations such as stronger bidirectional attention among visual tokens and more concentrated expert routing.
Method
The authors establish a framework for estimating scaling laws to determine compute-optimal allocations for large language models. Let M denote the FLOPs per token and D the number of objective tokens, establishing a training budget of C=MD. At a target budget C, the compute-optimal allocation minimizes the loss L(M,D) subject to the constraint MD=C:
Mopt(C),Dopt(C)=M,DargminL(M,D)s.t.MD=C.Across varying budgets, these optima adhere to the compute-optimal allocation law:
Mopt(C)∝Ca,Dopt(C)∝Cb,a+b=1.The corresponding compute-optimal frontiers are defined by:
L∗(C)=E+KC−γ,where γ>0 is the loss-compute exponent, K>0 is a fitted prefactor, and E represents the entropy floor induced by the data distribution. To estimate these parameters, the authors utilize IsoFLOP profiles. For a given budget C, they vary M and set D=C/M, fitting the validation loss as a quadratic function of logM. The fitted minimum identifies Mopt(C), from which Dopt(C) and L∗(C) are directly derived.
In parallel, the authors design a matched model ladder to compare architectural paradigms in multimodal large language models. This ladder comprises 11 sparse mixture-of-experts language models ranging from 1.1B to 44B total parameters and 71M to 2.4B active non-embedding parameters, all sharing the same data mixture, optimization setup, and visual-token granularity. The architectural comparison between encoder-based and encoder-free approaches is illustrated below.
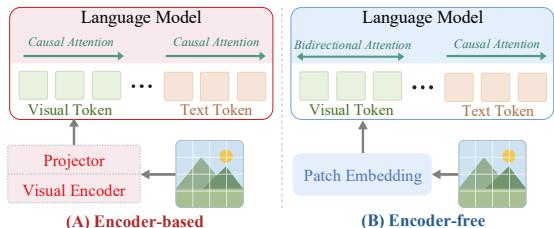
In the encoder-based configuration, images are processed using a pretrained SigLIP 2 Vision Transformer, followed by a ConvPool adapter and a projector. This architecture applies causal attention uniformly to all tokens. The Vision Transformer maintains a consistent size across different decoder scales and is trained jointly with the decoder. Conversely, the encoder-free model bypasses the dedicated visual encoder, mapping raw image patches directly into the decoder through a patch projection. In this setup, visual tokens attend bidirectionally within each image, while all other attention mechanisms remain strictly causal. The authors also investigate a fully causal variant of this encoder-free design to further isolate the impact of bidirectional visual attention.
Experiment
This set of experiments compares encoder-free and encoder-based multimodal models using IsoFLOP profiles and compute-optimal plus overtraining scaling analyses. Removing the pretrained visual encoder leaves text-objective allocation and loss behavior nearly unchanged but shifts multimodal training toward larger decoders and creates an initial multimodal efficiency gap that is projected to close within practical compute budgets, with earlier catch-up on language-heavy topics like STEM and later on perception-heavy topics like captioning. The decoder appears to compensate by developing encoder-like visual processing: visual tokens receive stronger bidirectional attention, are transformed earlier in shallow layers, and are handled by more concentrated expert routing.
Encoder-free models allocate compute to model scale much more aggressively on the multimodal objective than on the text objective. The multimodal allocation exponent remains elevated under causal attention over visual tokens, indicating that the shift toward larger models is not specific to bidirectional visual attention. Encoder-free text allocation exponents stay close to encoder-based text behavior under both attention settings. Multimodal allocation exponents rise substantially relative to text, indicating a compute-optimal preference for larger models. Causal attention over visual tokens yields a multimodal allocation exponent close to the bidirectional setting, so the larger-model shift persists across visual attention masks.
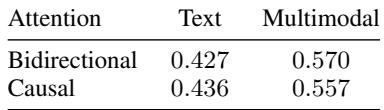
The experiments assess how encoder-free models allocate compute to model scale across text and multimodal objectives under bidirectional and causal visual attention. Multimodal objectives consistently favor substantially larger models than text objectives, while encoder-free text allocation remains close to encoder-based text behavior in both attention settings. The larger-model shift persists under causal visual attention, indicating that this preference is not specific to bidirectional visual attention.