Command Palette
Search for a command to run...
무엇이 월드 액션 모델의 일반화를 이끄는가: 테스트 시점 미래 모델링에 대한 실증 연구
무엇이 월드 액션 모델의 일반화를 이끄는가: 테스트 시점 미래 모델링에 대한 실증 연구
초록
월드 액션 모델(WAM)은 훈련 중에 행동과 함께 미래를 예측한다. 비디오 디노이징의 높은 계산 비용으로 인해 추론 시에도 미래를 여전히 생성해야 하는지는 논쟁의 대상이다. Explicit WAM은 각 행동 청크와 함께 미래를 깨끗한 프레임으로 디노이징하는 반면, Latent WAM은 가속을 위해 미래를 완전히 폐기한다. 우리는 Latent WAM이 분포 내(in-distribution) 태스크에서는 Explicit WAM과 대등함에도 불구하고, WAM의 원래 동기가 되었던 일반화 이점을 유지하지 못한다는 것을 발견한다. 이를 입증하기 위해 환경 섭동, 데이터 효율성, 태스크 일반화라는 세 축에서 일반화를 평가한다. 동일한 백본, 훈련 데이터, 예산을 사용한 통제 비교 결과, 행동 전문가가 더 이상 미래 표현을 조건으로 사용하지 않을 때 세 축 모두에서 일관된 성능 저하가 나타났다. 추가 분석은 이러한 격차가 거의 전적으로 첫 번째 디노이징 단계에서 발생함을 보여주며, 이점은 미래를 생성하는 것이 아니라 준비하는 데서 나온다. 이에 우리는 미래 모델링을 완전 잡음이 추가된 비디오 토큰의 단일 순전파로 단순화하고 훈련 시 잡음 스케줄을 이러한 추론 동작에 맞게 조정하는 Simple-WAM을 제안한다. 시뮬레이션과 실제 세계 태스크 전반에서 Simple-WAM은 양쪽의 장점을 모두 달성하여 Latent WAM에 필적하는 효율성으로 Explicit WAM을 앞서는 일반화 성능을 보인다.
One-sentence Summary
Leap Lab, Tsinghua University, et al. propose Simple-WAM, which simplifies future modeling into one forward pass of fully noised video tokens and adapts the training-time noise schedule to this inference behavior, after showing that latent WAMs lose the generalization benefits of explicit WAMs because the action expert no longer conditions on future representations; Simple-WAM matches latent WAM efficiency and outperforms explicit WAMs on simulation and real-world tasks.
Key Contributions
- A matched evaluation framework spanning environmental perturbation, data efficiency, and task generalization shows that latent world action models consistently lose generalization ability when inference-time future conditioning is removed.
- Controlled comparisons with a matched backbone, training data, and budget trace the generalization gap almost entirely to the first denoising step, indicating that preparing future video tokens matters more than generating clean future frames.
- Simple-WAM uses a single forward pass of fully noised video tokens and adapts the training-time noise schedule to this inference behavior, leading explicit world action models in generalization performance with efficiency comparable to latent models.
Introduction
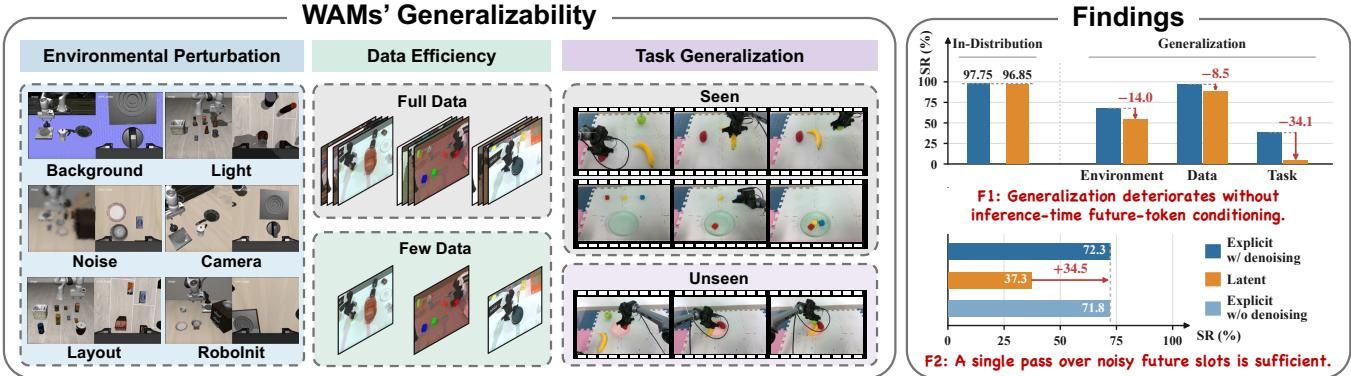
World Action Models (WAMs) aim to build generalizable robot policies by jointly predicting future video frames and actions, using web-scale video pretraining to supply rich spatiotemporal priors and observation-space supervision beyond sparse action labels. This future-modeling ability is seen as a key advantage over Vision-Language-Action models, whose static image-text pretraining provides little temporal understanding. A central open question is whether future video must also be generated at inference. Explicit WAMs denoise future frames alongside actions, which supports generalization but makes high-frequency closed-loop control costly because video tokens far outnumber action tokens. Latent WAMs skip test-time video generation and match explicit WAMs on in-distribution tasks at much lower cost, but prior comparisons did not isolate how inference-time future modeling affects the broader generalization that originally motivated WAMs. The authors introduce a controlled evaluation across environmental robustness, data efficiency, and task generalization, find that latent WAMs fall behind on all three axes, and propose Simple-WAM, which conditions on fully noised future tokens in one pass to recover most of the generalization benefit at near-latent inference cost.
Method
The authors leverage a language-conditioned visuomotor control framework that couples a video expert with an action expert. At each control step t, the policy takes an image observation ot, a language instruction ℓ, and a proprioceptive state st to predict an action chunk At=at:t+H−1. The video expert processes a sequence of latents spanning the current and future frames, while the action expert regresses a velocity field over an independent flow time.
To understand the design of the proposed method, it is necessary to consider the two existing conditioning paradigms. Explicit World Action Models iteratively denoise future video tokens across the entire schedule, providing rich future context but incurring high inference costs. Conversely, latent World Action Models drop the future video tokens entirely during inference, relying solely on the current frame to achieve high efficiency at the expense of generalizability.
Refer to the framework diagram for a visual comparison of these conditioning schemes.
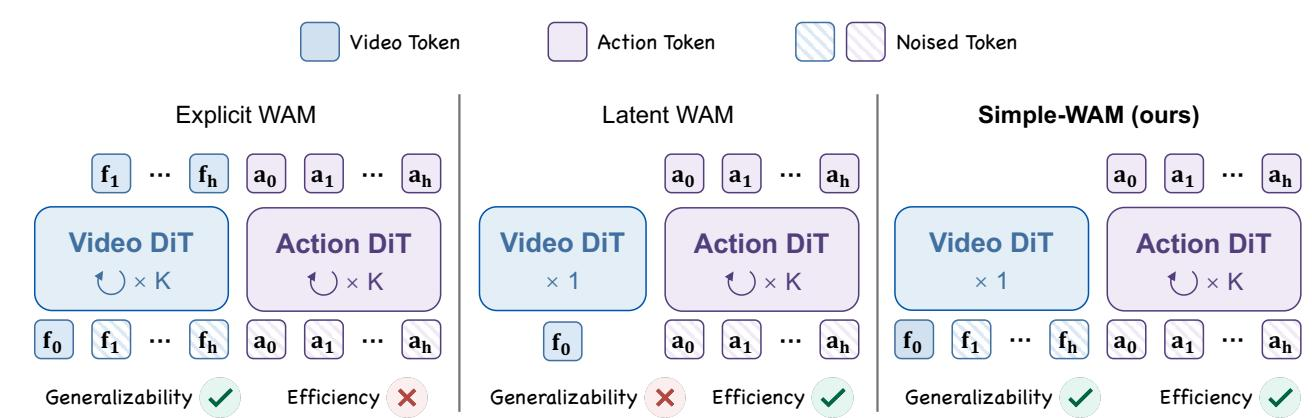
The proposed Simple-WAM bridges this gap by retaining the future video tokens of the explicit paradigm while adopting the single forward pass efficiency of the latent paradigm. During inference, the model abandons iterative denoising of the future video tokens. Instead, the video expert performs a single forward pass over the sequence with the future video tokens left as pure Gaussian noise at flow time τ=1. The resulting feature conditions all K action steps, effectively balancing the generalization of the explicit approach with the computational efficiency of the latent approach.
To support this inference strategy, the authors introduce a mixed training schedule. Since the inference relies entirely on features extracted at τ=1, the training process must strengthen the ability to read features from pure noise. The flow time of the future video tokens is sampled such that τ=1 with probability p, and drawn from the standard flow-time schedule otherwise. This mixture ensures the video expert is specifically optimized for the noise level encountered during inference, while the remaining training budget maintains supervision across the rest of the schedule. The two experts are trained jointly, minimizing a combined loss of the action and video velocity fields.
Experiment
The paper evaluates world-action model generalization along environmental perturbation, data efficiency, and task generalization, using controlled explicit and latent inference-time future conditioning paradigms. It finds that in-distribution parity hides a large gap: removing future modeling at inference hurts generalization, while conditioning on a fully noised future already provides most of the benefit. Simple-WAM builds on this by using noise-level future conditioning and matches or exceeds explicit future modeling across simulated and real-world benchmarks with substantially lower inference cost. Ablations show that the mixed schedule is robust and that noised video tokens outperform learned queries or zeros because they remain aligned with video pretraining.
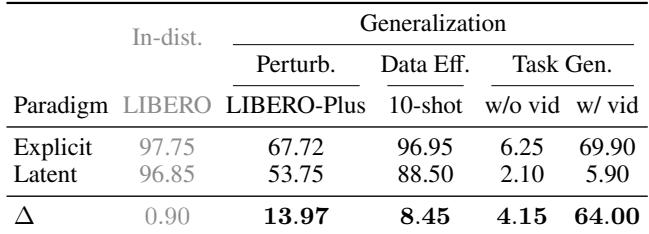
Under the matched in-distribution setting, explicit and latent future conditioning perform comparably. Across environmental perturbation, data efficiency, and task generalization, the explicit paradigm consistently leads, with the largest gap when action-free video is available for held-out tasks. This indicates that future modeling is needed at inference, not only as a training objective. In-distribution success is nearly identical between explicit and latent paradigms. Explicit future modeling maintains a clear advantage under environmental perturbation and reduced demonstration settings. Action-free video provides a large benefit for the explicit paradigm on held-out tasks, while the latent paradigm remains near its no-video level. Removing future modeling at inference reduces generalization even when in-distribution performance appears matched.
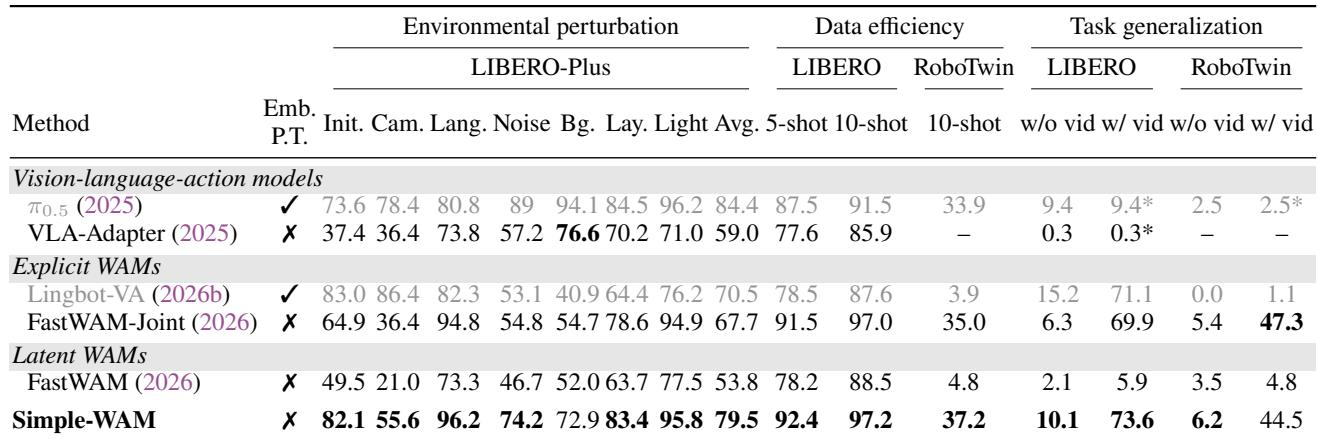
Simple-WAM preserves most of the generalization benefits of explicit future modeling while remaining much closer to latent-model inference cost. Across environmental perturbation, data efficiency, and held-out task generalization, latent future modeling falls behind, while noised future conditioning recovers performance without iterative denoising. This supports future modeling as a test-time requirement for robustness and generalization. Simple-WAM leads methods without embodied pretraining on environmental perturbation and narrows the gap to a large-scale embodied-pretrained baseline. Compared with explicit future modeling, Simple-WAM is substantially faster per action chunk while staying competitive on low-data and held-out task generalization.
Ablations on LIBERO-Spatial show that intermediate probabilities for the mixed schedule are robust and outperform both extremes, with data efficiency remaining the most stable axis across settings. The endpoints suffer mainly on environmental perturbation and task generalization. Replacing noised future video tokens with learned queries or zeros causes sharp drops on every axis, especially task generalization, underscoring the importance of pretraining-aligned noised video conditioning. Intermediate mixing probabilities outperform the extremes, with average performance remaining stable across the mid-range values. Replacing future video tokens with learned queries or zeros degrades all axes, with the largest losses on task generalization.
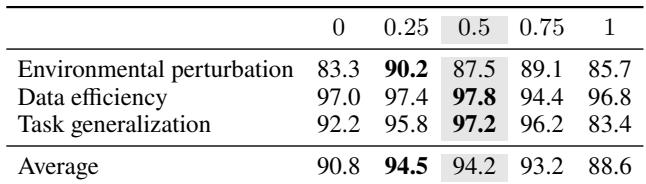
The experiments compare explicit and latent future conditioning across in-distribution, environmental perturbation, data efficiency, and held-out task generalization settings, with ablations on LIBERO-Spatial. Explicit future modeling performs comparably in-distribution but consistently leads under distribution shift and low-data regimes, especially when action-free video is available, while noised future conditioning via Simple-WAM retains these gains at lower inference cost. Ablations show that intermediate mixed-schedule probabilities are robust and that replacing noised future video tokens with learned queries or zeros sharply degrades all axes, particularly task generalization. Overall, future modeling is needed at inference, not only as a training objective.