Command Palette
Search for a command to run...
PanoVLN: 효과적인 파노라마 비전-언어 내비게이션을 향하여
PanoVLN: 효과적인 파노라마 비전-언어 내비게이션을 향하여
Zhen Wang Changpeng Wang Zhe Liu Zhangyang Qi Yuxiang Lu Zimo Zeng Donglian Qi Xi Chen
초록
최근 비전-언어 모델(VLM)은 비전-언어 내비게이션(VLN)을 발전시켜, 모델이 시각 관측과 언어 지시로부터 내비게이션 행동을 예측할 수 있게 하였다. 본 연구에서는 파노라마 관측을 사용하는 VLN을 탐구하고 PanoVLN을 제안한다. 그 동기는 단순하다. 더 완전한 시각적 맥락이 더 나은 정보에 기반한 내비게이션 결정을 가능하게 해야 한다는 것이다. 예를 들어, 파노라마는 원근 카메라의 시야 밖에 있는 통로를 드러낼 수 있어, 추가 탐색 없이도 모델이 의도된 경로를 식별할 수 있게 한다. 그러나 원근 이미지를 파노라마로 단순히 대체하는 것만으로는 제한적인 성능 향상만 얻을 수 있음을 발견하였다. 우리의 진단은 더 넓은 시야를 충분히 활용하려면 행동 예측, 학습 감독, 시각 표현의 수정이 필요함을 시사한다. 첫째, 더 넓은 시야는 더 장기적인 행동 계획을 지원한다. 우리는 모델이 더 긴 행동 시퀀스를 예측하도록 하여, 단일 파노라마로부터 더 큰 회전과 후속 이동을 가능하게 한다. 구체적으로, 재계획 전에 예측된 행동 중 몇 개를 실행할지를 동적으로 결정하는 신뢰도 기반 실행(CGE) 전략을 도입한다. 둘째, 더 넓은 시야는 더 복잡한 경로 선택을 수반한다. 따라서 우리는 경로 선택에 대한 표적화된 감독을 제공하기 위해 분기점이 빈번하고 지시가 명확한 학습 경로를 구성한다. 셋째, 파노라마 내비게이션은 개별 랜드마크를 인식하는 것을 넘어, 시야 방향들 간의 공간적 관계를 이해해야 한다. 우리는 RGB 파노라마에서 의미론적 특징과 기하학적 특징을 결합하여, 시각 토큰을 추가하지 않고도 장면 내용과 공간적 배치를 모두 포착한다. 4B 백본과 RGB-only 입력을 사용하여, PanoVLN은 R2R-CE와 RxR-CE Val-Unseen의 성공률에서 이전 SOTA를 각각 11.9%와 8.7% 능가한다. 사족 보행 로봇에서의 실제 실험은 기존 VLN 방법들보다 더 빠르고 정지가 적은 내비게이션을 추가로 입증한다. 프로젝트 페이지는 https://wangzhen-w.github.io/PanoVLN/ 에서 확인할 수 있다.
One-sentence Summary
Researchers from Zhejiang University and The University of Hong Kong propose PanoVLN, a panoramic vision-and-language navigation model that uses confidence-guided execution for longer-horizon actions, branching-point training supervision, and combined semantic-geometric RGB panorama features, surpassing the previous state of the art by 11.9% and 8.7% in success rate on R2R-CE and RxR-CE Val-Unseen and enabling faster real-world quadruped navigation with fewer pauses.
Key Contributions
- PanoVLN is a panoramic vision-and-language navigation method that predicts longer action sequences from a single panorama and uses confidence-guided execution to determine how many predicted actions to execute before replanning.
- A decision-centric training dataset of 98K trajectories across 800 HM3D scenes provides frequent branching points and visually grounded instructions, with denser sampling around turns and stopping points for route selection and completion supervision.
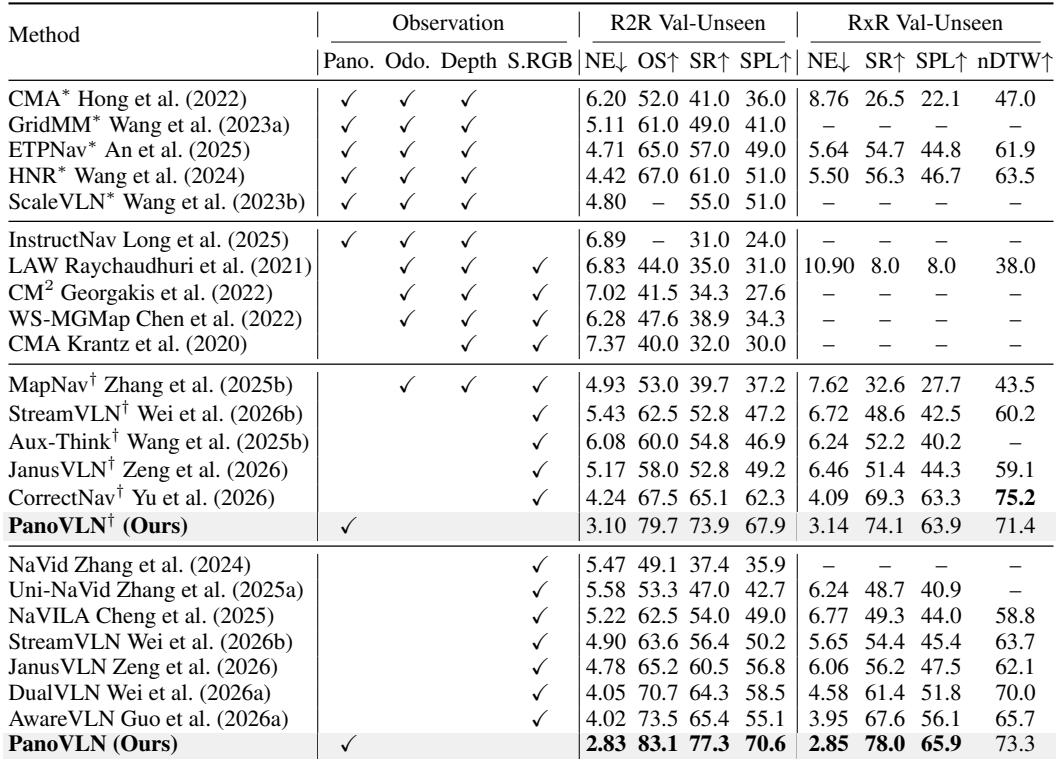
- The method combines semantic VLM features with geometric PanoVGGT features from the same RGB panorama; with a 4B RGB-only backbone, it achieves 77.3% success on R2R-CE Val-Unseen and 78.0% on RxR-CE Val-Unseen, improving over the previous state of the art by 11.9% and 8.7% and enabling faster real-world quadruped navigation with fewer pauses.
Introduction
Vision-and-language navigation (VLN) requires an agent to follow natural-language instructions through an environment, and recent vision-language models have improved this task by predicting navigation actions from visual observations. Most prior work uses perspective images, which limit the visual context available at each decision point. The authors investigate equirectangular panoramas, which provide a 360-degree view and can reveal passages, landmarks, and route alternatives. They find that simply replacing perspective images with panoramas does not improve performance under the same setup, so they propose PanoVLN, which adapts action prediction with longer horizons and confidence-guided execution, creates a 98K-trajectory decision-centric training dataset, and fuses semantic VLM features with panoramic geometric features. This approach achieves state-of-the-art success rates on R2R-CE and RxR-CE and enables faster real-world robot navigation with fewer pauses.
Dataset
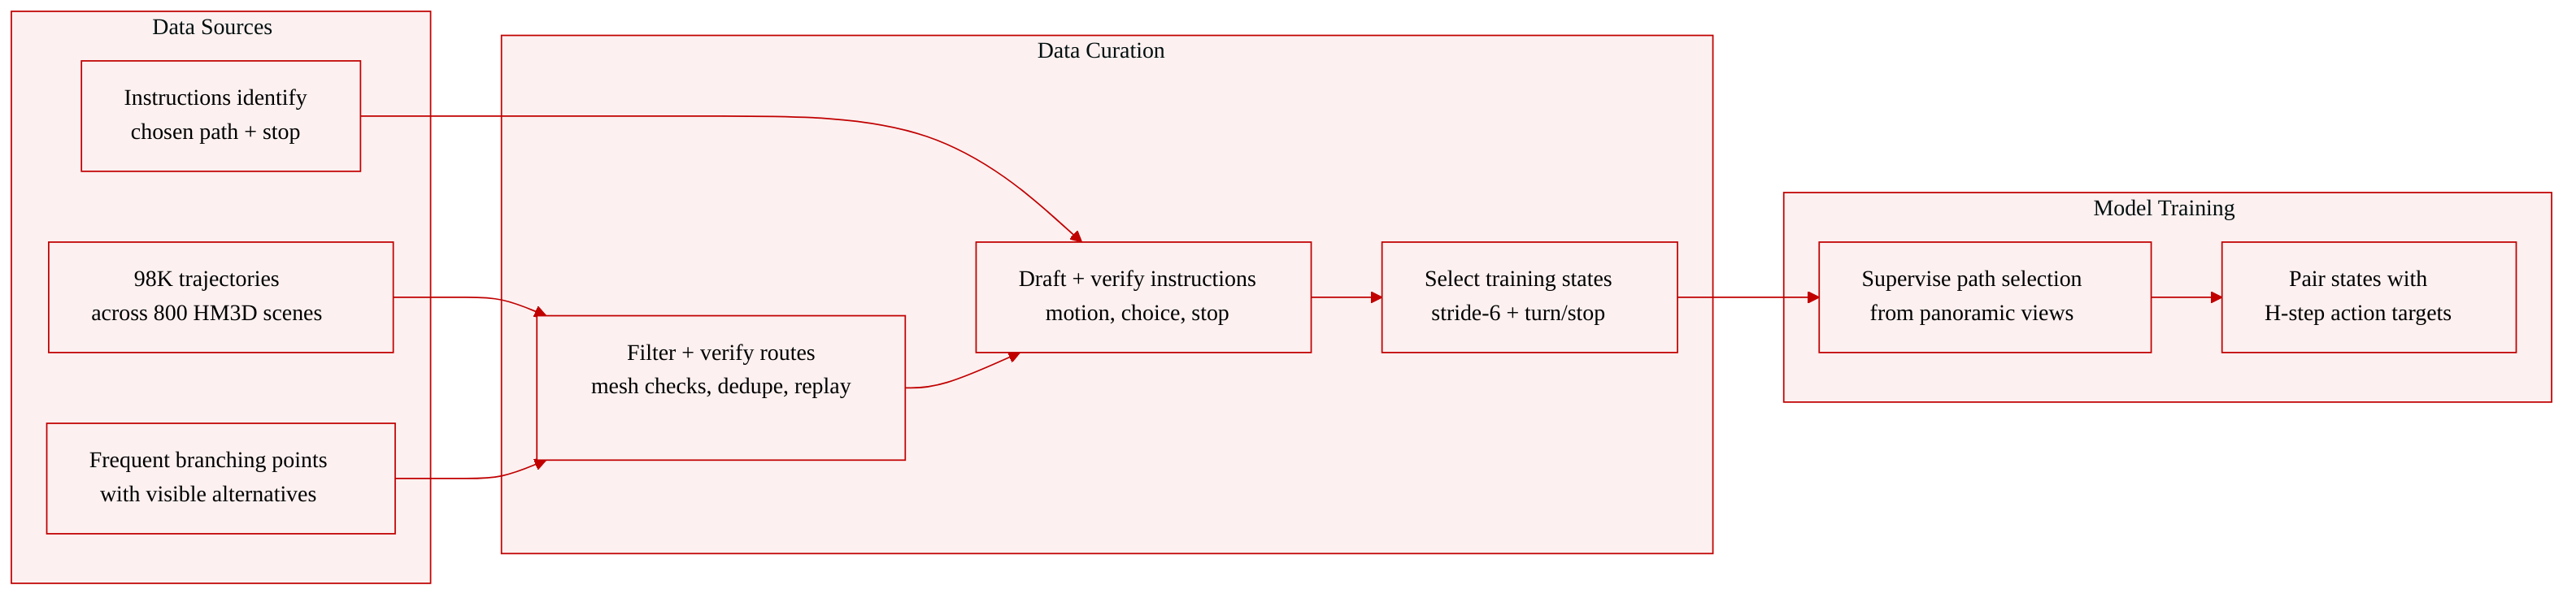
Dataset composition and sources
- The authors construct 98K navigation trajectories across 800 HM3D scenes.
- Trajectories are designed to contain frequent branching points, where the agent must choose among multiple visible traversable paths.
- Each trajectory is paired with an instruction that identifies the chosen path and stopping location.
Route construction and filtering
- Walkable space is divided into connected areas using the navigation mesh.
- A branching point is defined as having at least two visible, traversable paths to different areas, excluding the incoming path.
- Endpoints are sampled in different areas, and routes passing through branching points are retained.
- Rendering-quality checks remove candidates with mesh holes or incomplete geometry, followed by near-duplicate removal.
- An expert converts remaining routes into primitive action sequences.
- Replay verifies goal reachability and confirms that the chosen path and its alternatives are visible at each branching point.
Instruction construction and verification
- Trajectories are divided into travel, branching, and arrival segments.
- Travel segments use first-person video with the expert path marked on the ground.
- Branching and arrival segments additionally use eight-view compass images.
- Qwen3.8-27B describes movement, identifies the chosen path from visible cues, and specifies the stopping location.
- Descriptions are combined in route order, with repetition removed and wording refined.
- Verification uses clean videos and compass images without instruction or route overlays.
- Three checks are applied: motion consistency, choice grounding, and stop grounding.
- Mismatched segments are revised locally and reverified; only samples passing all three checks are retained.
Training sample construction and usage
- The data is used to provide supervision for learning path selection from panoramic observations.
- For H = 18, the authors use a stride-six grid to reduce overlap between adjacent grid targets from 17 to 12 actions.
- Additional states are added at sustained-turn onsets and near termination to supervise turning and stopping.
- Each state is paired with its H-step expert action sequence.
- The grid preserves route coverage, while added states emphasize action transitions.
- The provided section does not specify train/eval split or mixture ratios.
Method
The authors propose a method to fully exploit the complete visual context provided by panoramas in the Vision-and-Language Navigation task. Starting from a baseline model that takes panoramas as input, they introduce three key adaptations: longer action-sequence supervision and execution, decision-centric data construction, and geometry-aware visual representations.
To leverage the wider visibility of panoramic observations, the authors extend the action prediction horizon. Instead of predicting a single step, the policy is trained to predict a sequence of the next H expert actions. The training objective minimizes the negative log-likelihood of the expert action sequence using teacher forcing:
Lact=−H1i=1∑Hlogpθ(at,i∗∣Ot,At,<i∗)where At,<i∗ contains the preceding expert actions and pθ is the VLM next-token distribution.
During inference, the execution length is adapted based on prediction uncertainty through a mechanism called Confidence-Guided Execution. The uncertainty for a generated action is defined as the negative log probability of the predicted action. As shown in the figure below:
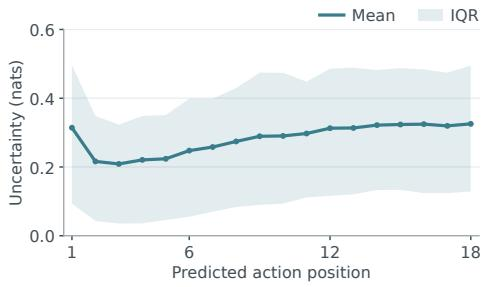
Mean uncertainty rises after an initial dip and exhibits substantial variation across policy calls. To handle this, the execution mechanism extends the executed prefix as long as the cumulative uncertainty Ut(k) remains within a predefined budget B, ensuring at least Emin actions are executed:
Et=max{k∈{1,…,H}:k≤Emin or Ut(k)≤B}The agent executes this prefix and then reobserves the environment unless it predicts a stop action.
To provide better supervision for selecting the correct path among multiple visible options, the authors construct a decision-centric training dataset. They generate navigation trajectories across various scenes, specifically targeting branching points where at least two traversable paths are visible. After filtering out routes with rendering issues or near-duplicates, an expert converts the valid routes into primitive action sequences. Instructions are constructed by dividing trajectories into travel, branching, and arrival segments. A large language model describes the movement and identifies the chosen path using first-person video and compass images. The authors rigorously verify motion consistency and choice grounding, revising and retaining only the segments that pass all checks. To reduce overlap between adjacent training states, they employ a stride-six grid for sampling and add specific states at sustained-turn onsets and near termination to emphasize action transitions.
Finally, the authors develop a geometry-aware visual representation to better understand the spatial relationships within a panoramic observation. They allocate a larger number of tokens to the current equirectangular panorama and fewer tokens to each history frame. To fuse geometric information without adding extra visual tokens, a pretrained PanoVGGT encoder extracts geometric features from the current RGB panorama. These features are resampled in ERP coordinates and grouped to align with the VLM merged current tokens. A trainable MLP projects the aligned geometric groups into the visual-token embedding space for residual fusion:
Vˉt=Vt+αfψ(Gt)where α is a fixed residual scale. This fusion combines semantics and geometry from corresponding ERP regions while preserving the token count and order, ultimately conditioning the action prediction alongside the instruction and history tokens. The VLM and projection layers are trained jointly, while the geometry encoder remains frozen.
Experiment
Experiments evaluate RGB-only PanoVLN on R2R-CE and RxR-CE Val-Unseen splits in Matterport3D using Habitat, with metrics including navigation error, success rate, SPL, and nDTW. Simulation results show PanoVLN achieves state-of-the-art success rates on both benchmarks and benefits from panoramic context, while real-world tests on a Unitree Go2 across hallway, office, and campus settings demonstrate reliable indoor route following, outdoor transfer, and efficient execution through longer predicted segments with confidence-guided execution. Ablations confirm that longer ERP prediction horizons, turn- and termination-aware sampling, confidence-guided execution, PanoVGGT panoramic features, and decision-centric training trajectories all improve navigation and stopping behavior.
PanoVLN achieves the highest success rate and SPL on both R2R-CE and RxR-CE, setting a new state of the art by large margins over prior panoramic navigation methods. A restricted-data version of PanoVLN also leads its training-data group in success rate and SPL. The results connect panoramic context and decision-centric trajectories to better generalization in unseen scenes. PanoVLN surpasses previous best success rates by 11.9 percentage points on R2R-CE and 8.7 percentage points on RxR-CE. PanoVLN trained without navigation data beyond R2R-CE and RxR-CE still leads the restricted-data group in SR and SPL on both benchmarks. Adding decision-centric trajectories further improves performance in unseen scenes.
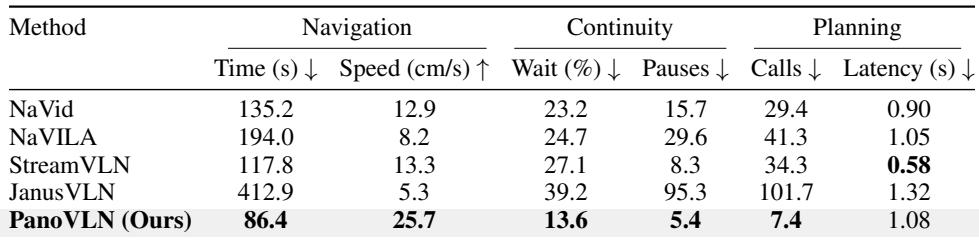
Across the real-world routes, PanoVLN achieves the shortest navigation duration and the highest travel speed among all compared methods. It also spends the least time waiting for policy responses and records far fewer pauses and policy calls. Although its per-request inference latency is not the lowest, its overall execution flow is the most efficient. PanoVLN combines the shortest navigation duration with the highest travel speed, while JanusVLN is the slowest by a wide margin. PanoVLN has the lowest waiting fraction, fewest pauses, and fewest policy calls, despite not having the lowest per-request latency.
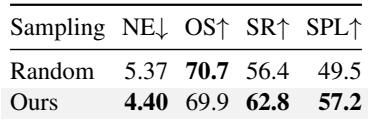
Compared with random-start sampling, the proposed turn- and termination-aware sampling lowers navigation error while keeping oracle success nearly unchanged. It also increases success rate and SPL by a clear margin, indicating more reliable termination and route completion when turn and stop states receive stronger supervision. The proposed sampling reduces navigation error relative to random-start sampling while maintaining comparable oracle success. It improves success rate and SPL, suggesting more reliable termination in the goal region and better supervision of turn and stop states.
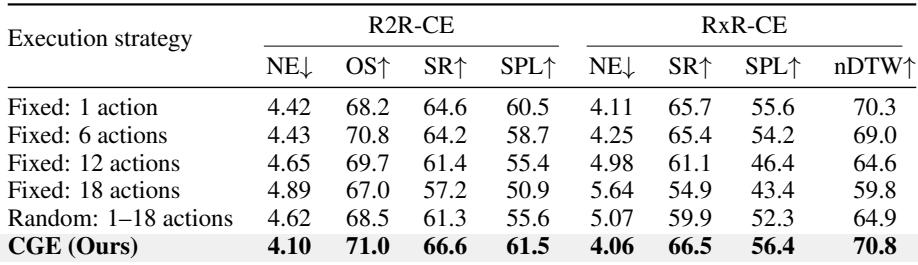
Confidence-guided execution achieves the best navigation performance on both benchmarks, outperforming fixed execution lengths and random execution. Fixed execution at one action is the strongest fixed setting, while longer fixed horizons generally reduce success and path quality. The results indicate that adapting execution to model confidence is more reliable than committing to a preset or random number of actions. Confidence-guided execution records the lowest navigation error and the highest success and path-quality metrics on both benchmarks. Among fixed strategies, one-action execution is strongest, and longer fixed horizons degrade success and SPL, especially on RxR-CE. Random execution over one to eighteen actions underperforms confidence-guided execution and trails the one-action fixed strategy on RxR-CE.
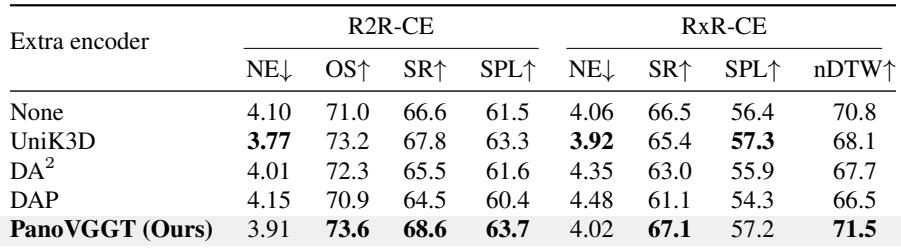
Geometry encoder comparison under matched fusion and execution settings shows mixed effects for existing encoders. PanoVGGT achieves the highest success rate on both R2R-CE and RxR-CE, and also leads on R2R-CE oracle success and SPL and on RxR-CE nDTW. The results suggest its panoramic geometric features add spatial cues that support route selection. PanoVGGT leads all compared encoders in success rate on both benchmarks, with the best R2R-CE oracle success and SPL and the best RxR-CE nDTW. Alternative encoders have mixed effects: UniK3D improves R2R-CE navigation error and SPL but not RxR-CE success, while DA^2 and DAP tend to reduce success on both benchmarks.
The experiments benchmark PanoVLN on R2R-CE and RxR-CE, real-world navigation routes, and ablations of sampling, execution, and geometry encoders. PanoVLN sets new state-of-the-art success and SPL on both benchmarks by large margins, and its real-world runs achieve the shortest duration and highest speed with fewer pauses and policy calls despite not having the lowest per-request latency. Turn- and termination-aware sampling and confidence-guided execution improve success and path quality over random or fixed baselines, while among geometry encoders PanoVGGT gives the strongest overall results and other encoders yield mixed effects.