Command Palette
Search for a command to run...
코드 에이전트 RL을 위한 그룹 단위 에이전트 평가 및 어드밴티지 재분배
코드 에이전트 RL을 위한 그룹 단위 에이전트 평가 및 어드밴티지 재분배
Jinhao Dong Liang Zhao Zihao Yue Wenhan Ma Linghao Zhang Lei Li Shicheng Li Yifan Song Bowen Ye Fuli Luo
초록
코드 에이전트를 위한 강화학습(RL)은 종종 실행 가능한 테스트를 사용해 이진 보상을 제공한다. 이러한 보상 하에서 GRPO(Group Relative Policy Optimization)는 각 롤아웃 그룹 내에서 테스트를 통과한 궤적들에 동일한 어드밴티지를 부여하여, 구현 품질과 작업 요구사항 준수 측면의 차이를 간과한다. 이로 인해 정책은 불필요하거나 범위를 벗어난 변경을 포함하는 구현보다 깔끔하고 목표에 부합하는 구현을 선호하도록 하는 학습 신호를 얻지 못한다. 우리는 코드 에이전트 RL에서 품질 인지형 크레딧 재분배를 위한 프레임워크인 Gagar를 제안한다. 통과 궤적과 실패 궤적을 모두 포함하는 그룹을 유지하는 동적 샘플링 위에 구축된 Gagar는 각 그룹의 모든 궤적을 공유 작업공간에 배치하고, SFT로 학습된 에이전트 평가자가 이를 함께 검사하여 테스트 통과 후보들의 순위를 매긴다. 이 순위에 기반하여, 우리는 낮은 순위의 궤적의 가중치를 낮추고, 모든 테스트 통과 궤적의 어드밴티지를 원래 합을 복원하도록 비례적으로 재조정한다. 이 합 보존 재분배는 품질 기반 가중치 감소로 설정된 상대적 가중치를 유지하면서 크레딧을 더 높은 품질의 구현으로 이동시킨다. 우리는 MiMo-V2.6-Flash(총 310B 파라미터)와 MiMo-V2.6-Pro(총 1.02T 파라미터)의 RL 이전 SFT 체크포인트를 사용하여 산업적 규모에서 Gagar를 평가한다. 통제된 코드 전용 Flash 실험은 코드 에이전트 성능 향상, 궤적 길이 증가 감소, 더 안정적인 학습을 보여준다. 나아가 Flash와 Pro 모두를 사용한 대규모 혼합 작업 RL에 Gagar를 적용한다. 우리의 결과는 코드 에이전트 RL의 품질과 안정성을 개선하기 위해 테스트 기반 검증과 그룹 단위 에이전트 평가를 결합하는 접근을 지지한다.
One-sentence Summary
Researchers from Xiaomi, Renmin University of China, Peking University, and other institutions propose Gagar, a quality-aware credit redistribution framework for code agent RL that uses dynamic sampling and an SFT-trained agentic grader to rank test-passing trajectories, downweights lower-ranked trajectories, and applies sum-preserving advantage rescaling; industrial-scale experiments with MiMo-V2.6-Flash (310B total parameters) and MiMo-V2.6-Pro (1.02T total parameters) show improved code agent performance, reduced trajectory-length growth, and more stable training.
Key Contributions
- Gagar is a quality-aware credit redistribution framework for code agent RL that uses dynamic sampling to retain groups with both passing and failing trajectories, then uses an SFT-trained agentic grader to inspect and rank test-passing trajectories in a shared workspace.
- Gagar downweights lower-ranked passing trajectories and proportionally rescales the advantages of all passing trajectories, preserving the original total positive advantage while shifting credit toward higher-quality implementations.
- Controlled code-only experiments with MiMo-V2.6-Flash show improved code agent performance, reduced trajectory-length growth, and more stable training; mixed-task RL with MiMo-V2.6-Flash and MiMo-V2.6-Pro reaches DeepSWE v1.1 avg@3 scores of 67.9 and 71.9.
Introduction
Reinforcement learning with executable feedback is a scalable way to train code agents that inspect repositories, modify code, and validate changes over long interactions. In common group-relative setups such as GRPO, all test-passing trajectories receive the same positive outcome advantage, so the training signal cannot distinguish cleaner, more focused patches from overly complex or risky implementations. Static text-based assessment also tends to miss repository context and execution evidence. The authors introduce Gagar, a quality-aware framework that uses an agentic grader to inspect code, run targeted checks, and rank test-passing candidates within each rollout group, then redistributes credit among successful trajectories while preserving their total positive advantage. This approach is designed to reinforce precise, minimally invasive, merge-ready solutions and is validated at industrial scale with MiMo models.
Method
The authors leverage groupwise quality supervision to augment reinforcement learning for code agents, moving beyond binary task outcomes. As shown in the figure below, the framework integrates groupwise agentic grading into the RL training loop to evaluate and rank valid passing implementations.
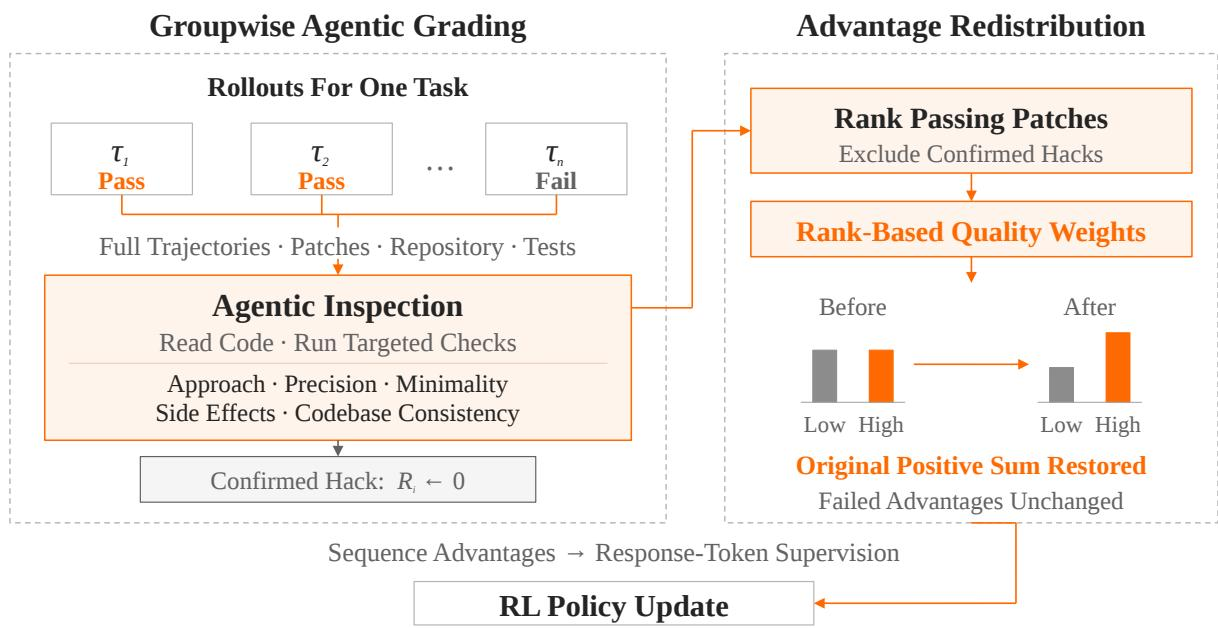
In the training setup, for each coding task, the rollout policy generates multiple trajectories. The final patch from each trajectory is evaluated using executable tests to yield a binary outcome reward. Let Gx={τi}i=1n denote the group of valid trajectories. The authors use the mean-centered outcome advantage Ai=Ri−Rˉ, where Rˉ=n−1∑j=1nRj. To ensure both successful and failed trajectories are present, dynamic sampling is adopted so that 0<Rˉ<1. All passing trajectories initially receive the same positive advantage 1−Rˉ, which fails to differentiate implementation quality.
To address this, the authors introduce groupwise agentic grading. The grader jointly examines all rollouts in a shared workspace containing the task specification, repository, complete trajectories, submitted patches, and test outputs. This comparison helps identify the strongest solutions and exposes ineffective strategies. The agentic grader gathers evidence iteratively, reviewing turn-by-turn summaries, reading relevant trajectory portions, and cross-checking patches against repository code and test logs. It can also run targeted checks. Quality is assessed across five criteria: approach suitability, precision, minimality, side effects, and codebase consistency. Passing solutions are checked for leaked or external answers, and confirmed hacks receive zero reward. The remaining candidates are scored and mapped to three quality tiers, which determine a discount factor fi∈(0,1] on their positive advantage.
Following grading, sum-preserving advantage redistribution is applied. Simply applying the discount factors would yield A~i=fiAi for passing trajectories, removing positive credit without a corresponding change on the negative side. This deficit weakens the reinforcement of successful trajectories. To preserve the total positive advantage S+=∑i∈PAi assigned to passing trajectories, the authors apply a common rescaling factor:
λ=∑j∈PfjAjS+The redistributed advantage is then:
Ai⋆={λfiAi,Ai,i∈P,i∈F.This ensures the total positive advantage is restored and the change is zero-sum over the passing subset, preserving both the ordering and relative strength of quality preferences.
During online training integration, grading runs asynchronously with rollout collection. The system checks the validity of grading results, falling back to original outcome advantages if necessary. Confirmed reliance on external solutions resets the affected reward to zero before group statistics are recomputed. The resulting sequence-level advantages are broadcast to the model-generated response tokens to supervise the RL policy update.
Experiment
These experiments evaluate Gagar on code-only reinforcement learning with MiMo-V2.6-Flash and on industrial-scale mixed-task RL with Flash and Pro, using DeepSWE v1.1 and SWE-bench Pro as benchmarks. The main comparisons show that Gagar improves long-horizon code agent performance, keeps trajectories shorter and more efficient, and yields higher implementation quality in external model review. An ablation confirms that sum-preserving redistribution is important for training stability, since downweighting passing trajectories without restoring credit leads to unstable dynamics and degraded downstream behavior. Industrial-scale runs further demonstrate competitive code agent performance relative to larger frontier models.
After industrial-scale mixed-task RL with Gagar, MiMo-V2.6-Flash and MiMo-V2.6-Pro achieve coding benchmark results competitive with strong external baselines. MiMo-V2.6-Pro outperforms Kimi K3 on DeepSWE despite having substantially fewer total parameters and surpasses GPT-5.6 Sol on SWE-bench Pro. Its DeepSWE score approaches GPT-5.6 Sol and Claude Opus 5, while it trails Claude Opus 5 on SWE-bench Pro. MiMo-V2.6-Pro outperforms Kimi K3 on DeepSWE despite using substantially fewer total parameters. MiMo-V2.6-Pro surpasses GPT-5.6 Sol on SWE-bench Pro. MiMo-V2.6-Pro approaches GPT-5.6 Sol and Claude Opus 5 on DeepSWE but remains below Claude Opus 5 on SWE-bench Pro. MiMo-V2.6-Flash achieves DeepSWE and SWE-bench Pro scores close to larger external models.
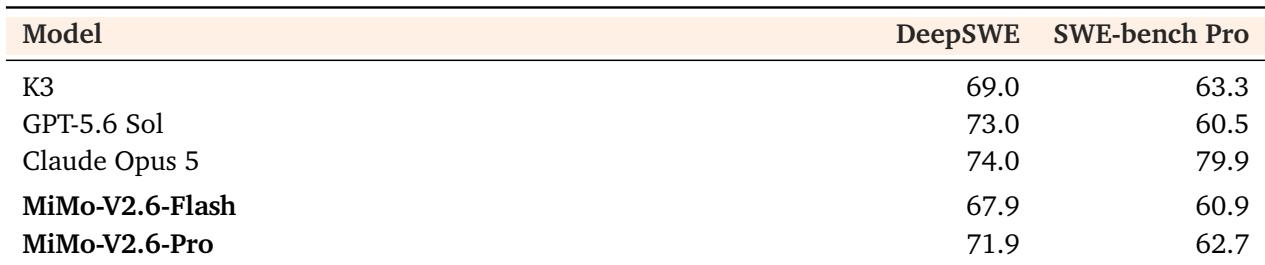
This experiment evaluates MiMo-V2.6-Flash and MiMo-V2.6-Pro after industrial-scale mixed-task RL with Gagar on coding benchmarks. The results show that MiMo-V2.6-Pro is competitive with strong external models, outperforming Kimi K3 on DeepSWE despite using substantially fewer parameters and surpassing GPT-5.6 Sol on SWE-bench Pro, while approaching GPT-5.6 Sol and Claude Opus 5 on DeepSWE but remaining below Claude Opus 5 on SWE-bench Pro. MiMo-V2.6-Flash also achieves DeepSWE and SWE-bench Pro scores close to larger external models.