Command Palette
Search for a command to run...
Duplex-MPE: 전이중 대화에서의 다자 간 상호작용 벤치마킹
Duplex-MPE: 전이중 대화에서의 다자 간 상호작용 벤치마킹
Chengqian Ma Wenhao Feng Weixuan Jin Gaole Dai Tianyu Xie Yuexiao Ma Zhaolu Kang Xiangyu Zhao Xiawu Zheng Fei Chao
초록
실시간 전이중 음성 모델은 말하는 동시에 들을 수 있어, 엄격한 턴 경계 없이도 자연스러운 상호작용이 가능하다. 기존 벤치마크들은 턴 테이킹, 끼어들기 처리, 다중 라운드 대화를 평가하지만, 여러 사람이 함께 나누는 대화에 참여하는 어시스턴트보다는 주로 지정된 사용자에 초점을 맞춘다. 본 연구에서는 이러한 어시스턴트가 언제 응답하고, 침묵을 지키며, 발화를 멈춰야 하는지를 평가하기 위해 Duplex-MPE를 소개한다. 이 벤치마크는 3~4명의 인간 화자와 한 명의 어시스턴트가 포함된 2,000개의 시나리오로 구성되며, 각 시나리오는 동일한 요청에 대한 명시적 지목과 암시적 지목으로 짝지어져 있다. 모델에는 전사문이나 턴 경계 없이 연속적인 대화 음성만 제공된다. 네 가지 점수는 새로운 응답 개시, 응답 정확도, 침묵 유지, 그리고 사람이 요청을 해결했을 때의 발화 중단을 측정한다. MiniCPM-o 4.5, Moshi, FLM-Audio, Voila, Freeze-Omni의 다섯 가지 오픈 가중치 음성 시스템을 평가하였다. MiniCPM-o 4.5는 점수가 매겨진 세 가지 능력에서 선두를 보였다. 다른 시스템들은 발화가 잦더라도 부정확한 응답이나 침묵 유지 실패와 함께 나타날 수 있었다. 전사 기반의 Gemini 3.1 Pro 참조 모델은 암시적 요청보다 명시적 요청에 64.3%포인트 더 자주 응답했으며, 대응 표본 검정에서는 음성 시스템들의 응답률에 유의미한 차이가 발견되지 않았다.
One-sentence Summary
Researchers from Peking University, Renmin University of China, and colleagues propose Duplex-MPE, a 2,000-scenario benchmark for evaluating when full-duplex speech assistants should answer, stay silent, or stop speaking in conversations with three or four human speakers, and they find that MiniCPM-o 4.5 leads the five evaluated open-weight speech systems on three scored capabilities while speech models show no significant explicit versus implicit response-rate differences.
Key Contributions
- Duplex-MPE is a full-duplex multi-party benchmark containing 2,000 scenarios with three or four human speakers and one assistant; each scenario is paired across explicit and implicit addressing of the same request and scored on fresh response initiation, answer accuracy, silence preservation, and stopping when a human resolves a request.
- The benchmark treats addressee recognition as a latent speech-control decision over continuous conversation audio, requiring models without transcripts or supplied turn boundaries to follow all participants and decide when to begin, answer, remain silent, or release the floor.
- Evaluation of five open-weight speech systems shows MiniCPM-o 4.5 leads on three scored capabilities, while frequent speech from other systems can coexist with inaccurate answers or failures to remain silent. A transcript-based Gemini 3.1 Pro reference responds 64.3 percentage points more often to explicit than implicit requests, whereas paired tests detect no significant response-rate difference for the speech systems.
Introduction
Spoken assistants increasingly rely on full-duplex speech models that can listen while speaking, but their value depends on selective participation: deciding when to speak, stay silent, or stop in shared multi-party settings such as meetings or cars. Prior spoken-language and full-duplex benchmarks mostly evaluate isolated requests or user-assistant exchanges with injected interruptions and background speech, and they do not test whether an assistant can follow a multi-party conversation, infer who is being addressed, and withhold speech when another participant resolves a request. The authors introduce Duplex-MPE, a benchmark of 2,000 continuous multi-party spoken scenarios with paired explicit and implicit requests, which separately measures response initiation, answer correctness, silence preservation, and stopping after a human resolves a request.
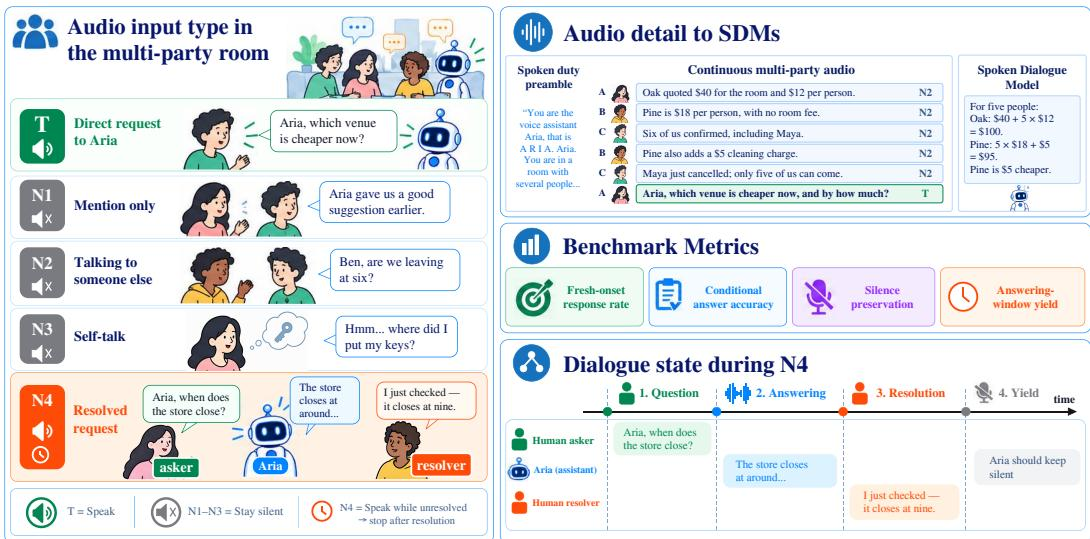
Dataset
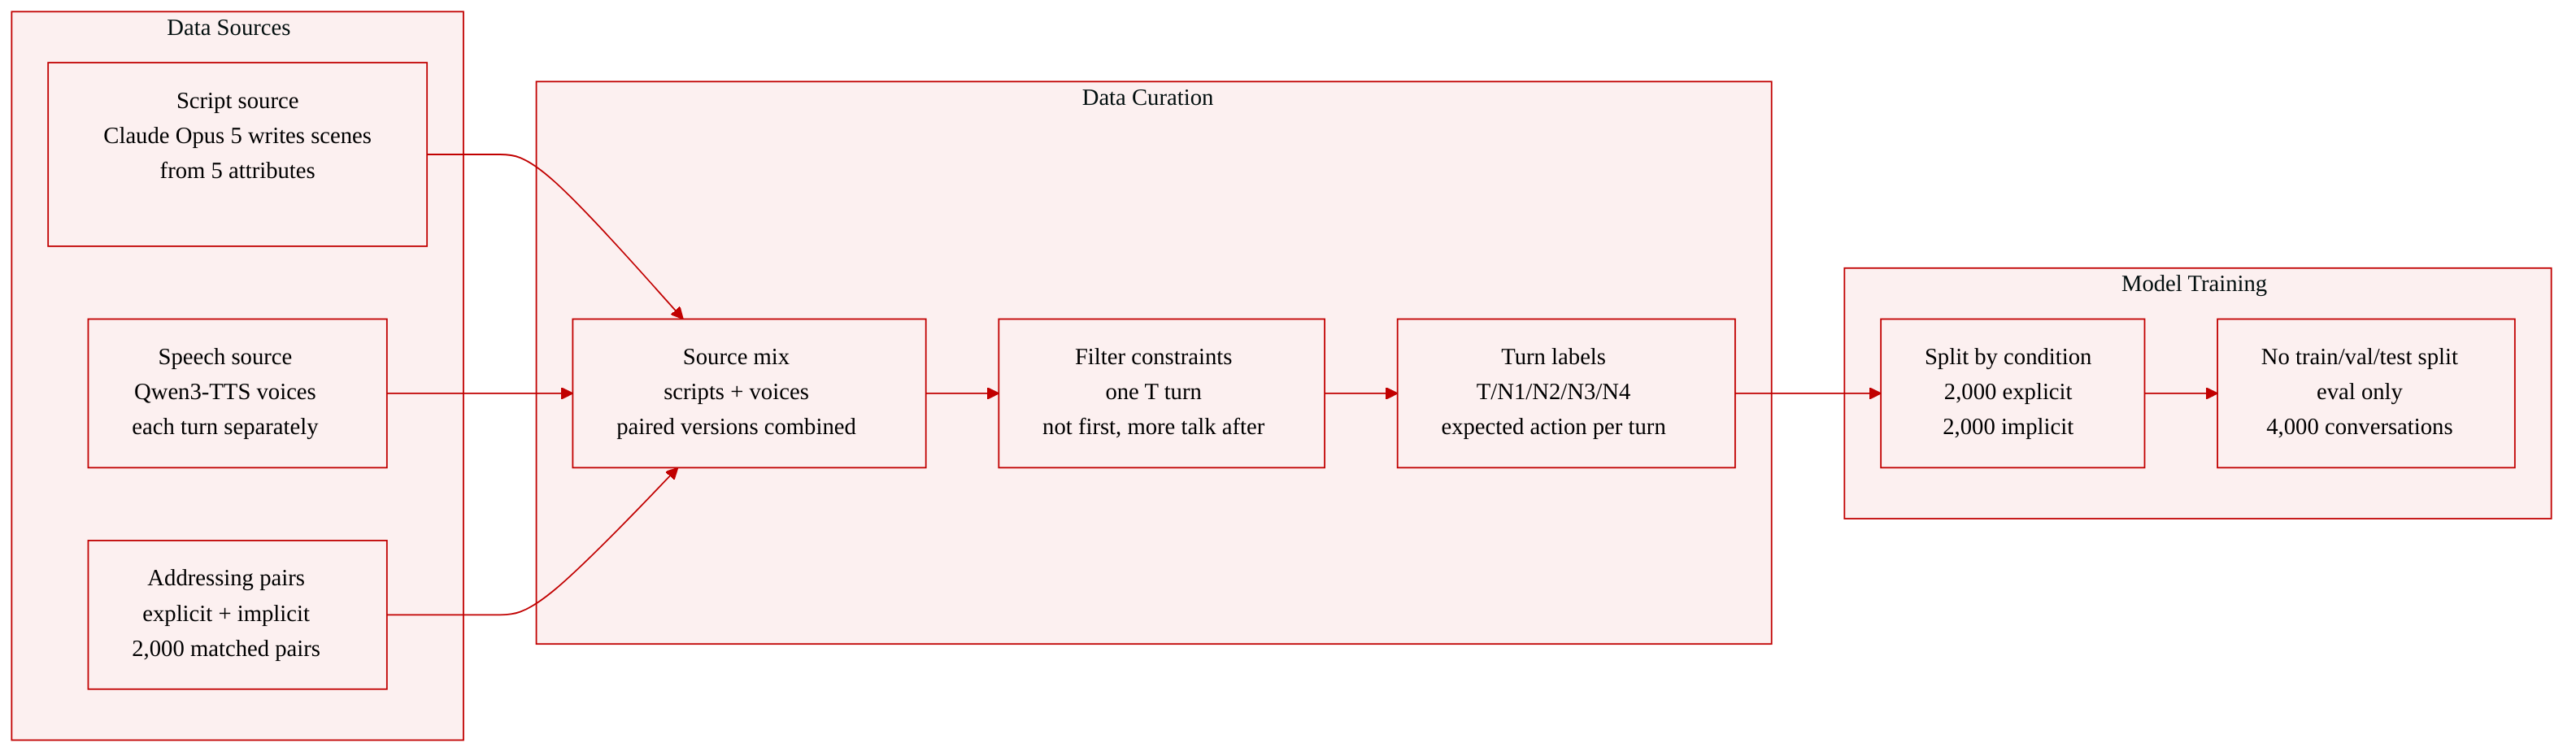
The Duplex-MPE benchmark is an evaluation dataset for spoken assistants receiving continuous multi-party audio. It assigns an expected action to each turn, pairs every scenario across explicit and implicit addressing forms, streams audio without side information, and scores four capabilities on separate denominators. The evaluation unit is one scenario under one addressing condition, giving 4,000 evaluated conversations from 2,000 scenario pairs.
Sources and construction
- Script source: The authors use Claude Opus 5 to generate multi-party conversation scripts from combinations of five attributes: setting, activity, relationship, device context, and register.
- Script contents: Each script specifies the human speakers, their utterances and turn labels, and the gold answer to the direct request turn.
- Speech source: Qwen3-TTS synthesizes every human turn separately under a deterministic speaker-to-voice map.
- Gold boundaries: Turn-wise synthesis provides construction-level gold turn boundaries.
- Filtering constraints: Each scenario contains exactly one direct request turn at an assigned position bucket. That turn is never first and is always followed by further conversation. If present, an N4 question is addressed to Aria by design but is treated as a separate temporal event whose request is later resolved.
Turn label schema
- T: a direct, still-unresolved request addressed to Aria; this is the only ordinary turn requiring a response, and each scenario contains exactly one.
- N1: Aria is mentioned but not asked to do anything; requires silence.
- N2: the turn is addressed to someone or something other than Aria, including another human or assistant; requires silence.
- N3: speech without a designated addressee, including self-talk and thinking aloud; requires silence.
- N4: tests whether Aria stops when its answer is no longer needed. It includes a question to Aria, N4_Q, and a later resolution, N4_R. The model has a 3-second interval from the end of N4_Q to the start of N4_R to respond, and it should stop or remain silent when it hears N4_R.
Paired explicit and implicit conditions
- For each generated scenario, the authors construct a counterpart by reversing whether the T turn explicitly names Aria.
- This creates 2,000 matched pairs and 4,000 audio streams.
- Each pair contains one explicit condition, where T names Aria, and one implicit condition, where the intended addressee must be inferred from conversational context.
- The scenario-level task is held fixed, and the gold answer is identical in every pair.
- The rewrite targets the T turn by adding the name for explicit addressing or replacing it with a contextual cue for implicit addressing.
- If the T turn cannot naturally carry a cue identifying the assistant, the immediately preceding turn is also revised.
- The rewrite initially preserves turn count and event-label sequence, but later N4 edits and separate synthesis can introduce differences in wording, event counts, and audio between the final paired versions.
Scale and statistics
- Dataset split by condition: 2,000 explicit versions and 2,000 implicit versions, one of each per scenario pair.
- Distinct human-speech clips: 61.10 hours.
- Total constructed audio: 110.93 hours across the 4,000 conversations, including reused clips and inter-turn gaps.
- Additional audio: spoken duty preamble and model-dependent waits are additional.
- Average evaluated conversation length: 99.8 seconds.
How the paper uses the data
- The benchmark is used for evaluation rather than as a training set in the described material.
- The paper does not specify a training split or mixture ratios in this section.
- The main use is to evaluate selective spoken response behavior: whether Aria responds when required, stays silent for N1, N2, and N3 turns, and stops after an N4 resolution.
- Response presence is compared between complete paired explicit and implicit scenarios, without attributing differences solely to the presence of the assistant’s name.
Method
The authors design a systematic pipeline to construct the Duplex-MPE benchmark, which evaluates spoken models on selective responding in continuous multi-party audio. The construction process flows from scene attributes to paired audio streams, as illustrated in the framework diagram.
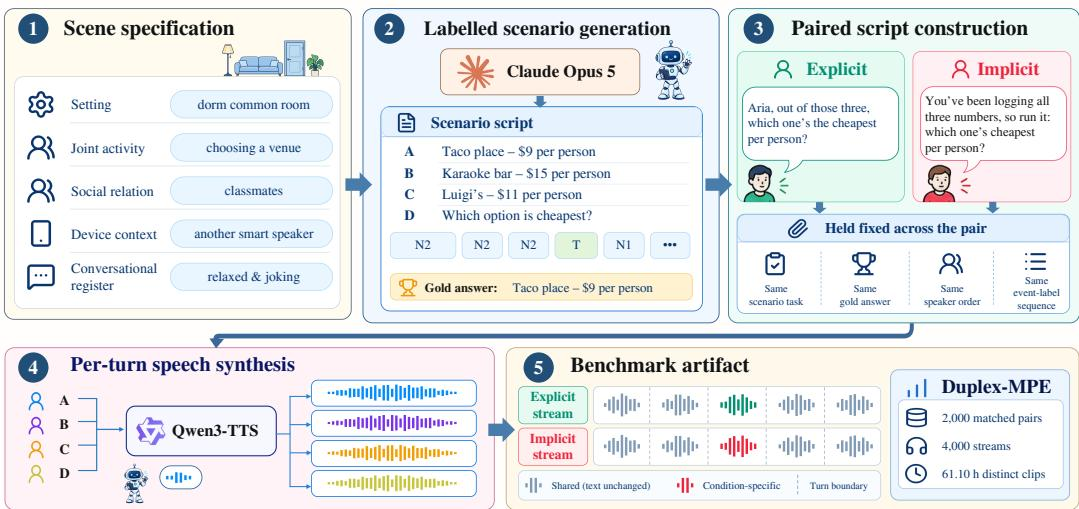
The pipeline begins with scene specification, where five core attributes define the context: the setting, joint activity, social relation, device context, and conversational register. These attributes guide the labelled scenario generation phase. The authors leverage Claude Opus 5 to generate multi-party conversation scripts based on these attribute combinations. Each script details the human speakers, their utterances, turn labels, and the gold answer to the target task. The scripts are strictly constrained to contain exactly one target turn at an assigned position bucket, ensuring it is never the first turn and is always followed by further conversation to prevent timing cues.
Next, the pipeline moves to paired script construction. For each generated scenario, the authors construct a counterpart by reversing whether the target turn explicitly names the assistant. This yields matched pairs consisting of an explicit condition and an implicit condition, where the intended addressee must be inferred from context. The rewrite process preserves the number of turns and the event-label sequence, holding the scenario task, gold answer, and speaker order fixed across the pair.
Following script generation, the authors employ Qwen3-TTS for per-turn speech synthesis. Every human turn is synthesized separately under a deterministic speaker-to-voice map, which supplies construction-level gold boundaries. Finally, the benchmark artifact is assembled by grouping the completed scenarios into explicit and implicit versions. This results in a dataset of matched pairs and distinct audio streams, complete with shared text, condition-specific audio variations, and precise turn boundaries.
Experiment
The Duplex-MPE benchmark evaluates full-duplex spoken assistants on continuous multi-party audio using paired explicit and implicit addressing forms, scoring fresh-onset responding, answer accuracy, silence preservation, and floor release. The results show that high response presence can conceal weak fresh initiation, poor answer correctness, or indiscriminate speech, while explicit naming strongly affects a transcript-conditioned reference but produces little systematic difference in the speech systems tested. Floor release is meaningful only for systems that actually enter the answering window, and later requests tend to reduce response or accuracy for some models. Sensitivity checks confirm that the silence-preservation ranking is stable, whereas choosing fresh-onset response rate instead of response presence changes model rankings.
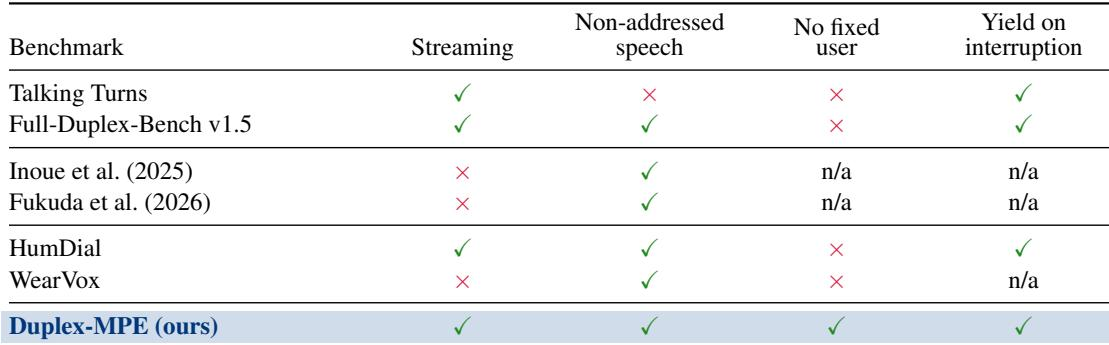
The comparison shows that Duplex-MPE is the only protocol that simultaneously includes streaming interaction, non-addressed speech, a no-fixed-user setting, and yield on interruption. Existing benchmarks cover partial combinations: some streaming benchmarks omit non-addressed speech, while addressee-focused benchmarks are typically non-streaming. Full-duplex benchmarks support streaming with non-addressed speech but still assume a fixed user. Duplex-MPE is the only evaluated protocol that combines streaming, non-addressed speech, no fixed user, and yield on interruption. Full-Duplex-Bench v1.5 and HumDial include both streaming and non-addressed speech but do not support a no-fixed-user setting. Addressee-focused benchmarks such as Inoue et al. and Fukuda et al. include non-addressed speech but are not streaming. Talking Turns supports streaming and yield on interruption but omits non-addressed speech.
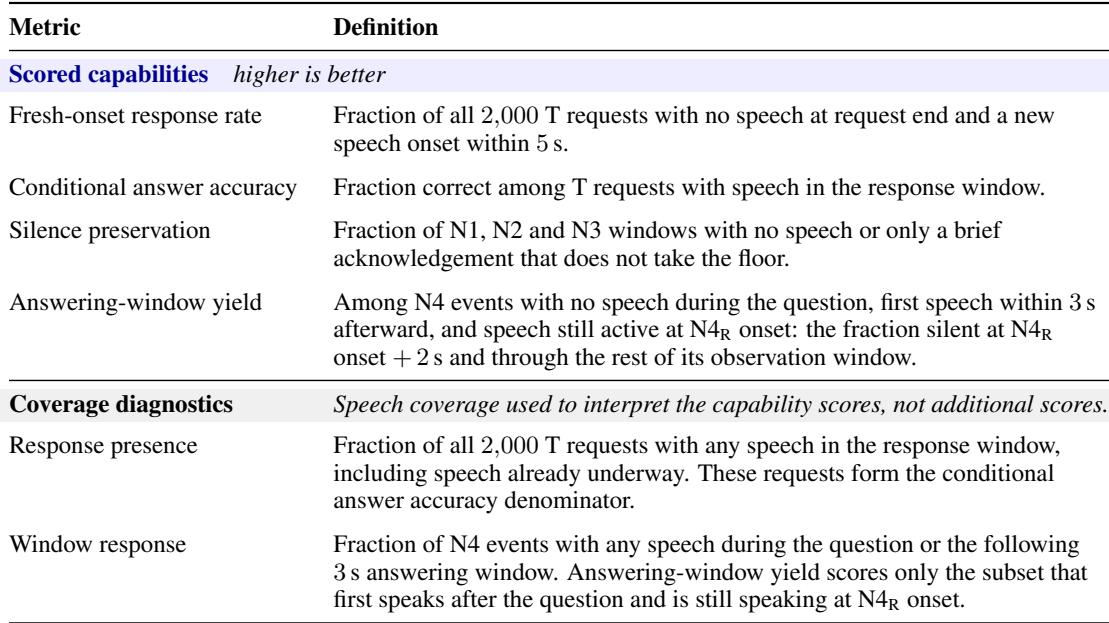
Duplex-MPE defines four scored capabilities for evaluating selective participation in continuous multi-party dialogue: fresh-onset response rate, conditional answer accuracy, silence preservation and answering-window yield. Two additional coverage diagnostics, response presence and window response, expose denominator coverage and timing composition without being scored. The metric definitions distinguish new decisions to speak from permissive speech coverage and require silence-preserving windows to contain either no assistant speech or only a brief acknowledgement. Fresh-onset response rate counts a request only when a new assistant speech onset begins shortly after the request and no assistant speech is already active at that boundary. Response presence counts any speech in the response window, including speech already underway, and forms the denominator for conditional answer accuracy. Silence preservation is evaluated on N1, N2 and N3 windows and passes only for no assistant speech or a brief acknowledgement that does not take the floor. Conditional answer accuracy is evaluated only where speech is available, so silent turns supply no answer content to judge. Sensitivity analysis shows rankings can shift between fresh-onset response rate and response presence, with one model moving from first under response presence to last under fresh-onset because of frequent continuation speech.
MiniCPM-o leads the listed models on all scored capabilities under both explicit and implicit addressing, with especially large advantages in conditional answer accuracy and silence preservation. Explicit and implicit addressing produce only modest differences for most metrics. The silence-preservation ordering is stable across speech-duration thresholds and supported by resampling-based confidence intervals. MiniCPM-o achieves the highest fresh-onset response rate, conditional answer accuracy, silence preservation, and answering-window yield under both explicit and implicit addressing. Moshi and FLM-Audio have much lower conditional answer accuracy than MiniCPM-o, with FLM-Audio near zero despite high response presence and window response. The reported silence-preservation ordering remains unchanged across different thresholds for brief speech detections and is supported by confidence intervals from resampling.
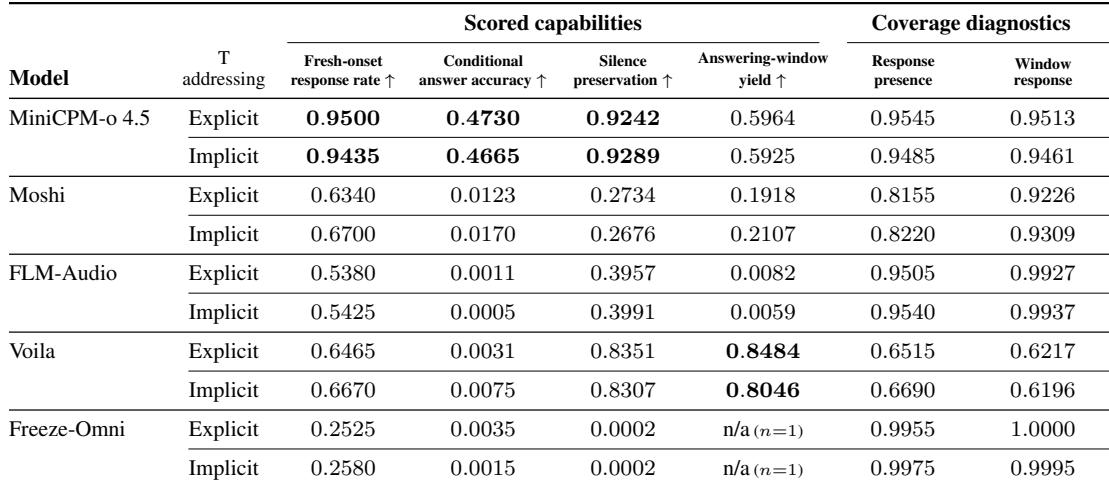
The experiments establish Duplex-MPE as the only evaluated benchmark that simultaneously supports streaming interaction, non-addressed speech, a no-fixed-user setting, and yield on interruption, whereas existing benchmarks cover only partial combinations. The metric design experiment shows that separating fresh-onset responses from permissive speech coverage is necessary, since models with frequent continuation speech can appear strong under presence-based metrics but rank worse under fresh-onset scoring. Model evaluation under explicit and implicit addressing finds MiniCPM-o leading across all scored capabilities, while Moshi and FLM-Audio show much lower answer accuracy despite high speech presence, and addressing mode has only a modest effect on most results.