Command Palette
Search for a command to run...
월드 모델에서 객체 영속성 훈련
월드 모델에서 객체 영속성 훈련
초록
객체 영속성과 고체성은 인간 인지 사전지식의 핵심 특징이다. 최근 연구들은 현재 월드 모델의 대표적인 부류인 비디오 생성 모델이 창발적 추론 능력을 보이기 시작했으며, 이로 인해 인간과 유사한 물리 지능을 구축하기 위한 이상적인 후보가 되고 있음을 보여준다. 비디오 모델은 내부에 창발적 객체 영속성을 갖추고 있는가? 그렇지 않다면 핵심 인지에서 영감을 받은 데이터셋으로 이를 훈련시킬 수 있는가? 우리는 인지과학에서 영감을 받아 수작업으로 설계한 150개 과제를 6개 인지 범주로 나눈 데이터 인프라 WROP(World Reasoning with Object Permanence)을 소개한다. 우리는 각 과제의 인지 구조를 보존하면서 속도, 조명, 카메라 각도 및 기타 방해 변수(nuisance parameters)를 무작위화하는 Blender 생성기를 구축하여 과제당 10,000개 이상의 샘플을 산출한다. 우리는 150만 샘플 규모의 훈련 코퍼스와 300문항 시험을 공개한다. 이 시험에서 우리는 reference-to-video 3종, edit 7종, continuation 4종을 포함한 14개 비디오 모델을 평가하며, 여기에는 우리의 16B 월드 모델 PWM-WROP도 포함된다. 블라인드 쌍대 비교 Elo 연구에서 PWM-WROP은 continuation 모델 중 1위, 전체 3위를 차지했으며, 그보다 높은 순위는 통계적으로 동률을 이룬 두 reference-to-video 모델뿐이었다. 우리는 데이터, 시험, 모델 답안, 점수, 가중치, 그리고 AWS Trainium2 상의 네이티브 PyTorch 훈련 스택인 PWM을 공개한다.
One-sentence Summary
University of Southern California and collaborators introduce WROP (World Reasoning with Object Permanence), a cognitive-science-inspired data infrastructure with 150 hand-designed tasks across six categories, a 1.5M-sample training corpus, and a 300-question exam, which they use to train and evaluate PWM-WROP, a 16B world model that ranks first among continuation models and third overall in a blind pairwise Elo study.
Key Contributions
- The paper introduces WROP, a benchmark and training resource built from 150 hand-designed Blender task generators across six cognitive categories, yielding a 1.5-million-sample training corpus and a fixed 300-question exam for object permanence and object solidity.
- It evaluates 14 video generation models spanning reference-to-video, edit, and continuation settings with blind pairwise human Elo ratings; the 16B PWM-WROP model ranks first among continuation models and third overall, behind only a statistical tie between two reference-to-video models.
- The work releases the corpus, exam, model answers, scores, weights, and the PWM training stack on AWS Trainium2, and offers preliminary evidence that training on cognitively principled synthetic data is a viable path toward enabling physical reasoning in video generation models.
Introduction
Recent video generation models produce photorealistic, temporally coherent footage and are increasingly treated as world models, yet they still fail at object permanence and object solidity, for example by letting occluded objects reappear in impossible positions or pass through solid barriers. This matters because object permanence and solidity are foundational core-knowledge abilities in human physical intelligence and are upstream requirements for valid collision, support-removal, and higher-level causal reasoning. Prior benchmarks often remain limited to 2D or image-to-video settings, provide little or no training data, and rely on VLM-based scoring even though VLMs have systematic deficits in the same physical reasoning capacities under test. The authors address these gaps with WROP, a 3D synthetic benchmark constructed from 150 Blender generators across six task families, including a 1.5-million-sample training corpus, a fixed 300-question human-evaluated exam, and a post-trained 16B continuation model, PWM-WROP, that ranks first among true continuation models in human pairwise comparison.
Dataset
The authors use a synthetic dataset built from 150 parameterized Blender task generators. It is not drawn from real videos; all clips are hand-authored 3D animations rendered at 1280×720 and 24 fps. The generators are organized into six families across two cognitive dimensions: object permanence (OP) and object solidity (OS). Structural parameters control the physical and cognitive challenge, while surface-level parameters such as color, material, lighting, and camera viewpoint are randomized for visual diversity.
Task families
- OP-1: Baillargeonian Occlusion. A target moves behind an occluder and must reappear with identity, size, and motion intact.
- OP-2: Object Static Occlusion. A moving occluder covers static objects; removal must reinstate the original number, identity, and spatial arrangement.
- OP-3: Container Permanence. An object is concealed inside a container that may move or swap; the object must stay bound to the container’s new position.
- OS-1: Baillargeonian Obstruction. A moving object approaches a barrier with an aperture and must be blocked or permitted based on object-to-aperture size.
- OS-2: Object Drop. A support surface is removed; the object must fall, and a size-aperture filter determines whether it passes through or rests.
- OS-3: Object Collision. A moving object strikes a stationary configuration and must produce physically consistent post-collision trajectories without merging or interpenetrating.
Scale and sample format
- Training corpus: 1,500,000 samples from 150 generators, with 10,000 samples per generator.
- Evaluation exam: 300 questions, using 2 samples from each of the 150 generators.
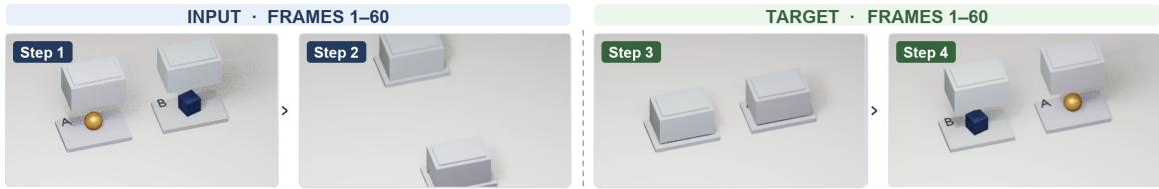
- Every sample is a 120-frame physically consistent animation split at the key event into a 60-frame input video and a 60-frame target video.
- Each sample includes a natural-language prompt, a per-frame trajectory of object poses, and a metadata record describing the scene state.
- Motion is authored as Blender keyframe animation, not produced by a physics engine; trajectory arrays are sampled from that animation.
Generation and validation
- Each task is implemented as a self-contained, parameterized Blender generator specifying objects, scene geometry, initial conditions, keyframed motion, camera setup, prompt, and expected physical outcome.
- No rigid-body solver is used; trajectories are authored analytically so occlusion, contact, and reappearance occur at controlled frames.
- A shared driver renders through Blender 4.4.3 with EEVEE Next. A random seed controls surface variation while preserving camera, geometry, spatial configuration, and physical mechanism.
- The 120-frame animation is split at frame 60 into the 60-frame input and 60-frame target.
- Each sample is packaged as a five-tuple: input video, target video, prompt, trajectory, and metadata.
- Automated validation checks that all five components are present and readable, both clips share the same frame rate, each clip has exactly 60 frames, and the clips meet at frame 60 without a gap or overlap.
- Trajectory and metadata files are checked for required fields. Metadata records generator identity, sample index, random seed, and rendering configuration.
- Failed or invalid samples are rejected and regenerated. Before release, representative samples from every generator are manually inspected.
How the data is used
- The input half establishes pre-event scene context, and the target half captures the physical event and its consequence.
- The split aligns with a video-to-video evaluation protocol in which the model generates the 60-frame target from the 60-frame input.
- Training uses equal per-generator contributions, while evaluation draws two samples per generator to cover all 150 tasks.
Method
The authors design a data generation pipeline where each generator instantiates its task family's physical scenario as a self-contained 3D Blender scene. Diverse everyday objects and scene configurations are utilized to test the same physical principle across visually distinct settings. To prevent models from relying solely on final position, the authors introduce multiple physically valid outcomes within a single generator. For instance, in the Marked Boxes Swap task, two labeled boxes close over distinct objects, exchange screen positions, and reopen with each object still associated with its original marked box. This construction requires the model to track box identity and hidden contents through motion and occlusion. Scene geometry, object trajectories, contact timing, occlusion coverage, and camera placement are revised whenever object interpenetration or other physical violations are observed during inspection.
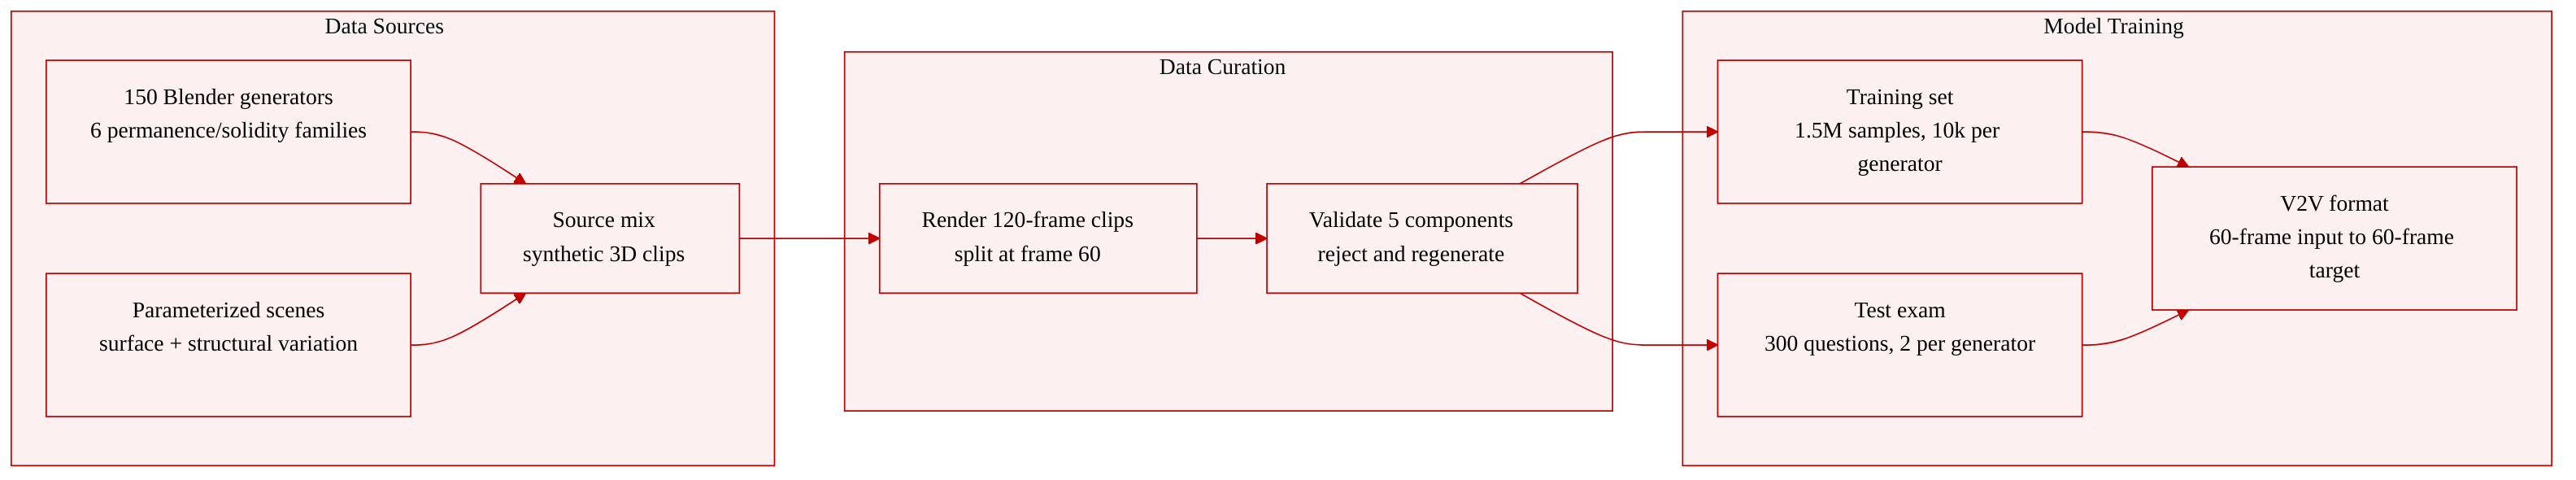
The data generation pipeline consists of three main stages. First, in the task-specific generator implementation stage, each of the 150 tasks is implemented as a self-contained, parameterized Blender generator. This generator specifies objects and their semantic roles, scene geometry, initial conditions, the keyframed motion and contact events that constitute the task, camera configuration, natural-language prompt, and expected physical outcome. No rigid-body solver is used; every trajectory is authored analytically so that occlusion, contact, and reappearance occur at controlled frames, making physical plausibility the responsibility of the scene author rather than a simulator.
Second, during sample generation and construction, a shared driver executes each generator through a common Blender rendering backend. A recorded random seed controls surface variations in object color, material, and scene lighting, while the authored camera, geometry, spatial configuration, and physical mechanism are preserved. The renderer produces a 120-frame animation, which is split at frame 60 to yield a 60-frame input video and a 60-frame target video. Each sample is packaged as a five-tuple comprising the input video, target video, prompt, trajectory, and metadata.
Third, in the large-scale generation and validation stage, generators run independently across parallel workers, with each contributing 10,000 training samples. Failed renders are automatically retried and logged, and an automated audit verifies file completeness and schema validity. Each generated sample undergoes automated validation before admission to the dataset. The authors verify that all five components are present and readable, that both clips share the same frame rate, and that each contains exactly 60 frames meeting at frame 60 without a gap or overlap. Trajectory and metadata files are checked for required fields, with the metadata recording generator identity, sample index, random seed, and rendering configuration to allow every sample to be traced to its generation conditions. Samples failing any check are rejected and regenerated. Before release, representative samples from every generator are manually inspected to confirm that the rendered sequence matches the intended task definition and that the split boundary is correctly placed.
Experiment
This evaluation measures video-to-video models on object permanence and solidity by fine-tuning PWM-WROP on the WROP corpus and comparing it with thirteen systems across true-continuation, reference-to-video, and edit or transfer interfaces. Human preference results show that reference-to-video models lead overall, while PWM-WROP is the strongest true-continuation model, suggesting that domain-specific fine-tuning improves physical reasoning and that interface class matters more than model scale. Task-family and qualitative analyses indicate that occlusion tracking and contact-based solidity make different demands, with PWM-WROP excelling on occlusion tasks but more variable on solidity tasks, while common failures involve representation dropout or causal decoupling. Automatic metrics are treated as secondary because they measure reference similarity rather than physical correctness.
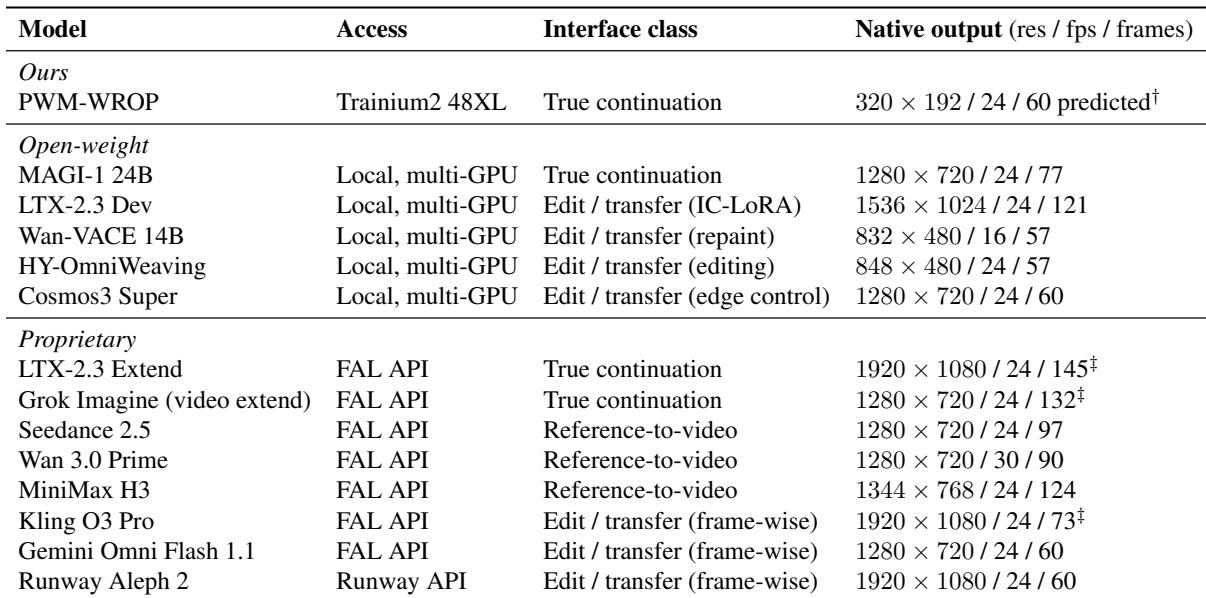
The evaluation covers fourteen video-to-video models grouped by provenance, access route, interface class, and native output geometry. The systems fall into true continuation, reference-to-video, and edit/transfer classes, with open-weight models run locally and proprietary models accessed through hosted APIs. Native output resolutions and frame counts vary widely across the set, and the proposed model generates lower-resolution clips than several open-weight alternatives. The fourteen systems split into true continuation, reference-to-video, and edit/transfer interface classes, reflecting different relationships to the conditioning clip. Open-weight models are run locally on multi-GPU hardware, while proprietary models are accessed through hosted APIs. True continuation models include the proposed PWM-WROP, MAGI-1, LTX-2.3 Extend, and Grok Imagine, while edit and transfer models include Wan-VACE, HY-OmniWeaving, LTX-2.3 Dev with IC-LoRA conditioning, Cosmos3 Super, Kling O3 Pro, Gemini Omni Flash, and Runway Aleph 2. The proposed model outputs lower spatial resolution clips than several open-weight baselines, whose native resolutions reach substantially higher dimensions.
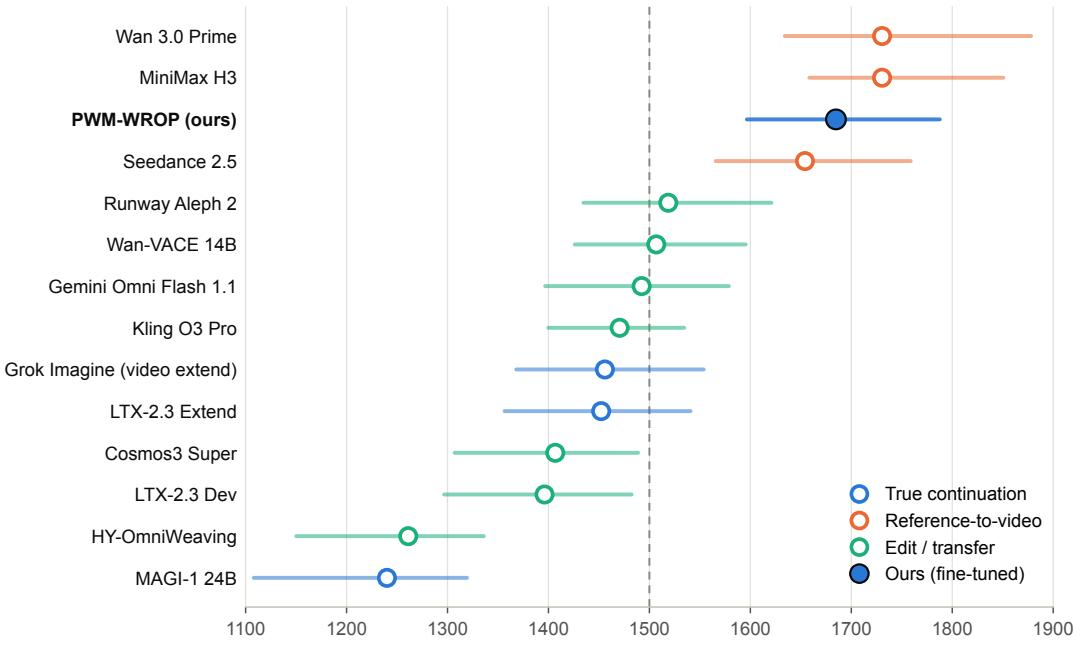
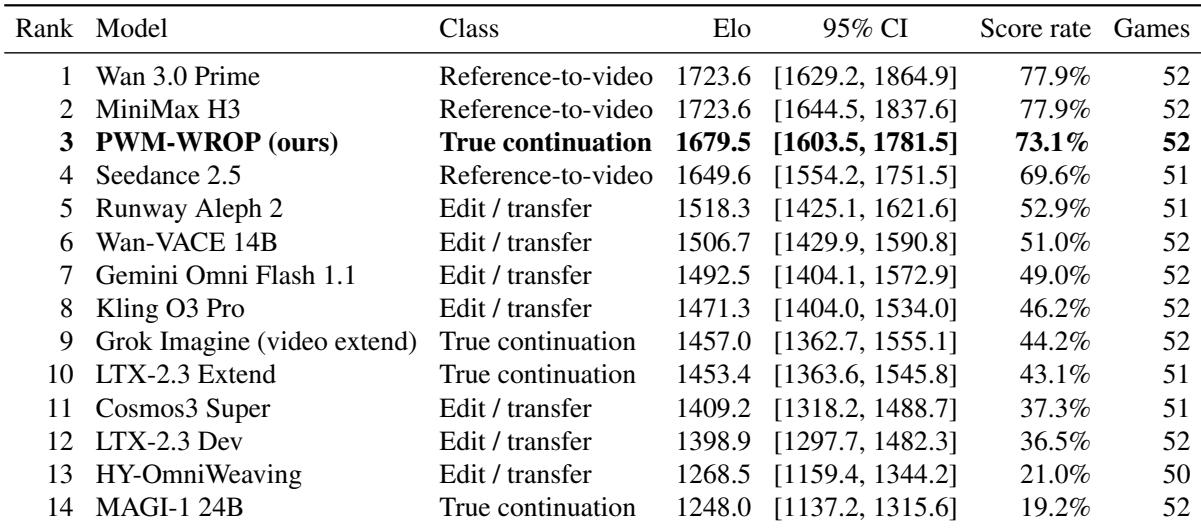
Reference-to-video models lead human preference rankings, with Wan 3.0 Prime and MiniMax H3 tied at the top and Seedance 2.5 also among the leaders. PWM-WROP is the highest-ranked true-continuation model, placing third overall and clearly ahead of the next true-continuation system. Edit and transfer models cluster near the middle of the leaderboard, while the remaining true-continuation models rank lower. Reference-to-video models dominate the leaderboard, with Wan 3.0 Prime and MiniMax H3 tied for first and Seedance 2.5 in fourth. PWM-WROP is the top true-continuation model, ranking third overall and outperforming the next-best true-continuation model by a large Elo margin.
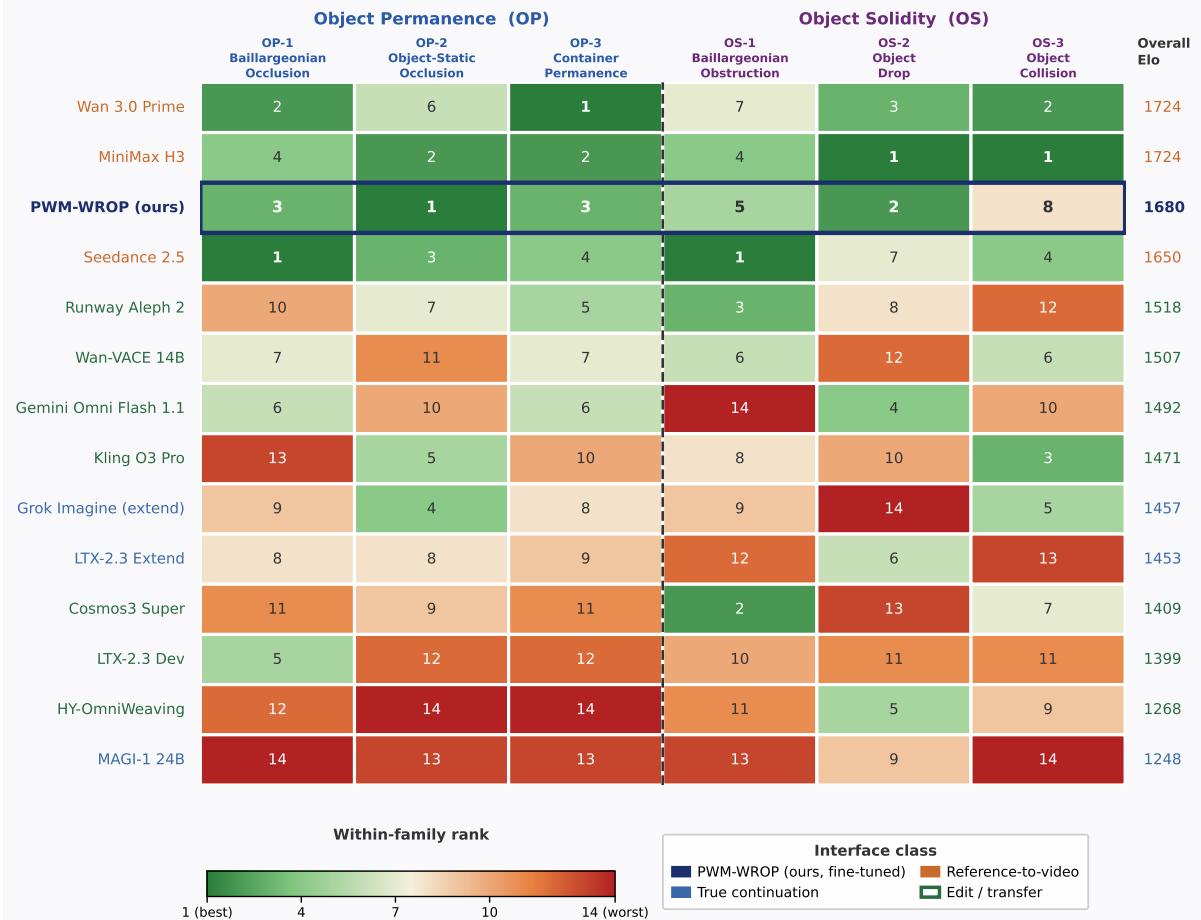
Human-preference ranks vary substantially across the six object permanence and object solidity task families, with no model uniformly leading. PWM-WROP is among the top models overall and shows its strongest family-level results in object-static occlusion and object drop, but performs relatively poorly on object collision. The variation aligns with a broader divide between occlusion tracking and obstruction or collision reasoning. No model dominates all six families; top ranks shift between occlusion, obstruction, and collision tasks. PWM-WROP performs best in object-static occlusion and object drop, but is among the weaker models in object collision. MiniMax H3 is consistently strong across families, while lower overall-ranked models such as Seedance still win individual occlusion and obstruction cases.
Full-reference metrics show PWM-WROP leading on perceptual distance, multi-scale structural similarity, and pixel error, while MiniMax H3 leads on CLIP similarity, PSNR, and FID. PWM-WROP's advantage weakens on resolution-sensitive measures, where its upsampled output shows relatively high FID. These metrics measure similarity to the target video rather than physical reasoning, so models that reproduce static scene appearance can rank well without depicting correct object permanence. PWM-WROP achieves the best LPIPS, MS-SSIM, MSE, and final-frame MSE among evaluated models and ranks second on CLIP similarity. MiniMax H3 leads CLIP similarity, PSNR, and FID, while edit or transfer models can score well on structural metrics without generating the required reappearance.
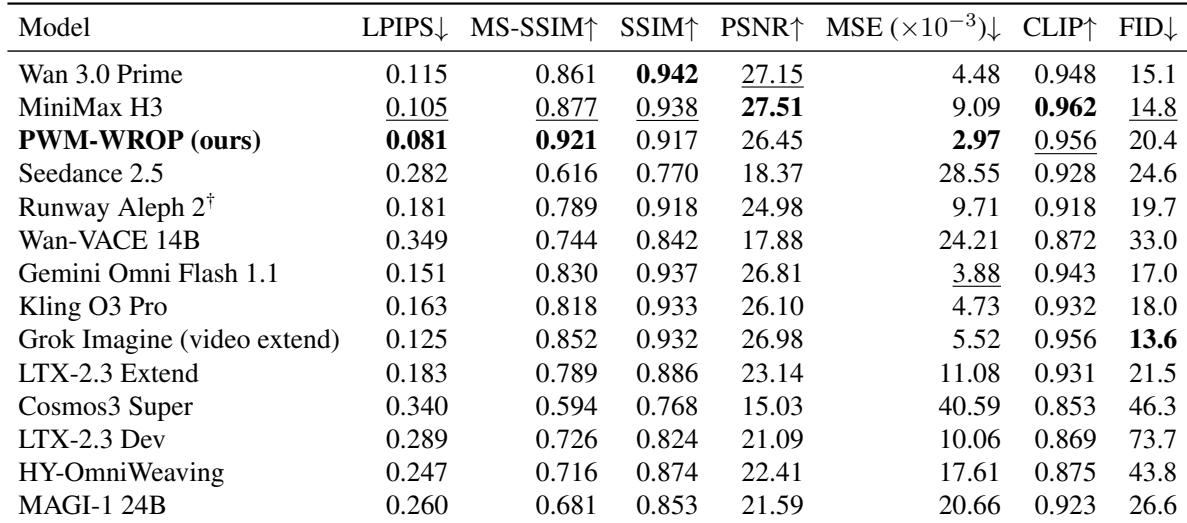
The study evaluates fourteen video-to-video models across true continuation, reference-to-video, and edit/transfer classes, combining local open-weight inference and hosted API access with human preference rankings, task-family breakdowns, and full-reference metrics. Reference-to-video models lead overall human preference, while the proposed PWM-WROP is the strongest true-continuation model and ranks third overall, performing well on object-static occlusion and object drop but relatively poorly on object collision. Full-reference metrics favor PWM-WROP on perceptual and structural similarity while MiniMax H3 leads on resolution-sensitive measures, although these metrics reflect appearance similarity rather than physical reasoning.