Command Palette
Search for a command to run...
Agent-Editing World Model: LLM 에이전트를 위한 월드 모델링의 재고찰
Agent-Editing World Model: LLM 에이전트를 위한 월드 모델링의 재고찰
Shuang Sun Guoxin Chen Fanzhe Meng Jia Deng Huatong Song Jinhao Jiang Wayne Xin Zhao Hongteng Xu Ji-Rong Wen
초록
최근 대규모 언어 모델(LLM)의 발전으로 에이전트가 다양한 환경에서 장기적인 과제를 수행할 수 있게 되었다. 에이전트 성능을 더욱 향상시키기 위해 기존 언어 월드 모델은 일반적으로 환경 관측을 예측하지만, 실제 피드백이 제공되는 상황에서는 높은 엔트로피를 가지며 실행에 의존하는 도구 응답을 재구성하는 것이 제한적인 가치밖에 없다. 한편 에이전트는 작업 상태 오염 문제를 겪는데, 이는 근거가 부족한 가정과 오래된 계획이 이력에 남아 이후 의사결정을 왜곡하는 현상이다. 우리는 도구 응답을 모사하는 대신 추론과 행동이 미래의 작업 진행에 어떻게 영향을 미치는지 모델링하는 에이전트-편집 월드 모델(Agent-Editing World Model, AEWM)을 제안한다. AEWM은 CRITICAL, EXPLORATORY, NOISY 결정을 구분하는 Action Judge와 동일한 관측 이력으로부터 잡음이 있는 추론-행동 연속을 편집하는 State Revision을 결합한다. EditAct는 이러한 기능을 실제 실행과 통합하여 단순히 비판을 제공하는 데 그치지 않고 이후 의사결정의 기반이 되는 상태를 직접 변경한다. 우리는 중간 학습(mid-training)과 지도 미세 조정을 통해 검색, 터미널, 소프트웨어 공학 분야에서 AEWM을 학습시킨다. AEWM은 Action Judge 벤치마크에서 70.5% macro-F1을 달성하여 가장 강력한 프런티어 기준선을 10.6포인트 초과한다. 6개의 벤치마크와 3개의 에이전트 백본에 걸쳐 EditAct는 가장 강력한 기준선 대비 평균 점수를 3.26.7포인트 향상시킨다. 또한 검증된 EditAct 궤적에 대한 거부 샘플링 미세 조정인 AEWM-RFT는 온라인 AEWM 안내 없이도 세 영역에서 Self-RFT보다 2.22.6포인트 향상된 성능을 보인다.
One-sentence Summary
Researchers at Renmin University of China propose the Agent-Editing World Model (AEWM), which models how reasoning and actions shape future task progress instead of simulating tool responses and combines Action Judge and State Revision to classify and edit noisy reasoning-action continuations; its EditAct integrates these capabilities with real execution, improving average scores by 3.2–6.7 points across six benchmarks and three agent backbones.
Key Contributions
-
The paper introduces the Agent-Editing World Model (AEWM), which models how reasoning and actions shape future task progress rather than simulating execution-dependent tool responses. AEWM combines Action Judge for classifying decisions as CRITICAL, EXPLORATORY, or NOISY with State Revision for editing noisy reasoning-action continuations, and EditAct applies these capabilities with real execution to alter the state behind subsequent decisions.
-
The work develops a cross-domain training framework that uses trajectory synthesis, mid-training, and supervised fine-tuning across Search, Terminal, and Software Engineering. It also contributes a 3,000-decision Action Judge benchmark and AEWM-RFT, which performs rejection sampling fine-tuning on verified EditAct trajectories to transfer decision patterns without online AEWM guidance.
-
AEWM reaches 70.5% macro-F1 on the Action Judge benchmark, exceeding the strongest frontier baseline by 10.6 points. EditAct improves average scores by 3.2 to 6.7 points across six benchmarks and three agent backbones, and AEWM-RFT surpasses Self-RFT by 2.2 to 2.6 points across three domains.
Introduction
World models are seen as a foundation for general intelligence and are increasingly important for long-horizon LLM agents that must understand task environments and sustain coherent decisions. Prior language world models typically follow an environment-centered objective, predicting action-conditioned next states or tool responses, but in open-ended agent tasks these observations are often high-entropy and execution-dependent, and reconstructing them provides limited value while risking simulated or fabricated evidence. The authors identify a recurring failure mode called task-state contamination, where agents accept unsupported assumptions, retain outdated plans, or mistake partial progress for completion. To address this, they propose the Agent-Editing World Model (AEWM), which shifts world modeling from reconstructing observations to modeling decision effects and editing agent states. AEWM includes Action Judge to classify proposed reasoning-action pairs as critical, exploratory, or noisy, and State Revision to replace noisy continuations before execution through EditAct, with training and transfer demonstrated across Search, Terminal, and Software Engineering domains.
Dataset
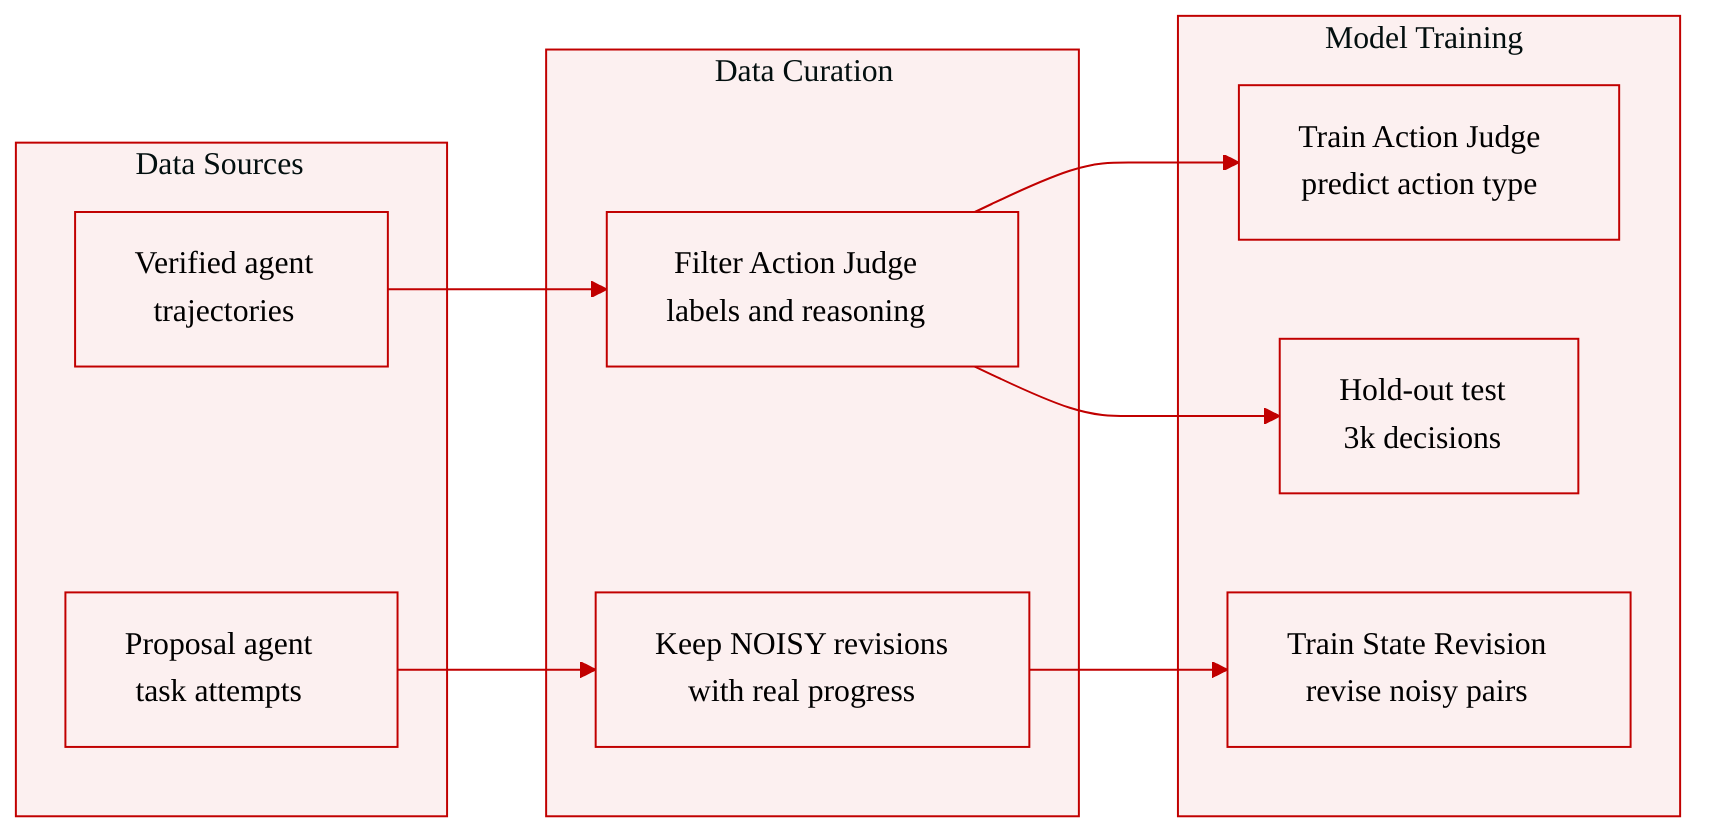
Dataset Description
The dataset is built from verified agent trajectories and is split into Action Judge and State Revision components.
Action Judge Data
- Composition: Turn-level annotations from successful, verified agent trajectories. Each example covers a single turn.
- Annotation and schema: An annotation agent labels each action as CRITICAL, EXPLORATORY, or NOISY based on the environment observation and its role in later task completion. It also writes a forward-looking reasoning trace. Inputs contain the visible history up to turn t and the proposed reasoning and action. Outputs contain the retrospective reasoning trace and action type.
- Filtering: The authors filter for label consistency, action-observation alignment, action validity, and reasoning grounded only in the pre-execution history.
- Benchmark: A held-out set of 3,000 decisions, equally distributed across Search, Terminal, and SWE. It is built from verified trajectories with repeated annotation, consistency filtering, model-based review, and diversity-aware sampling. Accuracy and macro-F1 are primary evaluation metrics.
- Size: The benchmark size is 3,000. The text does not specify the total training set size.
State Revision Data
- Composition: Created from tasks attempted by a proposal agent, with revisions generated by a separate revision agent and judged by an Action Judge checkpoint.
- Filtering: The authors retain only samples where the proposed action is labeled NOISY and the revised reasoning-action pair leads to substantive progress in the subsequent real-environment trajectory.
- Schema: Inputs contain the visible history and the noisy proposed reasoning-action pair. Outputs contain the revised reasoning-action pair.
Use in the Model
- Action Judge data trains the model to predict an action's downstream contribution from its pre-execution context.
- State Revision data trains the model to revise noisy proposed reasoning-action pairs into improved ones.
- The Action Judge benchmark is held out for evaluating pre-execution action judgment.
Method
The authors introduce the Agent-Editing World Model (AEWM), a framework designed to mitigate task-state contamination in long-horizon agent tasks. Task-state contamination occurs when agents treat unsupported assumptions as facts or retain outdated plans, allowing errors to persist and amplify through the interaction history. Rather than predicting high-entropy environment observations, AEWM directly models and edits the agent's reasoning and action states before execution.
Refer to the framework diagram for a comprehensive overview of the AEWM architecture, data synthesis pipeline, and integration process.
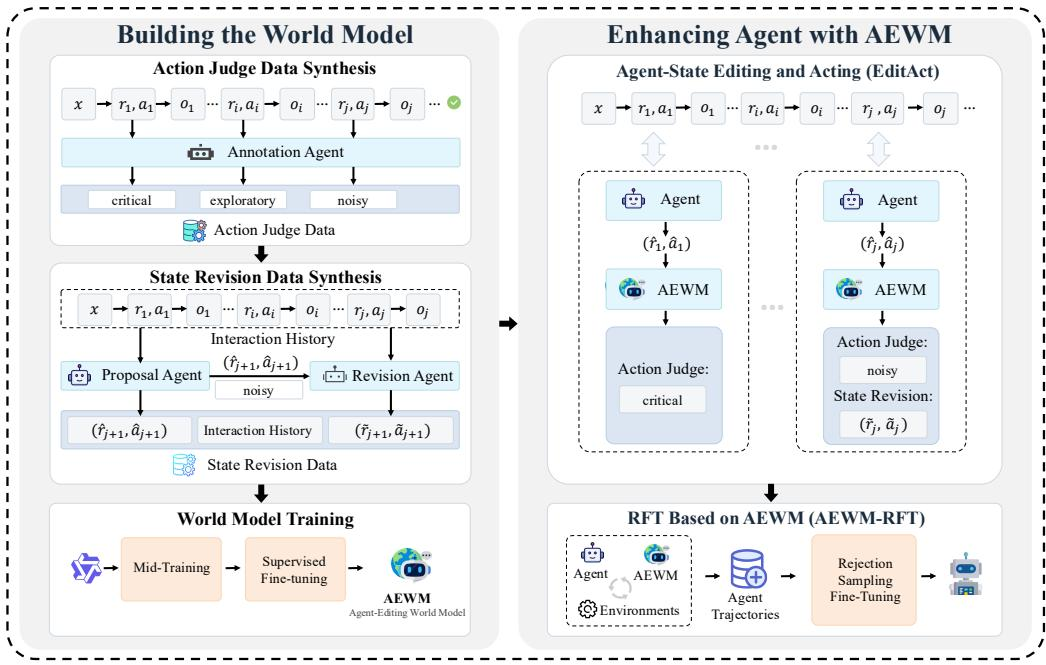
Agent State Modeling and Editing Given a task x, the interaction history before step t is denoted as ht=(x,(ri,ai,oi)i=0t−1). The agent proposes a reasoning and action pair (r^t,a^t), forming the pre-execution state st=ht⊕(r^t,a^t). AEWM, denoted as M, intervenes on this state through two primary modules: Action Judge and State Revision.
The Action Judge module, MAJ, evaluates the proposed continuation and predicts a decision-effect label yt∈{critical,exploratory,noisy}. Critical decisions close key gaps or perform required state changes, exploratory decisions reduce uncertainty or test plausible branches, and noisy decisions offer little progress or promote repetition and constraint violations.
If the Action Judge classifies a proposal as noisy, the State Revision module, MSR, generates a revised reasoning and action pair (rt,at) to form an edited state st. This grounded intervention contrasts with conventional observation-predictive world models:
Conventional WM: observation predictionstMobsotvs.AEWM: agent - state editingstMSRst=ht⊕(rt,at)EditAct: Integrating State Editing and Acting During inference, the authors integrate AEWM into the agent loop via a process called EditAct. At each step, the Action Judge produces the label yt=MAJ(st). The reasoning and action pair committed to the trajectory is determined by:
(rt,at)={(r^t,a^t),(rt,at),yt∈{critical, exploratory},yt=noisy.State Revision is invoked exclusively in the noisy case. The selected action at is then executed in the real environment E, yielding an observation ot∼E(⋅∣ht,at) and updating the history as ht+1=ht⊕(rt,at,ot). This loop allows state editing to redirect problematic decisions while real environment observations ground subsequent evolution.
Learning and Internalizing Agent Editing To train AEWM, the authors synthesize specialized datasets and employ a two-stage training process. Action Judge data is created by decomposing successful agent trajectories and using an annotation agent to label each turn as critical, exploratory, or noisy based on its downstream contribution. State Revision data is generated by having a proposal agent attempt tasks; when its noisy proposals are revised by a revision agent and lead to substantive progress, the revised pairs are retained.
The unified AEWM is trained across Search, Terminal, and SWE domains. The first stage is Mid-Training on a corpus of approximately 52 billion tokens, combining original trajectories with the synthesized data to teach the model broad task knowledge and decision-effect judgment. The second stage is Supervised Fine-Tuning (SFT) on a curated set of 120,000 examples, evenly split between Action Judge and State Revision tasks, to calibrate both capabilities.
Finally, the authors internalize the editing capabilities into the base agent through AEWM-based Rejection Sampling Fine-Tuning (AEWM-RFT). By running the agent with EditAct in real environments, they collect high-quality trajectories that include AEWM's state corrections. Fine-tuning the base agent on these verified trajectories allows it to learn local state corrections and sustain task progress independently, effectively internalizing the ability to avoid and recover from task-state contamination.
Experiment
The experiments evaluate EditAct across Search, Terminal, and SWE domains using ReAct and Best@3 baselines on six benchmarks, while separately assessing Action Judge and State Revision components. AEWM outperforms frontier models in action judgment, and EditAct improves over baselines across model scales and out-of-distribution benchmarks, with AEWM-RFT providing transferable supervision that improves success and often reduces turns. Ablations show that learned intervention selection, direct joint reasoning-action revision, and the full mid-training plus SFT recipe are important, while analyses indicate AEWM repairs task-state contamination by rechecking evidence, verifying execution, and preserving requirements.
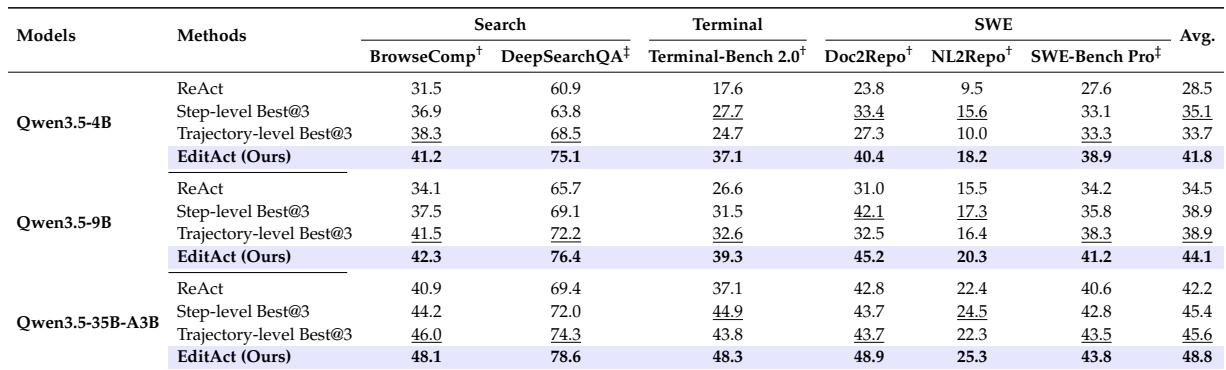
EditAct improves agent performance over ReAct and Best@3 baselines across benchmarks and model scales. The gains remain consistent on both in-distribution and out-of-distribution tasks, with especially large improvements in terminal and repository-related benchmarks. A mid-size model using EditAct can surpass a larger model using ReAct, indicating that the approach narrows performance gaps across agent scales. EditAct outperforms ReAct and both Best@3 variants on every benchmark and at each tested model scale. Average-score gains over the strongest baseline shrink but remain positive as model size increases. Compared with ReAct, EditAct yields larger average improvements than over the strongest Best@3 baseline, and a mid-size model with EditAct exceeds a larger model with ReAct. Improvements hold on both in-distribution and out-of-distribution benchmarks, with stronger relative gains on Terminal-Bench and Doc2Repo.
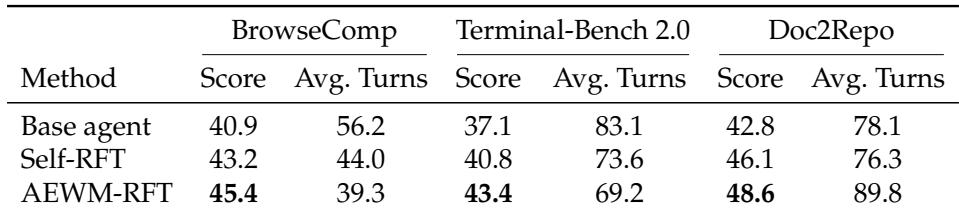
Fine-tuning on AEWM-guided trajectories outperforms both the base agent and an agent fine-tuned on its own trajectories across BrowseComp, Terminal-Bench 2.0, and Doc2Repo. Efficiency improves on the first two benchmarks, with higher scores and fewer average turns, while Doc2Repo improves with more turns. The pattern indicates that EditAct-based trajectories provide useful supervision beyond self-generated successful rollouts. AEWM-RFT achieves the highest scores across all three benchmarks, exceeding Self-RFT by about two to three points. It reduces average turns on BrowseComp and Terminal-Bench 2.0, while Doc2Repo improves with additional turns.
The full AEWM setup with EditAct achieves the best scores across BrowseComp, Terminal-Bench 2.0, and Doc2Repo, outperforming all tested inference interventions and training-stage combinations. Learned intervention selection and direct state revision contribute to this advantage, since random gating, agent resampling, hint guidance, single-component edits, and alternative world models all produce lower scores. The combined mid-training plus SFT recipe is stronger than either stage alone, with the largest gains on Terminal-Bench 2.0 and Doc2Repo. Full AEWM with EditAct achieves the highest score on BrowseComp, Terminal-Bench 2.0, and Doc2Repo. Random gating, agent resampling, and AEWM hint interventions all underperform the full method, supporting learned intervention selection and direct editing over resampling or critic-like guidance. Action-only and reasoning-only revisions each trail the full EditAct, indicating that joint reasoning-action editing is more effective. Using the inference agent as the world model underperforms the full method and is especially weak on Terminal-Bench 2.0; a DeepSeek-V4-Pro world model also trails full AEWM. Mid-training followed by SFT outperforms either training stage alone, with the full recipe producing larger gains on Terminal-Bench 2.0 and Doc2Repo.
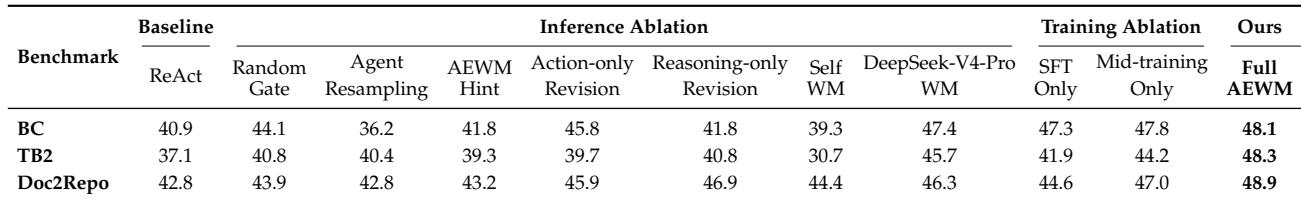
Across BrowseComp, Terminal-Bench 2.0, and Doc2Repo, the experiments compare EditAct with ReAct and Best@3 baselines at multiple model scales, then evaluate fine-tuning on AEWM-guided trajectories and ablate the full AEWM pipeline. EditAct consistently improves over the baselines on both in-distribution and out-of-distribution tasks, and a mid-size EditAct model can surpass a larger ReAct agent. Fine-tuning on AEWM-guided trajectories outperforms self-generated successful rollouts, while the full AEWM setup with joint reasoning-action editing and the combined mid-training plus SFT recipe achieves the best results, confirming the value of learned intervention selection and direct state revision.