Command Palette
Search for a command to run...
적시 메모리(Just-in-Time Memory): LLM 에이전트를 위한 과제 적응형 메모리 큐레이션 학습
적시 메모리(Just-in-Time Memory): LLM 에이전트를 위한 과제 적응형 메모리 큐레이션 학습
Yefan Zhou Yang Li Zeyu Leo Liu Semih Yavuz Shafiq Joty
초록
에이전트 메모리 시스템은 과거 경험을 재사용하여 미래 성능을 개선하지만, 기존 설계 대부분은 쓰기 시점에 메모리를 큐레이션한다. 즉, 과제가 완료되면 그 궤적은 성찰, 워크플로, 스킬, 추론 전략 등과 같은 고정된 산출물로 증류되고, 이후 유사도에 따라 검색된다. 이는 미래 질의가 알려지기 전에 무엇을 기억할 가치가 있는지 결정하도록 강제하며, 정보를 되돌릴 수 없이 버리고 다양한 후속 과제를 모두 지원해야 하는 질의 독립적 요약을 만든다. 이러한 쓰기 시점 큐레이터를 학습하는 것도 어렵다. 저장 결정의 가치는 관련 질의가 도착했을 때, 잠재적으로 여러 과제가 지난 후에야 드러날 수 있어 장기 지평의 신용 할당 문제를 만들기 때문이다. 대신 우리는 원시 궤적을 보존하고 현재 과제가 알려지는 읽기 시점까지 큐레이션을 미룬다. 검색된 궤적들과 새 과제가 주어지면, 메모리 큐레이터는 즉각적인 필요에 맞춘 간결하고 과제 적응적인 페이로드를 합성한다. 이 페이로드는 같은 과제에서 소비되므로, 큐레이터는 즉각적인 과제 성공으로부터 직접 학습될 수 있어 지연된 효용 신호와 관련 과제를 인위적으로 묶을 필요가 없다. ALFWorld, WebShop, τ²-bench에서 우리의 Just-in-Time Memory(JITMEM)는 메모리 없는 에이전트와 휴리스틱 및 학습된 쓰기 시점 메모리 방법들을 일관되게 능가하며, 가장 강력한 기준선 대비 절대 성공률을 각각 16.2, 16.3, 3.9포인트 개선했다. 특히, 학습되지 않은 큐레이터조차 이미 이러한 기준선들과 경쟁하거나 이를 능가하는데, 이는 과제 적응적 읽기 시점 큐레이션 자체가 성능 향상의 주요 원천임을 보여준다. 큐레이터를 학습시키면 그 개선이 더욱 증폭된다.
One-sentence Summary
Salesforce AI Research proposes Just-in-Time Memory (JITMEM), which retains raw trajectories and defers curation to read time so that a memory curator can synthesize a task-adaptive payload from retrieved traces and the current task, enabling direct training from immediate success; JITMEM outperforms write-time memory baselines by 16.2, 16.3, and 3.9 absolute success-rate points on ALFWorld, WebShop, and τ 2-bench, respectively.
Key Contributions
- Just-in-Time Memory (JITMEM) retains raw trajectories at write time and defers curation until read time, synthesizing a compact, task-adaptive payload from retrieved traces and the current task.
- This read-time curation converts memory curation from a delayed future-utility credit assignment problem into an immediate single-step objective, allowing the curator to be trained directly from task success without artificially grouping related tasks.
- Across ALFWorld, WebShop, and τ²-bench, JITMEM improves over the strongest baseline by 16.2, 16.3, and 3.9 absolute success-rate points, while even an untrained curator is competitive or better and RL training further improves effectiveness, efficiency, and transfer across executor models.
Introduction
Large language model agents are increasingly expected to solve sequences of tasks, making it valuable to reuse past trajectories as persistent memory. Prior memory systems typically curate experience at write time, distilling each completed trajectory into a fixed artifact before future tasks are known; this causes premature and irreversible information loss and forces one abstraction to serve many different downstream queries. The authors introduce JITMEM, which defers curation to read time by preserving raw trajectories in a streaming memory bank and using an RL-trained curator to synthesize a task-conditioned payload only when the current task is known. This makes credit assignment immediate and allows the same stored trajectory to produce different lessons for different tasks, with the method outperforming write-time curation baselines on ALFWorld, WebShop, and τ²-bench.
Method
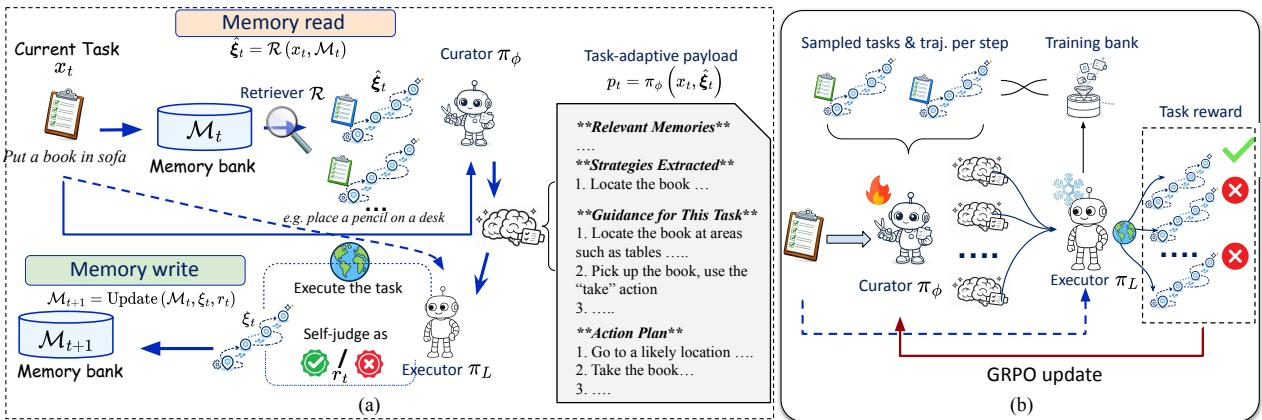
The authors propose JITMEM, a just-in-time memory framework designed for streaming task settings where an agent sequentially solves a series of tasks. The architecture is built upon four core components: a memory bank that stores raw trajectories, a retriever, a trainable memory curator, and a frozen agent executor. The primary objective is to maximize the expected cumulative task success by deferring memory curation until read time, ensuring the extracted information is strictly tailored to the current task.
As shown in the figure below:
During the inference phase, the pipeline operates through a sequence of retrieve, curate, execute, and update steps. The memory bank maintains complete, unabstracted trajectories comprising the task description and the full interleaved observation-action sequence. By avoiding premature summarization, the system preserves all raw details, allowing the curator to extract different lessons from the same trajectory depending on the downstream query. Since task success labels are unavailable at deployment, the executor model acts as a judge to gate which trajectories are appended to the bank, ensuring only positive exemplars are retained.
When a new task arrives, the retriever selects the top-k most relevant raw trajectories from the memory bank using BM25 over task descriptions. These retrieved trajectories are concatenated and passed to the memory curator. The curator processes the current task description alongside the retrieved traces to synthesize a compact, natural-language payload. This payload identifies relevant past experiences and extracts specific strategies for the current task. Because the payload generation is conditioned on the current task, the same retrieved trajectory yields a different distillation for different queries.
The frozen agent executor then receives the current task and the curated payload. The payload is prepended to the executor prompt, providing task-relevant guidance without the executor needing to process the raw trajectories directly. After execution, the resulting trajectory and reward are evaluated, and the memory bank is updated if the trajectory meets the quality gate.
To train the memory curator, the authors leverage Group Relative Policy Optimization (GRPO). To ensure the curator reward reflects payload quality rather than the stochasticity of available trajectories, a fixed training bank is constructed prior to training by running the base executor on the training set and retaining only successful trajectories.
During each training step, a task is sampled, and the retriever fetches relevant trajectories from this fixed bank. The curator generates a group of G candidate payloads. The frozen executor attempts the task with each candidate payload and returns the immediate task reward, which serves as the native evaluation metric. GRPO computes per-group advantages by subtracting the mean reward of the group from each individual reward. The curator is then updated using the following loss function:
LGRPO=−G1i=1∑GA^i⋅logπϕ(pt(i)∣xt,ξ^t)where A^i represents the advantage of the i-th payload. This design ensures a zero temporal gap between the curator generating the payload and receiving the reward, making credit assignment immediate and eliminating the need for delayed-return machinery. The executor remains entirely frozen throughout this process, maintaining modularity and allowing the trained curator to serve multiple different executors without retraining.
Experiment
Experiments on ALFWorld, WebShop, and τ²-bench compare read-time memory curation against no-memory agents and write-time memory baselines using several frozen executors, including Qwen3-8B, Gemini-2.5-Pro, and GPT-5.4. The results show that read-time curation generally outperforms write-time curation under matched curator strength, and that RL-trained read-time curation improves further while transferring across stronger executors and producing more compact context. Ablations validate the importance of task-adaptive conditioning, storing only successful raw trajectories, and grounding learned curation in retrieved experience rather than parametric knowledge. Qualitative analysis indicates that the curator can adapt the same stored experience to different task demands and that RL training induces environment-specific procedural guidance.
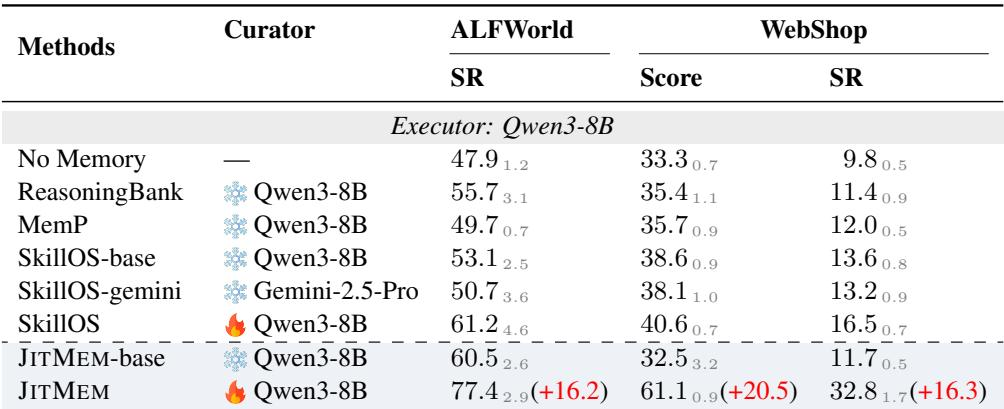
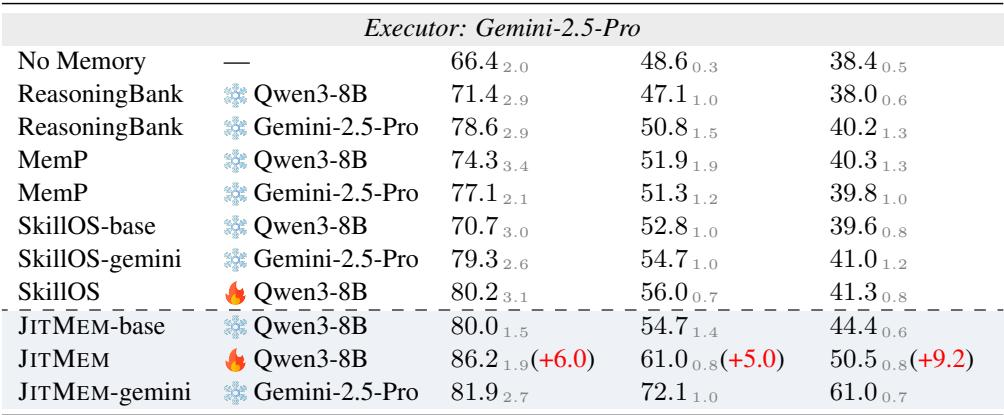
On ALFWorld and WebShop, read-time curation generally outperforms write-time curation when using the same curator, including in training-free settings. RL-trained read-time curation shows large gains over learned write-time baselines, and these gains persist with stronger executors. A curator trained with one executor also transfers to stronger executors without retraining and improves over the untrained read-time variant. Training-free read-time curation outperforms training-free write-time baselines on ALFWorld and WebShop under matched curator and executor choices. RL-trained read-time curation gives substantial gains over learned write-time curation, and the advantage remains with a stronger executor. The learned read-time curator transfers across executors, improving over the untrained read-time baseline without retraining.
On the benchmark with GPT-5.4 as executor, read-time curation consistently outperforms write-time curation under the same zero-shot curator. The advantage appears in domain-level success rates and in macro and micro averages, with especially large gains in individual domains. Only training-free variants are evaluated because no standard training split exists for this benchmark. Read-time curation variants achieve higher success rates than their write-time counterparts under the same zero-shot curator. The gains are visible across individual domains and aggregate macro and micro averages, with per-domain improvements being particularly large.
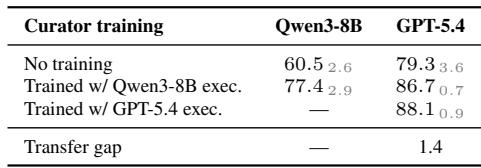
On ALFWorld, a curator trained with Qwen3-8B as the executor improves success rate over no curator training for both Qwen3-8B and GPT-5.4 test executors. The transferred curator nearly matches one trained directly with GPT-5.4, closing to within 1.4 SR points. This suggests the trained curator learns generalizable strategies rather than executor-specific patterns. Curator training with Qwen3-8B improves ALFWorld success rate for both weaker and stronger executors. The transferred Qwen3-8B-trained curator nearly closes the gap to a curator trained directly with GPT-5.4. A single trained curator can serve multiple executors, reducing deployment costs.
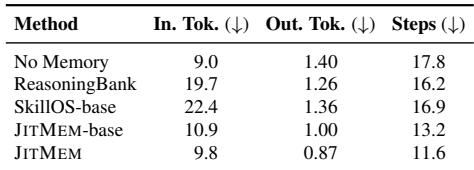
On ALFWorld with a GPT-5.4 executor, memory methods add input tokens over no memory but tend to reduce output tokens and execution steps. JITMEM-base achieves this trade-off more efficiently than ReasoningBank or SkillOS-base by adding far less input overhead while still cutting steps. RL training further improves all three efficiency metrics relative to JITMEM-base. JITMEM-base reduces executor steps by 18.5% to 21.9% compared with no memory while adding only a small input-token overhead. RL training lowers JITMEM input tokens by 10.1%, output tokens by 13.0%, and steps by 12.1% over JITMEM-base.
On WebShop, staged bank refresh provides only a modest success-rate gain for Qwen3-8B and no change for Gemini-2.5-Pro. Warm-starting the test bank with training samples leaves performance nearly unchanged. These interventions add little over the standard JITMEM setup. Staged bank refresh improves Qwen3-8B success rate while Gemini-2.5-Pro remains unchanged. Test bank warm-starting yields negligible changes for Qwen3-8B. The static training bank already appears to provide a sufficient training signal.
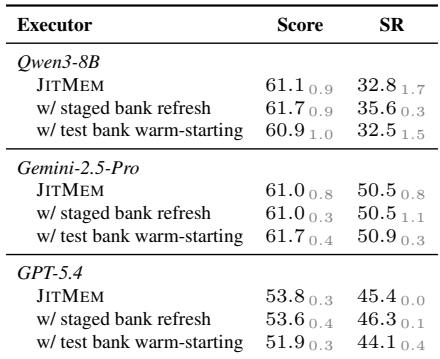
The experiments assess read-time versus write-time curation on ALFWorld and WebShop, as well as a broader benchmark with GPT-5.4, showing that read-time curation consistently outperforms write-time curation under matched curator and executor choices, with RL-trained read-time curators yielding further gains and transferring across executors without retraining. Additional ALFWorld analyses indicate that memory methods such as JITMEM improve efficiency by reducing executor steps with low input overhead, and RL training further reduces input tokens, output tokens, and steps. On WebShop, staged bank refresh and warm-starting the test bank produce only marginal changes, suggesting the static training bank already provides a sufficient training signal.