Command Palette
Search for a command to run...
SPEAKERMEM-R1: 다자 대화를 위한 화자 중심 이중 트랙 메모리
SPEAKERMEM-R1: 다자 대화를 위한 화자 중심 이중 트랙 메모리
Haobo Zheng Tan Tang Yan Chen Weijie Wang Yingcai Wu
초록
다자 환경에서의 장기 대화 메모리는 장기 대화에서 관련 내용을 검색하는 것 이상을 요구한다. 즉, 누가 무엇을 말했는지, 각 발언이 누구에 관한 것인지, 개인들이 서로를 어떻게 인식하는지, 어떤 정보가 집단에 의해 공유되는지, 그리고 상태가 시간에 따라 어떻게 변하는지를 구별해야 한다. 다자 대화 벤치마크에 대한 최근 연구들은 기존 범용 LLM 메모리 시스템이 인물 및 집단 관계를 잃어버리거나, 구성원, 집단, 시간에 걸쳐 분산된 단서를 통합하는 데 어려움을 겪는 경향이 있음을 보여준다. 이러한 문제들은 함께 두 가지 핵심 병목을 드러낸다. 즉, 다자 대화에서의 발언 귀속 및 관계 이해와, 뒤섞인 이력으로부터의 상태 재구성이다. 두 문제를 해결하기 위해 우리는 SPEAKERMEM-R1을 제안한다. 이 시스템의 이중 트랙 메모리는 화자 라벨이 부착된 축어적 메시지와, 인물 수준 및 집단 수준 뷰로 조직된 파생 상태를 저장한 뒤, 질의 시점에 개체, 사건, 시간을 기준으로 두 트랙의 증거를 결합한다. 구조화된 메모리 구축 과정에서 귀속 및 갱신 오류를 줄이면서 로컬 배포를 가능하게 하기 위해, 우리는 SpeakerLevenshtein과 화자 조건부 GRPO로 Writer-R1을 학습시킨다. Group-MemBench, SocialMemBench, EverMemBench에서 SPEAKERMEM-R1은 각각 47.9%, 69.2%, 61.9%의 이진 정확도를 달성한다. 이 점수는 각 벤치마크에서 평가된 주류 프레임워크의 최고 결과보다 각각 3.3, 12.4, 9.4퍼센트포인트 높다. EverMind-AI가 공개한 EverMemBench 리더보드에서 SPEAKERMEM-R1은 62.33%를 달성하여, 최신 최첨단 프레임워크 중 보고된 결과 가운데 가장 우수한 성능을 보인다. 또한 우리가 2인 장기 대화 경계 테스트로 사용하는 1,986개의 LoCoMo 질문 전체에서 70.85%를 달성한다. 305개 질문에 대한 통제 평가에서 RL은 질의/답변 파이프라인을 고정한 상태에서 SFT Writer의 평균 정확도를 57.38%에서 68.20%로 향상시킨다. 우리는 이진 정확도와 토큰-F1을 모두 보고하며, 절제 분석은 표준화된 평가 인터페이스 하에서 축어적 트랙과 구조화 트랙, 그리고 인물 수준과 집단 수준 뷰가 상호 보완적임을 보여준다.
One-sentence Summary
Researchers from State Key Lab of CAD&CG, Zhejiang University propose SPEAKERMEM-R1, a dual-track memory system that stores speaker-labeled verbatim messages and structured person-level and group-level states, is trained with SpeakerLevenshtein and speaker-conditioned GRPO, improves multi-party dialogue memory benchmarks by up to 12.4 points, and achieves 62.33% on EverMemBench.
Key Contributions
- Introduces SPEAKERMEM-R1, a dual-track memory system that stores speaker-labeled verbatim messages and derived states in person-level and group-level views, then combines evidence from both tracks by entity, event, and time for multi-party conversational recall.
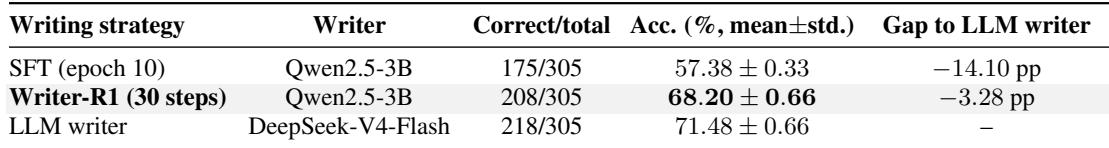
- Trains a Writer component with SpeakerLevenshtein and speaker-conditioned GRPO to reduce attribution and update errors while enabling local deployment; in a controlled 305-question evaluation, RL raises the SFT Writer’s mean accuracy from 57.38% to 68.20% under a frozen query/answer pipeline.
- Reports binary accuracy of 47.9%, 69.2%, and 61.9% on Group-MemBench, SocialMemBench, and EverMemBench, exceeding the best results of mainstream frameworks evaluated on each benchmark by 3.3, 12.4, and 9.4 percentage points, plus 62.33% on the EverMemBench leaderboard as the best reported result among latest state-of-the-art frameworks and 70.85% on all 1,986 LoCoMo questions. Ablations show the verbatim and structured tracks and the person-level and group-level views are complementary.
Introduction
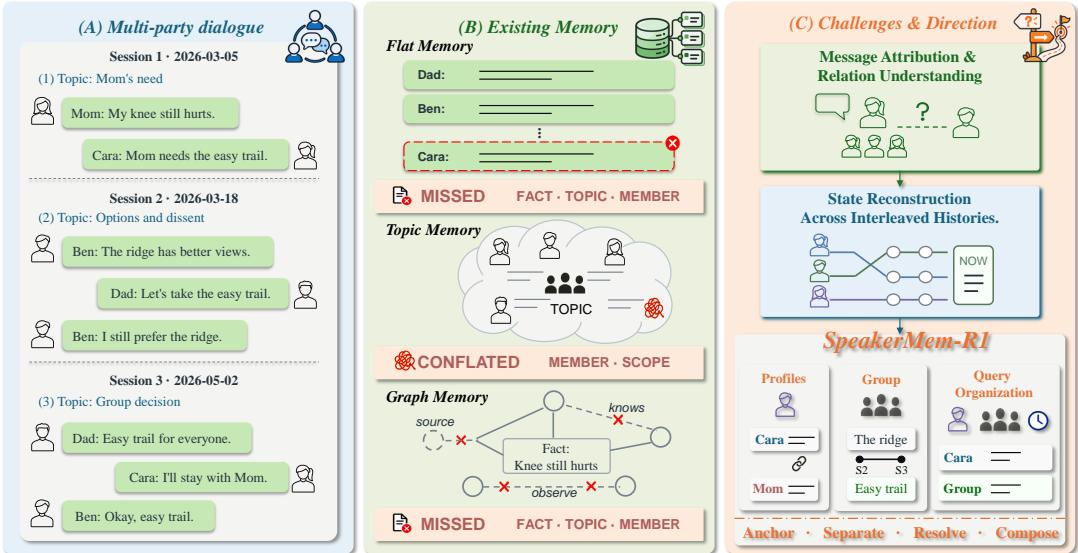
Long-term conversational memory helps language agents retain facts, preferences, and social relations across sessions, but most prior systems target single-user or two-person histories and compress conversations into flat message streams. Multi-party group chats add speaker relations, reply structure, cross-topic branches, and state revisions, so general-purpose memory frameworks degrade even when lexical or dense retrieval remains competitive. The core challenges are message attribution, such as who said what and whether information is shared or personal, and state reconstruction, which requires recovering current or historical states from clues distributed across members and time. The authors propose SPEAKERMEM-R1, a dual-track memory system that preserves traceable speaker-labeled messages alongside provenance-linked person- and group-level structured views, then uses Anchor-Separate-Resolve-Compose query-time organization and a locally deployable Qwen2.5-3B Writer trained with SpeakerLevenshtein and speaker-conditioned GRPO to reduce attribution and update errors.
Method
The authors propose SPEAKERMEM-R1, a system designed to process multi-party message streams by constructing a traceable dual-track memory and retrieving query-specific evidence for a frozen answerer. Given a dialogue stream D={ut}t=1T where each utterance ut contains text, speaker, time, and channel information, the system first writes the messages into memory M, then retrieves evidence Eq and generates an answer y^.
As shown in the figure below:
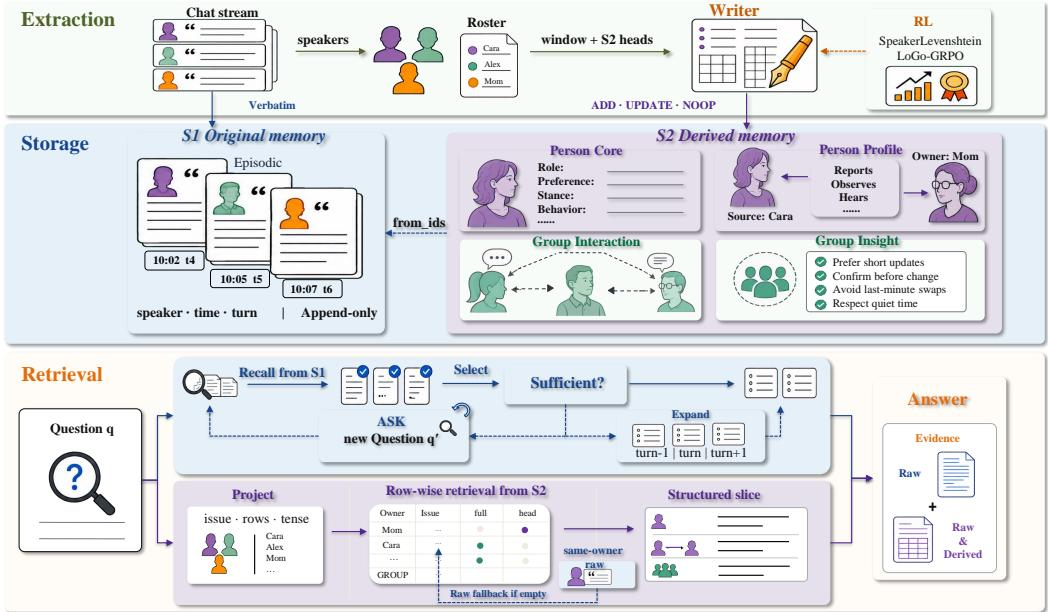
The overall architecture operates through extraction, storage, retrieval, and answering stages. The Writer is the core component responsible for converting local messages into structured memory actions, while the retrieval and answering stages operate on the resulting memory.
The storage module maintains a five-layer traceable dual-track memory. System 1 serves as the only verbatim layer, storing each message with its exact text, speaker, time, and channel in an append-only manner. System 2 is a four-layer derived structure comprising PERSON-scoped Core and Profile layers, along with GROUP-scoped Interaction and Insight layers. The PERSON layers capture stable identity, facts, stances, and cross-person cognition, while the GROUP layers track cross-speaker events, relations, and group norms. Every derived record is represented as a structured tuple containing content, source, owner, scope, event, time, state, and source reference. This design explicitly separates who provides the information from whom the content concerns, and links every derived record to its supporting messages in System 1.
During the retrieval phase, the system generates query-conditioned evidence. A Project module compiles the query and deterministic roster into common query constraints, specifying the target persons or groups, issue constraints, temporal mode, and source-owner constraints. Retrieval proceeds along two independent paths. System 1 retrieves exact wording and local context, optionally expanding neighboring messages. System 2 expands the relevant PERSON or GROUP rows and selects records matching the issue, relation, event, and time constraints. If a derived row is empty, the system falls back to the corresponding verbatim messages. Finally, a Compose operation organizes the evidence from both tracks along persons, relations, and update chains before passing it to the frozen answerer.
To enable efficient local deployment, the authors leverage reinforcement learning to train a small model to replace an expensive prompt-based Writer. The RL process trains the ADD, UPDATE, and NOOP decisions of the Writer, while System 1 writing, query organization, and answering remain frozen. The training utilizes a local-to-global return mechanism. Local structural signals evaluate owner-level writing errors using SpeakerLevenshtein, which combines token-level F1 with a normalized sequence-matching rate to perform coordinate-consistent matching within owner buckets. The local structural potential is defined as:
ΦSL(M,M⋆)=w1∣P∣1p∈P∑Fp+w2p∈PminFpwhere P is the owner set and Fp is the matching result for owner p. This macro-average term measures the overall state, while the worst-owner term prevents frequent participants from masking infrequent ones.
The global signal measures the downstream QA gain of System 1 plus System 2 over System 1 alone. The return at writing position t on trajectory g combines validity, memory structure, and QA gain:
rg,t=wvalidRg,tvalid+wmemRg,tmem+Pg,t+wQAγT−1−tRgQAThe authors sample multiple trajectories for the same network, compute group-relative advantages only at the same writing positions, and update the Writer using clipped GRPO.
Experiment
The evaluation uses GroupMemBench, SocialMemBench, and EverMemBench, with LoCoMo as a two-person boundary test, comparing the proposed system against retrieval and memory baselines. Results show that the dual-track memory method improves multi-party question answering across benchmarks, with ablations confirming that per-speaker and group tracks contribute complementarily and that the hierarchical design matters. The full R1 objective substantially improves a small writer model over supervised fine-tuning, though the gain is not evidence of broad cross-domain generalization. Remaining weaknesses concentrate on multi-hop, open-domain, cross-evidence, preference, and role-attribution questions.
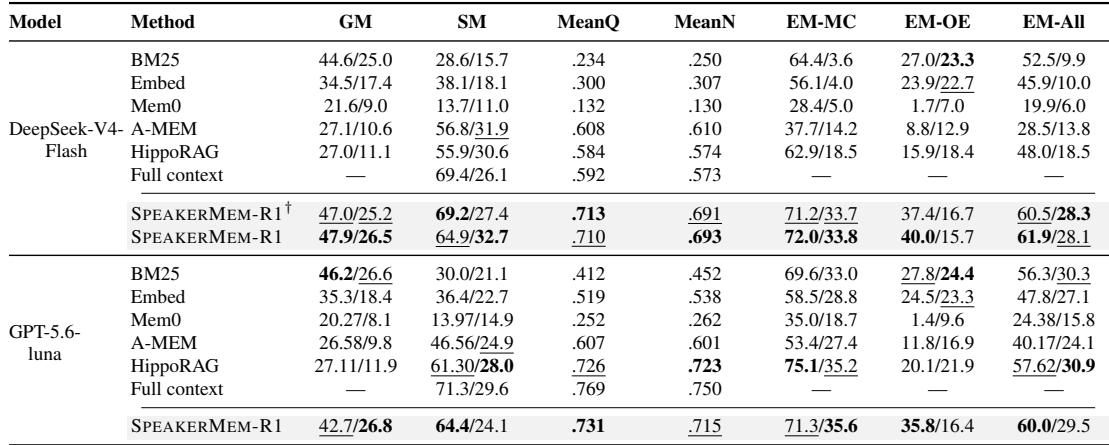
SPEAKERMEM-R1 achieves the best non-full-context accuracy across the reported multi-party memory benchmarks, with the strongest relative improvements on SocialMem and EverMem over the top mainstream baselines. Full context is only feasible on SocialMem, where the method nearly matches full-context accuracy; accuracy and token-F1 are not always aligned because overlapping answers can still be invalidated by scope or extra-person errors. The proposed method outperforms the strongest retrieval and memory baselines on all three benchmarks, with larger gains on SocialMem and EverMem. On SocialMem, the method approaches full-context accuracy while full context is unavailable for the other benchmarks.
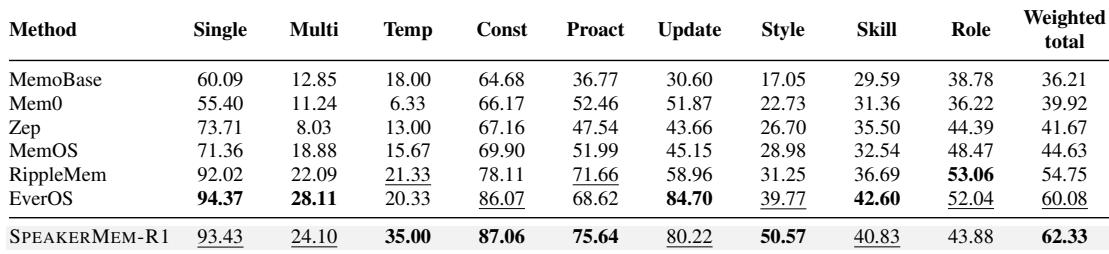
Under the public EverMemBench configuration using GPT-4.1-mini for answering and Gemini-3-Flash for judging, SPEAKERMEM-R1 achieves the highest question-weighted accuracy at 62.33%, ahead of EverOS and RippleMem. Its category-level strengths include single, constraint, proactive, update, temporal, and style, while multi, skill, and role are weaker. EverOS leads several individual categories but falls behind overall due to lower style and temporal scores. SPEAKERMEM-R1 leads the weighted total at 62.33% and is the top method in temporal, constraint, proactive, and style categories. EverOS has the best single, multi, update, and skill category scores, but its lower temporal and style results leave it second overall. Multi is the lowest-scoring category across all methods, with the best result only 28.11%. Role accuracy remains a shared bottleneck, with the best result just above 53% from RippleMem.
Reinforcement learning substantially improves the small writer over supervised fine-tuning on held-out SocialMem networks. It closes most of the accuracy gap to the LLM writer reference under the same frozen query and answer protocol, though the reference remains slightly ahead. The RL-trained writer gains about 11 percentage points over the SFT writer and answers 33 additional questions correctly. The gap to the LLM writer narrows from about 14 points for SFT to about 3 points for the RL-trained writer, reaching over 95% of the reference accuracy.
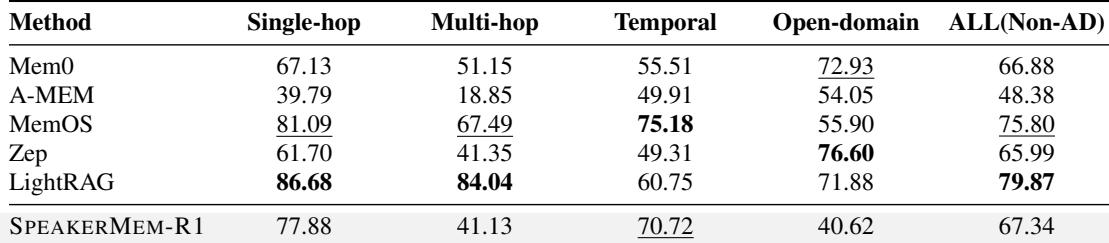
On the LoCoMo non-AD categories, LightRAG and MemOS lead overall, with LightRAG strongest on single-hop and multi-hop questions. SPEAKERMEM-R1 is competitive on temporal and single-hop categories but ranks near the bottom on multi-hop and open-domain questions, leaving its aggregate non-AD accuracy below the top two methods. Multi-hop and open-domain questions remain notable weak spots for SPEAKERMEM-R1. LightRAG records the highest overall non-AD accuracy and leads the single-hop and multi-hop categories, while MemOS is the strongest temporal method and second overall. SPEAKERMEM-R1 places second on temporal questions but is among the weakest methods on multi-hop and open-domain questions, with aggregate accuracy below LightRAG and MemOS.
The experiments evaluate SPEAKERMEM-R1 on multi-party memory benchmarks, the EverMemBench configuration, a reinforcement learning writer on held-out SocialMem networks, and LoCoMo non-AD categories. The method achieves the strongest non-full-context results on multi-party benchmarks and leads EverMemBench overall, with particular strengths in temporal, constraint, proactive, and style categories, while multi and role questions remain shared bottlenecks. Reinforcement learning substantially improves the small writer over supervised fine-tuning, narrowing most of the gap to the LLM writer reference. On LoCoMo non-AD questions, LightRAG and MemOS lead overall, with SPEAKERMEM-R1 competitive on temporal queries but weaker on multi-hop and open-domain questions.