Command Palette
Search for a command to run...
안목 있는 에이전트: 장기 지평 과제에서의 안목 측정 및 개선
안목 있는 에이전트: 장기 지평 과제에서의 안목 측정 및 개선
Wenbo Pan Zhichao Liu Shujie Liu Jingying Zeng Chin-Yew Lin Xianfeng Tang Yan Lu Qi He Xiaohua Jia
초록
LLM 에이전트는 점점 더 장기 지평 과제를 수행하고 있으며, 어떤 가설을 검증할지, 어떤 구현 위에 구축할지와 같이 그 과정에서 내리는 결정이 전체 실행의 결과를 좌우한다. 이러한 결정을 잘 내리는 것은 엔지니어링 및 연구 에이전트 모두에게 핵심 역량이 되고 있다. 우리는 좋은 장기 지평 결정을 내리는 능력을 에이전트의 안목(taste)이라고 부른다. 기존 벤치마크는 장기 지평 과제에서 에이전트의 종단 간 성공률을 측정하지만, 에이전트의 안목을 측정하는 것은 없다. 이 문제를 해결하기 위해 우리는 엔지니어링 및 연구 과제에서 에이전트가 생성한 궤적으로부터 자동으로 구성한 안목 질문 벤치마크인 Taste-Bench를 구축한다. 각 질문은 결정 분기점을 제시한다. 이는 궤적에서 여러 방향이 가능하고 그중 하나가 더 나은 결과로 이어지는 지점이며, 평가 대상 모델은 분기점 이후의 일을 보지 않고 이 방향들 중 하나를 선택한다. 우리는 동일 과제에 대한 병렬 시도들과 단일 궤적 내의 우회 경로들로부터 이러한 분기점을 사람의 주석 없이 자동으로 추출한다. 우리는 Taste-Bench에서 최첨단 모델들을 평가한 결과, 가장 우수한 모델도 질문의 59.7%만 정확히 답한다는 것을 발견했다. 또한 분기점을 결정하는 증거가 궤적의 더 뒤에 나타날수록 모든 모델에게 훨씬 더 어렵고, 더 큰 추론 예산이 정확도를 향상시키지 않는다는 것도 발견했다. 마지막으로 우리는 안목이 학습될 수 있음을 보인다. 결과를 본 교사의 판단을 학생 모델에 증류한 결과, 학생은 보지 못한 과제에서 더 나은 결정을 내리고, 홀드아웃된 SWE-bench Pro 과제들에서 종단 간 성공률을 향상시켰다.
One-sentence Summary
Researchers from City University of Hong Kong and Microsoft introduce Taste-Bench, a benchmark that automatically mines decision forks from agent trajectories to measure long-horizon taste, and they find that frontier models answer only 59.7% of the questions correctly, that forks whose deciding evidence appears later in the trajectory are much harder while a larger reasoning budget does not improve accuracy, and that distilling outcome-aware teacher judgment into a student improves decisions and end-to-end success on held-out SWE-bench Pro tasks.
Key Contributions
- The paper formalizes taste as an agent's ability to choose the better direction at a decision fork and shows that this ability can be measured from hindsight over existing trajectories without human annotation.
- The paper constructs and releases Taste-Bench, a benchmark of 502 taste questions mined automatically from parallel attempts and detours in software engineering and machine learning research tasks; the best frontier model answers 59.7% of the questions correctly, and forks whose deciding evidence appears later are much harder.
- The paper shows that taste is trainable by distilling the reasoning of an outcome-informed teacher into a student, which improves decision quality on unseen tasks and yields end-to-end gains on held-out SWE-bench Pro tasks.
Introduction
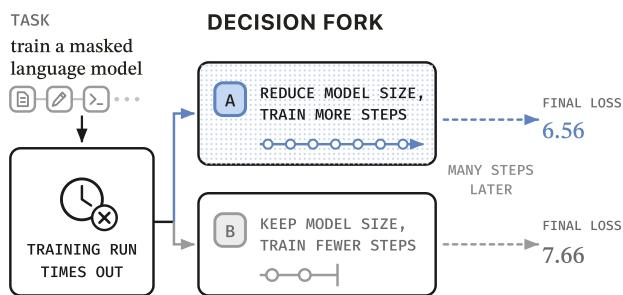
The authors study taste in LLM agents: the ability to make good long-horizon decisions whose impact appears only later, such as choosing a research hypothesis or implementation direction. Prior benchmarks measure end-to-end task completion but do not assess the quality of intermediate decisions, and expert annotation is expensive and hard to scale across domains. The authors leverage hindsight from existing trajectories, identifying decision forks where attempts diverge and later recorded outcomes label the better direction. They build Taste-Bench, a benchmark of 502 such questions from software engineering and machine-learning research, and show that taste can be measured automatically and improved by distilling a teacher’s reasoning, which also produces end-to-end gains on held-out tasks.
Dataset
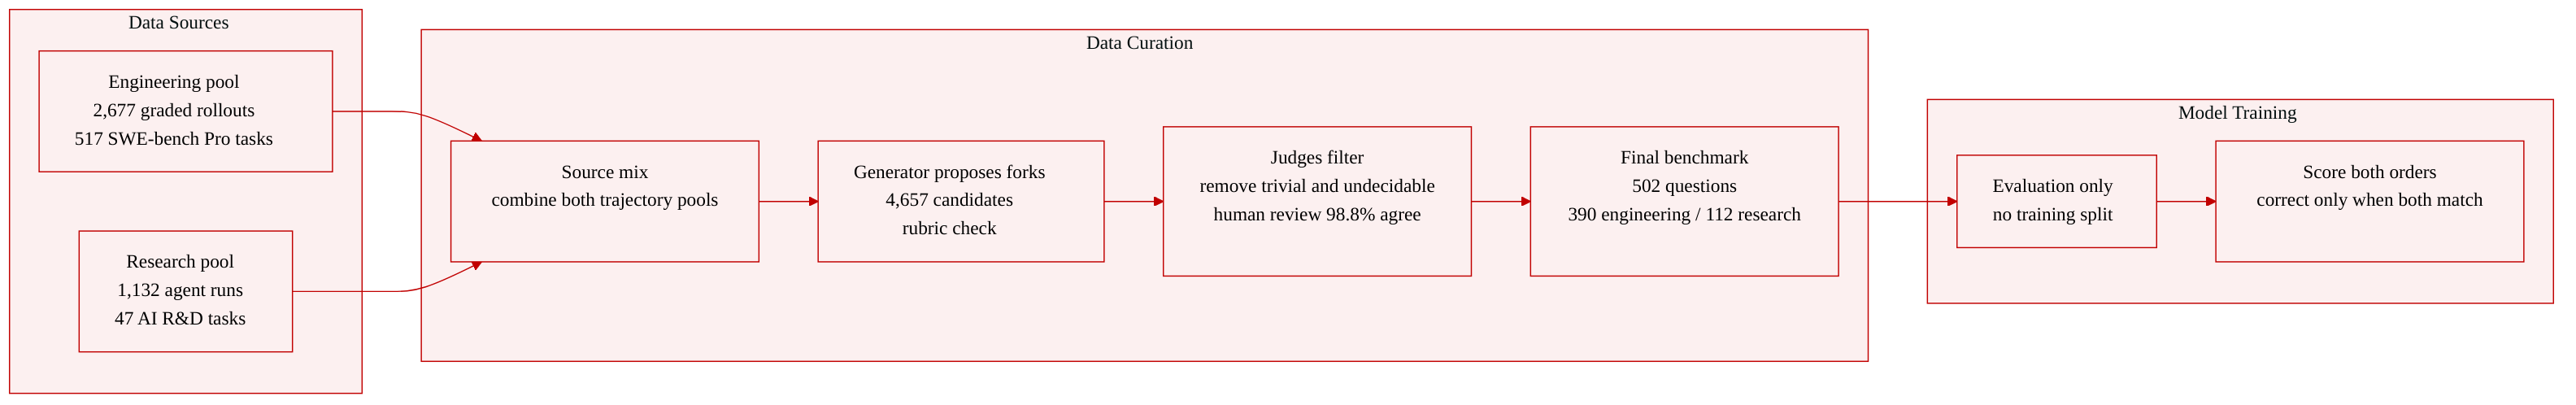
The authors introduce Taste-Bench, a benchmark of 502 taste questions derived from real agent trajectories. Each question is built by recovering a task, a trajectory prefix before a decision fork, two candidate directions, and a label from an unstructured record.
Sources and composition
- The benchmark uses two trajectory pools:
- Engineering pool: 2,677 graded rollouts from GPT-5.4 and GPT-5.5 agents on 517 SWE-bench Pro tasks.
- Research pool: 1,132 agent runs on 47 AI R&D tasks from RE-Bench and the research subset of HCAST, downloaded from MALT, METR's public transcript release.
- Questions are constructed from two complementary fork types:
- Parallel trajectories: pairs of attempts on the same task diverge at the same fork with opposite outcomes. The shared prefix becomes the question prefix, the two diverging directions become the candidates, and the branch that passes the tests or achieves the objective determines the label.
- Detour trajectories: a single trajectory where the agent takes a wrong direction, observes a failure, and later corrects itself. The abandoned direction and the later recovery become the candidates. The fork is placed right before the abandoned direction, and the prefix must not reveal the failure or the later fix.
Processing and filtering
- A generator model reads the trajectories, proposes candidate forks, applies a rubric, and keeps only candidates that can form valid questions.
- Judge models, distinct from the generator, remove two failure types:
- Trivial questions: every judge answers correctly from the two candidates alone without the trajectory.
- Undecidable questions: the recorded outcome is not clearly consistent with the label.
- A question is included only when every judge agrees with the label after reading the full task record, trajectory, and outcome.
- The generator proposes 4,657 candidate forks; 10.8% pass all filters, yielding 502 questions.
- The final benchmark follows a 2 × 2 design crossing construction type, parallel or detour, with domain, engineering or research. Engineering provides 390 questions and research provides 112.
Human validation
- In a review of 100 sampled questions, two reviewers separately chose a direction and then judged which decision was better after seeing summaries of the recorded continuations and outcomes.
- Of 172 explicit A/B judgments, 170 agree with the mined label, a 98.8% agreement rate.
- On the 74 questions where both reviewers chose A or B, inter-reviewer agreement is 98.6%, with Cohen's κ = 0.973.
Usage
- Taste-Bench is used only for evaluation, not for training. There is no training split or mixture ratio.
- Each question is presented to the evaluated model as a two-choice decision over the trajectory prefix and two candidate directions.
- To reduce position bias, each question is evaluated twice: once in a deterministic seeded order and once in the exact reverse order.
- In the main accuracy metric, a question counts as correct only when both orders are answered correctly. The paper also reports mean accuracy over the two orders.
Method
The authors view taste as a form of long-horizon judgment, where the advantage of a chosen direction only becomes apparent in later work. To measure this without expert annotation, they mine hindsight from existing agent trajectories. They identify decision forks where attempts at the same task share an equivalent prefix but diverge into different candidate directions. The outcomes of these branches estimate the quality of the judgments. Formally, for a task q with trajectory prefix ht and two candidate directions c1 and c2, the supported candidate is labeled based on the outcome measure U:
y=argi∈{1,2}maxU(Ei)The evaluated model π receives the question x=(q,ht,c1,c2) and its taste is estimated as the fraction of correct choices. To construct the Taste-Bench benchmark, the authors extract these forks from two types of trajectories: parallel trajectories, where an agent tries the same task multiple times and diverges, and detour trajectories, where an agent corrects itself within a single run.
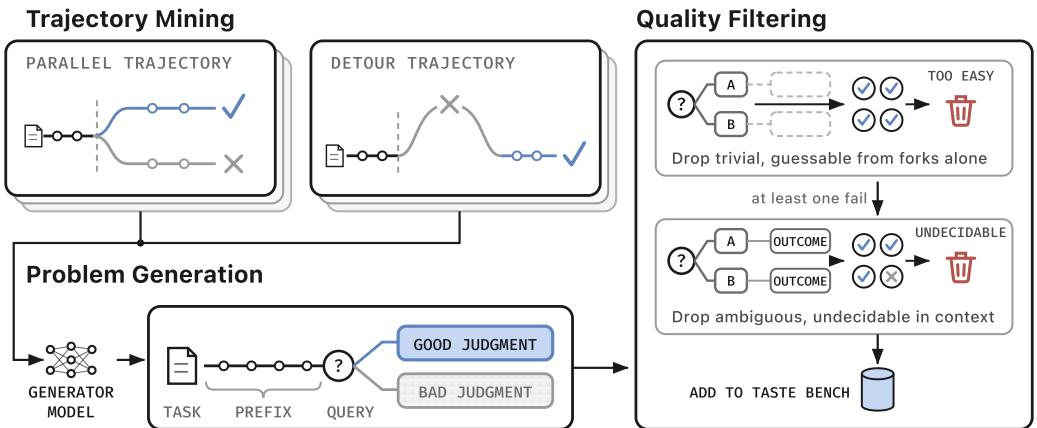
As shown in the figure above, the pipeline involves trajectory mining, problem generation, and quality filtering. A generator model reads trajectories from engineering and research pools to propose candidate forks. During the filtering stage, judge models remove trivial questions, where the answer can be guessed from candidate wording alone, and undecidable questions, where the recorded outcome is not clearly consistent with the label. This ensures that every released question requires genuine judgment over the trajectory context.
To improve model taste, the authors distill judgment capabilities into a base model using the constructed questions. The training pool consists of task-disjoint folds to prevent data leakage. Instead of fine-tuning directly on binary labels, which risks memorization, they distill complete reasoning sequences generated by a privileged teacher.
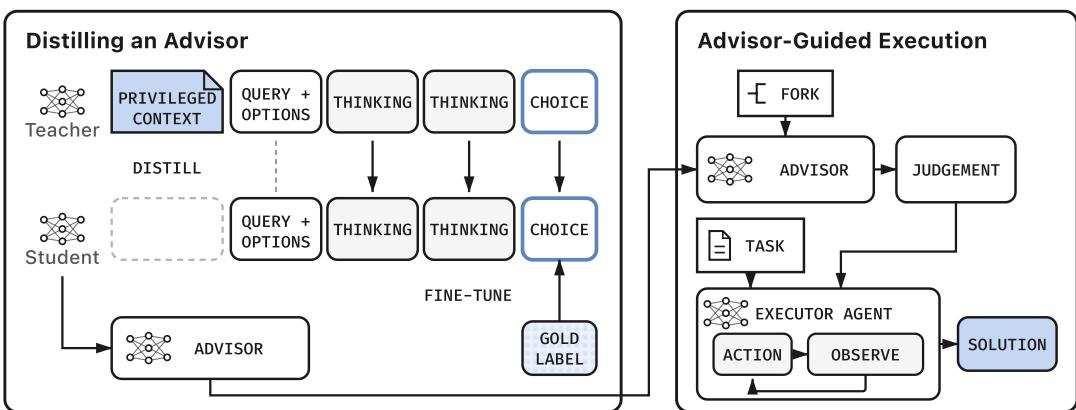
As illustrated in the figure above, the distillation process involves a teacher model that receives the question along with a demonstration of the supported candidate. The teacher generates a reasoning sequence and the final choice. The student model, which only sees the task, trajectory prefix, and shuffled candidates, is trained to align with the teacher's generated tokens. The loss is a token-level forward KL divergence computed over the reasoning tokens and the final choice. At evaluation time, the distilled advisor model provides judgments at each fork, which are injected as advice into the task context for an executor agent to complete the task independently.
Experiment
The evaluation uses two-choice taste questions presented in both orders, requiring a model to answer correctly in both orders to count as a correct judgment. Across 14 frontier models, no model approaches solving the benchmark, accuracy declines as the time horizon of a fork grows, and larger reasoning budgets do not improve taste, while comparison with SWE-bench Verified shows only partial correlation. Distillation demonstrates that taste can generalize to unseen tasks, and the distilled student's advice raises a downstream executor's success rate from 14.6% to 33.7%, near the 39.0% upper bound achieved with correct advice.