Command Palette
Search for a command to run...
GAE: 3D 일관적 세계 생성을 위한 기하학 네이티브 잠재 공간 학습
GAE: 3D 일관적 세계 생성을 위한 기하학 네이티브 잠재 공간 학습
Jiahao Lu Minghao Yin Wenbo Hu Hengyu Liu Wang Zhao Sai-Kit Yeung Ying Shan Yuan Liu
초록
우리는 인식과 생성을 위한 공유 기반으로서 압축된 기하학 네이티브 잠재 공간을 제시한다. 시각 생성기는 일관된 3D 장면을 보존하지 않으면서도 사실적인 프레임을 생성할 수 있다. 우리는 이것이 모델링 문제일 뿐 아니라 표현 문제이기도 하다고 주장한다. 생성기는 일반적으로 외관 중심의 잠재 표현을 발전시키는 반면, 인식 모델은 교차 뷰 구조를 인코딩하는 의미적으로 풍부한 공간에서 기하 정보를 복원한다. 기하를 또 다른 출력으로 추가하는 대신, 우리는 기하 파운데이션 모델의 특징을 생성용 압축 잠재 공간으로 재매개변수화한다. 우리는 이러한 전환을 기하학 네이티브 오토인코더(GAE)로 구현하며, GAE의 잠재 벡터는 외관, 깊이, 카메라, 포인트 맵으로 공동 디코딩될 수 있다. 이 상태를 사용하면 표준 조건부 플로우가 다양한 생성 작업을 지원한다. 생성기와 학습 프로토콜을 고정한 통제 비교에서 잠재 표현을 GAE로 대체하면 시각적 품질과 독립적으로 측정된 3D 일관성이 모두 향상된다. RealEstate10K와 DL3DV에서 FVD가 각각 12.7%와 23.1% 감소하고, RealEstate10K에서는 카메라 궤적 오차가 절반으로 줄어든다. 이러한 결과는 잠재 공간이 기하학적으로 일관된 생성의 핵심이며 인식과 생성 간의 공유 인터페이스 역할을 할 수 있음을 보여준다.
One-sentence Summary
Researchers from The Hong Kong University of Science and Technology, ARC Lab, Tencent IEG, et al. propose the geometry-native autoencoder (GAE), which reparameterizes geometry foundation model features into a compact latent decodable to appearance, depth, cameras, and point maps, enabling a standard conditional flow to generate diverse 3D-consistent scenes with FVD reduced by 12.7% on RealEstate10K and 23.1% on DL3DV and camera-trajectory error halved on RealEstate10K.
Key Contributions
- A geometry-native autoencoder (GAE) reparameterizes a geometry foundation model’s features into a compact latent space jointly decodable to appearance, depth, cameras, and point maps.
- This latent space serves as the evolving state for a standard conditional flow model, allowing generated target-view latents to decode natively to both RGB and geometry.
- Controlled comparisons holding the generator and training protocol fixed show that GAE reduces FVD by 12.7% on RealEstate10K and 23.1% on DL3DV and roughly halves camera-trajectory error on RealEstate10K, demonstrating improved visual quality and 3D coherence.
Introduction
Photorealistic video generation is not enough for world modeling: generated views can look plausible while their recovered geometry drifts and camera trajectories stray, so persistent 3D structure must be embedded in the generative latent state. Existing approaches either use appearance or semantic latents that do not make depth, camera geometry, and cross-view relations natively readable, or they add geometry as an auxiliary signal to an appearance-led state. Geometry foundation models already contain the needed structure, but their multi-level feature hierarchies are redundant, anisotropic, and split complementary cues across levels, making them difficult to model directly with a single generative flow. The authors introduce a geometry-native autoencoder, GAE, that compresses DA3’s frozen multi-level geometry features into one compact latent and reconstructs the full feature hierarchy for frozen geometry decoding, while also decoding RGB from the same latent. Token-wise and pairwise alignment objectives organize that latent for smooth transport, and the model supports text-to-image, camera-controlled video, and novel-view synthesis. In controlled comparisons, GAE improves generation quality and 3D consistency over pixel, semantic, and raw geometry latents.
Method
The authors propose the Geometry-Native Autoencoder (GAE), a framework that embeds 3D inductive bias directly into the generated state. The method operates through a two-stage training pipeline. As shown in the figure below:
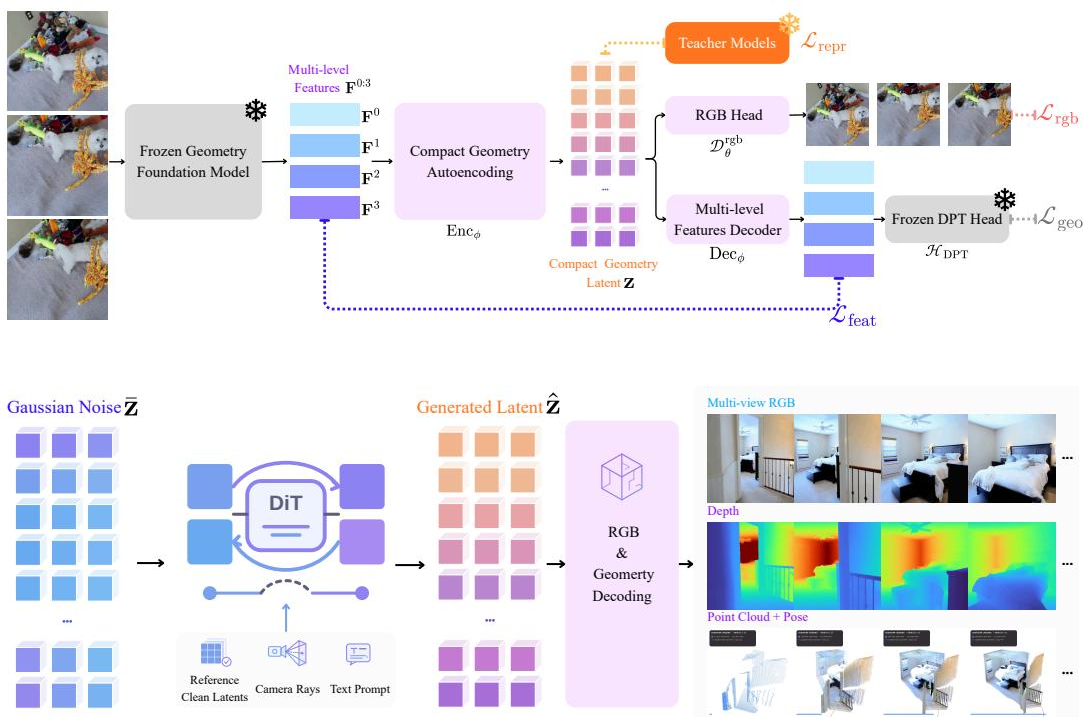
In the first stage, the authors train a codec to compress the multi-level features of a frozen geometry backbone into a compact latent space that is jointly decodable to both RGB and geometry. Given V input views, a frozen DA3 encoder E extracts a four-level feature hierarchy. A fixed operator P normalizes each level using training-set statistics and concatenates them along the channel dimension to form a fused tensor Xv. The trainable encoder Encϕ compresses this tensor into a grid-shaped latent zv, while the decoder Decϕ reconstructs the full feature hierarchy.
To ensure the compact latent supports both modalities, the framework employs two distinct decoding pathways. A separate learned head Dθrgb renders RGB images directly from the latent zv. Concurrently, the reconstructed feature hierarchy is passed through a frozen dense-prediction transformer head HDPT to output depth, rays, and point maps. This design ensures the latent remains geometry-decodable without requiring a level-wise generative cascade. The codec is optimized using a composite objective that includes feature reconstruction, RGB and geometry losses, a KL divergence term, and a representation shaping term Lrepr. To organize the latent space for subsequent generation, the authors leverage frozen C-RADIO and DINOv2 teacher models. The C-RADIO teacher provides token-wise semantic alignment, while the DINOv2 teacher enforces relational structure by matching pairwise spatial similarities directly in the latent space.
In the second stage, the authors freeze the trained codec and train a conditional flow model within the standardized latent space. The posterior mean of the codec is standardized using training-set statistics to supply the flow targets. The flow model is trained via conditional flow matching, predicting the velocity field to transport Gaussian noise to the target latent distribution.
The conditioning set C incorporates text prompts, metric Plucker-ray embeddings for camera control, and clean latent tokens derived from reference views. To prevent train-inference mismatches inherent in set-conditioned geometry encoders, the authors do not place full-set reference latents directly into the flow state. Instead, they jointly encode the observed reference views to produce clean latents zˉref, which are prepended as conditioning tokens at timestep t=0. These reference tokens attend jointly with the noisy target-view tokens but are removed before the decoder prediction head, allowing a single standard Euler sampler to operate without denoising-level mismatches. During inference, Gaussian target-view latents are integrated from t=1 to t=0, denormalized, and decoded into final RGB and geometry outputs through the frozen codec and respective heads.
Experiment
The experiments evaluate latent representations and codecs under a controlled flow-matching setup on RealEstate10K and DL3DV, covering latent-space properties, RGB and geometry reconstruction, generation quality, 3D consistency, and ablations. GAE, which fuses the full DA3 hierarchy into compact latents, provides the best overall balance among geometry-native representations and improves RGB fidelity, geometry recovery, camera control, and multi-view consistency without sacrificing appearance. Ablations show that representation shaping and larger backbone capacity yield complementary gains, while clean reference tokens, metric ray conditioning, and text-to-image co-training improve appearance, geometry, and camera motion. Qualitative results further demonstrate long-rollout and text-conditioned RGB and geometry generation.
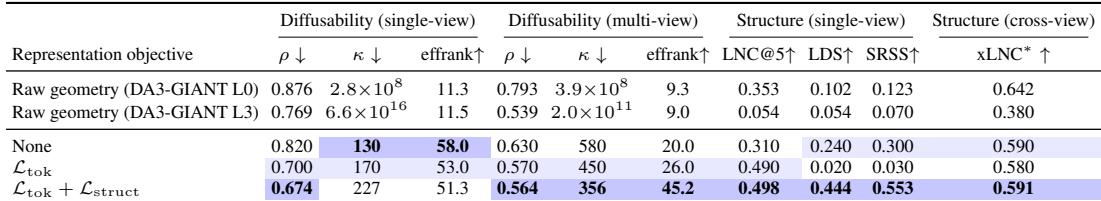
The representation ablation shows a progressive improvement over the raw geometry hierarchy. Reconstruction alone sharply improves conditioning, but leaves transport smoothness and semantic neighborhoods weak. Token alignment improves transport and semantic consistency while collapsing relational structure, and adding the structural objective restores single-view and cross-view structure while retaining those gains. Relative to raw geometry, the reconstruction-only baseline greatly reduces conditioning difficulty and raises effective rank, but its transport and semantic metrics remain weak. Token alignment improves diffusability and semantic neighborhood consistency but causes a large drop in relational structure scores, while the combined objective recovers those scores and improves cross-view organization.
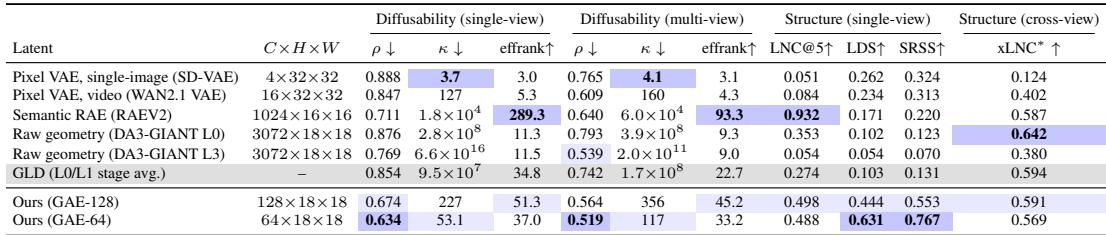
No single latent is strong on every axis: pixel VAEs are well conditioned but weakly structured, semantic RAE has strong semantic neighborhoods but poor conditioning and no native geometry readout, and raw DA3 features are high-dimensional and poorly conditioned. Within raw DA3, shallow features preserve cross-view correspondence while deeper features trade spatial and cross-view structure for lower transport cost. GAE fuses the hierarchy into a compact geometry-native state and achieves the best overall balance of transport, conditioning, spatial and cross-view structure, and semantic organization. Pixel VAE latents are well conditioned but weakly structured, while the video variant shows better cross-view structure than the single-image variant. Raw DA3 L0 features preserve stronger cross-view correspondence, whereas raw L3 improves transport but loses spatial and cross-view structure. GAE fuses the hierarchy into a compact geometry-native state that balances transport, conditioning, spatial and cross-view structure, and semantic organization better than the raw levels.
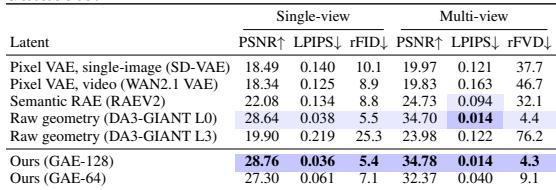
The proposed GAE-128 latent matches or slightly exceeds raw geometry features from DA3-GIANT L0 on single-view and multi-view RGB reconstruction, while using 24 times fewer channels. Raw L3 and the tested pixel VAE and semantic RAE latents reconstruct appearance substantially less well. GAE-128 and raw L0 show much stronger fidelity and distributional alignment than the alternatives. GAE-128 achieves the best or tied-best single-view and multi-view reconstruction quality, essentially matching raw DA3-GIANT L0 across PSNR, LPIPS, rFID, and rFVD. Raw DA3-GIANT L3 loses substantially more reconstructable appearance information than L0, with much worse LPIPS and distributional metrics. Pixel VAE latents and the semantic RAE fall well behind GAE-128 and raw L0 on RGB reconstruction, especially on multi-view rFVD.
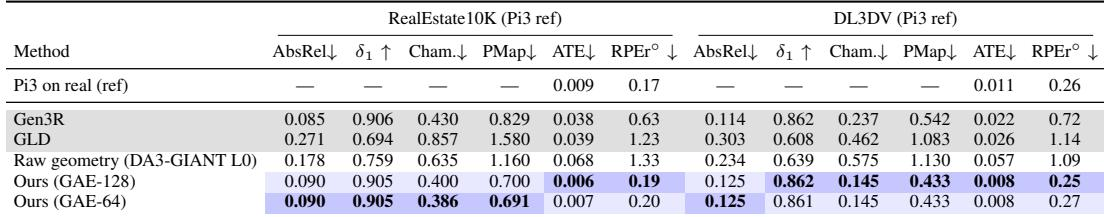
The encoded latents preserve geometry-relevant information beyond RGB fidelity. Both GAE variants improve over the raw geometry baseline on depth, point-map, and camera pose metrics for RealEstate10K and DL3DV. Against external reconstruction systems, GAE yields lower camera errors than Gen3R and GLD and lower point-cloud errors than GLD, while Gen3R is slightly better on some depth metrics. Both GAE-64 and GAE-128 improve depth, point-map, and pose metrics over the raw geometry baseline on both datasets. GAE attains lower camera errors than Gen3R and GLD and lower point-cloud errors than GLD, with Gen3R slightly ahead on some depth metrics.
The proposed GAE latent family improves camera-conditioned appearance generation over pixel VAE, semantic, and raw geometry latents. GAE-64 is reported to deliver the strongest overall distributional and paired fidelity on RealEstate10K and DL3DV, while GAE-128 achieves the best RealEstate10K FID among the compared variants. Alternatives such as pixel VAE, semantic RAE, and raw geometry latents generally show weaker FVD/FID and reconstruction fidelity. GAE-64 reduces FVD by double-digit percentages relative to the best non-GAE controlled latent on both datasets and leads the paired fidelity metrics. GAE-128 achieves the best RealEstate10K FID among the compared variants. Pixel VAE video latent shows especially weak results, with the highest FVD and lowest PSNR and SSIM on both datasets.
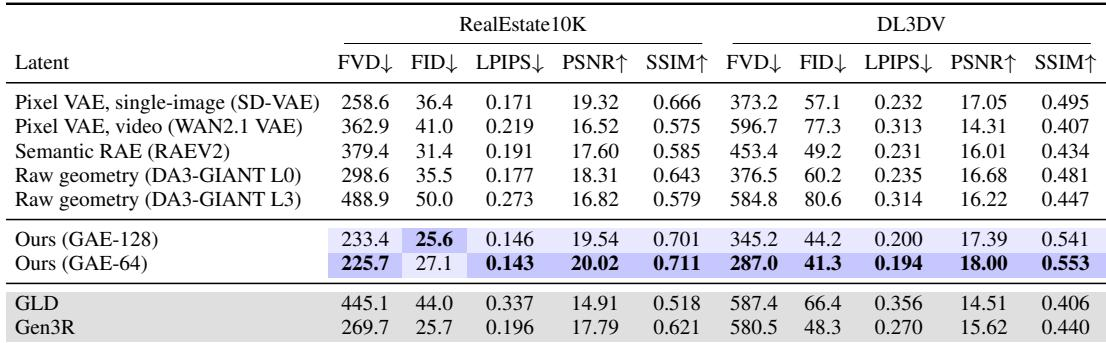
The experiments evaluate the proposed geometry-native autoencoder against raw DA3 geometry levels, pixel VAEs, and a semantic RAE across representation ablation, reconstruction, geometry estimation, and camera-conditioned generation. The ablation shows reconstruction improves conditioning, token alignment improves transport and semantic consistency, and the added structural objective restores relational and cross-view structure. Overall, GAE fuses the geometry hierarchy into a compact latent that matches or surpasses raw shallow geometry on RGB reconstruction with far fewer channels, improves depth, point-map, and pose metrics over raw baselines and external systems, and leads camera-conditioned appearance generation over the tested alternatives.