Command Palette
Search for a command to run...
HappyWorld-Bench
HappyWorld-Bench
초록
세계 모델(world model)을 평가하려면 생성된 세계의 품질뿐 아니라 탐색, 상호작용, 수정 아래에서의 일관성과 반응성도 평가해야 한다. 본 논문에서는 에이전트가 세계와 상호작용할 때 생성된 세계가 계속 신뢰할 수 있는지를 평가하는 종합 벤치마크인 HappyWorld-Bench를 소개한다. 설계는 생성적 구성부터 통합 세계 모델링까지 여섯 가지 세계 능력(W1–W6)의 계층적 능력 프레임워크에 기반하며, 비디오 세계 모델, 공간 세계 모델, 체화 세계 모델이라는 세 독립적 평가 트랙으로 구현된다. HappyWorld-Bench는 1,138개의 비디오 프롬프트, 300개의 공간 장면, 254개의 체화 테스트 케이스로 구성된다. 세 트랙 모두에서 HappyWorld-Arena를 구축·운영하여 인간 A/B 비교를 조직하고 모델 수준 Elo 레이팅을 도출하며, 행동 정확성을 포착하는 새로 설계된 자동 지표로 이를 보완한다. 이 통합 프레임워크에서 14개 비디오 세계 모델, 9개 공간 시스템, 8개 체화 후보를 평가했다. 결과는 세 트랙 모두에서 남아 있는 신뢰성 격차를 보여준다. 비디오 모델은 장기 롤아웃과 재방문 시 일관성이 저하되고, 공간 모델은 배치 정확도 최대 70.14%, 편집 실행 최대 73.33%에 그쳤으며, 체화 모델은 다단계 행동에 걸쳐 상태를 유지하고 변경된 행동 조건과 물리 규칙에 정밀하게 반응하는 데 어려움을 겪었다. 이러한 발견은 세계 모델을 시각적 품질뿐 아니라 상태 일관성과 행동 및 개입에 대한 반응의 정확성으로 평가해야 할 필요성을 강조한다.
One-sentence Summary
The authors introduce HappyWorld-Bench, a comprehensive benchmark that evaluates six hierarchical world capabilities (W1–W6) across video, spatial, and embodied tracks by combining HappyWorld-Arena human A/B comparisons, Elo ratings, and automated behavioral metrics; evaluation of 31 systems reveals persistent reliability gaps in consistency, state preservation, and action responsiveness.
Key Contributions
- HappyWorld-Bench is a unified benchmark that evaluates video, spatial, and embodied world models through a hierarchical six-level capability framework from W1 to W6, with 1,138 video prompts, 300 spatial scenes, and 254 embodied test cases.
- HappyWorld-Arena complements automated behavioral correctness metrics with human A/B comparisons and model-level Elo ratings, and is applied to 14 video world models, 9 spatial systems, and 8 embodied candidates.
- The benchmark reveals reliability gaps: video models lose consistency in extended rollouts and revisits, spatial models achieve at most 70.14% placement accuracy and 73.33% edit execution, and embodied models struggle with state persistence and precise responses to altered actions or physical rules.
Introduction
World models let an agent predict future environment responses and choose actions without real-world trial and error, but this only works if the simulated world stays geometrically consistent, physically plausible, temporally persistent, and controllable under interaction. Existing benchmarks remain fragmented: they evaluate video, spatial, and embodied world models in separate settings, often measuring different subsets of capabilities, so it is hard to tell whether apparent generation quality reflects reliable world modeling. The authors introduce HappyWorld-Bench, a unified benchmark that organizes evaluation around a hierarchical W1-W6 capability framework and applies it across video, spatial, and embodied tracks. It pairs automated capability metrics with large-scale human A/B ratings in HappyWorld-Arena and evaluates 14 video models, 9 spatial systems, and 8 embodied candidates, showing that current systems still struggle with interactive simulation, persistent state, and programmable dynamics.
Dataset
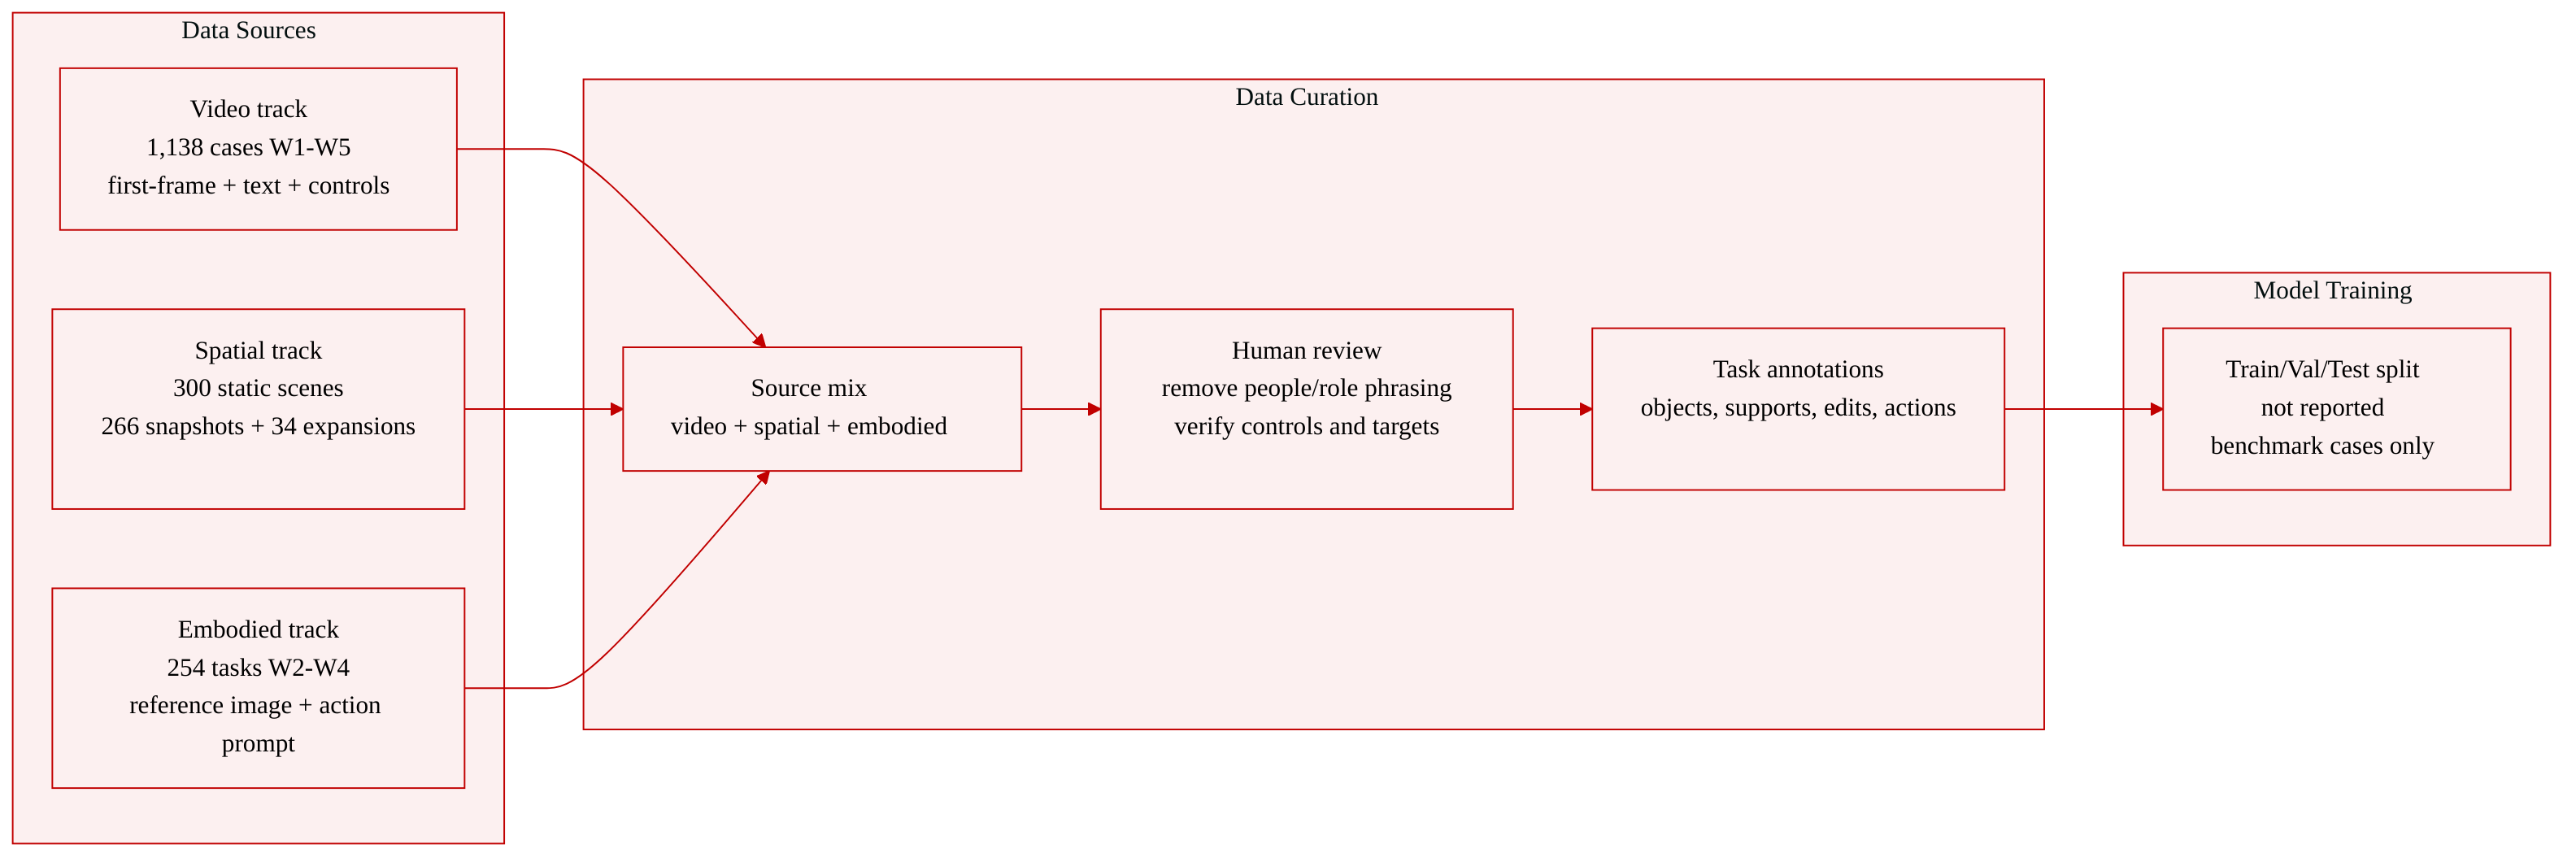
The paper describes three dataset tracks for world-model evaluation: a video track, a spatial track, and an embodied track. These sections define benchmark data rather than a training split, so no training mixture ratios are reported. No explicit cropping strategy is described in the provided text.
Video World Model Track
- Composition and sources: 1,138 structured test cases spanning W1 to W5. Each case includes a first-frame image, a textual description of the scene and selected subject, and a time-indexed control sequence where applicable. First frames are collected from real-world imagery, rendered environments, and generated images.
- Metadata and control levels: Cases are annotated by target capability, W level, application domain, image source, and viewpoint. W1 cases require no actions. W2 and W3 control sequences specify movement or camera rotation directions and time intervals, not target positions. W4 adds natural-language instructions for subject actions, interactions, and environmental rule edits. W5 and W6 support assigning controls to specific subjects.
- Filtering: Human reviewers verify that image and description agree, controls are executable and temporally coherent, and the evaluation target is observable. Cases with ambiguous targets, infeasible controls, or insufficient observable evidence are filtered out.
- Statistics:
- W1: 218 cases
- W2: 294 cases
- W3: 342 cases
- W4: 180 cases
- W5: 104 cases
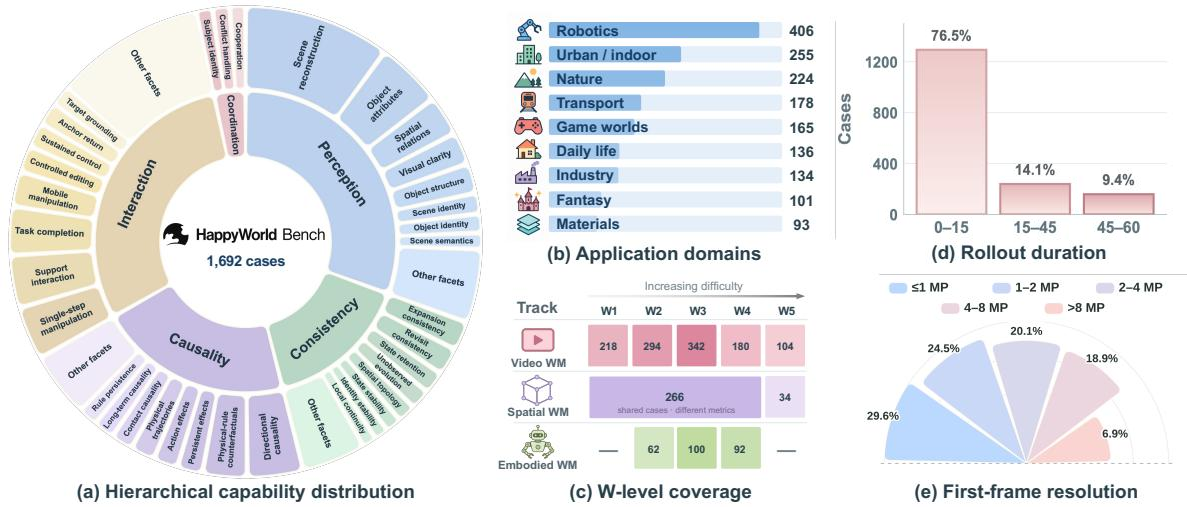
- The pool defines 74 fine-grained evaluation facets across five dimensions: perception and representation 342 cases, consistency and state retention 228 cases, causality and causal rollout 299 cases, controllable interaction and counterfactuals 212 cases, and multi-subject coordination 57 cases.
- Usage: The track provides structured test cases for video generation and capability-guided evaluation.
Spatial World Model Track
- Composition and sources: 300 static scenes total, consisting of 266 snapshot scenes and 34 separate spatial expansion cases. The data is built from filtered video-track inputs plus additional cases collected for specific spatial tasks.
- Filtering and rewriting: Candidate scenes are manually reviewed. Initial images containing people or visible body parts, including hands and legs, are excluded. Video-track descriptions are rewritten to remove first-person and third-person role phrasing.
- Task-specific annotations:
- Object consistency: Up to two visible, unobstructed objects are annotated per scene for orbit-based evaluation. In total, 424 target objects are annotated.
- Physical support: Scenes with identifiable support surfaces such as tabletops are selected. Support surfaces are annotated in 72 scenes for six plate-placement trials.
- Editing: 30 scene-instruction pairs are provided. This covers 18 object-level categories: addition, deletion, replacement, color, state, and material, plus 12 global categories: weather, lighting/time, atmospheric effects, and terrain.
- Expansion: 34 scenes are selected to allow further spatial expansion, including open doorways, corridors, paths, and open landscapes.
- Usage: The dataset is used for static spatial-world evaluation. The authors select only static scenes because no existing method currently supports full spatiotemporal world modeling.
Embodied World Model Track
- Composition and sources: 254 formal evaluation task instances spanning W2 to W4. Each instance is paired with a reference image. Records include a unique sample ID, task level, any required initial-frame condition, and an action prompt combining the robot head-mounted camera viewpoint with the complete action condition.
- Metadata construction: Each record includes annotated environment and subject descriptions used for auditing and for compiling VLM assertions. W4 records also include a shared paired-condition group, a branch ID, and the branch-specific action or physical-rule condition.
- Capability design:
- W2: Single atomic robot action. Each case specifies the acting subject, target, direction, and expected post-action state.
- W3: Longer-horizon ordered action sequences with temporal placement, used to assess action order, state persistence, and accumulated effects.
- W4: Paired condition tests from a shared initial state. Action-condition variants change motion direction, displacement magnitude, target, or action type. Physical-rule variants change gravity, friction, collision constraints, or material rigidity.
- Processing and evaluation format: W2 and W4 use 5.0 second rollouts; W3 uses 12.0 seconds. Videos are standardized to 24 FPS, yielding 120 frames for W2/W4 and 288 frames for W3. Automatic metrics and VLM assertion evaluation use 4 FPS sampling, yielding 20 frames for W2/W4 and 48 frames for W3. Spatial dimensions and encoding are normalized.
- Action vocabulary: The track covers grasping, lifting, opening, moving, pushing, placing, releasing, pressing, pulling, folding, inserting, wiping, sliding, turning, carrying, tapping, touching, stacking, and cutting.
- Usage: This track uses image-to-video rollouts with an explicit initial-frame condition for embodied evaluation.
Method
The authors propose a unified evaluation framework for world models that spans video, spatial, and embodied tracks. The framework is structured along two orthogonal axes: a capability axis ranging from W1 to W6, where each level represents a qualitative capability transition, and a scoring axis comprising perception, consistency, causality, and controllability. This design allows the framework to discriminate specific failure modes that holistic judgments might conflate, such as reaching a plausible terminal state while omitting the required action process.
For the Video World Model Track, the authors construct structured test cases for video generation. Each case comprises a first-frame image, a textual description of the scene, and a time-indexed control sequence. Task assignments follow a capability matrix that specifies the target W level and evaluation dimension. The control specifications are tailored to the target capability; for instance, W1 cases assess natural scene evolution without external control inputs, while W4 cases support natural-language instructions for subject actions and environmental rule edits. The case design covers complementary aspects of world modeling, including natural dynamics, appearance and spatial structure, movement and environmental responses, long-term persistence, and interaction.
The hierarchical capability distribution and W-level coverage across the different tracks are summarized in the figure below:
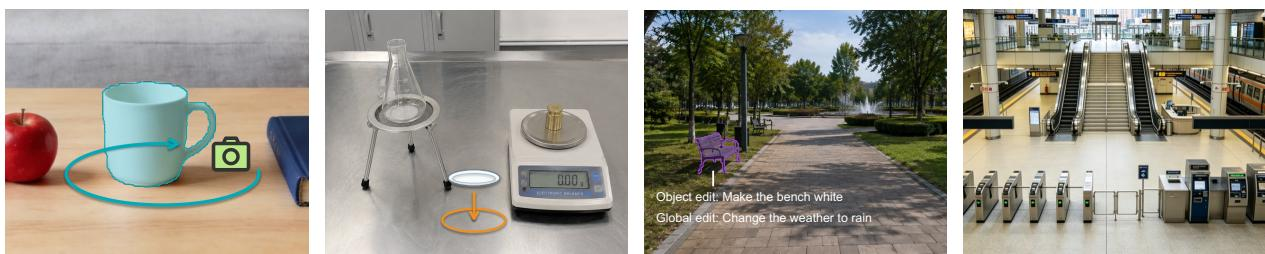
For the Spatial World Model Track, the authors build a dataset from filtered video-track inputs and additional cases collected for specific spatial tasks, focusing exclusively on static scenes. They select candidate scenes and manually review them to exclude initial images containing people or visible body parts. To address the limitations of generic video conditions, selected cases are supplemented with task-specific annotations. These include annotating visible objects for orbit-based evaluation, identifying support surfaces for plate-placement trials, constructing scene-instruction pairs for object-level and global edits, and collecting scenes that allow further spatial expansion.
Examples of the task-specific scenes and annotations for the spatial track are shown in the figure below:
For the Embodied World Model Track, the authors formulate each case as an image-conditioned, prompt-controlled video generation problem. Let I0 denote the prescribed reference image representing an egocentric observation of the scene before the action, and let p denote the action prompt specifying the acting subject, target, action type, and direction. The model generates the video according to the equation Y1:T=Gθ(I0,p). The track evaluates three progressively challenging levels: W2 assesses the immediate response to a single atomic robot action, W3 evaluates ordered multi-step rollouts with persistent state, and W4 evaluates paired rollouts from a shared initial state under either a changed action condition or a changed physical rule. All generated videos are converted to a common evaluation format with standardized frame rates and spatial dimensions to ensure comparable metric computation across different model outputs.
Experiment
The evaluation spans three world-model tracks with progressively demanding capability levels. The video world model track assesses interactive models on perception, consistency, causality, and controllability, finding that overall preference does not align with level-specific strengths and that successful intervention execution alone does not ensure stable rule-governed dynamics. The spatial world model track compares models on visual quality, physical usability, persistence, editing, and expansion, showing that strong visual quality does not guarantee navigability, consistency, or editability, and that expansion quality depends on preserving existing regions. The embodied world model track evaluates video models on action-conditioned rollouts, where visual fidelity remains strong but action grounding, persistent state transfer, and condition-dependent physical responses remain limited.
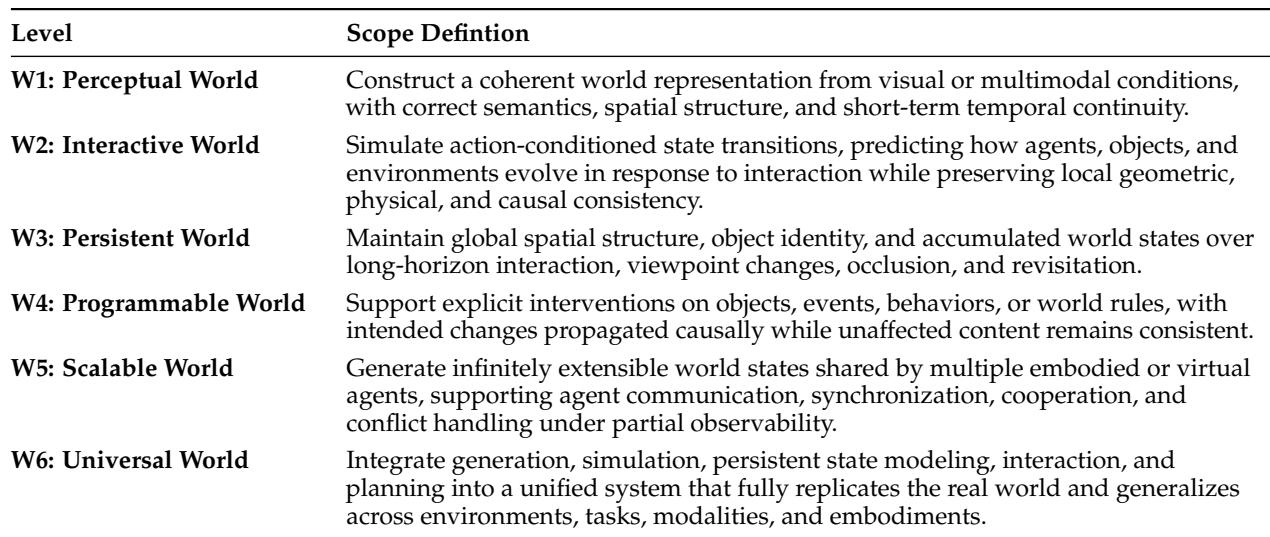
The capability hierarchy defines six world levels, from constructing short-term coherent perceptual worlds to supporting persistence, programmable interventions, multi-agent scalability, and universal simulation. Evaluation spans perception and representation, consistency and state retention, and causality and causal rollout. Across interactive through programmable levels, visual fidelity remains generally strong, but action grounding, persistent state evolution, and condition-dependent physical response become progressively weaker. The hierarchy moves from short-term perceptual coherence and action-conditioned transitions to long-horizon persistence, programmable interventions, multi-agent worlds, and unified universal simulation. Across interactive through programmable levels, visual fidelity and scene appearance remain generally strong while faithful modeling of action-conditioned dynamics becomes more limited as interaction requirements increase. Persistent world scenarios show unreliable transfer of previously established states into later stages, leading to failures in long-horizon action execution and accumulated scene changes. Programmable world scenarios often show little observable response to edited physical rules such as material, gravity, or friction, and only partial response to edited action conditions. Current video models generate realistic robot-centric rollouts but remain limited in action grounding, persistent state evolution, and condition-dependent physical response.
HappyOyster leads overall Arena preference, with Genie 3 ranking second. Capability-specific scores show a different picture: Genie 3 is strongest on W1 by a narrow margin, while HappyOyster records the top W2 and W3 scores. W4 results are available for only two models, and HappyOyster outperforms LingBot-World-v2 in that setting. Overall preference and capability scores do not align perfectly: HappyOyster has the highest Arena Elo, but Genie 3 edges it out on W1. HappyOyster is the only top Arena performer to also post the highest W2 and W3 capability scores and leads the limited W4 comparison.
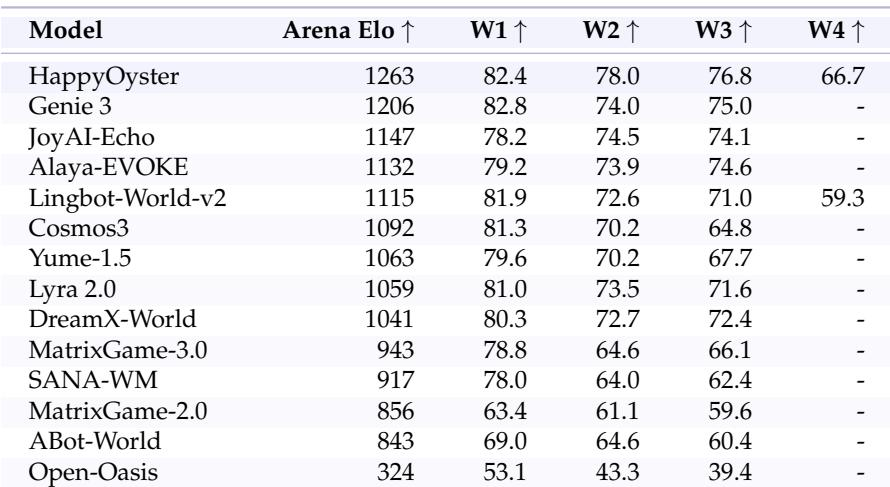
Across evaluated models, visual quality and instruction following are generally strong, while consistency measures vary much more. Several models with high perceptual scores still show weaknesses in dynamic, temporal, or geometry consistency, showing that visually compelling generation does not guarantee stable world behavior. The results support treating perceptual quality and world consistency as complementary capabilities. HappyHorse 1.1 and HappyOyster show strong visual and instruction-following performance, yet their dynamic consistency is only moderate, and HappyHorse also has weak geometry consistency. DreamX-World produces a near-perfect dynamic score but weak geometry consistency, whereas ABot-World combines strong background and geometry scores with very low dynamic consistency.
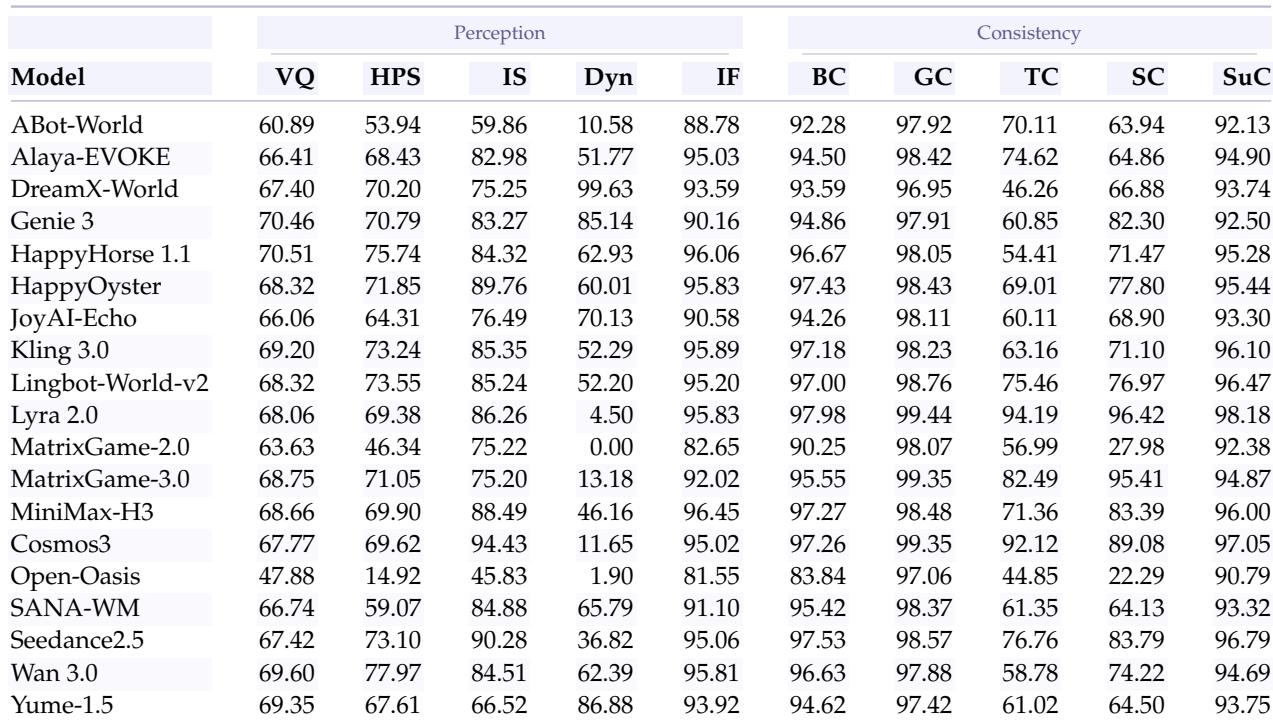
In this interactive world evaluation, action execution and causal consistency vary widely across models. HappyOyster achieves the strongest action execution and causal consistency among reported models, while Genie 3 shows strong visual quality and state consistency but weaker action execution. Visual plausibility and control-following do not guarantee coherent state transitions or causally consistent outcomes. HappyOyster leads in action execution and causal consistency but has relatively low temporal consistency compared with its strong interaction and physical consistency scores. Genie 3 performs well on visual quality and state consistency yet records the weakest action execution among the compared models. Models with similar control-following or target accuracy can differ substantially in state consistency and causal consistency, showing a gap between action resemblance and grounded world transitions.
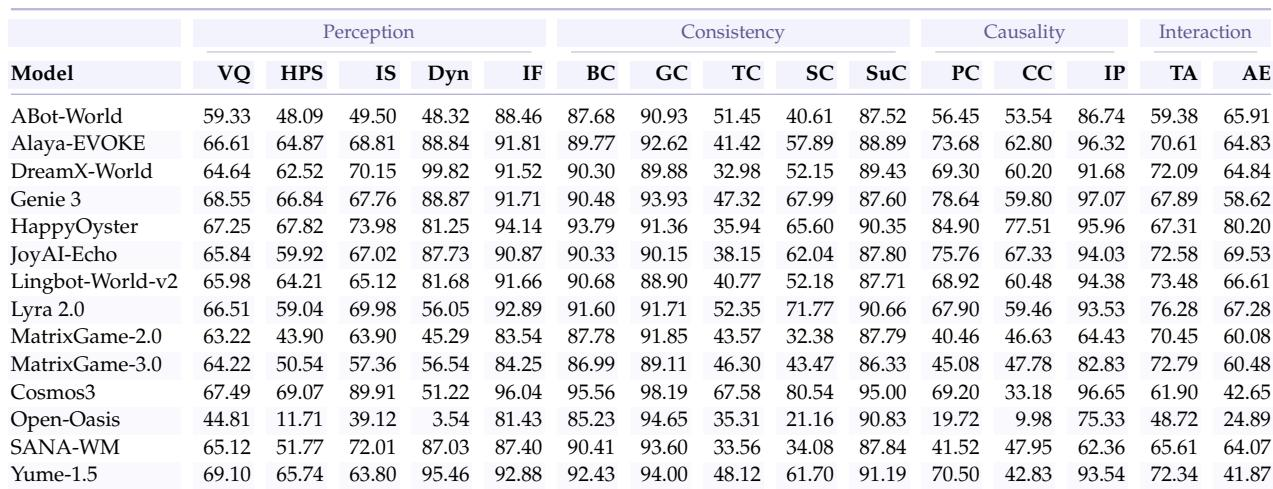
Long-horizon world persistence remains challenging for evaluated models. Visual and geometric consistency are relatively stable, but temporal and state consistency weaken substantially under extended interaction and revisitation. HappyOyster leads overall on this benchmark, while ABot-World lags across visual, consistency, and causality metrics. Temporal consistency and state consistency are the weakest consistency dimensions across most evaluated models. HappyOyster achieves the highest overall world persistence score among the evaluated models. ABot-World trails other models in visual quality and in several state and causal consistency metrics.
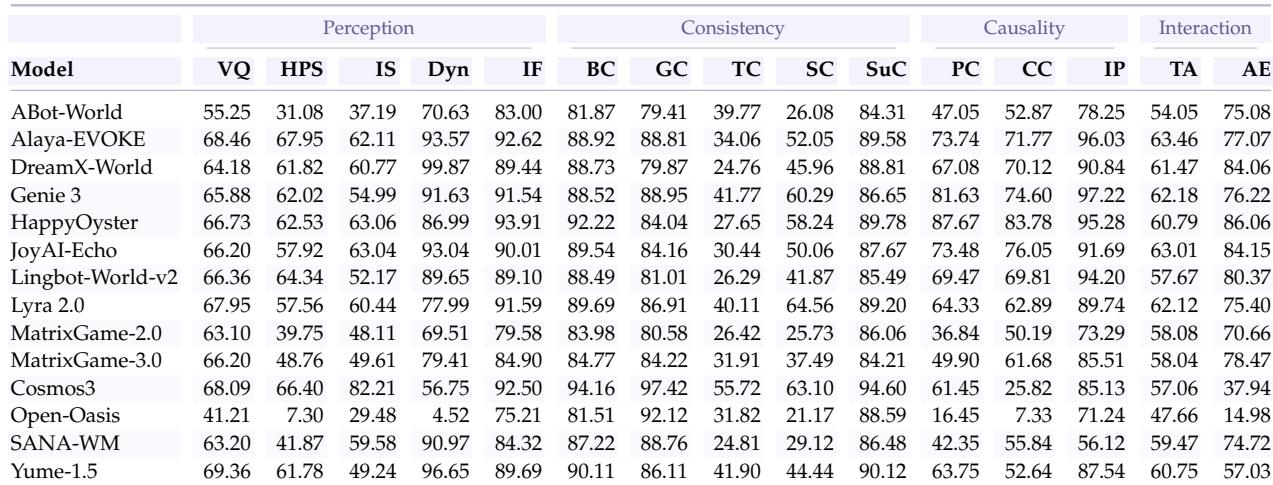
The evaluation spans six world-capability levels, from short-term perceptual coherence to programmable and persistent worlds, and assesses visual quality, consistency, action grounding, causality, and long-horizon state retention. Visual fidelity and instruction following are generally strong, while temporal, state, and geometric consistency vary widely, and models often fail to honor edited physical rules or maintain previously established states over long interactions. HappyOyster leads the overall arena and most interactive and persistence benchmarks, whereas Genie 3 is competitive on early visual perception but weaker on action execution; overall, high perceptual quality does not guarantee grounded, causally stable world transitions.