Command Palette
Search for a command to run...
스크립트 인지형 Mixture-of-Experts 기반 올인원 다국어 장면 텍스트 인식
스크립트 인지형 Mixture-of-Experts 기반 올인원 다국어 장면 텍스트 인식
Xingsong Ye Yongkun Du Jiaxin Zhang Zhixian Li Chong Sun Chen Li Jing LYU Lianwen Jin Zhineng Chen
초록
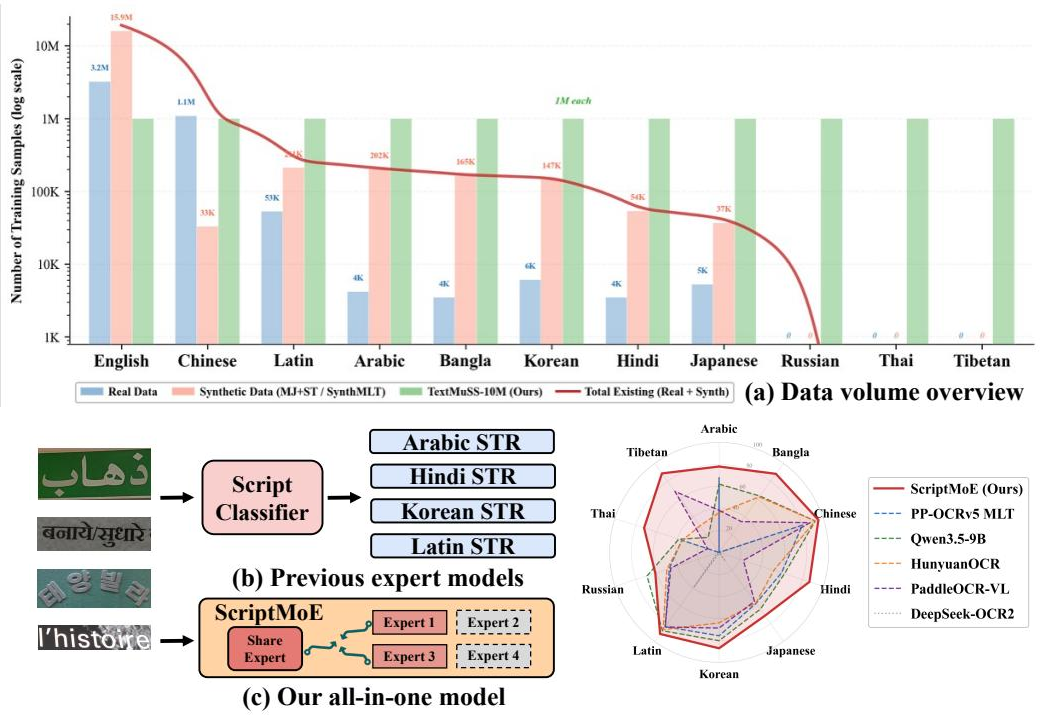
다국어 장면 텍스트 인식(STR)은 대부분 언어에서 학습 데이터가 부족하고, 단일 모델로 다양한 스크립트를 처리하기 어렵기 때문에 여전히 도전적인 문제이다. 기존 해결책은 언어별 인식기를 배포하여 비용이 증가하고 오류 누적이 발생하거나, 거대한 비전-언어 모델(VLM)에 의존하지만 이는 계산 비용이 크고 많은 스크립트에서 여전히 부정확하다. 본 연구에서는 언어별 전문가보다 단순하고 VLM보다 가벼우며 둘 다보다 정확한 올인원 다국어 인식기를 목표로 한다. 먼저, 10개 스크립트와 229개 언어를 포괄하는 대규모 합성 장면 텍스트 데이터셋 TextMuSS-10M을 구축한다. 이 데이터셋은 실제 데이터가 부족한 경우 균형 잡히고 충분한 지도 신호를 제공한다. 둘째, 스크립트 인지형 Mixture-of-Experts(MoE) 아키텍처인 ScriptMoE를 제안한다. 이 모델은 단일 시각 인코더를 공유하고 기존의 밀집 디코더를 희소 MoE 블록으로 대체한다. 이 블록은 이미지 수준 라우터가 각 이미지를 상위 2개의 스크립트 정렬 전문가로 분배하고, 공유 전문가가 교차 스크립트 지식을 흡수하도록 구성된다. 우리가 구축한 TextMuSS-Bench(10개 스크립트, 10,899개 이미지)에 대한 광범위한 실험 결과, ScriptMoE는 82.06%의 가장 높은 정확도를 달성하여 가장 강력한 STR 기준 모델보다 1.31% 높은 성능을 보였다. CC-OCR 종단 간 다국어 과제에서는 PP-OCRv5의 인식기만 ScriptMoE로 교체하여 F1 점수가 65.71%에서 80.89%로 향상되었으며, 이는 최고 VLM(80.73%)을 훨씬 적은 파라미터 수로 근소하게 능가하는 결과이다.
One-sentence Summary
Researchers from Fudan University, Tencent Inc., and South China University of Technology propose ScriptMoE, a script-aware Mixture-of-Experts recognizer that uses an image-level router to dispatch images to top-2 script-aligned experts and a shared expert; trained on the TextMuSS-10M dataset spanning 10 scripts and 229 languages, it achieves 82.06% on TextMuSS-Bench and lifts CC-OCR F1 to 80.89%.
Key Contributions
- Introduces TextMuSS-10M, a large-scale synthetic scene text dataset covering 10 scripts and 229 languages, and TextMuSS-Bench, a real-image benchmark spanning all ten scripts with 10,899 images.
- Proposes ScriptMoE, a script-aware Mixture-of-Experts architecture with a shared visual encoder and a sparse MoE decoder where an image-level router dispatches each image to the top-2 script-aligned experts and a shared expert.
- Experiments report 82.06% average accuracy on TextMuSS-Bench, 1.31% above the strongest STR baseline, and replacing the PP-OCRv5 recognizer with ScriptMoE on the CC-OCR task raises F1 from 65.71% to 80.89%, surpassing the best VLM score of 80.73% at a fraction of the parameter count.
Introduction
Scene text recognition in the wild is a core OCR task, but most accurate models focus on English and Chinese, while deployed systems must handle many scripts such as Arabic, Cyrillic, Hindi, Japanese, Korean, and Thai. Prior multilingual approaches either use per-language expert recognizers with a separate language-identification step, which raises cost and error accumulation, or rely on large vision-language models that are too heavy for edge deployment; moreover, real training data for non-English and non-Chinese scripts is scarce. The authors address these gaps by building TextMuSS-10M, a balanced synthetic dataset covering 10 scripts and 229 languages, and TextMuSS-Bench for real evaluation, and by proposing ScriptMoE, a script-aware Mixture-of-Experts recognizer that shares a visual encoder while routing each image to top-2 script experts plus an always-on shared expert. This gives a single lightweight all-in-one model that improves average accuracy on their multilingual benchmark and reaches end-to-end OCR performance on par with much larger vision-language models.
Dataset
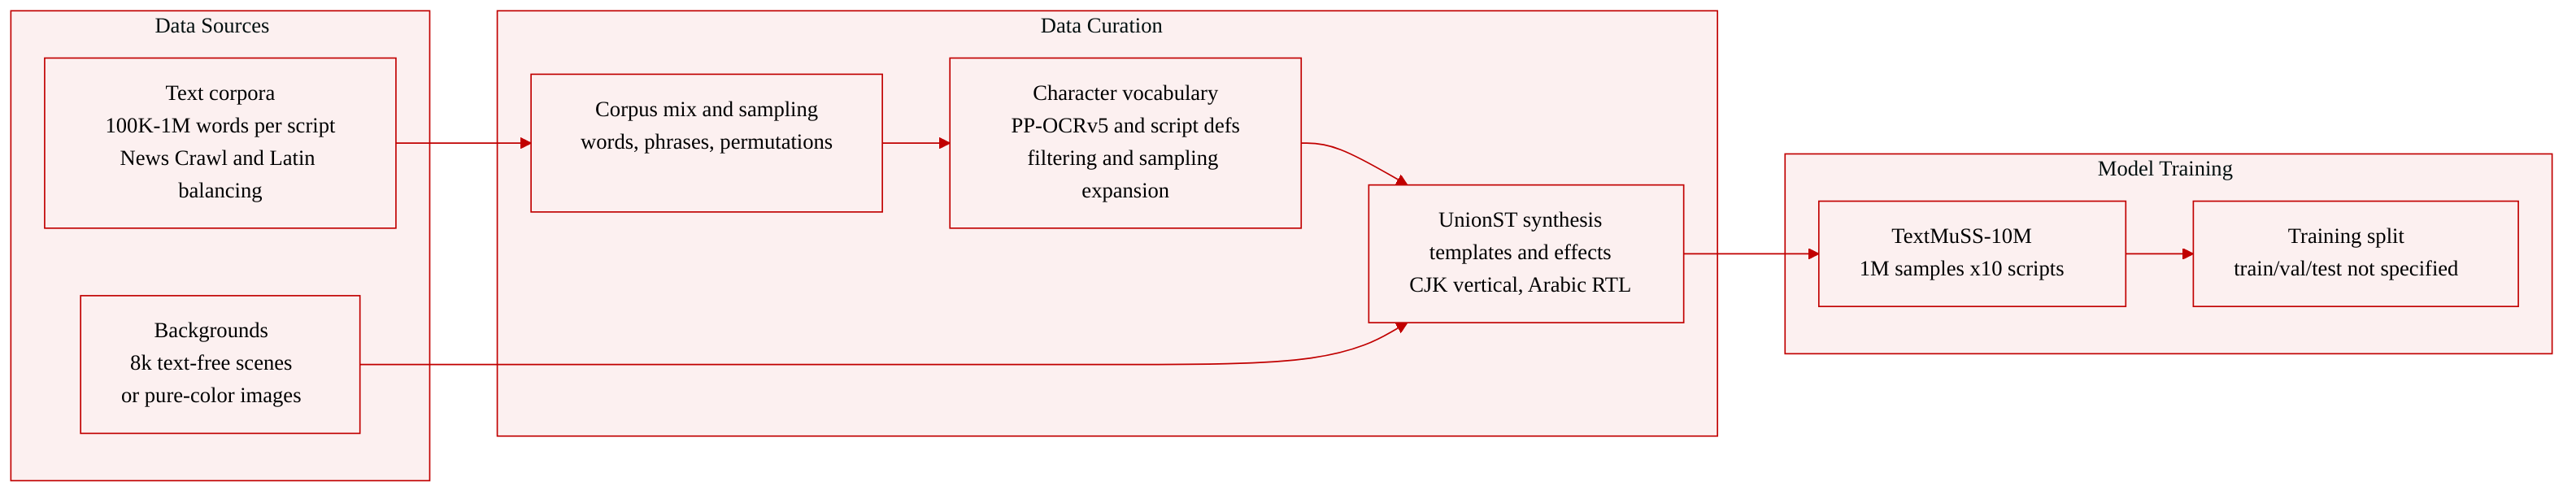
The authors build a large synthetic multilingual scene-text dataset called TextMuSS-10M after concluding that SynthMLT is too small and covers too few languages for high-accuracy training.
-
Dataset composition and sources
- TextMuSS-10M contains 1M synthetic samples per script across ten target scripts, for a total of 10M samples.
- Backgrounds come from 8,000 text-free scene images or pure-color images.
- Text corpora are collected per script, with 100K to 1M words per script.
- For Latin, which covers many languages, the authors collect more words and balance across languages.
- Longer text is simulated by concatenating word-level text with spaces.
- Random permutations of the character table add meaningless text to balance character and length distributions and cover rare characters.
- News Crawl newspaper corpora provide real sentence-level text, from which phrases and sentences of various lengths are extracted.
-
Key processing details
- The authors adapt the UnionST synthesis engine.
- A character vocabulary is built for each target script using PP-OCRv5 MLT and standard script definitions.
- This character set is used for filtering and sampling expansion.
- Layout templates include horizontal, vertical, multidirectional rotation, and curved text.
- Text layers receive effects such as shadow, distortion, and perspective before being overlaid on backgrounds.
- Script-specific adjustments include:
- Chinese, Japanese, and Korean use 20% vertical text synthesis.
- Other scripts use 5% vertical text synthesis.
- Arabic text is rendered from right to left and saved in logical order.
-
How the dataset is used
- TextMuSS-10M serves as the foundation for subsequent script-balanced, high-accuracy scene text recognition models.
- The section does not specify a training split, mixture ratios, cropping strategy, or metadata construction details.
Method
The authors identify data scarcity for long-tail scripts as a primary obstacle in building a high-accuracy multilingual scene text recognizer. To address this, they construct TextMuSS-10M, a balanced multilingual synthetic dataset. They adapt the UnionST synthesis engine by collecting specific character vocabularies and diverse corpora for each target script. The corpus collection includes word-level text, concatenated phrases to simulate longer text, random permutations for rare characters, and extracted sentences from newspaper corpora to simulate real semantics. Language-specific adjustments are applied, such as a higher proportion of vertical text for CJK scripts and right-to-left rendering for Arabic. The specific synthesis flow involves selecting text-free scene images as backgrounds, rendering text using preset layout templates including horizontal, vertical, rotated, and curved formats, applying effects like shadow and distortion, and overlaying the text layer onto the background. The resulting synthesis examples are displayed below.
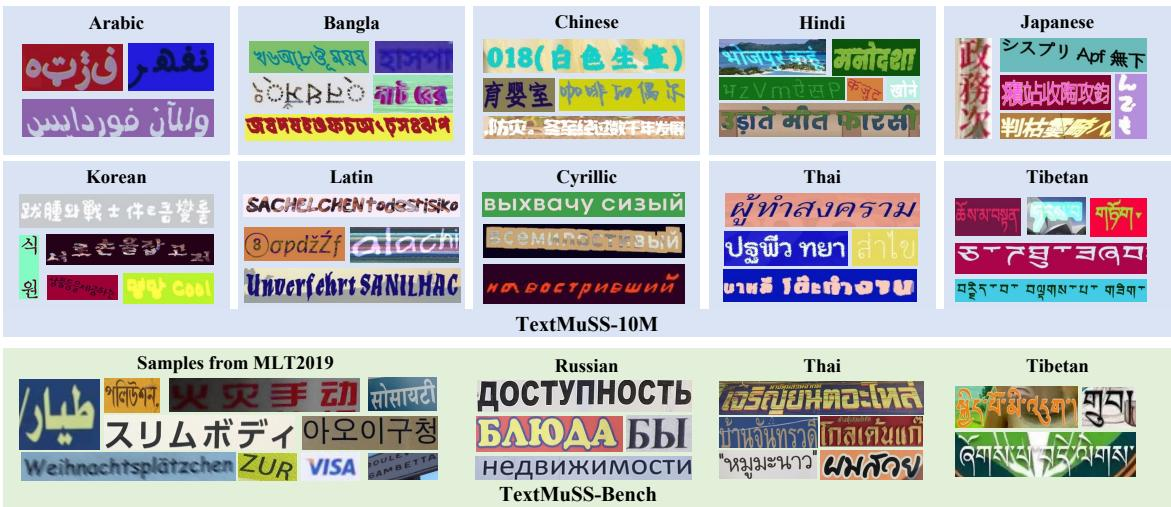
To overcome the capacity limitations of a single dense decoder, the authors propose ScriptMoE, which leverages the single-image-few-script prior. Refer to the framework diagram for the full pipeline overview.
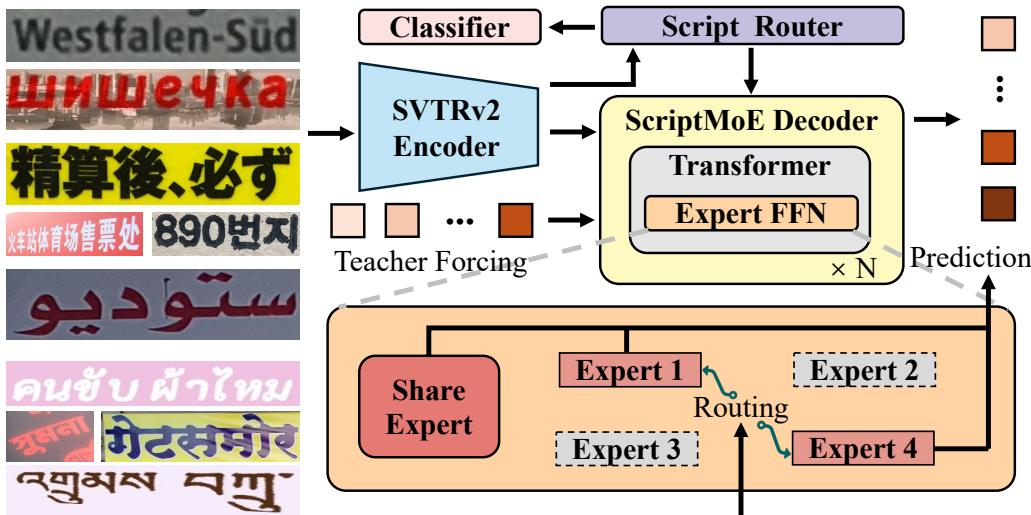
The architecture begins with a hierarchical visual encoder (SVTRv2) that maps an input image x∈RH×W×3 to a sequence of visual tokens F∈RL×d. These tokens are fed into a script-aware Transformer decoder where the standard feed-forward network (FFN) is replaced by a Mixture-of-Experts (MoE) block. The remaining components operate identically to a vanilla Transformer decoder, producing output autoregressively. Let ht∈Rd be the decoder hidden state at step t. The MoE layer computes the output as:
MoE(ht)=αtFFNshare(ht)+(1−αt)i=1∑ngiFFNi(ht)where the gating weights gi are determined by:
gi=∑jpj⋅I{j∈TopK(p)}pi⋅I{i∈TopK(p)}and the routing probabilities p are calculated via:
p=softmax(Wg(Fˉ⊙(1+σ⋅ϵ)))Here, Fˉ∈Rd is the image-level router input obtained by mean-pooling the visual tokens F. ϵ∼N(0,I) is a multiplicative router jitter applied during training, Wg is the router projection, and TopK selects the highest-scoring experts (Top-2). A learnable per-token gate αt=sigmoid(ws⊤ht) balances the shared and routed branches.
Crucially, the router input is formed once per image rather than per token, meaning all output tokens of an image are processed by the same routed experts. This design reduces routing cost, avoids token-level instability, and allows each expert to act as a script specialist. The authors group the ten target scripts into four categories based on character morphology: Alphabet (Latin, Cyrillic), CJK (Chinese, Japanese, Korean), Arabic family, and Others (Hindi, Bangla, Tibetan, Thai).
The shared expert FFNshare is always activated regardless of the routing decision. It absorbs script-invariant features such as digits, punctuation, and geometric distortions, preserving cross-script transfer and preventing the fragmentation of common knowledge.
To ensure the router aligns with actual scripts rather than discovering arbitrary groupings, the authors introduce a script-classification signal. An auxiliary four-way classification head hscls:Rd→R4 is attached to the same pooled router input Fˉ. This head is trained using cross-entropy loss against the script-group label yx, which is derived automatically by mapping the Unicode ranges of the ground-truth transcription characters to one of the four script groups:
Lscls=−∣B∣1x∈B∑logsoftmax(hscls(Fˉx))yxwhere B is the mini-batch. This classifier shares the router input but not the router weights, providing a script-aware learning signal while allowing the router to form useful within-script sub-populations.
The entire ScriptMoE model is trained end-to-end by minimizing the combined objective:
L=Lar+λsclsLsclswhere Lar is the standard autoregressive cross-entropy loss. The auxiliary term Lscls is weighted with λscls=0.1 to orient the experts towards scripts without overriding the router flexibility.
Experiment
ScriptMoE is evaluated on the TextMuSS-Bench STR benchmark covering ten scripts and on end-to-end multilingual OCR with CC-OCR, using a fixed detector and training baselines on identical data for fair comparison. The main results show that ScriptMoE improves recognition especially on low-resource scripts and that its router learns script-specific expert specialization, while broad generalist OCR systems do not guarantee multilingual accuracy. Ablations confirm that synthetic data is essential for unseen low-resource scripts, that a moderately sparse mixture-of-experts decoder is more effective than dense or overly specialized variants, and that script-aware components provide the largest benefits for low-resource scripts.
The benchmark comprises 10,899 images across ten major scripts. Latin is the dominant script group, contributing more than half of all images, while the remaining scripts have much smaller and uneven representation. Among non-Latin scripts, Russian and Thai have the largest evaluation sets, and Chinese and Tibetan are among the smallest. Latin contributes the majority of images in the benchmark. Non-Latin script representation is uneven, with Russian and Thai larger than Chinese and Tibetan. Several scripts, including Arabic, Bangla, Hindi, and Tibetan, have relatively small evaluation sets.

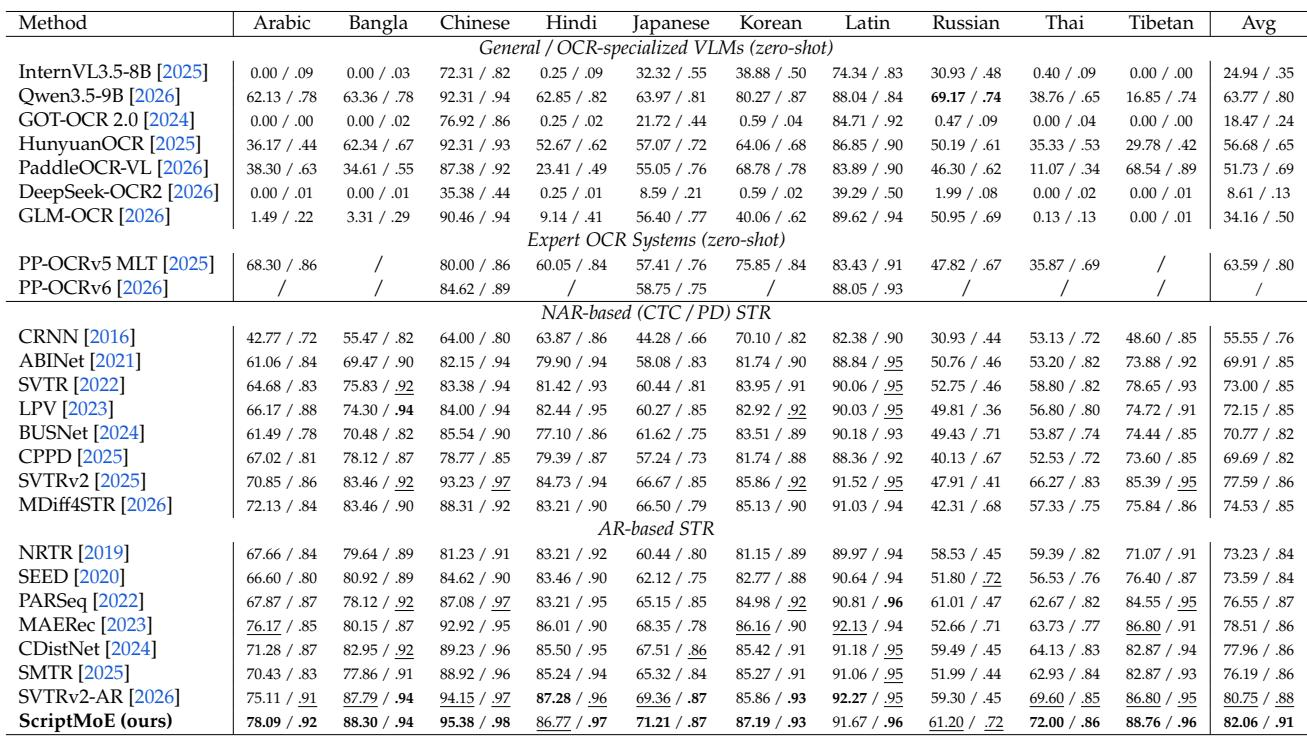
ScriptMoE attains the highest average text recognition accuracy among STR-class models on TextMuSS-Bench and outperforms the strongest baseline, with the largest gains on low-resource scripts such as Arabic, Thai, and Tibetan. General and OCR-specialized vision-language systems trail substantially, and several fail almost completely on Arabic, Bangla, and Tibetan. ScriptMoE achieves this while activating far fewer parameters per image than VLM-based alternatives. ScriptMoE reaches 82.06% average word accuracy, improving over the strongest STR baseline by 1.31 percentage points. Gains are concentrated on low-resource scripts, with notable improvements for Arabic, Thai, and Tibetan. Generalist vision-language OCR systems trail by 18 to 70 average points and some collapse on Arabic, Bangla, and Tibetan. ScriptMoE activates far fewer parameters per image than VLM-based systems.
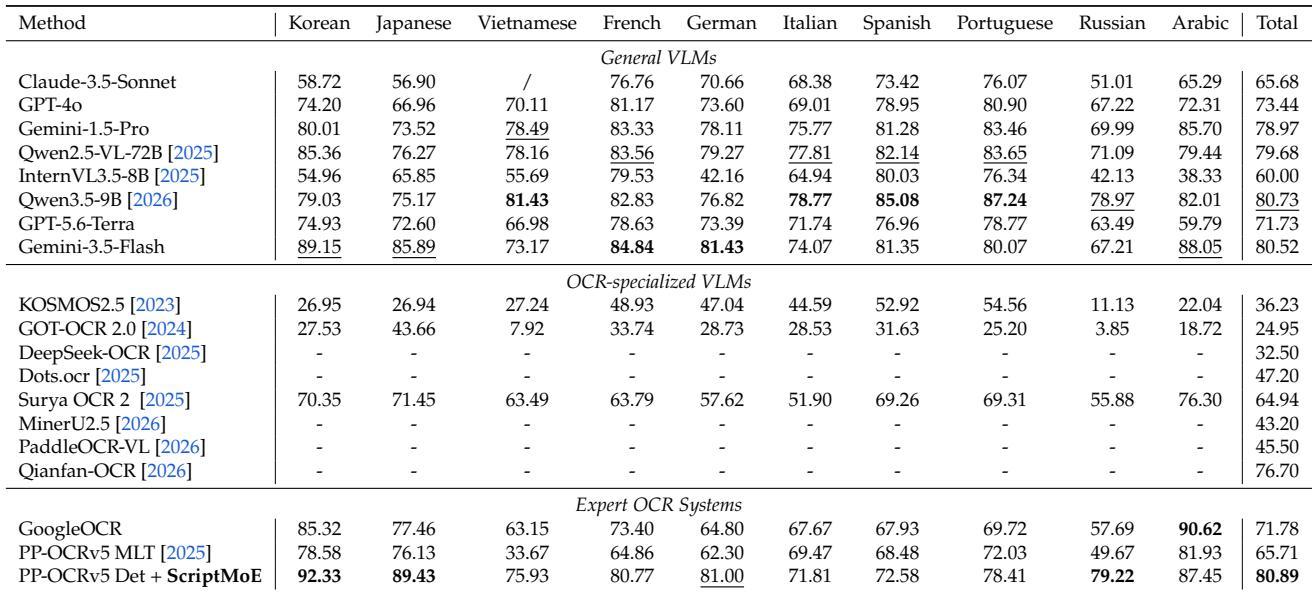
On the multilingual end-to-end OCR benchmark, general vision-language models vary widely, with Qwen3.5-9B leading and InternVL3.5-8B clearly trailing. Replacing the PP-OCRv5 MLT recognizer with ScriptMoE lifts overall F1 from about 66 to about 81, narrowly surpassing the strongest generalist and specialized baselines. Because detection is fixed, the gain is attributed to stronger script-aware recognition. Among general VLMs, Qwen3.5-9B posts the highest total F1, followed closely by Gemini-1.5-Pro and Qwen2.5-VL-72B; InternVL3.5-8B lags substantially, especially on Arabic, Russian, and German. ScriptMoE-based OCR edges past the strongest zero-shot general VLM, the best OCR-specialized VLM, and expert OCR baselines while using a fixed detector, indicating recognition quality drives the improvement. Latin-script languages such as Spanish, Portuguese, French, and Italian tend to score higher across systems, while performance on Korean, Japanese, and Arabic is more variable.
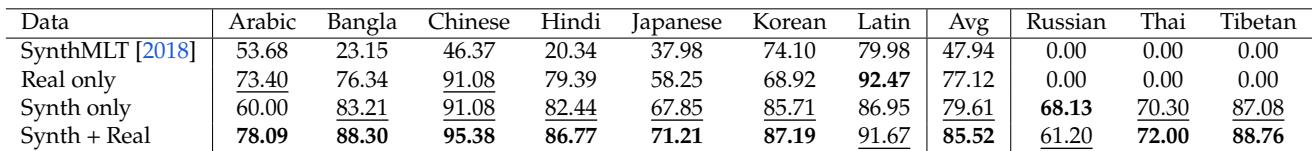
Real-only training performs well on the seven scripts it sees but fails on Russian, Thai, and Tibetan. Synthetic-only training covers all ten scripts and already surpasses real-only on the seven-script average, while the combined setup achieves the highest overall accuracy. The main trade-offs are small drops in Latin and Russian, attributed to visual confusion between Latin and Cyrillic. Real-only training collapses on Russian, Thai, and Tibetan, while synthetic-only training lifts those scripts from zero to substantial accuracy and already beats real-only on the seven-script average. Combining real and synthetic data produces the best overall accuracy, though adding synthetic data slightly lowers Latin and adding real data slightly lowers Russian, indicating Latin-Cyrillic cross-script confusion.
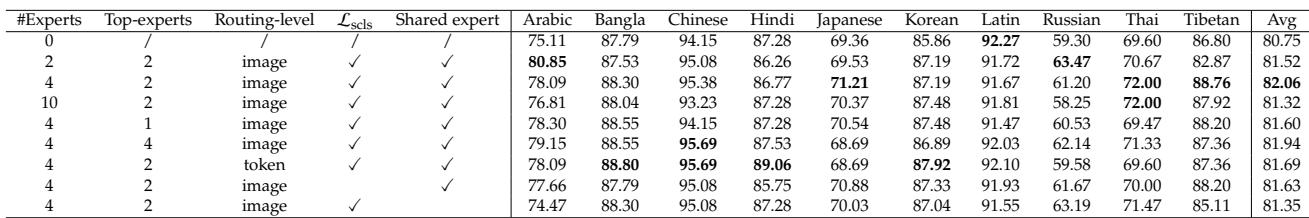
The MoE decoder is essential for multi-script recognition: the pure AR baseline without experts trails MoE configurations except on Latin. Four experts with top-2 routing achieve the best average accuracy, while scaling to one expert per script or activating more experts per item does not improve overall performance. Script-aware components provide further gains, with the shared expert being especially important for low-resource scripts. The no-MoE baseline underperforms MoE variants on average and only remains competitive on Latin, the most data-rich script. Four experts with top-2 routing yield the best average accuracy, with notable gains on Thai and Chinese compared with the baseline. Using ten experts, one per script, reduces accuracy relative to four experts because each expert sees too few samples to specialize. Top-1 routing beats the no-MoE baseline but is weaker than top-2 on Thai and Chinese; top-4 routing adds cost without meaningful average benefit and hurts Japanese and Korean. Token-level routing performs similarly to image-level routing overall, with small per-script trade-offs but higher router cost. Removing the shared expert causes a larger average drop than removing the script-classification signal, concentrated on low-resource scripts such as Arabic and Tibetan.
The experiments evaluate multilingual scene text recognition on a ten-script benchmark where Latin dominates and non-Latin scripts are unevenly represented, and they also test end-to-end OCR with a fixed detector. ScriptMoE outperforms strong STR baselines and generalist or OCR-specialized vision-language models, with the largest gains on low-resource scripts, and it lifts end-to-end OCR F1 from about 66 to about 81, indicating that recognition quality drives the improvement. Data ablations show that real-only training fails on unseen scripts, synthetic data is essential for coverage, and combined training works best except for small Latin/Cyrillic confusion. MoE ablations confirm that the expert decoder is necessary, four experts with top-2 routing are most effective, and the shared expert especially benefits low-resource scripts.