Command Palette
Search for a command to run...
OmniEdu: 학습과 교수를 위한 개방형 파운데이션 모델
OmniEdu: 학습과 교수를 위한 개방형 파운데이션 모델
Hao Liang Qihan Lin Meiyi Qiang Linzhuang Sun Hengyi Feng Mingrui Chen Sizhe Qiu Wentao Zhang
초록
교육용 파운데이션 모델은 단순히 정답을 생성하는 것 이상을 수행해야 한다. 즉, 문제가 교육과정에서 어디에 위치하는지 이해하고, 학습자가 왜 어려움을 겪는지 진단하며, 적절한 교수적 대응을 선택할 수 있어야 한다. 기존 교육 언어 모델은 대개 교과 문제 해결이나 튜터링 중 하나에 특화되어 있으며, 학습 혼합 데이터는 주로 출처나 과제별로 구성되어 이러한 능력들을 명시적으로 균형 있게 다루지 못한다. 본 논문에서는 K–12 학습 및 교수를 위한 개방형 파운데이션 모델군인 OmniEdu를 제안한다. OmniEdu는 능력 중심의 instruction-tuning corpus로 학습되었다. 이 corpus는 100개 이상의 교육 자원과 일반 instruction 소스를 결합하고, 교과 역량, 교육과정 그라운딩, 진단적 추론, 교수적 행동 및 스캐폴딩이라는 네 가지 상호보완적인 능력을 중심으로 supervision을 구성한다. 다단계 파이프라인은 결정적 정제, 의미적 감사 및 재작성, 과제별 품질 점수 부여, 토큰 예산 기반 다양성 선택, 교수적 instruction 할당을 수행하여 69,999개의 예시와 15.96M개의 supervised response token을 생성하며, 그중 60,951개는 교육 특화 예시이다. 우리는 4B, 9B, 27B 모델을 파인튜닝하고, 일반 능력에 대한 보조 테스트와 함께 교육과정 그라운딩, K–12 문제 해결, 교수적 튜터링 벤치마크에서 평가한다. 모든 모델 규모에서 교육 지향 튜닝은 세 교육 능력 그룹을 일관되게 향상시킨다. 특히 OmniEdu-27B는 K12-Bench에서 63.12% EM / 76.69% F1, MathFish에서 85.89%, EDUMATH에서 86.95%, MathTutorBench의 Scafold 설정에서 78.74%, LongTutor에서 평가 모델 중 최고인 Teaching average 3.02를 기록한다. 이러한 결과는 신중하게 선별되고 능력 간 균형을 갖춘 supervision이 일반 언어 모델을 문제 해결만이 아니라 교육과정 구조를 이해하고 효과적인 교수 상호작용을 지원하는 더 강력한 교육 시스템으로 전환할 수 있음을 보여준다.
One-sentence Summary
Researchers from Peking University, University of the Chinese Academy of Sciences, and Zhongguancun Academy introduce OmniEdu, an open family of K-12 foundation models trained with a capability-oriented instruction-tuning corpus that explicitly balances subject competence, curriculum grounding, diagnostic reasoning, and pedagogical action rather than specializing in either problem solving or tutoring as prior educational language models do; OmniEdu-27B achieves benchmark gains across all three educational capability groups, including 63.12% EM and 76.69% F1 on K12-Bench, 85.89% on MathFish, 86.95% on EDUMATH, 78.74% on MathTutorBench's Scafold setting, and the best Teaching average of 3.02 on LongTutor.
Key Contributions
- OmniEdu is introduced as an open family of K-12 educational foundation models trained with a capability-oriented instruction-tuning corpus that balances subject competence, curriculum grounding, diagnostic reasoning, and pedagogical action and scaffolding.
- The training corpus combines more than 100 educational resources and general instruction sources, and a multi-stage pipeline produces 69,999 examples and 15.96M supervised response tokens, including 60,951 education-specific examples through deterministic cleaning, semantic auditing and rewriting, task-specific quality scoring, token-budgeted diversity selection, and pedagogical instruction assignment.
- Evaluations across 4B, 9B, and 27B models on curriculum-grounding, K-12 problem-solving, and pedagogical-tutoring benchmarks show consistent improvements in all three educational capability groups. OmniEdu-27B reaches 63.12% EM / 76.69% F1 on K12-Bench, 85.89% on MathFish, 86.95% on EDUMATH, 78.74% on MathTutorBench's Scaffold setting, and the best Teaching average of 3.02 on LongTutor among evaluated models.
Introduction
Large language models are increasingly used in education, but answer accuracy alone misses the coordinated demands of tutoring: an effective model must connect a problem to curriculum structure, diagnose misconceptions, and choose instructional scaffolds that preserve learner reasoning. Prior educational models often isolate these capabilities by task or subject, while training data is heterogeneous and can obscure the intended pedagogical behavior. The authors introduce OmniEdu, an open family of K-12 foundation models organized around four capabilities: subject competence, curriculum grounding, diagnostic reasoning, and pedagogical action and scaffolding. They develop a reproducible, capability-oriented data pipeline that curates a compact 69,999-example training mixture with explicit pedagogical instructions. Evaluations show consistent gains across curriculum grounding, K-12 problem solving, and pedagogical tutoring at 4B, 9B, and 27B scales, with OmniEdu-27B achieving strong open-weight results and remaining competitive with larger proprietary systems on several problem-solving benchmarks.
Dataset
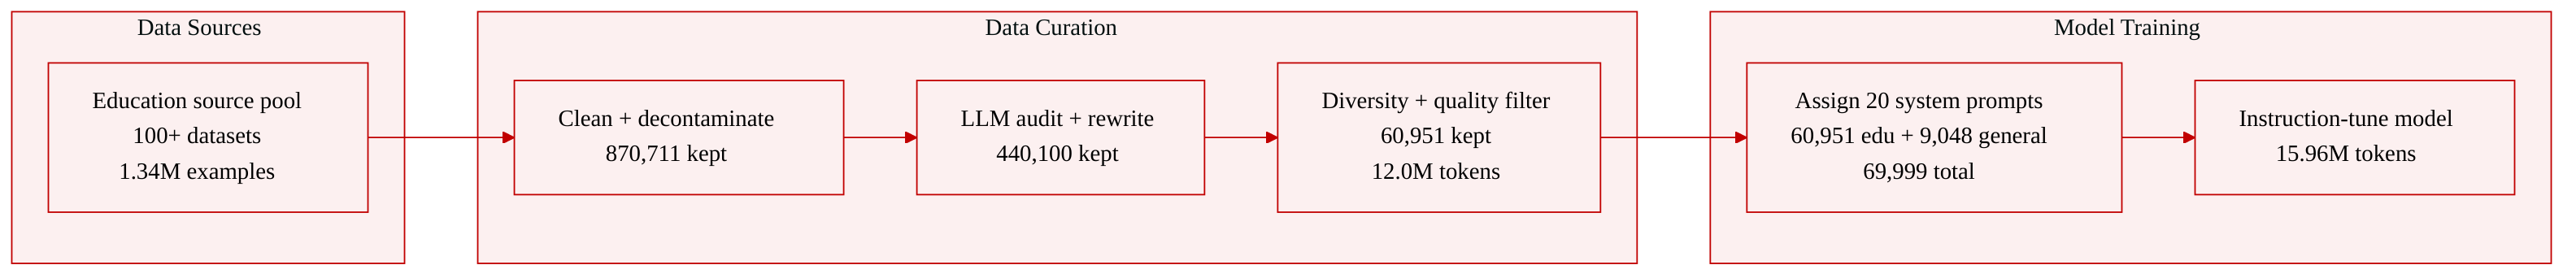
The authors construct an instruction-tuning corpus for K-12 education from more than 100 datasets and educational resources. Before curation, the education-specific pool contains approximately 1.34M examples. Example-level provenance, license, source-to-category mapping, and audit metadata are retained throughout the pipeline.
Dataset composition and capability taxonomy
- General-purpose partition: 9,048 examples, drawn from DataFlow-Instruct-10K (7,431), Tulu-3-SFT-mixture (1,495), and MathV360K (122). This partition preserves general instruction following, multilingual coverage, refusal behavior, and diagram-based reasoning.
- Education-specific partition: The main focus of the corpus. After curation, it contains 60,951 examples with about 12.0M supervised response tokens.
- Capability categories: Each education-specific example is assigned to one primary capability:
- Subject competence
- Curriculum grounding
- Diagnostic reasoning
- Pedagogical action and scaffolding
- Examples are further partitioned into fine-grained task buckets according to task form, modality, and supervision type.
- Final corpus size: 69,999 examples and 15.96M supervised response tokens.
Processing pipeline
-
Deterministic cleaning and evaluation decontamination:
- Standardizes sources into a unified representation.
- Removes exact duplicates and malformed examples.
- Verifies answer consistency where possible.
- Keeps only K-12 relevant content from mixed-domain sources.
- Confirms image accessibility and alignment for multimodal examples.
- Removes examples with unclear usage conditions and any evaluation set overlap.
- Result: 870,711 education-specific examples.
-
LLM-assisted semantic auditing and rewriting:
- Uses Qwen3.5-122B-A10B-FP8 to score examples from 0 to 100.
- Examples scoring 85 to 100 are kept, 50 to 84 are rewritten, and below 50 are removed.
- Rewritten examples are audited again and retained only if classified as keep.
- Result: 440,100 education-specific examples.
-
Preliminary diversity selection and fine-grained quality filtering:
- Applies k-center greedy selection over BGE-M3 embeddings to reduce overrepresented sources.
- Examples include:
- RACE: 60,180 to 5,000
- AquilaEdu: 23,226 to 2,000
- CJEval: 17,178 to 2,000
- Uses GPT-5.6-Terra for fine-grained scoring on a 1 to 5 scale.
- Retains examples only if all applicable dimensions score at least 3, with task-critical dimensions such as correctness, validity, and grounding scoring at least 4.
- Result: 121,318 education-specific examples.
-
Token-budgeted diversity selection:
- Performs k-center greedy selection over BGE-M3 embeddings within fine-grained task buckets.
- Allocates each bucket a supervised response token budget rather than an example-count budget.
- Result: 60,951 education-specific examples and approximately 12.0M supervised response tokens.
-
Pedagogical instruction assignment and final assembly:
- Assigns each example one of 20 task-specific system instruction templates.
- Templates cover behaviors such as reasoned problem solving, reading comprehension, diagnosis and correction, Socratic questioning, and tutoring dialogue.
- Original user and assistant content remains unchanged.
- Converts examples into a unified message-based format.
- Materializes images and aligns them with placeholders.
- Runs final checks on message structure, media availability, duplicate identifiers, and cross-category duplicates.
How the data is used
The final corpus is used as an instruction-tuning mixture for the educational language model. The 9,048 general-purpose examples maintain broad instruction-following abilities, while the 60,951 education-specific examples provide K-12 subject knowledge, curriculum grounding, diagnostic reasoning, and pedagogical supervision. The system instruction assigned to each example makes the intended pedagogical behavior explicit during training.
Method
The authors design a six-stage data preparation pipeline for constructing a K-12 instruction-tuning corpus. The pipeline begins with capability taxonomy and source collection, then progressively curates heterogeneous sources into a final training mixture while retaining example-level provenance and audit metadata.
The first stage defines the capability taxonomy and collects education-specific sources, producing an initial pool of roughly 1.34M examples before filtering. The second stage standardizes all heterogeneous sources into a unified representation, removes exact duplicates, and discards examples with missing or malformed required fields. For examples whose answers can be deterministically verified, the pipeline checks consistency between the provided answer and the corresponding reference or structured annotation. For mixed-domain sources, only K-12 relevant examples are kept, while unrelated content such as finance or general encyclopedic knowledge is filtered out. Multimodal examples are verified for image accessibility and correct alignment with the textual input. Source and license information is retained, data with unclear usage conditions are excluded, and any example overlapping with the final evaluation set is removed to prevent contamination. This stage reduces the education-specific pool to 870,711 examples.
The third stage applies LLM-assisted semantic auditing and rewriting. The authors use Qwen3.5-122B-A10B-FP8 to perform semantic quality control that cannot be handled by deterministic rules. Each example is evaluated with a task-specific auditing prompt and assigned a 0-100 usability score together with one of three actions: keep, rewrite, or remove. Examples scoring 85-100 are retained, examples scoring 50-84 are sent for repair, and examples below 50 are discarded. The auditing criteria adapt to the supervision target. Subject competence examples are checked for answer correctness, consistency between the answer and explanation, and grounding in the given problem or passage. Curriculum examples are checked for valid curriculum relations and sufficiently specific knowledge point alignment. Diagnostic examples are checked for whether the identified error is supported by the student work and whether the diagnostic explanation and corrective response are consistent with that error. Pedagogical examples are additionally evaluated for instructional relevance, coherence, scaffolding quality, and premature leakage of the final answer. For examples labeled rewrite, the original input remains fixed and only defective supervision is repaired. The rewritten example is audited again using the same criteria and is retained only if it is classified as keep. This stage leaves 440,100 education-specific examples.
The fourth stage combines preliminary diversity selection with fine-grained quality filtering. Before applying a more expensive quality scorer, the authors reduce a small number of highly overrepresented sources whose candidate sizes substantially exceed their intended contribution to the final mixture. For these sources, k-center greedy selection over BGE-M3 embeddings is used to select a semantically diverse subset rather than randomly subsampling. Then GPT-5.6-Terra performs fine-grained scoring with task-specific rubrics refined from the third-stage criteria. Each applicable dimension is scored on a 1-5 scale. For example, problem-solving data are evaluated separately for problem validity, answer correctness, reasoning correctness, completeness, relevance, and clarity. An example is retained only if every applicable dimension scores at least 3, with a stricter threshold of 4 for task-critical dimensions such as correctness, validity, and grounding. This reduces the candidate pool to 121,318 examples.
The fifth stage applies token-budgeted diversity selection within fine-grained task buckets. Because response lengths differ substantially across tasks, each bucket is allocated a budget in terms of supervised response tokens. Within each bucket, k-center greedy over BGE-M3 embeddings is again used to maximize semantic coverage, and examples are selected greedily until the corresponding supervised-token budget is reached. This reduces the education-specific pool to 60,951 examples, containing approximately 12.0M supervised response tokens.
The final stage assigns pedagogical instructions and assembles the corpus. The authors associate each selected example with a task-specific system instruction determined by its predefined task bucket. They use 20 system instruction templates covering behaviors such as reasoned problem solving, reading comprehension, diagnosis and correction, Socratic questioning, and tutoring dialogue. This design allows a single model to learn multiple pedagogical behaviors while making the desired behavior explicit in the input. Each example receives exactly one system instruction, while the original user and assistant content remains unchanged. Finally, all examples are converted to a unified message-based format, referenced images are materialized and aligned with their corresponding image placeholders, and final integrity checks are performed on message structure, media availability, duplicate identifiers, and cross-category duplicates.
Experiment
The paper first standardizes and filters heterogeneous K-12 sources, removes duplicates and evaluation overlaps, and retains 870,711 examples for semantic auditing. The main experiments fine-tune three base models of different scales on this corpus and evaluate them on curriculum grounding, K-12 problem solving, pedagogical tutoring, and general benchmarks, comparing with open educational LLMs and proprietary systems. Education-oriented tuning consistently improves curriculum understanding, exam-style problem solving, and tutoring quality across all scales, with particularly large gains in scaffolded instruction and use of student learning history. These specialization gains do not come at the cost of general instruction following, reasoning, or multimodal understanding.
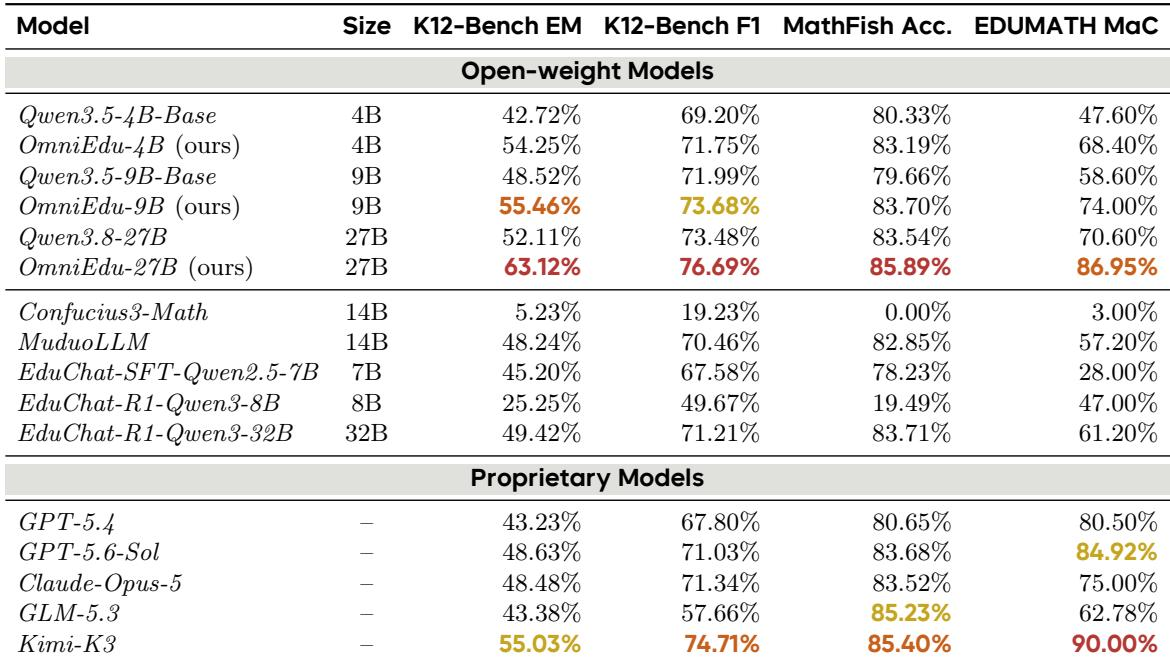
Education-oriented tuning improves curriculum grounding across all model scales, with OmniEdu-27B achieving the strongest overall performance among evaluated models. Gains are consistent across K12-Bench, MathFish, and EDUMATH, covering both knowledge grounding and structural curriculum reasoning. OmniEdu-27B ranks first on K12-Bench and MathFish among evaluated models and is second only to Kimi-K3 on EDUMATH. The 4B and 9B tuned models also show substantial and consistent gains over their base versions, especially on EDUMATH.
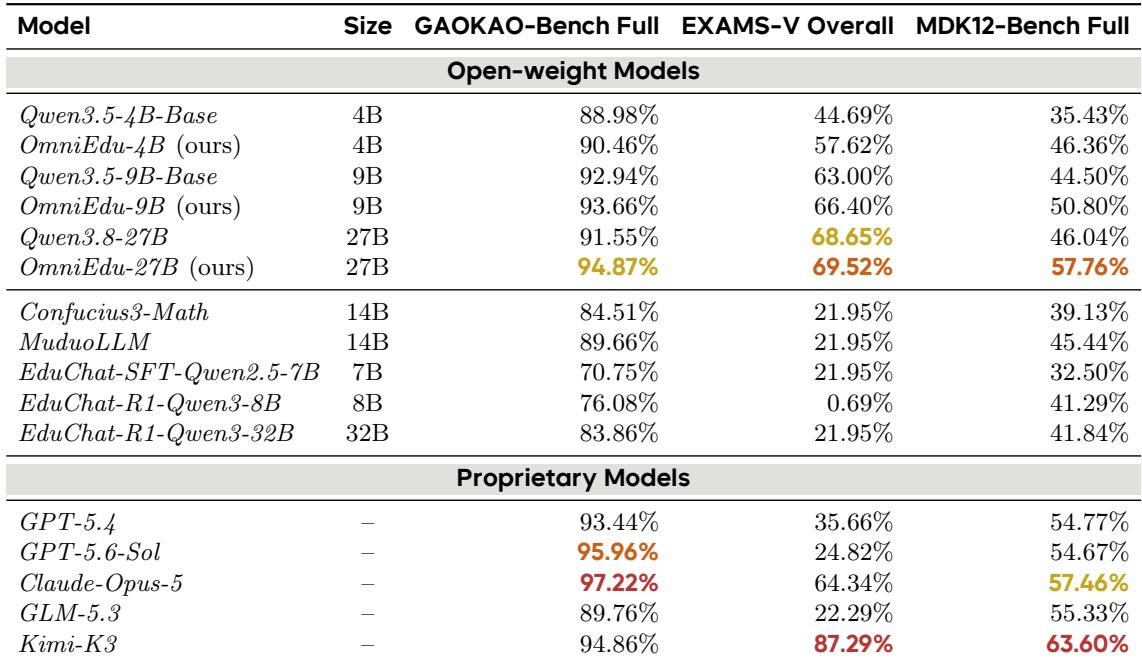
Education-oriented tuning improves K-12 problem-solving across all evaluated model scales. Each OmniEdu model outperforms its corresponding base model on the overall metric for GAOKAO-Bench, EXAMS-V, and MDK12-Bench, with especially strong gains for OmniEdu-4B on EXAMS-V and OmniEdu-27B on MDK12-Bench. OmniEdu-27B leads the open-weight educational baselines and remains competitive with frontier proprietary models despite its smaller scale. OmniEdu-27B improves the GAOKAO-Bench full-score rate from 91.55% to 94.87% and the MDK12-Bench overall score from 46.04% to 57.76%. OmniEdu-4B shows the largest EXAMS-V gain, rising from 44.69% to 57.62% overall accuracy. Every OmniEdu model outperforms its corresponding base model on overall K-12 benchmark metrics. OmniEdu-27B ranks within the top three overall on all three benchmarks and leads the evaluated open-weight educational baselines.
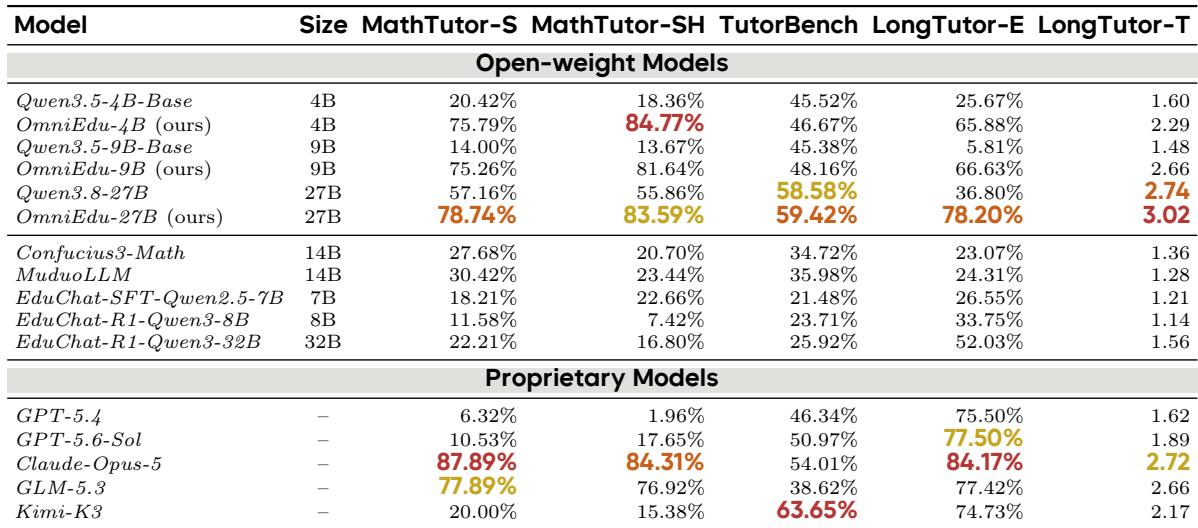
Education-oriented tuning improves pedagogical tutoring performance across all evaluated model scales. Gains are largest in scaffolded math tutoring and in using longitudinal student evidence, where tuned models substantially outperform their base versions. The largest tuned model achieves the strongest overall tutoring and teaching scores among the listed open models, while knowledge-state diagnosis remains comparatively difficult. Scaffolded and scaffolded-hard win rates improve markedly after tuning for every model size, with the smaller tuned models showing especially large relative gains. Use of longitudinal student evidence rises sharply after tuning, with the 9B model improving from a very low base level to match the tuned 4B model. The 27B tuned model leads the listed models in overall tutor benchmark score and teaching average, though knowledge-state diagnosis accuracy stays relatively low.
The experiments evaluate OmniEdu models at 4B, 9B, and 27B scales after education-oriented tuning across curriculum grounding, K-12 problem solving, and pedagogical tutoring benchmarks. In all three areas, tuned models consistently outperform their base versions, with OmniEdu-27B achieving the strongest overall results among open-weight educational models and remaining competitive with frontier proprietary systems. The largest gains appear in structural curriculum reasoning, exam-style problem solving, scaffolded tutoring, and use of longitudinal student evidence, while knowledge-state diagnosis remains comparatively difficult.