Command Palette
Search for a command to run...
VLM의 지능을 로봇 제어로 전이하기
VLM의 지능을 로봇 제어로 전이하기
Meng-Hao Guo Zhe-Han Mo Jia-Jun Wang Yi Zhang Kejin Wang Yi-Xuan Deng Jia-Peng Zhang Yongming Rao Shi-Min Hu
초록
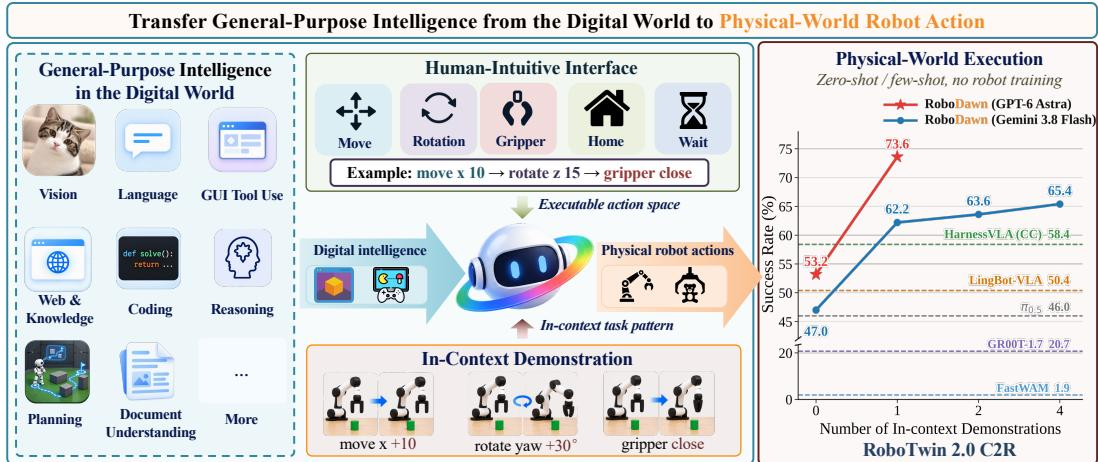
인간은 물리 세계와 디지털 세계 모두에 매끄럽게 적응할 수 있으며, 이는 구현(embodiment), 환경, 과업에서 디지털-실제 간극이 존재하더라도 인간의 지능 자체는 이 간극을 넘어 전이될 수 있음을 시사한다. 이는 자연스럽게 근본적인 질문을 제기한다: 시각-언어 모델(VLM)의 지능도 로봇 제어를 위해 디지털 세계에서 물리 세계로 유사하게 일반화될 수 있는가? 우리는 이 질문을 인간에게 직관적인 인터페이스인 RoboDawn을 통해 탐구한다. RoboDawn은 이산적인 병진(translation), 회전(rotation), 그리퍼(gripper) 명령의 간결한 집합을 통해 에이전트형(agentic) VLM에게 로봇 제어를 노출한다. 이 인터페이스를 사용하여 VLM은 로봇을 폐루프(closed loop)로 제어한다: 현재 시각 상태를 관찰하고, 다음 행동을 추론하며, 이를 실행하고, 결과 상태에 따라 후속 결정을 적응시킨다. 나아가 우리는 소수의 데모를 사용하여 VLM이 인터페이스 사용법과 과업 해결 전략 모두에 기반을 두도록 하는 인컨텍스트 학습(ICL) 기법을 도입한다. RoboTwin 2.0 C2R과 RoboDojo에서의 실험은 RoboDawn이 과업 특정 로봇 훈련 없이도 강력한 성능을 달성함을 보여준다. 제로샷 설정에서 RoboDawn은 벤치마크 특정 로봇 데이터로 훈련된 여러 강력한 정책을 능가하며, 단일 인컨텍스트 데모는 추가로 상당한 성능 향상을 가져와 최신(state-of-the-art, SOTA) 결과를 달성한다. RoboTwin 2.0 C2R에서 성공률은 제로샷 53.2%에서 원샷 73.6%로 증가하여 견고한 기준선인 π0.5(46.0%)를 넘어선다. RoboDojo에서도 유사한 향상이 관찰되며, 성공률은 제로샷 35.67%에서 원샷 47.17%로 개선된다. 동일한 프레임워크는 실제 로봇으로도 전이되어 Franka에서 블록 담기(block-in-basket)와 블록 쌓기(block stacking)를 수행한다.
One-sentence Summary
Researchers from Tsinghua University and Tencent Hunyuan propose RoboDawn, an interface that lets an agentic VLM perform closed-loop robotic control through discrete translation, rotation, and gripper commands with an in-context learning scheme, and on RoboTwin 2.0 C2R and RoboDojo it surpasses baselines, improving from 53.2% zero-shot to 73.6% one-shot, exceeding π0.5 (46.0%), and transferring to real Franka robots.
Key Contributions
- RoboDawn introduces a human-intuitive interface that exposes an agentic vision-language model to a compact set of discrete translation, rotation, and gripper commands for closed-loop robotic control without task-specific robot training.
- An in-context learning scheme uses a few demonstrations to ground the VLM in both interface usage and task-solving strategies, improving manipulation performance without parameter updates.
- On RoboTwin 2.0 C2R and RoboDojo, zero-shot RoboDawn outperforms several strong benchmark-specific trained policies. One demonstration raises success rates from 53.2% to 73.6% on RoboTwin 2.0 C2R and from 35.67% to 47.17% on RoboDojo, and the framework also transfers to real Franka robots for block-in-basket and block stacking.
Introduction
The authors study whether pretrained vision-language models can transfer their digital-world reasoning and perception capabilities directly to physical robot control, without robot-specific training. Prior approaches such as vision-language-action models and world-action models require large robot action datasets that are costly, embodiment-specific, and may degrade the model’s general reasoning abilities through overfitting. To address this, the authors introduce RoboDawn, a lightweight interface that exposes discrete motion primitives to a frozen agentic VLM and supports closed-loop manipulation through a few in-context demonstrations. Their experiments show that this zero-shot approach can outperform robot-trained policies and that even one demonstration substantially improves success rates across simulated and real-world tasks.
Dataset
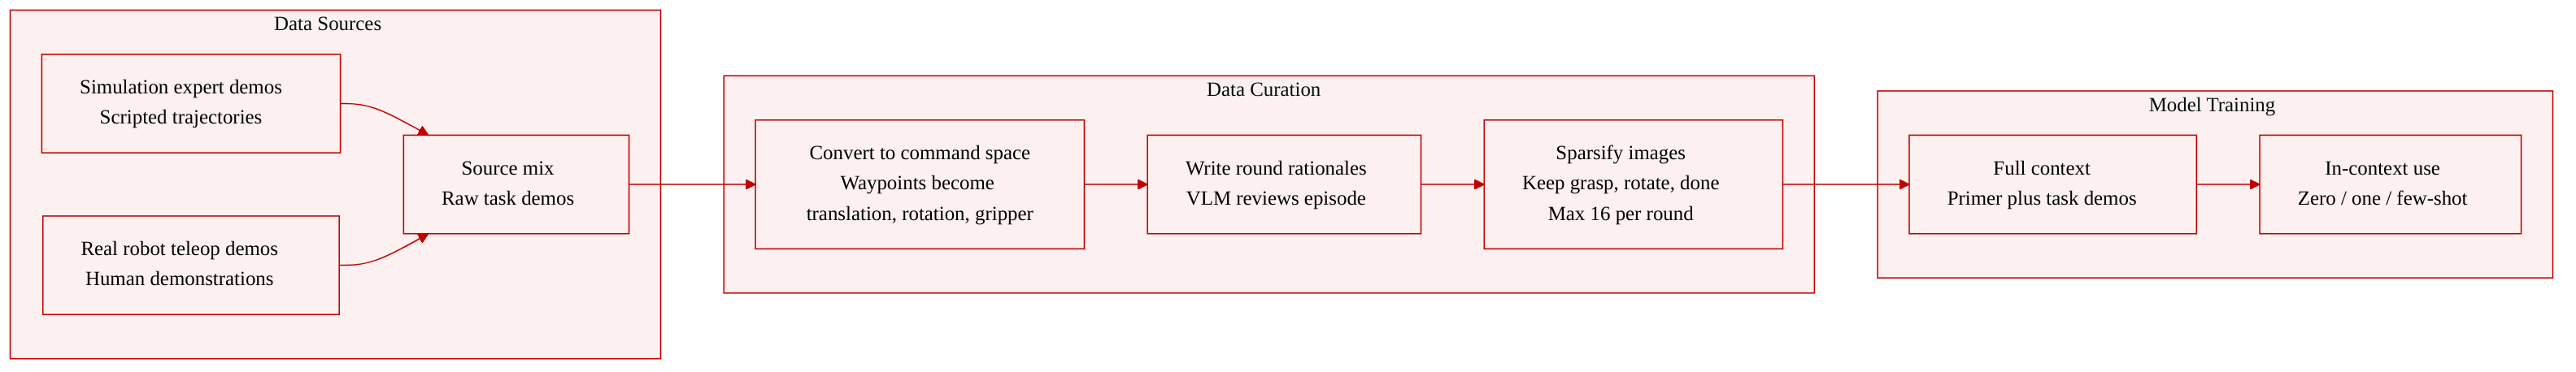
The authors construct an in-context demonstration dataset from two levels:
- Shared command primer: illustrates all basic command effects for the model.
- Task-level demonstrations: collected from scenes disjoint from evaluation, using scripted expert trajectories in simulation and human teleoperation on real robots. In simulation, these are the same trajectories used to train the robot policies used for comparison.
- Demonstration format: each task demonstration has Nm interaction rounds. Each round records the visual observation, robot state, issued commands, the physical effect of those commands, and a short rationale. The physical effect is derived from consecutive states as the change in GIP pose and gripper opening.
- Processing of raw trajectories: raw expert trajectories are converted into the semantic command space. A trajectory is first reduced to end-effector waypoints and gripper states, then each waypoint is expressed as a short sequence of translation, rotation, and gripper commands. Rationales are written afterward by a VLM that reviews the recorded episode with a task-agnostic prompt.
- Filtering and image sparsification: visual observations may be empty in some rounds while the full textual trajectory is retained. For long-horizon RoboDojo trajectories, the in-context image budget is set to 16 observations per round. If exceeded, images are kept only for semantically informative rounds such as grasping, rotation, and task completion, while visually redundant transition rounds are omitted.
- Usage in the model: the full context is D=Dprim⊕Dtask. Task-level demonstrations support zero-shot, one-shot, and few-shot settings through ND=0, ND=1, and ND>1. The primer shows primitive command effects, while task demonstrations show how primitives are composed into complete behaviors.
Method
The authors propose RoboDawn, a framework that leverages a pretrained Vision-Language Model (VLM) for closed-loop robotic manipulation without requiring task-specific parameter updates. The system conditions the VLM on a human-intuitive semantic action interface and in-context demonstrations to bridge multimodal reasoning and physical robot control.
As shown in the figure below:
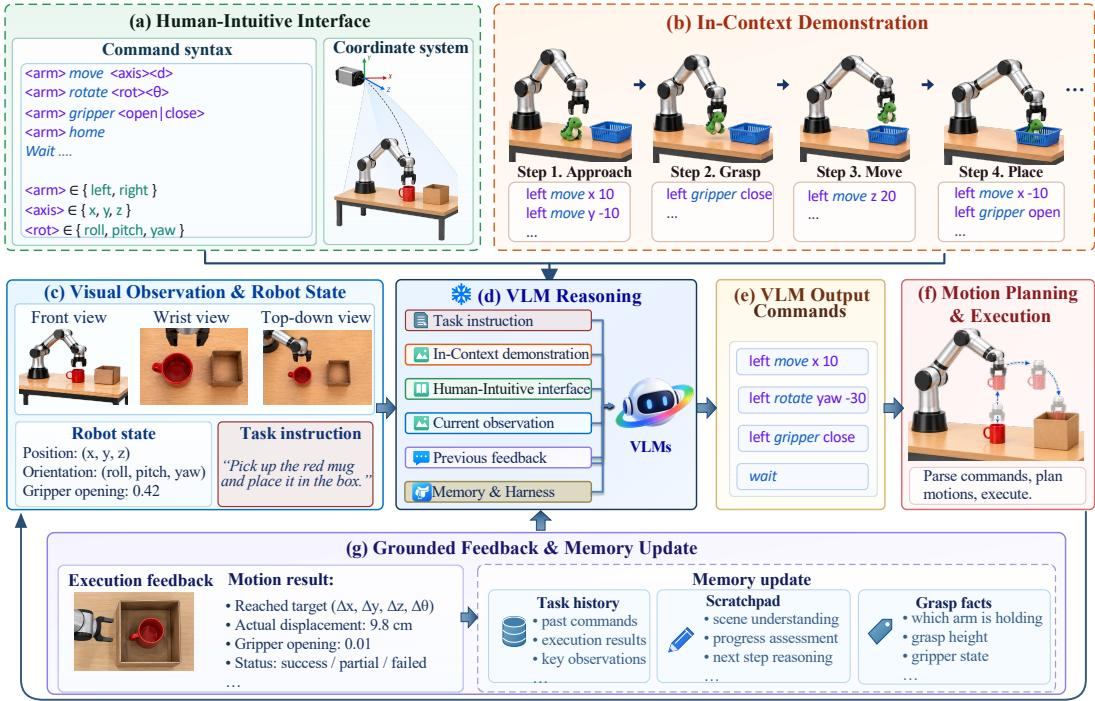
At each decision round t, the VLM receives annotated visual observations It, the measured robot state xt, execution feedback Ft−1 from previous rounds, and an interaction memory Mt. The model is additionally conditioned on two forms of fixed context throughout an episode: a robot-environment profile E and an in-context demonstration set D. The profile E describes interface conventions such as workspace constraints and gripper properties, while D provides examples of how to interact with the environment. The closed-loop interaction is formalized as:
(yt,at)(st+1,Ft)(It+1,xt+1)Mt+1=πθ(L,E,D;It,xt,Ft−1,Mt),=EP(st,at),=OP(st+1),=U(Mt,at,yt,Ft,xt+1).Here, πθ denotes the pretrained VLM with frozen parameters. It outputs a sequence of semantic action commands at alongside a structured response yt, which contains task progress estimates, the current plan, and a compact scratchpad. The execution operator EP parses these commands, grounds them into robot motions, and converts the physical outcome into feedback Ft. The observation operator OP constructs the next visual and proprioceptive observation, and U updates the interaction memory. The environment state st formalizes physical transitions but is not directly exposed to the VLM, ensuring online control does not rely on privileged object poses.
To facilitate this interaction, the authors design a human-intuitive interface centered around the gripper interaction point (GIP), defined as the midpoint between the two fingertips. This GIP is used consistently for visual annotations, state reporting, and motion commands. Instead of predicting joint-level actions or high-frequency continuous controls, the VLM interacts through a compact vocabulary of parameterized semantic commands:
A={<arm> move <axis> <d>,<arm> rotate <rot> <\theta>,<arm> point <pose>,<arm> gripper <g>,<arm> home, wait, done}.In this grammar, translation and rotation axes refer to the world frame, and all spatial commands specify incremental changes to the GIP pose. Translation and rotation magnitudes are clipped to 20 cm and 90 degrees per command, respectively. Each semantic motion command is translated into a complete planned motion to a target GIP pose and executed until the robot reaches a stationary state, abstracting away low-level trajectory generation.
To further resolve ambiguities in action semantics and granularity, the authors implement an in-context learning design. The demonstration context is decomposed into D=Dprim⊕Dtask, where Dprim is a shared command primer illustrating basic command effects, and Dtask contains task-level demonstrations. This formulation supports zero-shot, one-shot, and few-shot settings by varying the number of task examples. Raw expert trajectories are converted into the semantic command space by reducing them to end-effector waypoints and generating corresponding translation, rotation, and gripper commands. Each complete demonstration consists of Nm interaction rounds:
D(m)={(Ij(m),xj(m),rj(m),aj(m),fj(m))}j=1Nmwhere Ij(m) is the visual observation, xj(m) the robot state, aj(m) the issued commands, fj(m) the physical effect derived from consecutive states, and rj(m) a short rationale generated by a VLM. To manage the in-context image budget, visually redundant transition rounds are omitted, retaining images only for semantically informative steps such as grasping or task completion.
Experiment
RoboDawn is evaluated in the RoboTwin 2.0 and RoboDojo simulation benchmarks and on real robots to test zero-shot and few-shot manipulation without task-specific parameter updates. In simulation, it matches or exceeds robot-trained and agentic baselines, with ablations showing that reasoning, spatial grounding, stronger vision-language models, and more demonstrations improve performance, while additional test-time commands further boost success. Real-world deployment transfers to block manipulation tasks but struggles with cloth folding due to precise orientation demands, and failure analysis highlights limited fine-grained control, IK-related execution errors, and incorrect success judgment.
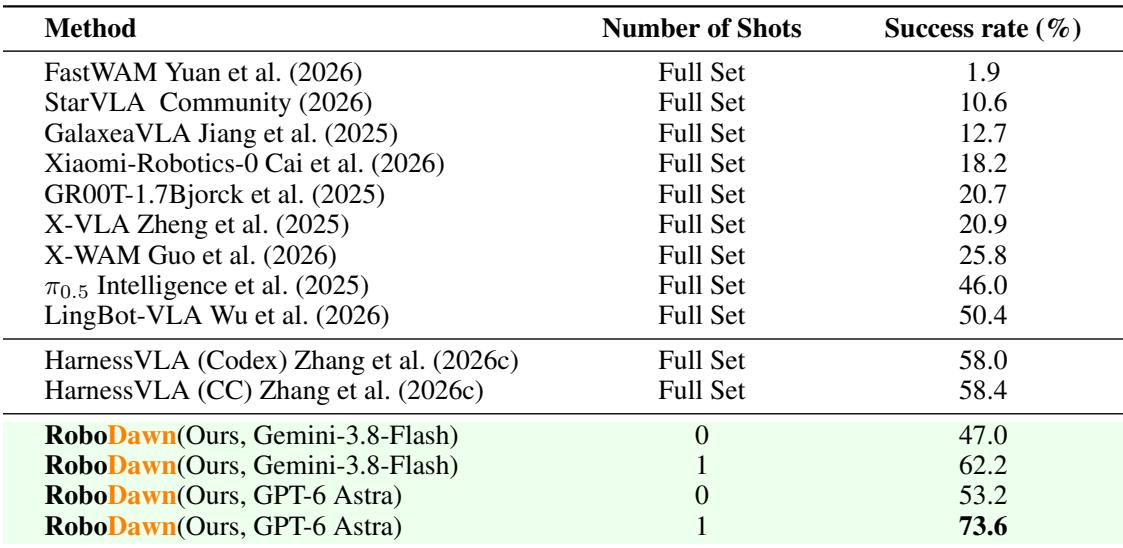
On RoboTwin 2.0 C2R, many robot-trained baselines post-trained on full demonstration sets achieve only modest success under domain randomization, while RoboDawn performs control without task-specific parameter updates. In zero-shot mode, RoboDawn outperforms several strong robot policies, and adding a single in-context demonstration raises its success by a large margin, exceeding an agentic VLA baseline. This suggests pretrained vision-language models can transfer general-purpose reasoning into bimanual manipulation through a lightweight action interface. Full-set post-trained robot policies often show limited clean-to-randomized generalization compared with in-context VLM control. RoboDawn in zero-shot mode already surpasses strong robot policies such as π0.5 and LingBot-VLA despite no task-specific training. A single in-context demonstration yields a large success gain and places RoboDawn clearly above the compared agentic VLA method. The results indicate that pretrained reasoning can substitute for task-specific demonstration training when paired with a lightweight action interface.
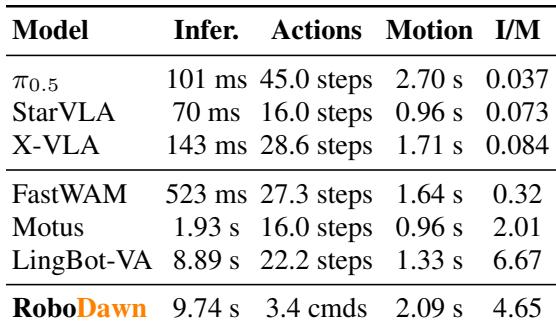
RoboDawn has the highest inference latency in the comparison but issues far fewer actions per episode than the VLA baselines, while its motion execution time remains comparable. Policies such as π0.5, StarVLA, X-VLA, and FastWAM maintain low inference-to-motion ratios below 0.5, indicating potential for overlapping reasoning with motion. RoboDawn and LingBot-VA show ratios well above that threshold, reflecting a different efficiency tradeoff. RoboDawn incurs longer inference latency than all compared policies, but produces only a few high-level commands per episode instead of many low-level steps. Its motion execution time is similar to that of several baselines, so the added latency comes primarily from model inference rather than physical execution. Several evaluated policies have inference-to-motion ratios under 0.5, suggesting their inference can be overlapped with robot motion for streaming execution. RoboDawn and LingBot-VA exceed the 0.5 inference-to-motion threshold by a large margin, indicating limited overlap between inference and motion.
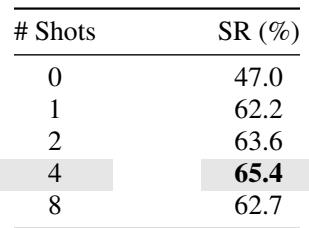
The RoboDawn ablation on RoboTwin 2.0 shows that providing a small number of in-context demonstrations improves task success, with the largest gain moving from zero-shot to one-shot. Further demonstrations beyond one produce diminishing returns, and performance slightly declines at eight demonstrations, suggesting long context can interfere. The choice of VLM also has a strong effect on success rate. With the Gemini-3.8-Flash model, success rises from 47.0 percent zero-shot to 62.2 percent with one demonstration, then to 65.4 percent with four demonstrations before falling to 62.7 percent with eight. Under the one-shot setting, success varies widely by VLM strength, improving from 14.4 percent with a weaker VLM to 43.2 percent with a stronger one.
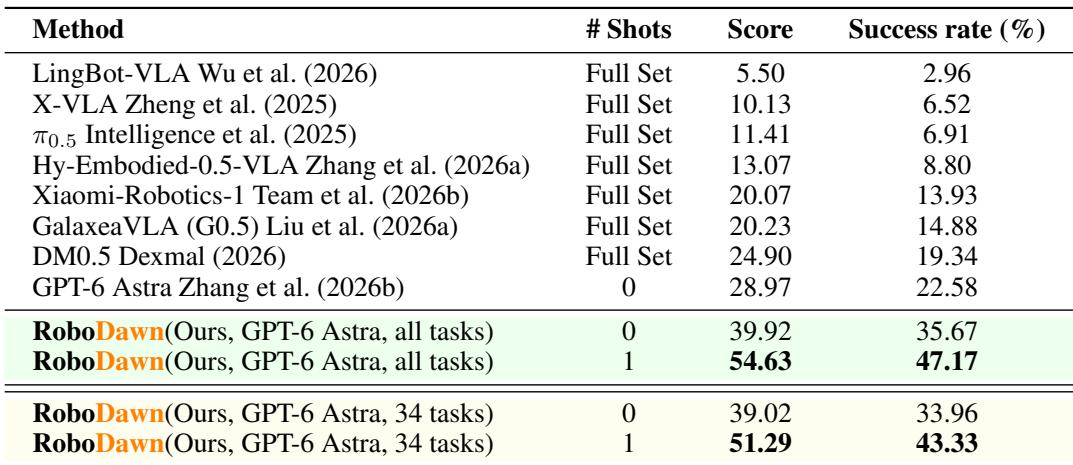
On RoboDojo, RoboDawn attains stronger task success than full-set post-trained baselines without task-specific post-training. Its success rate reaches 35.67% zero-shot and 47.17% with a single demonstration, compared with 19.34% for the best listed full-set method. RoboDawn also shows consistent test-time scaling, improving as the command budget increases. RoboDawn's zero-shot and one-shot success rates exceed every reported full-set post-trained baseline. A single demonstration yields a large improvement over RoboDawn's zero-shot performance. Increasing the test-time command budget improves RoboDawn's success in both zero-shot and one-shot settings.
RoboDawn with Gemini 3.8 Flash was evaluated zero-shot on real robots across three manipulation tasks. It performed best on block-in-basket, moderately on block stacking, and did not succeed on cloth folding. The paper attributes the lower block stacking performance to precision and spatial alignment demands, and cloth folding difficulty to substantial end-effector rotation and orientation adjustment. Block-in-basket achieved the highest real-world success rate, followed by block stacking. Cloth folding recorded no successful trials and was considered considerably more challenging due to frequent end-effector rotation and orientation adjustment.

The paper evaluates RoboDawn on RoboTwin 2.0 C2R and RoboDojo simulations and on real robots. It shows that zero-shot and one-shot VLM control can outperform full-set post-trained robot policies without task-specific parameter updates, with a single in-context demonstration providing the largest gain and additional examples yielding diminishing returns. Efficiency tests indicate longer inference latency but far fewer high-level actions per episode than VLA baselines, with limited overlap between inference and motion. Real-robot results are strongest on block-in-basket, moderate on block stacking, and unsuccessful on cloth folding due to precision and orientation demands.