Command Palette
Search for a command to run...
RECREATIONWORLD: 하이브리드 컴퓨터 사용 에이전트를 위한 확장 가능하고 검증 가능한 환경
RECREATIONWORLD: 하이브리드 컴퓨터 사용 에이전트를 위한 확장 가능하고 검증 가능한 환경
초록
컴퓨터 사용 에이전트(CUA)는 그래픽 인터페이스를 통한 애플리케이션 조작과 코드 및 명령줄을 통한 소프트웨어 구축이라는 대체로 분리된 두 갈래로 발전해 왔으며, 각각은 상대가 가장 잘하는 것을 보지 못한다. GUI 에이전트는 인터페이스 이면의 소프트웨어를 구축할 수 없고, 터미널 에이전트는 자신의 행동이 만들어내는 인터페이스를 볼 수 없다. 실제 디지털 작업은 둘을 동시에 요구하며, 단순히 끝에서 끝으로 쌓는 방식보다는 교차적으로 수행되어야 한다. 우리는 이 둘을 융합한 하이브리드 CUA를 연구한다. 즉, 언제 인터페이스를 탐색하고, 언제 구현하며, 언제 자신이 만든 산출물을 실행하고 시각적으로 검증할지 자율적으로 결정하는 에이전트이다. 이러한 능력을 구축하려면 통제된 조건에서 이를 평가하면서도 대규모로 검증된 경험을 생성하는 환경이 필요하다. 우리는 재구현(recreation)을 중심으로 구축된 5개 플랫폼 프레임워크인 RECREATIONWORLD를 소개한다. 실행 중인 참조(reference)가 주어지면 에이전트는 정해진 작업 절차 없이 그 동작을 탐색하고 충실한 구현을 구축해야 한다. 이 프레임워크에서 재구현은 하이브리드 루프를 가장 순수한 형태로 구현하며, 실행에 기반한 객관적 보상을 제공한다. 실행 중인 참조가 숨겨진 행동 테스트를 도출할 수 있는 오라클 역할을 하기 때문이다. 이 루프를 여러 플랫폼에서 실행하기 위해 RECREATIONWORLD는 Ubuntu, macOS, Windows, Android, Web에서 재현 가능한 환경과 네이티브 GUI 제어 및 코딩 도구를 갖춘 통합 하네스를 제공한다. 나아가 고품질 오픈소스 애플리케이션을 활용해 규모를 확장하고, 이를 사용하여 훈련용 장기 재구현 궤적을 생성한다. 이 궤적으로 훈련된 모델은 코딩과 하이브리드 컴퓨터 사용을 아우르는 5개의 분포 외 벤치마크에서 성능이 향상되고, 자신이 렌더링한 출력을 더 자주 검증한다. 이는 재구현이 재구현을 넘어 전이되고 자기 개선을 지원하는 하이브리드 에이전트 능력을 구축한다는 증거이다. 홀드아웃 평가를 위해 다양한 도메인과 플랫폼에 걸친 250개의 다양한 과제로 구성된 RECREATIONBENCH를 소개한다. 평가 계층에서는 참조 기반 테스트 생성이 실행 가능한 동작을 구현에 구애받지 않는 감독 신호로 변환한다. 프로그램적 및 시각적 단언(assertion)은 여러 상호작용 깊이에서 행동 조건부 결과를 포괄하며, 각 단언은 자동 채점을 위해 스위트가 고정되기 전에 참조와 인간 검토자에 의해 검증된다. RECREATIONBENCH에서 GPT-6 Astra가 전체 58.1%로 선두를 차지하지만, 모든 프로그램적 테스트를 통과한 과제는 2.8%에 불과하다. 우리의 분석에 따르면 에이전트는 상호작용 및 계산된 출력보다 정적 인터페이스 구조를 더 안정적으로 재현하며, 생성된 애플리케이션은 참조보다 상당히 작고 더 단일체적인 경향을 보인다. 벤치마크, 환경, 테스트 스위트를 공개한다.
One-sentence Summary
Researchers from Alibaba Token Hub, Alibaba Group, introduce RECREATIONWORLD, a five-platform framework for hybrid computer-use agents that interleave GUI exploration, coding, and visual verification by building faithful implementations of running references and providing execution-grounded rewards across Ubuntu, macOS, Windows, Android, and Web; on its RECREATIONBENCH, GPT-6 Astra reaches 58.1% overall.
Key Contributions
- The paper introduces RECREATION-WORLD, a five-platform framework for hybrid computer-use agents that interleave GUI exploration, implementation, execution, and verification while recreating a running reference application with no prescribed workflow. It provides reproducible environments on Ubuntu, macOS, Windows, Android, and Web, along with a unified harness for native GUI control and coding tools.
- The paper contributes RECREATIONBENCH, a held-out benchmark of 250 tasks across those platforms, with reference-grounded programmatic and visual assertions that convert executable behavior into implementation-agnostic supervision. The test suites are validated against the reference and by human reviewers before being frozen for automatic scoring, and the benchmark, environments, and test suites are released.
- Experiments show that training on long-horizon recreation trajectories generated from open-source applications improves performance across five out-of-distribution coding and hybrid computer-use benchmarks by up to 17.9 percentage points and increases self-verification of rendered outputs. On RECREATIONBENCH, GPT-6 Astra reaches 58.1% overall but passes all programmatic tests on only 2.8% of tasks, with static interface structure reproduced more reliably than interactions and computed outputs.
Introduction
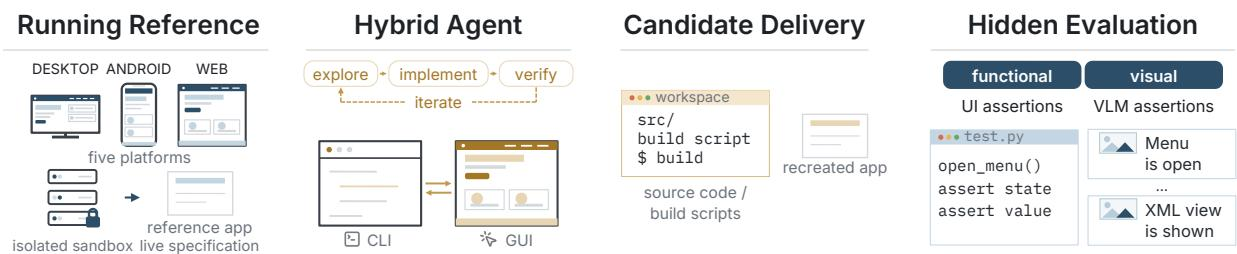
General-purpose computer-use agents have largely split into GUI-only agents that perceive screens and issue clicks, and terminal-based agents that write code and invoke tools. Each approach misses the other’s strengths, yet many software-intensive tasks require repeatedly interleaving interface exploration, implementation, execution, and visual verification. Existing benchmarks tend to emphasize one interaction mode, so they under-measure an agent’s long-horizon ability to coordinate this hybrid loop. The authors introduce RECREATIONWORLD and RECREATIONBENCH, a multi-platform framework in which agents must discover a running reference application’s behavior and construct a faithful implementation. Reference-grounded programmatic and visual tests provide execution-based scoring, and selected recreation trajectories are used for training, with reported transfer gains on out-of-distribution coding and hybrid computer-use benchmarks.
Dataset
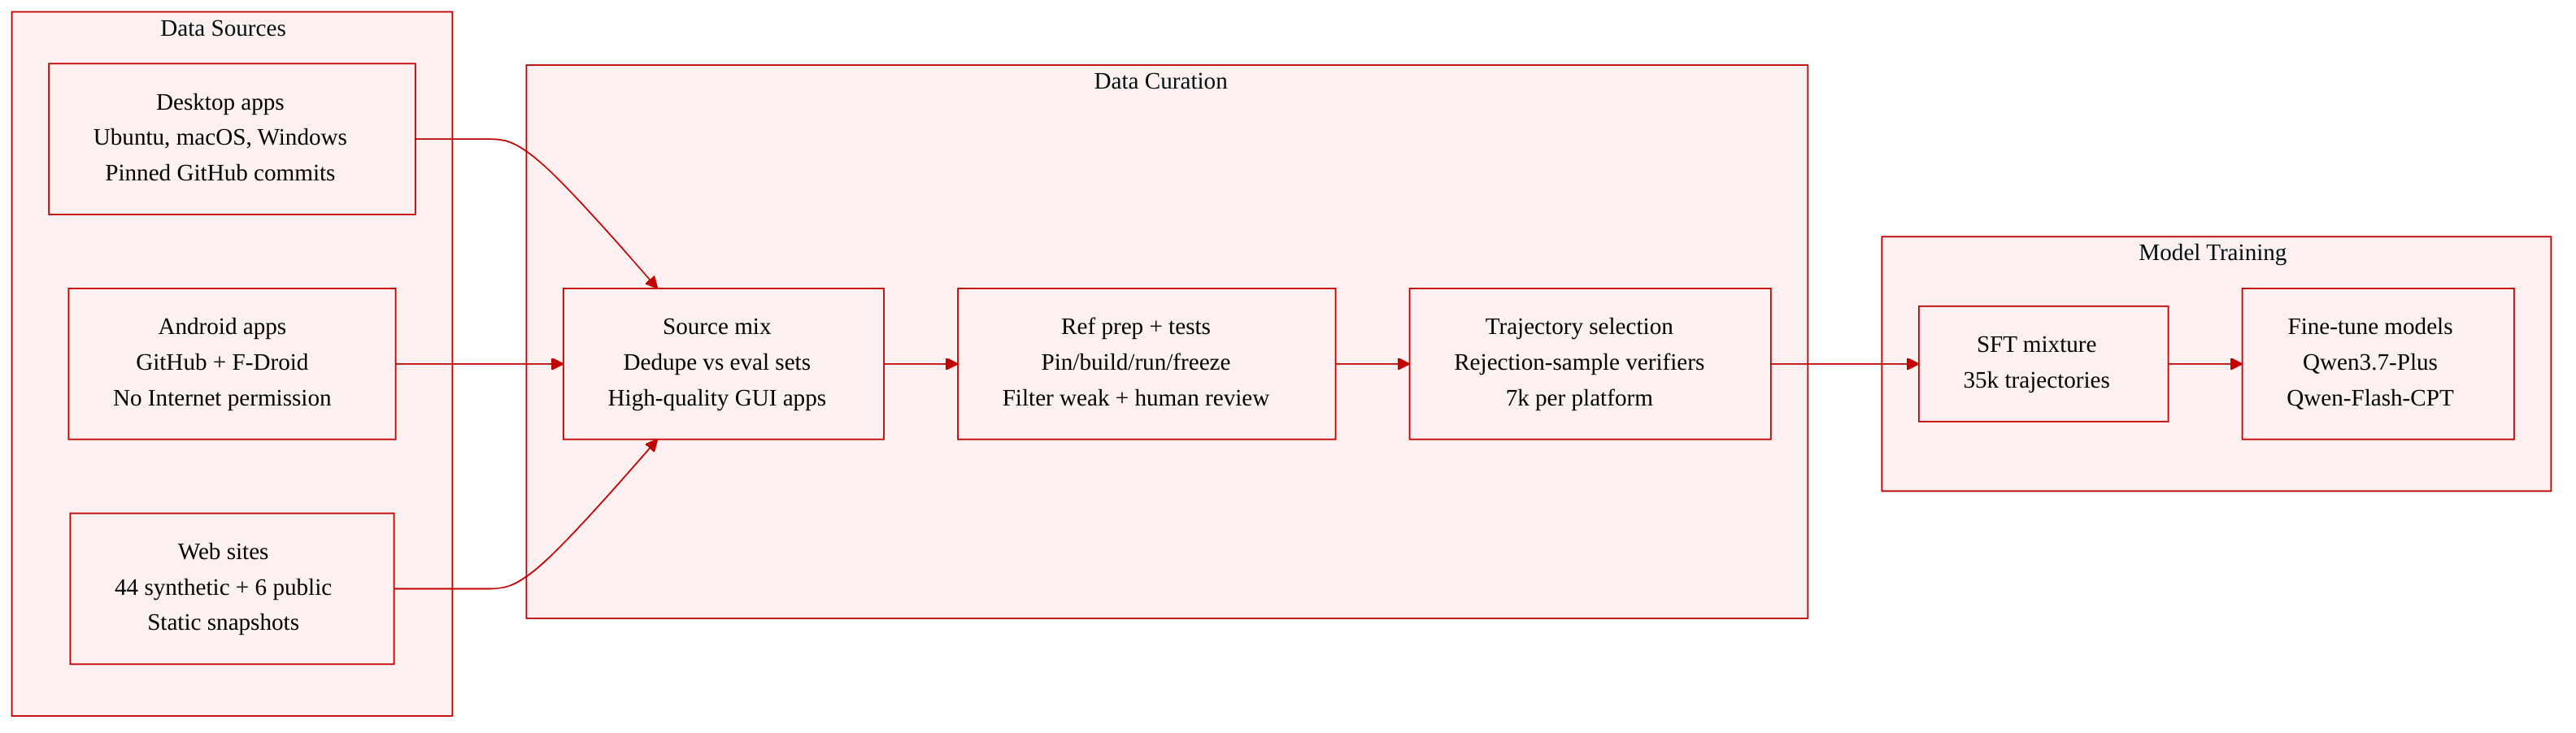
The authors use two data resources: RECREATIONBENCH for evaluation and a 35,000-trajectory recreation mixture for supervised fine-tuning.
Sources and composition
- RECREATIONBENCH contains 250 tasks, with 50 applications or websites for each of five platforms: Ubuntu, macOS, Windows, Android, and Web.
- Candidates come from open-source desktop repositories, Android projects on GitHub or F-Droid, and openly licensed or benchmark-authored websites.
- Web consists of 44 synthetic sites and 6 sites derived from public websites.
- Desktop and Android are source-blind: the agent sees only the executable reference while the implementation is withheld. Web cannot be fully source-blind because the served client code is visible; the protected materials are the captured ground truth and generated test suite.
- Desktop rosters record upstream repository and revision. Application selection balances domains, frameworks, source size, feature complexity, and upstream activity. Ubuntu mixes Qt, GTK, and web-wrapped apps; macOS is dominated by AppKit and SwiftUI; Windows leans toward .NET and JVM stacks with a Qt cohort; Android mixes Kotlin/Java apps and XML/Compose interfaces with a median of 15.0k LOC.
Training data construction
- Training tasks are high-quality open-source GUI applications from GitHub across the same five platform families, deduplicated against evaluation sets.
- Qwen3.8-Max generates recreation trajectories through the RECREATION-WORLD framework: agents explore the running reference, implement a candidate, and build, run, inspect, and refine it using execution feedback.
- Rollouts run concurrently on isolated workers and their interaction histories are recorded.
- Rejection sampling with task-specific behavioral verifiers selects high-scoring trajectories.
- The final mixture takes 7,000 selected trajectories from each platform, producing a balanced 35,000-trajectory SFT mixture. The balance is by trajectory count; trajectory lengths and token contributions may differ across platforms.
Reference freezing and filtering
- Desktop references are pinned to upstream commits, built, and exercised in a graphical session.
- Android references are built and installed in an emulator, with incidental first-run interruptions removed.
- Web references are frozen as static snapshots, with pages discovered and reviewed before the scored page set is fixed.
- Authors exclude libraries, frameworks, host-program extensions, and applications whose core functionality depends on a login or remote service. Android additionally selects applications without the Internet permission.
- References that fail to launch, render incompletely, or lack meaningful interaction are rejected.
Test suite and metadata
- Behavioral tests are built from source or page analysis combined with exploration of the running reference. Each case specifies any fixture or initial state, an interaction sequence, and programmatic assertions, visual assertions, or both.
- Proposed cases are replayed against a clean reference; invalid or unstable checks are discarded, followed by human review before freezing.
- In the frozen suites, 81 tasks package 393 files in fixture trees. Web snapshots are stored separately and have no explicit testcase fixture bundle.
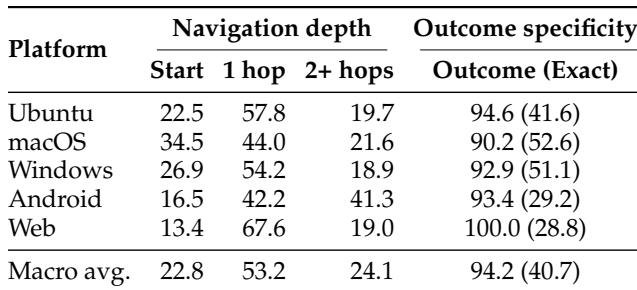
- The frozen suites are audited for navigation and outcome specificity. Averaged equally across platforms, about 77% of cases leave the start surface, 24% traverse two or more surfaces, 94.2% check an interaction outcome, and 40.7% require an exact expected result.
Use in model
- The 35,000-trajectory mixture is used for supervised fine-tuning of two model initializations: Qwen3.7-Plus and Qwen-Flash-CPT.
- RECREATIONBENCH is the evaluation resource. During web evaluation, the delivered page must not load the reference at evaluation time, both desktop and mobile viewports are scored, and multi-page tasks preserve original path-based URLs rather than hash routing.
Method
The authors formulate application recreation as a task where an agent constructs a runnable application from an executable reference. The agent receives a high-level prompt, interactive access to the reference application, and a prepared environment containing GUI control and software-development tools. The interaction follows a recurring explore-implement-verify loop: the agent observes the reference to update a partial behavioral specification, writes code to implement a candidate, and visually or behaviorally checks the running candidate against the reference. This process reverses the usual direction of coding tasks, requiring the agent to recover specifications by forming hypotheses about hidden behavior.
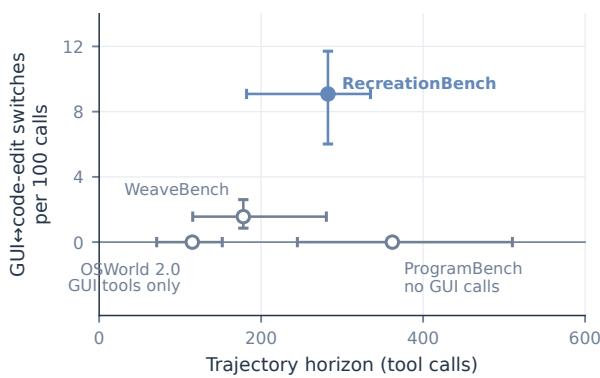
This feedback loop naturally leads to long-horizon interactions. As shown in the figure above, RECREATIONBENCH trajectories exhibit a high median of top-level calls and frequent transitions between GUI operations and code edits, significantly exceeding the switching rates of benchmarks like WeaveBench. To support these extended rollouts, the authors design a scalable execution infrastructure. Each rollout receives a versioned, task-isolated worker that pins its graphical runtime and build toolchains. These workers are scheduled across a horizontally scalable virtual-machine pool, preserving workspace and state across cycles, with a per-rollout wall-clock timeout of 20 hours.
The framework also includes a systematic pipeline for constructing reference-grounded tasks and hidden behavioral test suites.
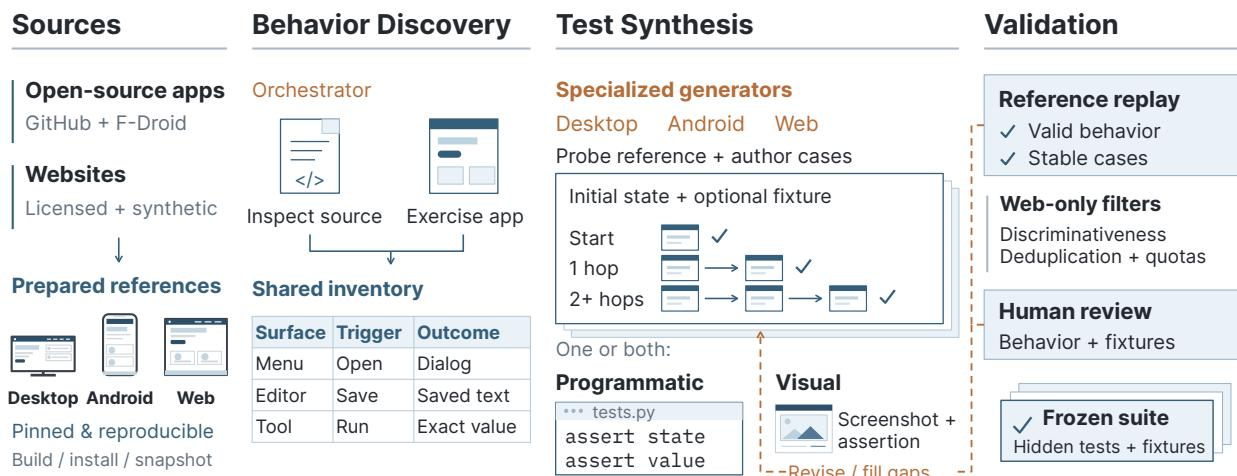
As illustrated in the framework diagram, the construction process begins with sources such as open-source desktop repositories, Android projects, and websites. These are prepared into reproducible references. An orchestrator then performs behavior discovery by inspecting the source and exercising the running reference to build a shared inventory of features, reachable surfaces, and observable responses. Specialized generators for Desktop, Android, and Web platforms use this inventory to author test cases. Each case specifies an initial state, optional fixtures, an interaction sequence, and assertions. These assertions can be programmatic, checking exact values via automation interfaces, or visual, relying on screenshot comparisons. The proposed cases undergo validation through reference replay to discard unstable checks, followed by platform-specific filters and human review, before the suite is frozen for evaluation.
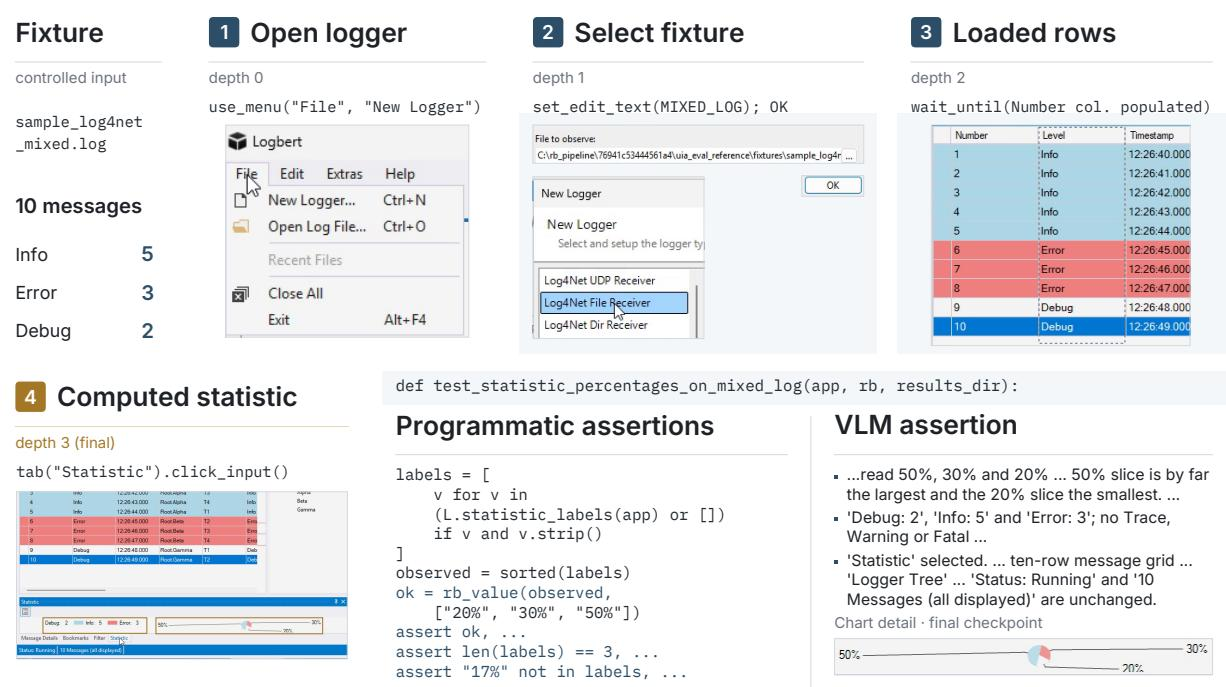
The figure above details a generated Windows test case for the Logbert application. It demonstrates the progression from loading a fixed log fixture and selecting a receiver to computing statistics. The evaluation contract includes both programmatic assertions, which verify exact UI Automation values and state, and VLM assertions, which check the rendered visual output against natural-language descriptions.
For the training setup, the authors source tasks from high-quality open-source GUI applications across five platform families. They use Qwen3.8-Max to generate recreation trajectories through the agentic framework, where agents explore references, implement candidates, and refine them using execution feedback. The framework runs these rollouts concurrently on isolated workers. The authors apply rejection sampling using task-specific behavioral verifiers to select high-scoring trajectories. They collect 7,000 selected trajectories from each platform to create a balanced 35,000-trajectory SFT mixture. Finally, they fine-tune two model initializations, Qwen3.7-Plus and a continually pre-trained Qwen-Flash checkpoint, on this mixture.
Experiment
The experiments evaluate recreation-trained coding agents on RECREATIONBENCH, a 250-task suite spanning five platforms, and on five external coding and computer-use benchmarks, using isolated clean-room evaluation with separate programmatic and visual scoring. Recreation supervision transfers to out-of-distribution benchmarks and shifts agent behavior toward more verification, GUI observation, and interaction, while GPT-6 Astra leads overall but full programmatic reconstruction remains rare. Analyses show that broader reference exploration and higher GUI-call shares coincide with stronger results, yet agents reproduce static interface structure better than action-dependent behavior, produce smaller and more concentrated artifacts with frequent toolkit substitutions, and often skip a final edit-relaunch-inspection loop. A programmable interaction runtime further reduces tool calls, context, wall-clock time, and estimated cost without materially changing observed task quality.
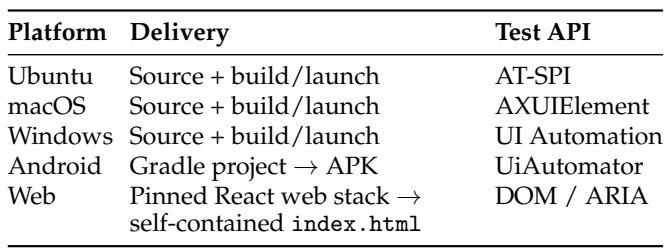
A single observe-build-evaluate contract is applied across five platforms with native delivery and test interfaces. Desktop and Android use a source-blind setting while web exposes its served client implementation. Visual assertions supplement the platform-specific programmatic APIs on every platform. Desktop delivery uses source plus build/launch, with accessibility-oriented test APIs: AT-SPI on Ubuntu, AXUIElement on macOS, and UI Automation on Windows. Android delivers a Gradle project to APK and tests through UiAutomator, while web uses a pinned React web stack to a self-contained index.html with DOM/ARIA.
The frozen test suites are dominated by one-hop navigation cases, while start and two-plus-hop cases are less common on average. Android differs most, with two-plus-hop cases nearly as frequent as one-hop cases. Outcome specificity is high throughout, but exact outcome rates are more moderate and vary by platform, led by macOS and Windows. One-hop navigation is the most common case type across platforms, with the highest share on Web. Android has a nearly even split between one-hop and two-plus-hop navigation and relatively few start cases. macOS has the highest share of start cases among the five platforms. Outcome specificity is consistently high across platforms, with Web reaching the highest observed rate. Exact outcome specification is more variable, with macOS and Windows higher than Android and Web.
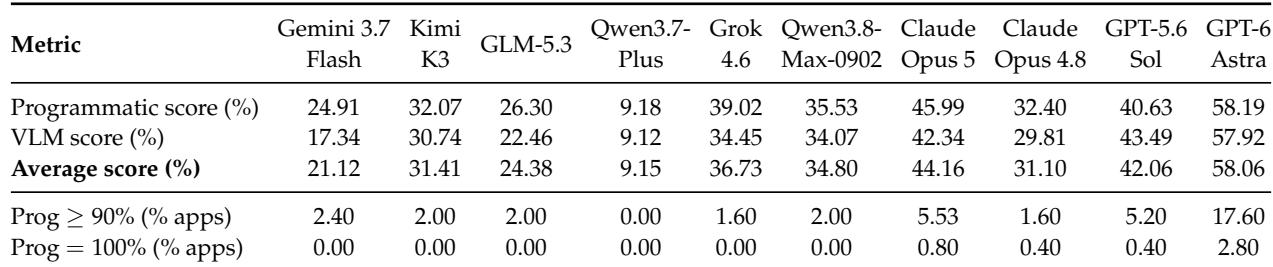
GPT-6 Astra leads overall performance, followed by Claude Opus 5 and GPT-5.6 Sol. Full programmatic suite passes remain rare, and aggregate programmatic scores conceal limited high-threshold coverage. Recreations are stronger at reproducing static interface structure and content than at action-dependent state changes or computed outputs. GPT-6 Astra records the highest average, programmatic, and VLM scores, and is the only model with full-suite passes on multiple platforms. Static structure and content pass rates exceed interaction, computation, and button behavior across most model-platform comparisons, with gaps up to 34.4 points on native platforms and up to 36.7 points on web.
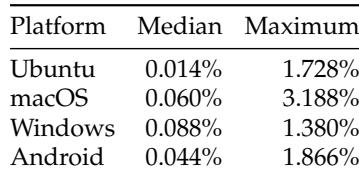
Noise-filtered exact-line overlap between recreated implementations and reference source is consistently low across all four platforms. Median overlap ranges from 0.014% on Ubuntu to 0.088% on Windows, with every platform maximum remaining below 3.2%. These results indicate the delivered source is overwhelmingly textually distinct from references rather than large verbatim copies. Windows has the highest median overlap among the four platforms, while Ubuntu has the lowest. All platform maxima remain below 3.2%, with macOS reaching the largest maximum overlap.
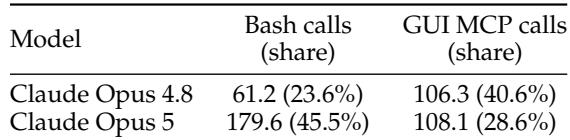
Claude Opus 5 shifts tool use toward Bash relative to Claude Opus 4.8 across weighted platform means. It makes substantially more Bash calls and devotes a much larger share of its tool calls to Bash, while its share of dedicated GUI tool calls is lower. Case-level evidence indicates shell calls can bundle many GUI exploration and verification actions, so dedicated GUI call counts may understate GUI work. Claude Opus 5 makes nearly three times as many Bash calls on average while its GUI MCP call share falls compared with Claude Opus 4.8. Both models have relatively similar mean GUI MCP call counts, but Claude Opus 5 allocates almost twice the share of tool calls to Bash. In an Ubuntu TeXworks case, Claude Opus 5 batches menu captures and reuses shell scripts for verification, whereas Claude Opus 4.8 relies more on separate desktop-control calls.
The experiments evaluate multimodal agents across five platforms with a shared observe-build-evaluate contract, native delivery and test interfaces, and visual assertions, covering desktop, Android, and web settings. They show that one-hop navigation and high outcome specificity dominate the benchmark, while full programmatic suite passes remain rare, and models reproduce static interface structure and content more reliably than action-dependent state changes or computed outputs. Source overlap analysis indicates that recreated implementations are textually distinct from reference code rather than copied, and tool-use comparisons suggest newer models increasingly rely on bundled shell commands for GUI exploration and verification.