Command Palette
Search for a command to run...
IntBMoE: 완전 참여형 Mixture-of-Experts를 위한 전문가 합성에 블록 수준 조건화 통합
IntBMoE: 완전 참여형 Mixture-of-Experts를 위한 전문가 합성에 블록 수준 조건화 통합
Ran Cheng Longfei Xu Zheng Liu Kaikui Liu Xiangxiang Chu
초록
Mixture-of-Experts(MoE)는 모델 용량을 확장하지만, 기존 설계는 세 가지 양을 독립적으로 설정하지 못한다. 단일 토큰에 대해 participation(참여)은 출력에 지식을 기여하는 전문가의 수, execution(실행)은 실제로 계산되는 전문가의 수(연산 비용), materialization(구체화)은 구축·저장해야 하는 전문가 크기의 파라미터 집합 수(메모리 비용)를 의미한다. 희소 라우팅은 execution과 materialization을 낮게 유지하지만 participation을 줄여 토큰마다 소수의 전문가만 기여하게 한다. 밀집 출력 혼합(dense output-mixing)은 완전한 participation을 복원하지만 execution이 전문가 수에 따라 증가한다. 파라미터 병합(parameter-merging)은 execution을 전문가 하나 수준으로 유지하지만 materialization이 라우팅 결정 수에 따라 증가한다. 우리는 밀집 전문가 합성(dense expert composition)과 희소 블록 실행(sparse block execution)을 결합하여 세 가지를 분리하는 블록 조건화 MoE인 IntBMoE를 제안한다. 블록은 학습된 작은 코드북에서 얻으며, 코드북 항목마다 하나씩 존재한다. 각 내부 계층에서 경량 하이퍼네트워크가 해당 계층 풀의 모든 전문가 베이스를 하나의 합성 전문가로 병합한다. 모든 합성 전문가가 전체 풀을 활용하므로 participation은 완전하다. 라우터가 각 토큰을 소수의 블록에만 보내므로 execution은 희소하게 유지된다. 입력이 아니라 코드북이 블록 수를 고정하므로 materialization은 제한된다. Dual-Path Residual Gating(DPRG)은 곱셈적 게이팅을 통해 독립적으로 합성된 두 경로를 추가로 결합한다. 이미지 분류 실험은 대표적인 sparse 및 dense MoE 베이스라인 대비 일관된 성능 향상을 보여준다. 언어 모델링과 순차 추천에 대한 추가 실험은 비전 너머의 일반화를 검증한다. IntBMoE는 AMap의 생성형 추천 시스템에 완전히 배포되어 60ms 지연 시간 예산 하에 수억 명의 사용자에게 서비스되고 있으며, 온라인 A/B 테스트에서 2.4%의 상대적 UVCTR 상승을 달성했다. 코드는 https://github.com/AMAP-ML/DreamX-Rec/에서 이용할 수 있다.
One-sentence Summary
Researchers from DreamX, Alibaba Group propose IntBMoE, a block-conditioned Mixture-of-Experts that decouples participation, execution, and materialization by pairing dense expert composition with sparse block execution through a learned codebook and Dual-Path Residual Gating, achieving gains in image classification, language modeling, and sequential recommendation, along with a 2.4% relative UVCTR lift in AMap’s deployed generative recommendation system under a 60 ms latency budget.
Key Contributions
- IntBMoE is a block-conditioned mixture-of-experts architecture that decouples expert participation, execution, and materialization by pairing dense expert composition with sparse block execution. Its blocks come from a small learned codebook, so participation is full, execution stays sparse, and materialization is bounded by the codebook size.
- Within each block, Dual-Path Residual Gating (DPRG) couples two independently composed paths through residual multiplicative gating, combining separate value and gate pathways.
- On ImageNet-1K, IntBMoE shows consistent gains over representative sparse and dense MoE baselines, and additional experiments on MiniPile and IntTravel validate generalization to language modeling and sequential recommendation. It is deployed in AMap’s generative recommendation system, serving hundreds of millions of users under a 60 ms latency budget with a 2.4% relative UVCTR gain in online A/B testing.
Introduction
Mixture-of-Experts (MoE) architectures are widely used in language, vision, multimodal, and recommendation models because they scale model capacity while controlling computation. Prior MoE designs, however, couple expert participation, execution, and materialization: sparse routing activates few experts but limits each token to selected experts; dense output mixing lets all experts contribute but requires computing every expert; parameter merging achieves full participation but creates many expert-sized parameter sets at runtime. The authors introduce IntBMoE, a block-conditioned MoE that separates reusable block construction from token-level execution. A finite codebook and shared hypernetwork compose a bounded set of reusable blocks from the full expert pool, while a router executes only a few blocks per token, achieving pool-wide expert participation, sparse execution, and bounded parameter materialization.
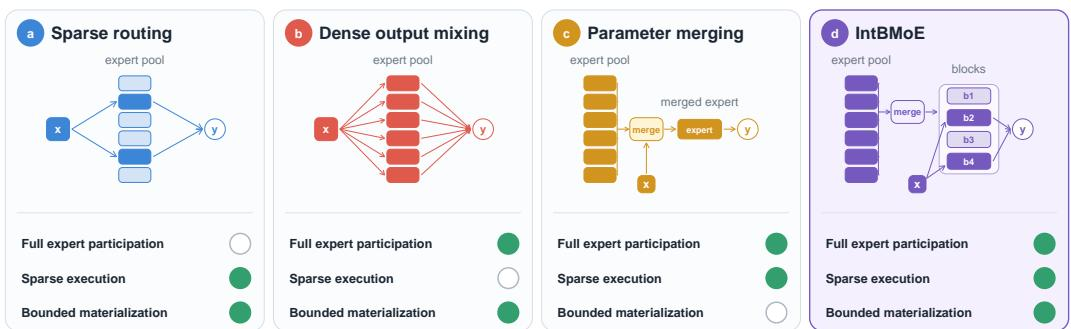
Method
The authors introduce IntBMoE, which integrates into a standard Transformer backbone by replacing the traditional Feed-Forward Network sublayer. Instead of utilizing standard dense or token-level expert routing, the architecture composes reusable multi-layer blocks from shared expert pools and sparsely routes each token to a select few of these blocks.
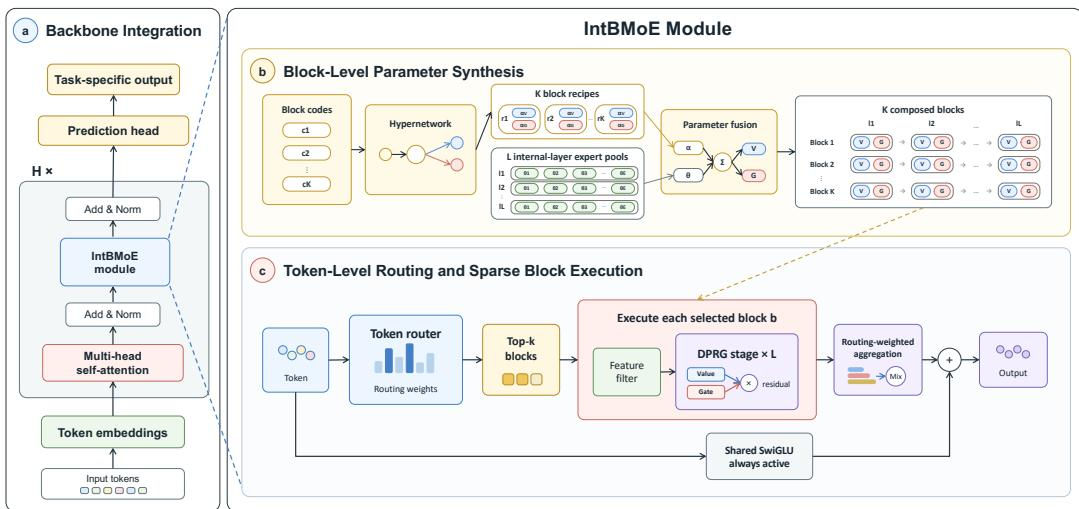
As shown in the figure below, the design operates at two distinct levels: block-level parameter synthesis and token-level routing.
At the block level, the module maintains a codebook of K learned embeddings, where each embedding cb∈Rdc identifies a candidate L-layer block. A shared hypernetwork hϕ processes each embedding through a linear-LayerNorm-ReLU trunk to produce a hidden representation qb. Two linear output heads then map this representation to value and gate composition coefficients, αbv and αbg.
For each internal layer ℓ, the module maintains a layer-specific pool of E expert bases. The hypernetwork coefficients linearly combine these expert bases to synthesize the parameters for the K blocks. To maintain parameter scale stability as the pool grows, a variance-preserving factor of 1/E is applied during composition:
Wb,p(ℓ)=E1e=1∑Eαb,epWe(ℓ),bb,p(ℓ)=E1e=1∑Eαb,epbe(ℓ)where p∈{v,g}. Because this synthesis depends solely on the learned block embeddings and not on token representations, the K composed blocks are token-independent and can be precomputed.
At the token level, a router independently selects the Top-k blocks for each token t based on its representation xt. The router, implemented as a two-layer ReLU MLP, outputs a score vector rt, and the routing weights πt,b for the selected blocks are computed via softmax. Before entering a selected block b, the token representation undergoes block-conditioned feature filtering. The token xt is concatenated with the block codebook embedding cb and passed through a shared feature-filtering layer to generate a soft feature-wise mask mt,b. The filtered representation zt,b(0)=xt⊙mt,b provides distinct views of the same token for different blocks.
Within each block, the authors employ Dual-Path Residual Gating to introduce nonlinear interactions between the independently composed value and gate paths. For an internal layer ℓ with input zt,b(ℓ−1), the value and gate transformations are computed as:
vt,b(ℓ)=Wb,v(ℓ)zt,b(ℓ−1)+bb,v(ℓ) gt,b(ℓ)=RMSNorm(Wb,g(ℓ)zt,b(ℓ−1)+bb,g(ℓ))These paths are coupled through residual multiplicative modulation:
zt,b(ℓ)=vt,b(ℓ)⊙(1+λSiLU(gt,b(ℓ)))where λ is a learnable residual scale shared across internal layers. LayerNorm is applied between consecutive layers, and the final output of the block is denoted as Fb(xt).
The outputs of the selected blocks are aggregated using their respective routing probabilities to form the routed output ytroute. To capture common information that does not require token-dependent selection, the architecture adds an always-active shared SwiGLU expert S. The final output is the sum of the routed block outputs and the shared expert output:
yt=ytroute+S(xt)Regarding computational complexity, the composition of all K blocks from E bases incurs a cost of O(KED), while executing the k selected blocks for T tokens costs O(TkD). During inference, because block composition relies only on fixed model parameters, the composed block parameters can be constructed once and cached. This removes the O(KED) composition term from request-time computation, ensuring that the dominant routed-block cost remains O(TkD) and is independent of the expert-pool size E.
Experiment
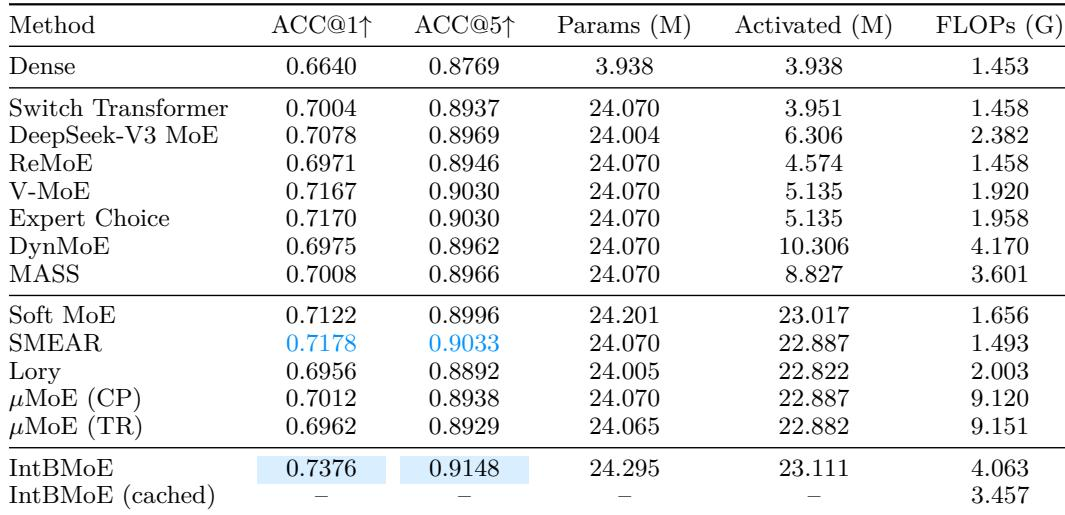
The authors evaluate IntBMoE on ImageNet-1K with a DeiT-Tiny-style backbone and compare it against dense, sparse-routing, and dense-participation MoE baselines. IntBMoE outperforms all baselines, and ablations show that the composed gate path, two-layer block structure, shared expert, and feature filtering each contribute, with the gate path being the most important. Analyses further indicate effective full-pool expert participation, class- and depth-dependent block routing, and increasingly block-specific expert-composition recipes in deeper layers. Cached inference keeps request-time memory and computation independent of expert-pool size, and the method generalizes to language modeling and sequential recommendation, including a production POI recommendation deployment with improved UVCTR under latency constraints.
IntBMoE achieves 73.76% Top-1 and 91.48% Top-5 accuracy on ImageNet-1K, improving over its dense backbone by 7.36 and 3.79 percentage points respectively. It also exceeds all compared sparse-routing and dense-participation MoE baselines, including the strongest competitor, while using a comparable total parameter budget near 24M. Inference cost is 4.063 GFLOPs per image without caching and 3.457 GFLOPs with caching. IntBMoE outperforms the dense backbone by over seven Top-1 points and nearly four Top-5 points. It surpasses the strongest MoE baseline by close to two Top-1 points under comparable parameter budgets. Caching lowers per-image inference cost from about 4.1 GFLOPs to about 3.5 GFLOPs while preserving selective block execution.
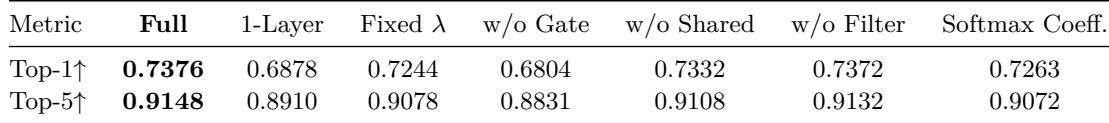
The full model achieves the highest Top-1 and Top-5 accuracy among the ablated variants. Removing the composed gate path causes the largest performance decline, followed by collapsing the two-layer block into a parameter-matched single-layer design. Shared expert and feature filtering provide smaller but consistent gains, while fixed and softmax-normalized coefficient formulations underperform the full formulation. The composed gate path is the most critical component, with its removal causing the largest Top-1 and Top-5 drops among all ablations. The shared expert and feature filter contribute smaller but consistent accuracy gains, and learned or unconstrained coefficient formulations outperform fixed or softmax-normalized alternatives.
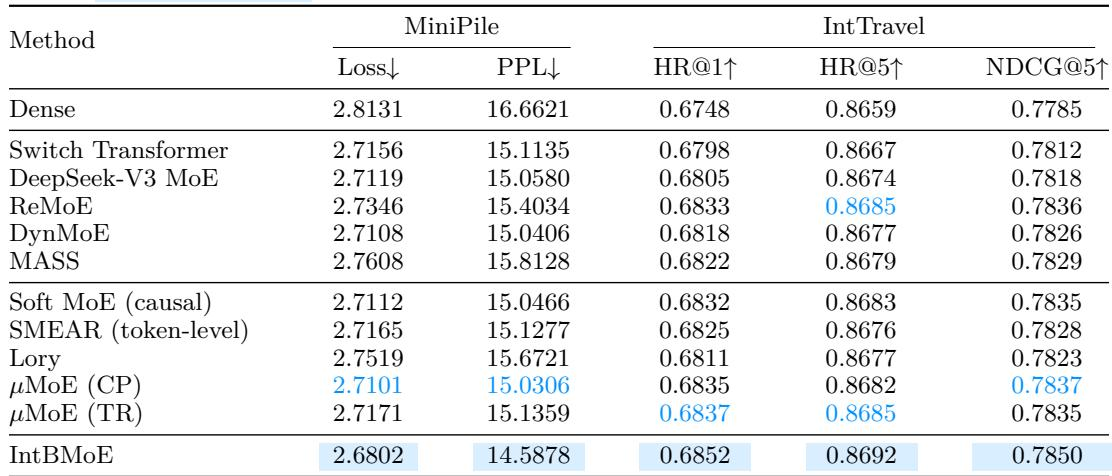
IntBMoE generalizes to autoregressive language modeling and sequential recommendation tasks. On MiniPile, it achieves lower perplexity than the dense backbone and all reported sparse or dense-participation baselines. On IntTravel, it attains the best ranking metrics among evaluated methods. On MiniPile, IntBMoE reduces perplexity by a clear margin over the dense backbone and by a smaller margin over the strongest baseline. On IntTravel, IntBMoE achieves the highest HR@1, HR@5, and NDCG@5 among the compared methods. The dense backbone has the weakest MiniPile language modeling metrics, while several sparse baselines improve loss and perplexity.
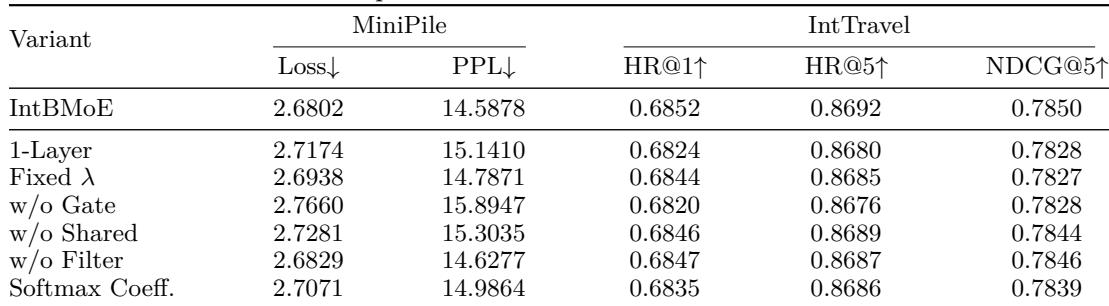
The full model achieves the best results on both MiniPile and IntTravel across all reported metrics. Ablations show the gate path is the most influential component for MiniPile and a major contributor for IntTravel, while the two-layer structure provides benefits beyond matched expert parameters. Shared experts, learned lambda, feature filtering, and unconstrained composition all contribute consistent gains on both autoregressive tasks. Removing the gate path causes the largest increase in MiniPile loss and perplexity and lowers IntTravel hit rates. The parameter-matched 1-layer variant underperforms the full model, showing the two-layer block structure adds benefits beyond expert parameter count. Using a shared expert yields smaller but consistent improvements across both tasks. Fixing lambda or removing feature filtering hurts both tasks, while unconstrained variance-scaled coefficients outperform softmax-normalized composition.
IntBMoE is evaluated on ImageNet-1K classification, MiniPile autoregressive language modeling, and IntTravel sequential recommendation, with additional ablation studies. It consistently outperforms its dense backbone and compared sparse or dense-participation MoE baselines under comparable parameter budgets, while caching reduces per-image inference cost from about 4.1 to 3.5 GFLOPs. Ablations show the composed gate path and two-layer block structure are most important, with shared experts, feature filtering, and unconstrained coefficient composition providing smaller but consistent gains across tasks.