Command Palette
Search for a command to run...
JEPA-Anything: 서로 다른 세계 전반의 예측 모델 학습
JEPA-Anything: 서로 다른 세계 전반의 예측 모델 학습
초록
세계 모델링은 지능이 결과를 예측하고, 개입을 안내하며, 상호작용으로부터 학습할 수 있게 한다. 그러나 예측 모델은 여전히 도메인 특정적이다. 근본적으로 상이한 시스템들 전반의 세계 모델링을 하나의 공통 학습 원리가 뒷받침할 수 있는가? 우리는 직교 예측 분해(OPF)에 기반한 도메인 독립적 프레임워크인 JEPA-Anything을 제안한다. OPF는 조인트 임베딩 예측 구조를 확장하여, 잠재 타깃을 상보적 요인들로 분해하고, 각 요인을 전용 경로를 통해 학습한 뒤, 공유된 예측 설계 안에서 재결합한다. 우리는 시각, 생물학, 임상 궤적, 제어, 분자 동역학, 물리장, 기상의 7개 도메인에서 JEPA-Anything을 평가한다. 실험은 표현 학습, 개입 예측, 분포 외 일반화, 장기 지평 동역학을 포괄하며, 10개의 대응 동역학 과제, 1,000건 이상의 임상 사건 예측, 4개 시스템에 걸친 100단계 분자 롤아웃을 포함한다. 대응 JEPA 기준선들과 비교하여, JEPA-Anything은 10개 동역학 과제 모두에서 보고된 지표를 개선하고, Interventional Pong의 단일 개입 예측 오차를 34.8% 감소시킨다. 비교된 방법들 중 4개 시스템 모두에서 1단계 및 100단계 분자 오차가 가장 낮다. 예측을 넘어, 요인 기반으로 선정된 생물학적 개입이 세포 공동배양, 환자 유래 오가노이드, 종양 절편 및 생쥐에서 실험적 지지를 얻었으며, 잠재 궤도 모드는 -1.4991의 적합 기울기로 케플러 스케일링 지수를 복원한다. 이 결과는 이질적 세계들 전반에 걸친 공통 분해 예측 원리를 뒷받침하며, 세계 모델링을 개입 및 실험적으로 뒷받침되는 과학적 발견과 연결한다.
One-sentence Summary
Researchers from PhAI Labs, The Chinese University of Hong Kong, Fudan University, and other institutions propose JEPA-Anything, a domain-agnostic framework based on orthogonal predictive factorization (OPF) that decomposes latent targets into complementary factors, learns them through dedicated pathways, and recombines them within a shared predictive design, improving over matched JEPA baselines on all 10 dynamics tasks, lowering single-intervention prediction error on Interventional Pong by 34.8%, and achieving the lowest one-step and 100-step molecular errors among compared methods across four systems.
Key Contributions
- JEPA-Anything is introduced as a domain-agnostic framework based on orthogonal predictive factorization (OPF), which decomposes latent targets into complementary factors, learns them through dedicated pathways, and recombines them within a shared predictive design.
- Evaluated across seven domains, JEPA-Anything improves reported metrics on all 10 matched dynamics tasks, reduces single-intervention prediction error on Interventional Pong by 34.8%, and achieves the lowest one-step and 100-step molecular prediction errors among compared methods in all four systems.
- The results connect factorized prediction to experimentally grounded discovery: a factor-nominated biological intervention receives support in cell co-cultures, patient-derived organoids, tumor fragments, and mice, and latent orbital modes recover the Keplerian scaling exponent with a fitted slope of -1.4991.
Introduction
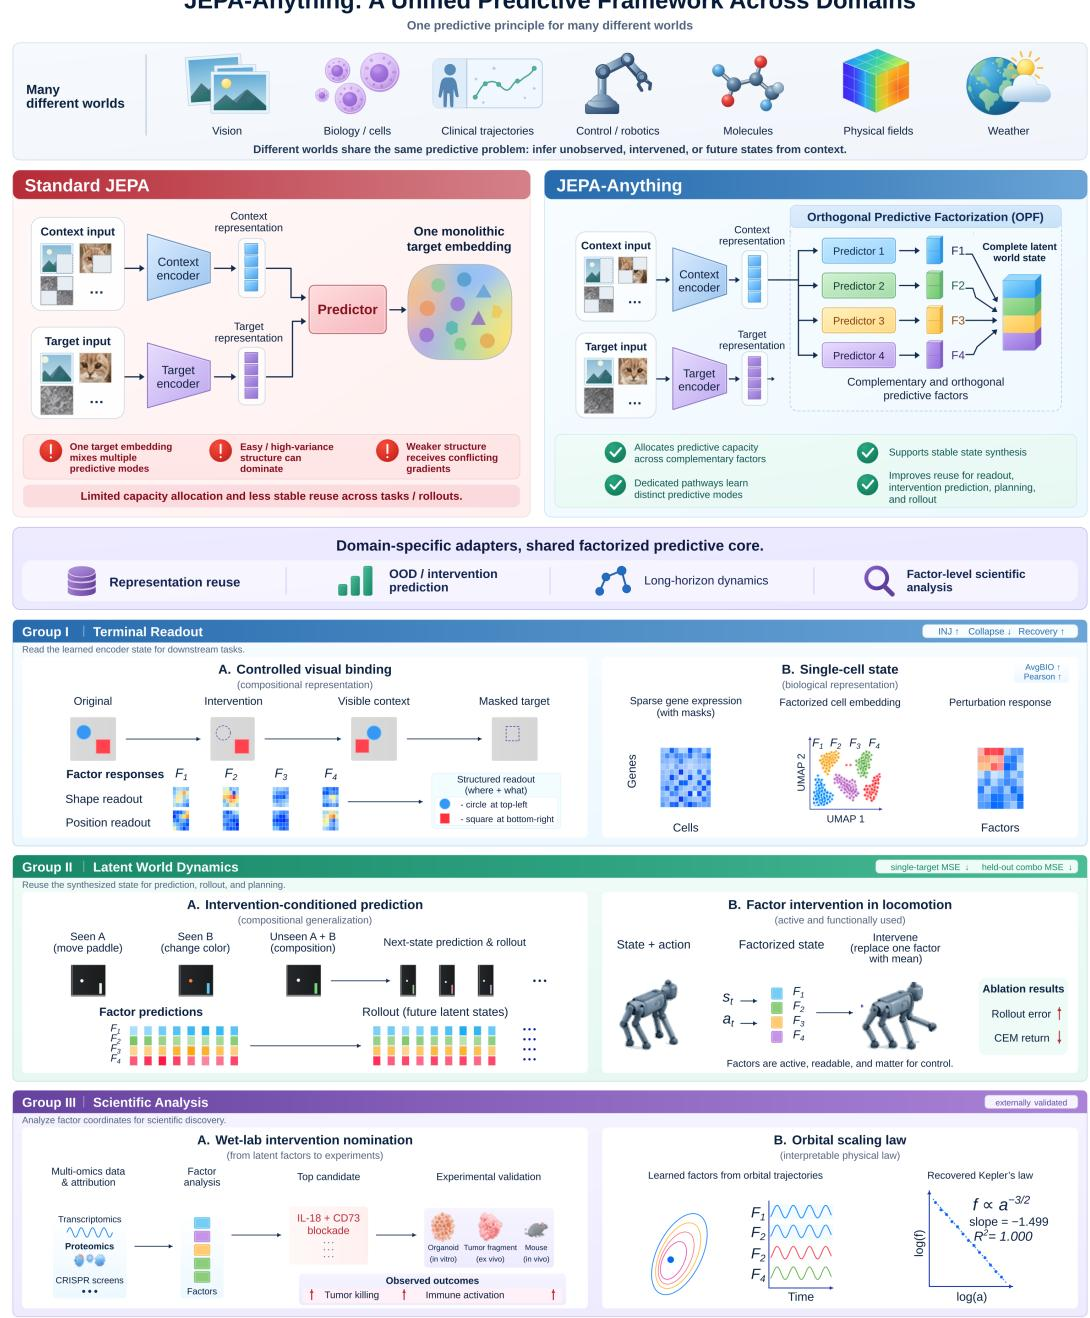
Latent world models learn predictive states that let agents and scientific models anticipate future or hidden states across many domains, from visual scenes and patient histories to molecular trajectories and physical fields. Joint-embedding predictive architectures support this by predicting in latent space, but the usual formulation represents each target as one monolithic embedding with one prediction pathway. That design can let high-variance or easily predicted structure dominate optimization, while weaker or complementary predictive structure receives conflicting gradients, turning latent state design into a capacity-allocation problem. The authors address this with JEPA-Anything, a framework based on orthogonal predictive factorization that decomposes each target state into multiple learned factors with dedicated predictors, using within- and cross-factor orthogonality and activity regularization. The same interface is applied across visual, single-cell, longitudinal health, control, molecular dynamics, physical field, weather, and clinical systems.
Method
The authors leverage a unifying latent world-state interface to standardize predictive learning across diverse domains. A domain adapter maps a raw observation into content tokens and structural descriptors, while a view sampler selects context and target indices. This establishes a common interface where the semantics of the adapter and sampler are domain-specific, but the subsequent predictive algorithm remains identical.
As shown in the figure below:
An online encoder processes the context tokens to produce a context representation, while a target encoder generates a latent target representation. The target encoder parameters are updated as an exponential moving average of the online encoder parameters and receive no gradients.
To overcome the limitations of predicting a monolithic target embedding, the authors introduce Orthogonal Predictive Factorization (OPF). Instead of a single predictor, the framework employs K learned projectors Pk∈Rd×r, chosen such that Kr=d. The stop-gradient target representation is factorized into K complementary subspaces:
z~t=sg(zt),zt(k)=Pk⊤z~t,k=1,…,KEach factor is assigned a dedicated predictor qk that maps the shared context representation and target descriptor into an r-dimensional space:
z^t(k)=qk(zc,st)The individual factor predictions are concatenated into a single vector u^t and synthesized into a complete latent state using the Moore-Penrose pseudoinverse of the analysis map:
z^t=(P⊤)†u^twhere P=[P1,…,PK]. When the projectors are exactly orthogonal, this synthesis reduces to a simple summation of the projected factors.
The training objective combines a standard base loss with the OPF loss. The prediction loss directly regresses each predicted factor to its target:
Lpred=K∣T∣r1t∈T∑k=1∑K∥z^t(k)−zt(k)∥22To ensure the learned subspaces are mutually orthogonal and avoid degenerate bases, an orthogonality loss is applied:
Lorth=k=1∑K∥Pk⊤Pk−Ir∥F2+1≤i<j≤K∑∥Pi⊤Pj∥F2Furthermore, to prevent representation collapse and maintain factor activity, the authors introduce activity regularization terms. These terms penalize low empirical standard deviations in both the projected target coordinates and the online context representations. The complete training loss is the sum of the domain-specific base loss and the weighted OPF components:
Ltrain(δ)=Lbase(δ)+Lpred+λorthLorth+λfacLfac+λencLencThe optimization loop iteratively adapts observations, samples contexts and targets, computes representations, predicts orthogonal factors, and updates the network parameters. For downstream applications, the framework supports two distinct modes. In representation mode, the online encoder is retained to extract reusable features for task-specific readouts, discarding the predictive heads. In operational world-model mode, the learned projectors and predictors are preserved to synthesize future latent states, enabling autoregressive simulation, planning, and intervention forecasting.
Experiment
The evaluation applies the same JEPA-Anything core across visual, biological, clinical, control, molecular, physical-field, and weather systems, organized into terminal readout, recursive latent dynamics and planning, and scientific factor analysis. Terminal-readout experiments show gains in controlled visual binding, single-cell clustering and perturbation prediction, and clinical event forecasting. Dynamics and rollout experiments indicate improved intervention composition, out-of-distribution prediction, and long-horizon stability, while continuous-control planning improves on Walker2d and HalfCheetah but not Hopper. Factor-level analyses confirm active and intervenable latent channels, and external wet-lab and orbital scaling results support reuse of the learned coordinates for scientific validation.
JEPA-Anything separates domain-specific predictive-state construction from a shared predictive core. Domain adapters and view samplers handle raw representation, tokenization, context-target semantics, encoder architecture, and the original loss, while the core provides a common token interface, factorized predictors with state synthesis, and orthogonal regularization. Analyses in biological and orbital domains show that the learned factor coordinates can support external scientific validation. Raw representations and encoder architectures vary across images, sequences, graphs, sets, and records, while the predictive core and regularizers remain shared. Learned factor coordinates supported a wet-lab nominated intervention in cancer models and recovered a Keplerian orbital scaling relation from unlabeled trajectory data.
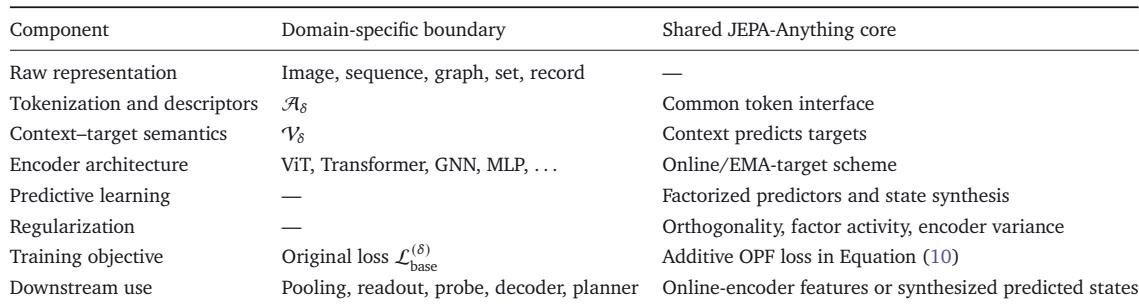
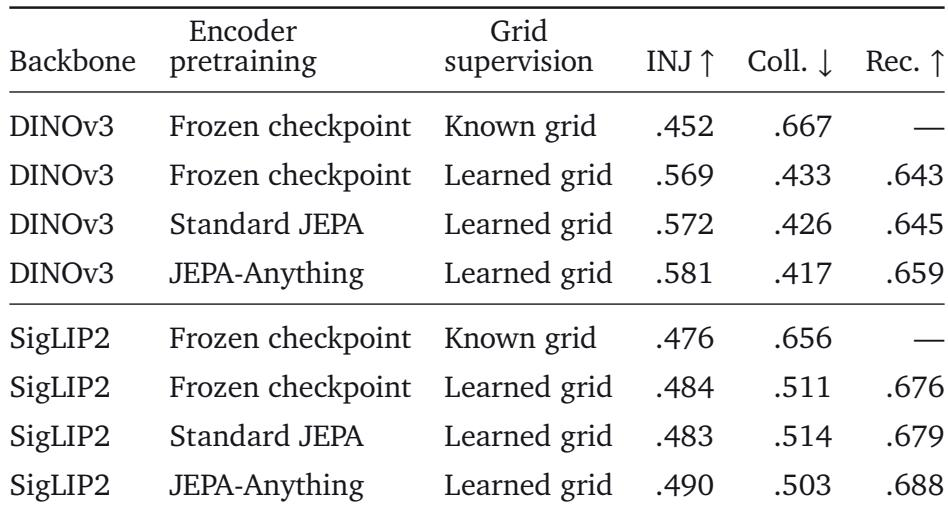
The experiments evaluate a shared orthogonal predictive factorization interface across visual, single-cell, clinical, interventional, dynamical, PDE, and long-rollout settings. Quantitative comparisons hold core modeling choices fixed against domain and monolithic JEPA baselines, using domain-specific metrics over repeated seeds and held-out or out-of-distribution splits. Factor-level analyses connect learned coordinates to external biological and physical validation. Terminal-readout experiments report stronger visual, cellular, and disease-state metrics with the OPF-based formulation. Intervention and dynamics benchmarks support combined-intervention prediction, out-of-distribution forecasting, and repeated multi-step rollout. Learned factor coordinates are non-overlapping and unit-conditioned, with near-exact synthesis. Factor-level analysis nominated an IL-18 plus NT5E/CD73 blockade intervention that wet-lab studies supported and recovered the Keplerian orbital scaling relation from simulated trajectories.
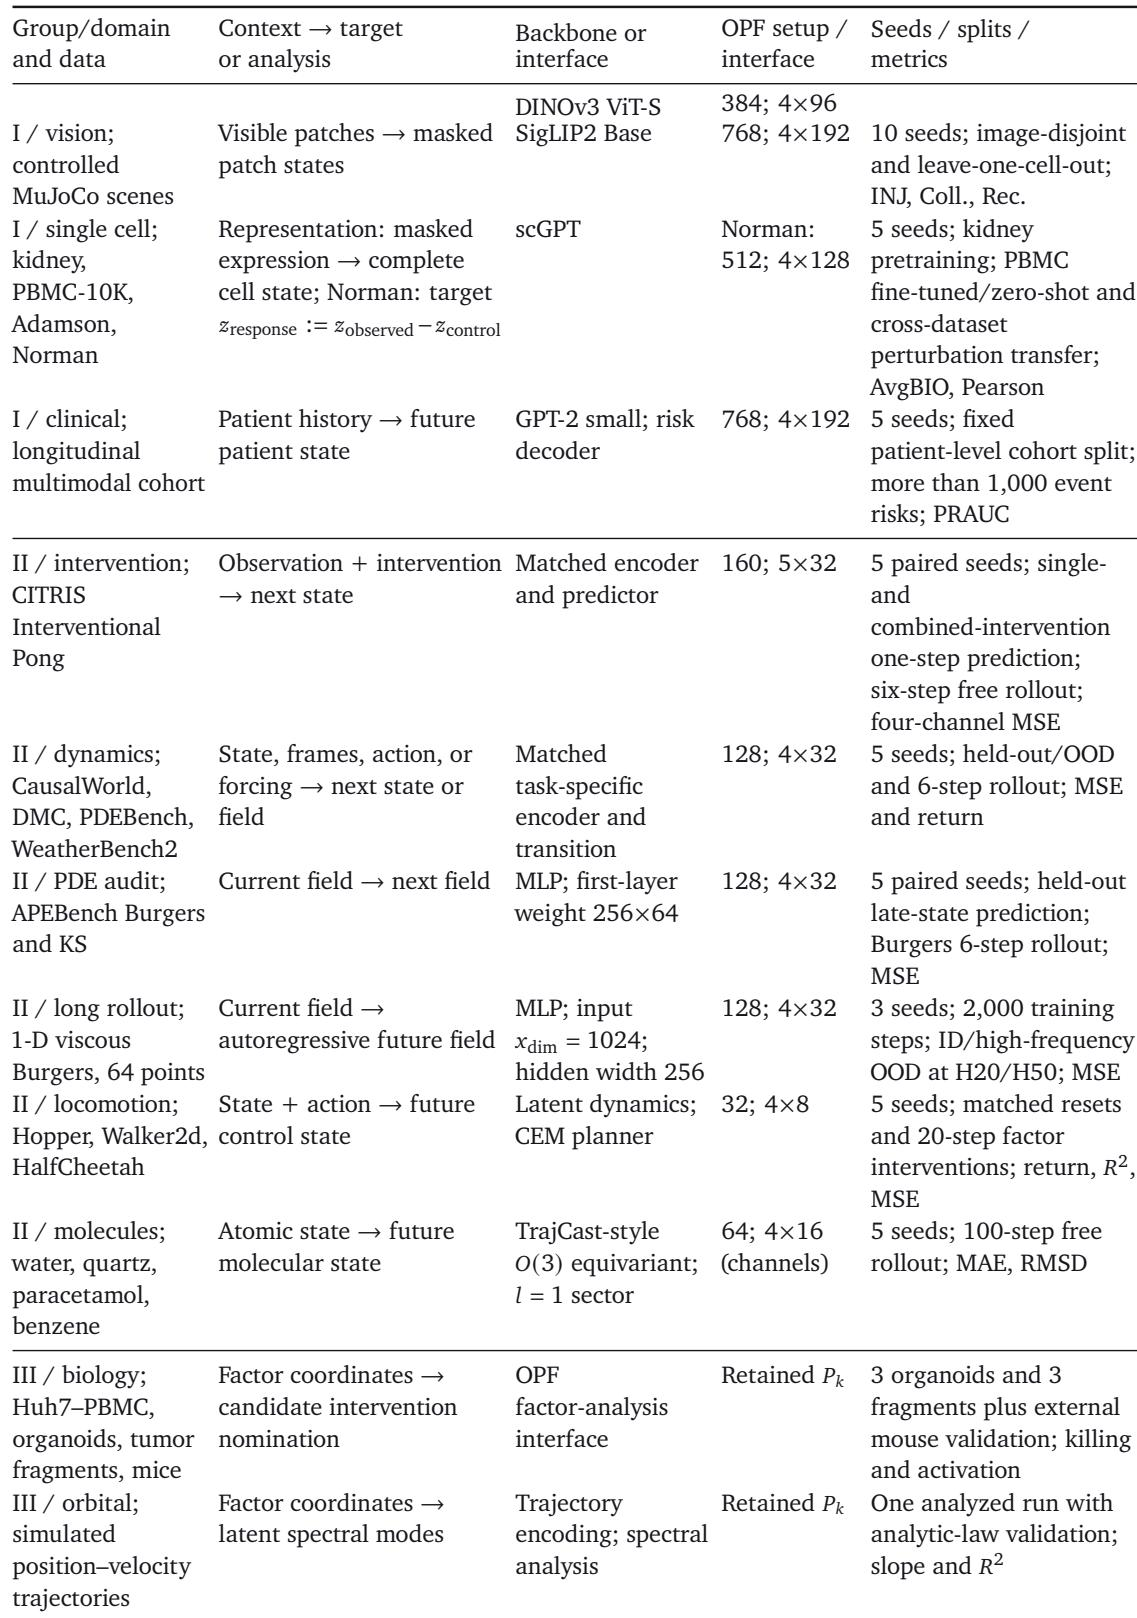
In controlled MuJoCo visual binding, using a learned grid readout improves intervention and collision metrics for both frozen encoder backbones while also enabling reconstruction. DINOv3 benefits further from JEPA-style encoder pretraining, with JEPA-Anything yielding the best reported intervention and collision results. SigLIP2 shows a smaller frozen-checkpoint gain, and its standard JEPA variant performs similarly to the learned-grid frozen setup. Learned grid supervision improves collision over known grid supervision for frozen DINOv3 and SigLIP2 backbones. DINOv3 with JEPA-Anything and a learned grid achieves the strongest combined intervention and collision performance in the reported comparison. For SigLIP2, standard JEPA pretraining tracks the frozen learned-grid readout rather than providing a large additional gain.
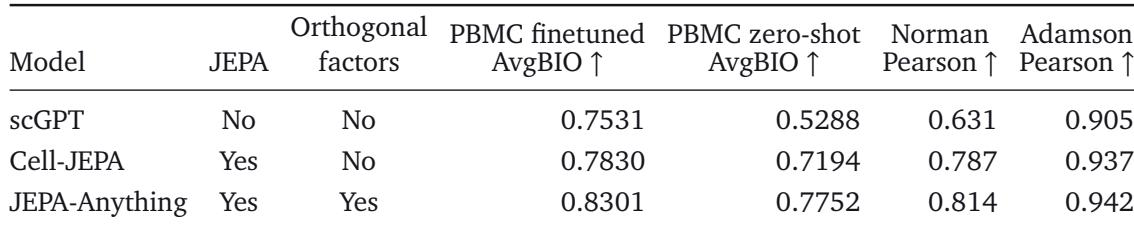
The evaluation compares scGPT, Cell-JEPA, and JEPA-Anything on PBMC cell-type clustering and perturbation-response prediction. Cell-JEPA improves over scGPT across all reported metrics, with especially large gains in zero-shot PBMC clustering and Norman perturbation prediction. JEPA-Anything adds orthogonal factorization and achieves the highest scores on both clustering metrics and both perturbation datasets. JEPA-Anything attains the highest values across PBMC finetuned clustering, PBMC zero-shot clustering, Norman perturbation prediction, and Adamson perturbation prediction. Cell-JEPA improves over scGPT on every reported metric, with the largest gains in zero-shot PBMC clustering and Norman perturbation prediction. Adding orthogonal factors to Cell-JEPA further improves both clustering quality and perturbation-response prediction.
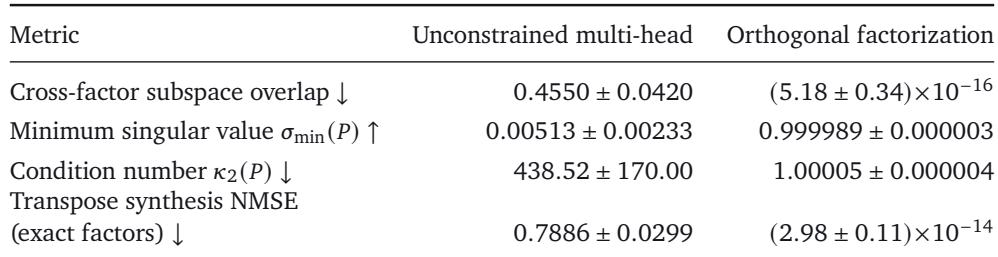
An audit of the factor interface on CITRIS Interventional Pong shows that orthogonal factorization produces factor subspaces with negligible overlap, near-unit minimum singular values, and near-unit condition numbers, whereas unconstrained multi-head factors overlap substantially and are poorly conditioned. Orthogonal factorization also reduces transpose synthesis NMSE by many orders of magnitude, indicating near-exact reconstruction from exact factors. Orthogonal factorization drives cross-factor subspace overlap down to near machine precision, while unconstrained multi-head factors remain substantially overlapped. The projection matrix under orthogonal factorization is well-conditioned, with minimum singular value and condition number close to one; unconstrained multi-head is ill-conditioned with a much lower minimum singular value. Transpose synthesis from exact factors becomes near-exact under orthogonal factorization, in contrast to high reconstruction error for unconstrained multi-head.
The experiments evaluate a shared orthogonal predictive factorization interface across visual binding, single-cell, clinical, interventional, dynamical, PDE, and long-rollout settings, comparing JEPA-Anything with domain-specific and monolithic JEPA baselines under held-out and out-of-distribution evaluations. Visual binding results show learned grid readouts and JEPA-style pretraining improve intervention and collision performance, with the strongest combined result from JEPA-Anything. In biological and factor-audit settings, orthogonal factorization improves clustering and perturbation prediction while producing non-overlapping, well-conditioned, near-exact factor synthesis. Factor-level analyses link learned coordinates to external validation, including a wet-lab supported cancer intervention and recovery of the Keplerian orbital scaling relation from unlabeled trajectories.