Command Palette
Search for a command to run...
EOS 토큰이 불일치할 때: 온폴리시 증류에서의 길이 팽창 이해
EOS 토큰이 불일치할 때: 온폴리시 증류에서의 길이 팽창 이해
Yuxiao Yang Tianrun Yu Shangzhe Li Kaixiang Zhao Xuchao Zhang Chetan Bansal Huaxiu Yao Taylor W. Killian Weitong Zhang
초록
우리는 온폴리시 증류(OPD)에서 학생 응답이 지나치게 길어지고 심지어 생성 예산을 모두 소진하기도 하는 길이 팽창을 연구한다. 우리는 기본 학생 모델과 사후 학습된 교사 모델 간의 종료 토큰 불일치가 이러한 현상의 중요한 원인임을 밝힌다. Qwen3, Llama, Gemma에 걸쳐 두 모델은 선언된 종료 집합이 동일하더라도 서로 다른 EOS 토큰에 종료 확률을 둘 수 있다. 이러한 불일치는 학생이 선호하는 종료 행동을 억제하면서도 교사가 선호하는 대안을 신뢰성 있게 전이하지 못할 수 있다. 우리는 디코딩 종료 집합을 맞추는 것만으로는 충분하지 않으며, 기능적으로 동등한 EOS 토큰을 공유된 의미적 종료 행동으로 취급하는 방식이 세 모델 계열 모두에서 불일치로 인한 길이 팽창을 상당히 완화함을 보인다. 훈련 중 종료 행동이 어떻게 진화하는지 더 이해하기 위해 다양한 K2-Horizon 훈련 단계에 걸쳐 OPD를 분석한다. 이 단계별 분석은 훈련 중 종료 선호가 크게 바뀔 수 있음을 보여주고, OPD 실행 후반에 종료 정렬 이후에도 지속되는 뚜렷한 길이 팽창을 드러낸다. 종합하면, 이 결과들은 종료 불일치가 OPD 길이 변화의 중요하지만 전부는 아닌 원인임을 확인한다. 우리는 제안된 종료 처리 보정을 통합한 구현을 공개한다.
One-sentence Summary
Researchers at the University of North Carolina at Chapel Hill, Brigham Young University, and Microsoft show that termination-token mismatch between base students and post-trained teachers drives length inflation in on-policy distillation across Qwen3, Llama, and Gemma, and they propose treating functionally equivalent EOS tokens as a shared semantic stopping action, which substantially mitigates this mismatch-induced inflation, while stage-wise K2-Horizon analysis reveals additional late-run length dynamics.
Key Contributions
- The paper identifies termination-token mismatch between base students and post-trained teachers as a key source of length inflation in on-policy distillation, showing across Qwen3, Llama, and Gemma that models can prefer different EOS tokens even when their declared stopping sets are identical, which suppresses the student's preferred termination action without reliably transferring the teacher-preferred alternative.
- The paper demonstrates that aligning the decoding stopping set alone is insufficient, whereas treating functionally equivalent EOS tokens as a shared semantic stopping action substantially mitigates mismatch-induced length inflation across all three model families.
- The paper presents a stage-wise analysis of on-policy distillation across K2-Horizon training stages, showing that termination preferences can shift substantially during training and that a distinct late-training length inflation persists beyond termination alignment, and it releases an implementation incorporating the proposed termination-handling corrections.
Introduction
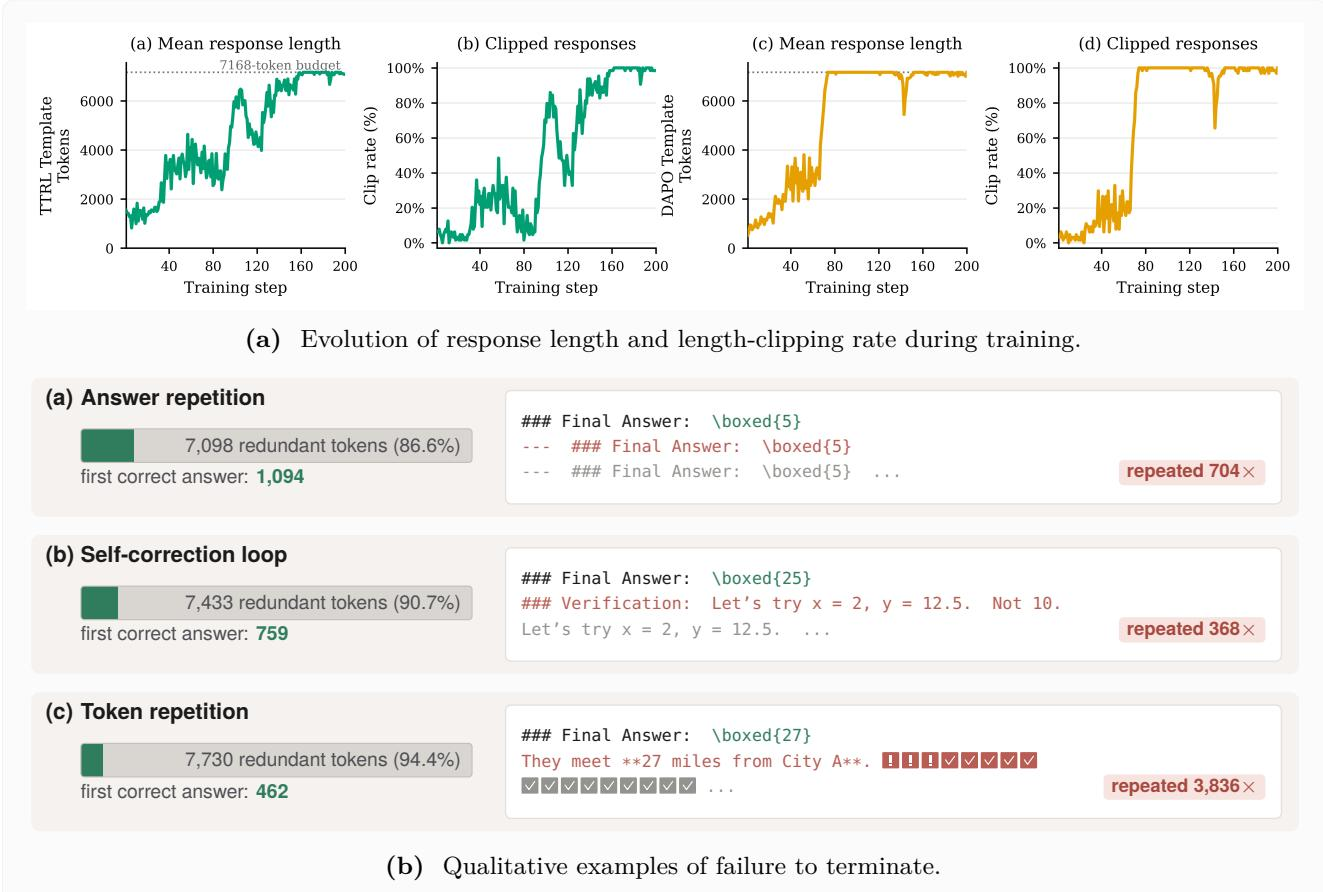
On-policy distillation (OPD) trains a student on its own sampled rollouts with dense token-level supervision from a post-trained teacher, making it a practical way to transfer strong behavior to smaller or less capable models. However, OPD often produces progressively longer responses with truncation or repetition, and prior work has attributed this length inflation to objective-level effects, rollout degradation, or training instability. The authors identify termination-token mismatch as a direct and diagnosable cause: base students and post-trained teachers may encode the same semantic stop decision with different EOS tokens, even when their declared stopping sets match. Because the teacher evaluates only student-generated tokens, the student's own termination action can be suppressed. The authors show that aligning the decoding stopping set alone is insufficient, while treating functionally equivalent EOS tokens as a shared semantic stopping action substantially mitigates mismatch-induced length inflation across Qwen3, Llama, and Gemma.
Method
The authors identify that modifying only the decoding interface is insufficient to address termination mismatch in distillation. The mismatch must be corrected within the distillation signal itself by reconciling the termination probabilities of the teacher and the student. Let EEOS denote the termination-equivalent tokens under the rollout protocol, and let e⋆∈EEOS be a canonical EOS token supported by the base student. To address this, the authors propose three probability-level alignment corrections.
The first correction, teacher-side EOS mapping, maps the probability mass the teacher assigns to all termination-equivalent tokens to the canonical student EOS token. This is formulated as:
πE(e⋆∣st)=e∈EEOS∑πE(e∣st)In practice, negligible probability is retained on other EOS tokens for numerical stability, while the canonical probability is adjusted to preserve the total mass. The student distribution remains unchanged, and rollout terminates exclusively on e⋆.
The second correction, semantic EOS class, treats all tokens in EEOS as realizations of a single semantic action, STOP, rather than selecting a canonical surface token. For any policy π∈{πθ,πE}, the aggregated probability is defined as:
πˉ(STOP∣st)=e∈EEOS∑π(e∣st)while πˉ(a∣st)=π(a∣st) for non-EOS tokens. If a sampled token yt is an EOS token, it is replaced by yˉt=STOP. The standard sampled-token OPD update is then applied directly:
At=logπˉE(yˉt∣st)−logπˉθ(yˉt∣st),gt=At∇θlogπˉθ(yˉt∣st)This ensures EOS samples are supervised through the total termination probability without altering non-EOS tokens.
The third correction, canonical single-EOS action space, maps the teacher EOS probability mass to e⋆ and removes all other tokens in EEOS from the student sampling distribution, renormalizing the remaining probabilities. This creates a consistent action space with a single canonical termination action.
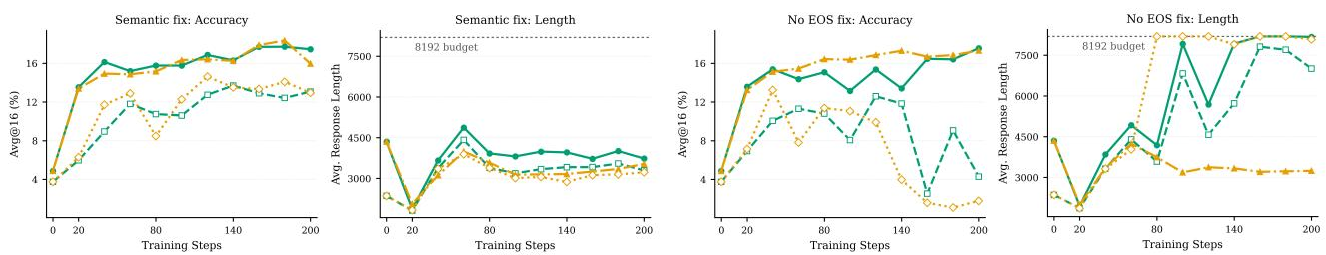
The authors note that these three corrections yield similar empirical results. Teacher-side EOS mapping is utilized for explicit, known mismatches because it simply modifies the teacher distribution. However, semantic EOS aggregation is adopted as the default for cross-family experiments because it avoids the requirement of designating a canonical surface form, accommodating models that expose the same declared EOS set but prefer different tokens.
The shared termination failure is distinct from its effect on measured task performance. Cross-template evaluation can reduce observed response length, and performance gains from OPD can persist despite severe length inflation, particularly under specific evaluation templates. The apparent effect on accuracy also depends on the grader, as certain evaluation styles are more sensitive to long redundant continuations. Consequently, length inflation does not necessarily imply a comparable loss of reasoning capability.
As shown in the figure below:
Experiment
The experiments evaluate sampled-token on-policy distillation between base student models and post-trained or instruct teachers from Qwen3, Llama 3.2, Gemma 3, and K2-Horizon on single-turn math reasoning tasks. They show that length inflation and clipping arise when teacher and student distribute termination probability across different equivalent EOS tokens, even if the decoding stopping sets are aligned, and that probability-level corrections such as semantic EOS aggregation substantially mitigate this mismatch across model families. Stage-wise K2-Horizon runs indicate that vanilla distillation can transfer a teacher-preferred termination token when the student already gives it enough sampling support, but later re-inflation and other residual length dynamics remain even after correction. Template and grader comparisons further show that the severity of length inflation depends on evaluation context, while some downstream performance gains can still transfer.
The studied model families differ in their declared EOS token configurations across training stages. Qwen and Llama base checkpoints declare a single end-of-text token, while their post-trained checkpoints also recognize additional conversational termination tokens. Gemma and K2-Horizon show cases where declared stopping sets are shared across stages, so termination mismatches can persist through learned preferences rather than decoding configuration alone. Post-trained Qwen and Llama checkpoints declare additional conversational termination tokens beyond the single end-of-text token used by their base checkpoints. Gemma and K2-Horizon keep declared stopping tokens consistent across compared stages, but learned termination preferences can still diverge.
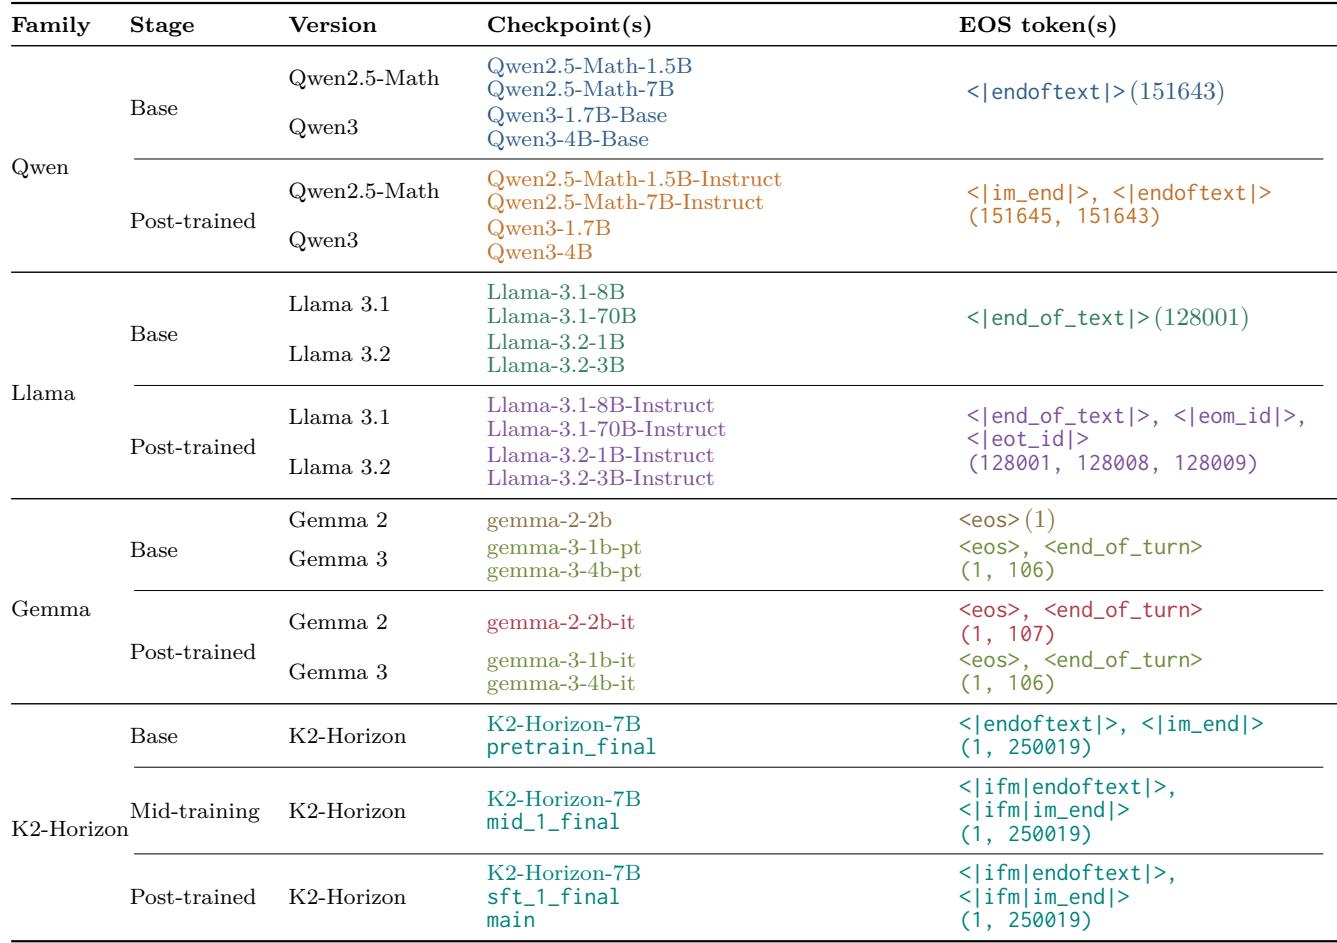
The evaluation inspects declared end-of-text token configurations across base and post-trained checkpoints from Qwen, Llama, Gemma, and K2-Horizon. Qwen and Llama base models declare a single end-of-text token, while their post-trained versions add conversational termination tokens, creating a configuration-level shift. Gemma and K2-Horizon keep declared stopping tokens consistent across stages, but their learned termination preferences can still diverge, showing that stopping mismatches may arise from training behavior rather than decoding setup alone.