Command Palette
Search for a command to run...
PPO에서의 비평가 학습 재고: 가치 평탄화(Value Flattening) 이해 및 완화
PPO에서의 비평가 학습 재고: 가치 평탄화(Value Flattening) 이해 및 완화
초록
대규모 언어 모델을 위한 강화 학습에서 PPO(Proximal Policy Optimization)는 일반적으로 상태 가치를 추정하고 정책 업데이트의 분산을 줄이기 위해 비평가(critic)를 사용합니다. 그러나 우리는 PPO 비평가에서 체계적인 실패 모드를 발견했으며, 이를 가치 평탄화(Value Flattening)라고 부릅니다. 여러 몬테카를로 연속(Monte Carlo continuation)에서 추정된 상태 가치는 중간 상태들에 걸쳐 급격하게 변하는 반면, 비평가 예측은 상대적으로 평평하게 유지됩니다. 우리는 또한 통제된 FrozenLake 환경에서 이 현상을 관찰했으며, 상태 공간이 커질수록 더 두드러진다는 것을 발견했습니다. 우리의 이론적 및 실증적 분석은 가치 평탄화를 비평가 손실의 암묵적 분산 패널티와 유사한 기울기를 가진 시간적으로 상관된 상태들의 중복 업데이트와 연관시킵니다. 이러한 발견에 동기를 부여받아, 우리는 SParse Proximal Policy Optimization(SP3O)을 도입합니다. 이는 각 응답에서 잘 분리된 소수의 상태에만 가치 손실을 적용하여 두 효과를 모두 완화합니다. Qwen3-Base에 대한 실험은 응답당 단 3개의 상태만 감독하는 SP3O가 가치 평탄화를 완화하고 모델 크기와 평가 스위트 전반에 걸쳐 학습된 정책을 일관되게 개선할 수 있음을 보여줍니다. 종합적으로, 우리의 결과는 가치 평탄화가 표준 PPO에서 간과되지만 중요한 비평가 학습의 실패 모드임을 식별하고, 간단한 희소 감독 전략이 이를 완화할 수 있음을 보여줍니다.
One-sentence Summary
Researchers from Shanghai Jiao Tong University, Shanghai AI Laboratory, Westlake University, Nanjing University, Tsinghua University, The Chinese University of Hong Kong, and Nanyang Technological University identify Value Flattening, a systematic failure in Proximal Policy Optimization (PPO) where critic predictions remain flat despite sharp Monte Carlo value changes across states, and propose SParse Proximal Policy Optimization (SP3O), which applies the value loss to only three well-separated states per response, mitigating this issue and consistently improving policy performance on Qwen3-Base.
Key Contributions
- Identifies and names Value Flattening, a failure mode in PPO critics for large language model reasoning where critic predictions remain flat despite sharp changes in state values estimated from multiple Monte Carlo continuations; the phenomenon is demonstrated in a controlled FrozenLake environment and becomes more pronounced as the state space grows.
- Attributes Value Flattening to two causes: an implicit variance penalty in the critic's mean squared error loss that discourages value differences across token positions, and redundant updates from temporally correlated states with similar gradients, supported by theoretical and empirical analyses.
- Introduces SParse Proximal Policy Optimization (SP3O), which supervises the critic at only a few well-separated states per response to mitigate both effects; experiments on Qwen3-4B-Base and Qwen3-8B-Base show SP3O mitigates Value Flattening and consistently improves actor performance across mathematical and out-of-distribution reasoning benchmarks.
Introduction
Reinforcement learning (RL) is used to train large language models (LLMs) for complex reasoning tasks that require long sequences of decisions. A key challenge in this setup is policy optimization, which needs fine-grained credit assignment: the model must know which intermediate steps helped or hurt the final outcome. Proximal Policy Optimization (PPO) handles this by using a critic network to estimate the value of each state and generate token-level advantages. For this to work, the critic must accurately reflect changes in expected success across different points in a response.
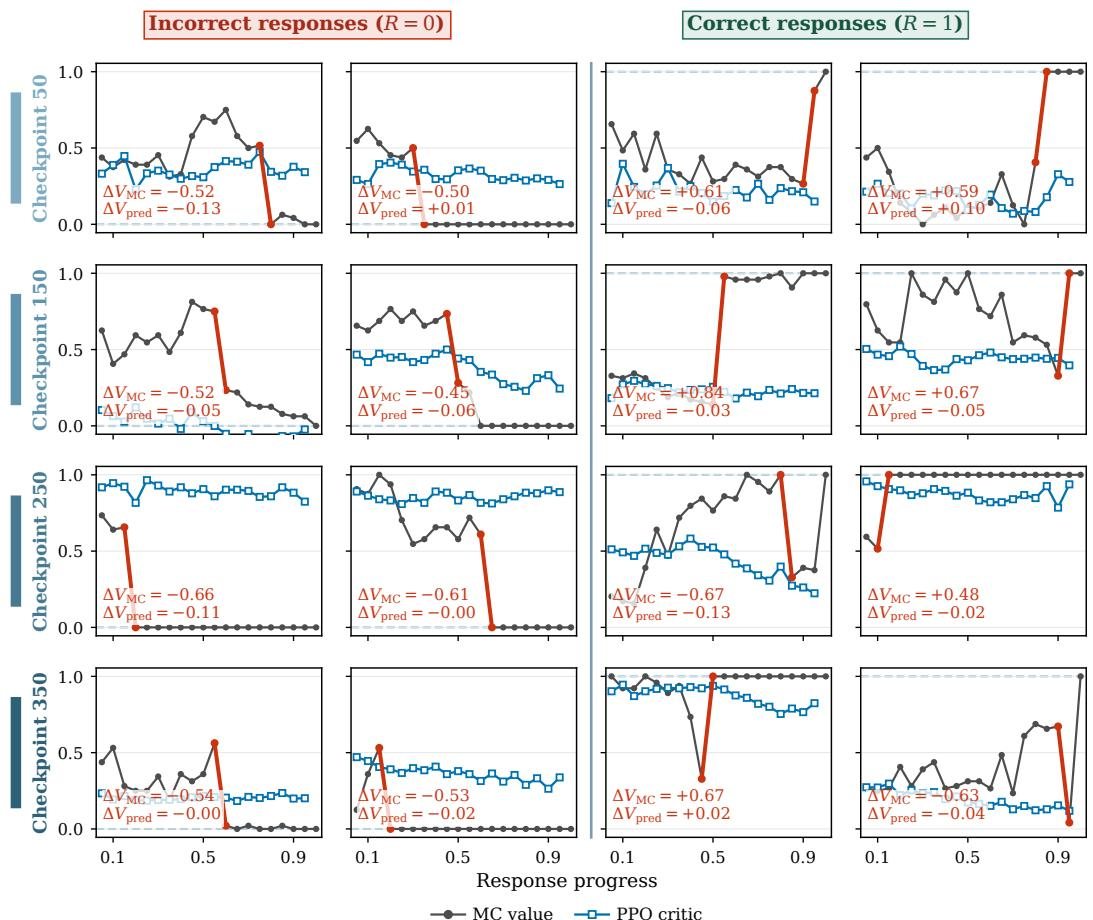
However, the authors find that PPO critics often fail at this task. They observe a phenomenon they call Value Flattening: the critic's predicted state values stay nearly constant within a response, even when the true expected return (estimated using Monte Carlo simulations of multiple continuations) changes sharply. This issue persists across training checkpoints and is present in both correct and incorrect responses, suggesting it is a learned property of the critic rather than an artifact of specific trajectories. In controlled FrozenLake experiments, the flattening becomes more severe as the state space grows.
The authors identify two contributing factors. First, the critic's mean squared error (MSE) loss, applied at every token position under standard PPO with terminal-only rewards, includes an implicit variance penalty that pushes predictions toward a flat value profile. Second, since neighboring states differ by only one token, they are highly temporally correlated, leading to similar gradients and redundant updates that further homogenize predicted values.
To address this, the authors propose SParse Proximal Policy Optimization (SP3O), which applies the critic loss at fewer, widely separated states. This restricts the variance penalty and reduces redundant updates. Experiments on Qwen3-4B-Base and Qwen3-8B-Base show that SP3O mitigates Value Flattening and consistently improves policy performance on mathematical and out-of-distribution reasoning benchmarks.
Method
The authors leverage Proximal Policy Optimization (PPO) as the foundational framework for aligning large language models. In this setup, a policy πθ generates a response y=(y1,…,yT) given a prompt x, forming a trajectory τ. The state at step t is defined as st=(x,y<t) and the action as at=yt. The framework employs a critic network Vϕ(st) to estimate the policy-conditioned state value. Under a terminal reward setting where rt=0 for t<T and rT=R(τ), the generalized advantage estimation targets simplify such that the critic regression target Gt equals the terminal return R(τ) for all t. The standard critic is trained by minimizing the mean squared error between its predictions and these targets across all token positions in the response.
However, the authors identify a critical failure mode in this standard approach termed Value Flattening. Despite Monte Carlo estimates of state values exhibiting sharp local transitions during reasoning, the critic's predicted value profile remains comparatively flat, failing to capture the magnitude and direction of these changes.
The authors attribute Value Flattening to two primary factors inherent in the standard training process. First, applying the mean squared error loss at every token position with a shared terminal target introduces an implicit variance penalty, which directly penalizes variation in the critic's predictions within a single response. Second, because adjacent states in an LLM trajectory differ by only one token, they are highly temporally correlated. Supervising all positions leads to redundant updates from neighboring states that produce aligned gradients, further suppressing value variation.
To mitigate these issues, the authors propose SParse Proximal Policy Optimization (SP3O). This method retains the standard actor objective and rollout procedure but fundamentally alters the critic supervision strategy. Instead of applying the value loss at every token, SP3O restricts the critic loss to a small, well-separated subset of states I(τ) within each trajectory. The sparse critic objective is formulated as:
LVSP3O(ϕ)=∑τ∈B∣I(τ)∣1τ∈B∑t∈I(τ)∑(Vϕ(st)−Gt)2By selecting fewer positions, the per-response variance penalty is restricted, and by spacing them apart, the accumulation of aligned gradients from highly correlated neighboring states is reduced.
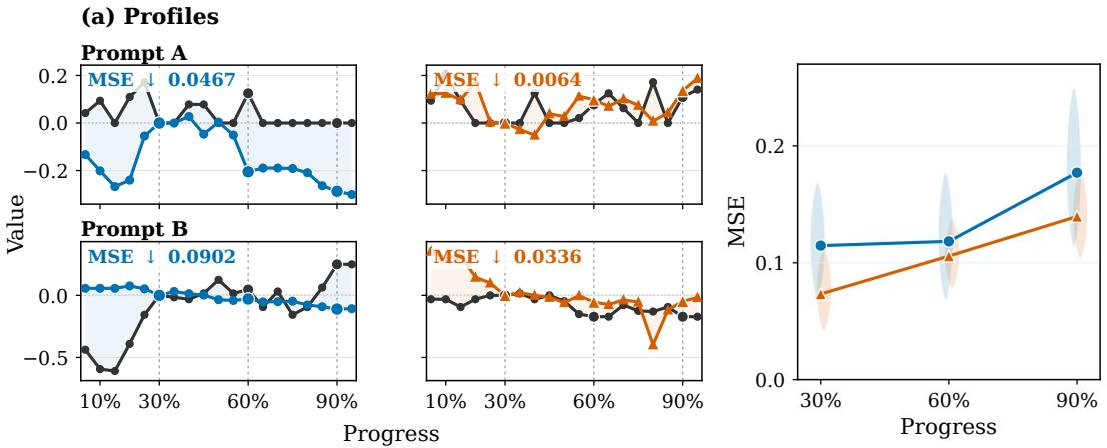
The impact of this sparse supervision is evident in both critic predictions and optimization dynamics. When compared to standard PPO, the SP3O critic more closely tracks the direction and magnitude of local changes in Monte Carlo values, significantly reducing the profile mean squared error across response progress.
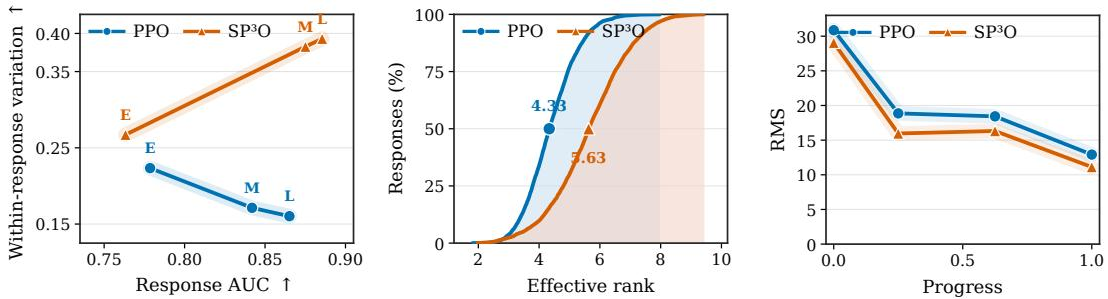
Furthermore, sparse supervision preserves richer hidden representations and reduces redundant updates. The SP3O critic achieves higher within-response variation while maintaining response-level outcome discrimination, and it shifts the effective rank of response-centered hidden states upward, indicating greater dimensional diversity. Additionally, it exhibits lower RMS discrepancy between value-head gradients induced by terminal-return targets and Monte Carlo values, leading to smoother actor optimization throughout training.
Experiment
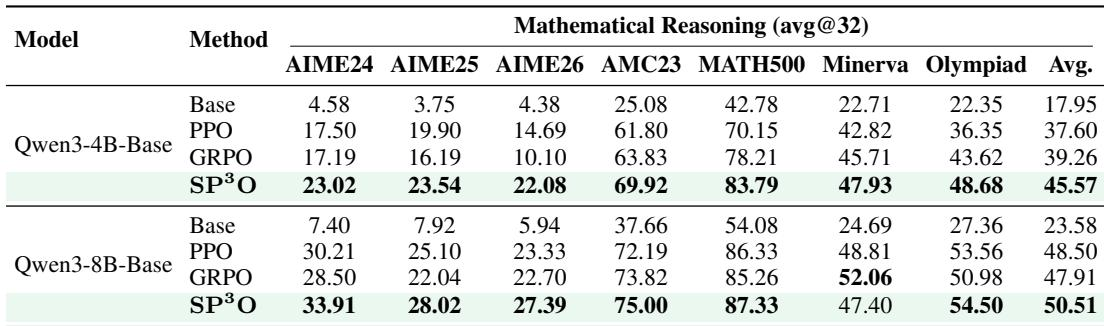
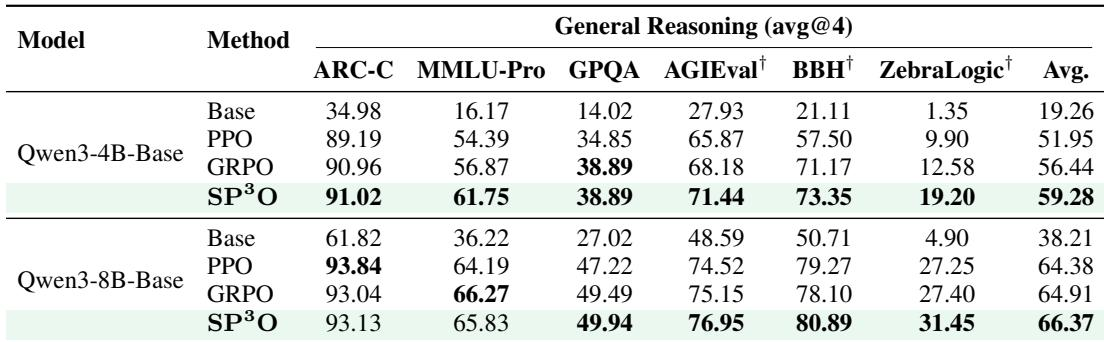
SP3O, which applies sparse critic supervision with explicit late-tail coverage, consistently outperforms standard PPO and GRPO on both in-domain and out-of-distribution reasoning benchmarks across Qwen3-4B-Base and Qwen3-8B-Base. Ablations show that a small number of well-spaced supervision anchors (K=3 to 8) yields better training rewards than denser supervision, and that fixed-position placement outperforms random placement. Adding a tail anchor specifically improves both final performance and generation stability by reducing repetition, indicating that mitigating critic value flattening enhances policy learning rather than just critic diagnostics.
The proposed method consistently improves in-domain mathematical reasoning accuracy over both PPO and GRPO baselines across two model sizes, with the largest gains observed on the Qwen3-4B model. The approach also yields more stable training dynamics, as indicated by smaller actor updates and higher validation accuracy compared to standard PPO. Sparse supervision with a few well-placed anchors appears to be more effective than dense supervision, and adding a tail anchor notably improves performance and reduces repetition. The method outperforms both PPO and GRPO on the average across seven mathematical reasoning tasks for both 4B and 8B models. The performance gain over PPO reaches nearly 8 percentage points on the in-domain average. Training with the method shows smaller and less variable actor updates than PPO, along with higher validation accuracy and rollout reward after the early stage. Sparse supervision with a small number of anchors (K=3 to 8) yields better training rewards than denser configurations or standard token-level critic supervision. Adding a final tail anchor improves the average score and drastically reduces generation repetition compared to omitting it.
SP³O consistently outperforms both PPO and GRPO on out-of-distribution reasoning tasks across two model sizes, with the largest gains over PPO. The method also leads to more stable training dynamics, characterized by smaller actor updates and improved validation accuracy compared to PPO. SP³O achieves the highest average accuracy on all six out-of-distribution tasks for both Qwen3-4B-Base and Qwen3-8B-Base. The improvement of SP³O over PPO is especially large on the ZebraLogic task, while gains on other tasks are more modest. SP³O shows consistent gains over GRPO, particularly on tasks like MMLU-Pro and AGIEval. Training with SP³O exhibits more stable policy updates and maintains higher validation accuracy than PPO after the early training phase.
This ablation study compares different anchor placement strategies for sparse-supervision training on Qwen3-4B-Base with K=3. Fixed-position anchor placements substantially outperform random placement in accuracy, and the fixed scheme with later anchors achieves the highest performance, highlighting the importance of well-spaced coverage of the trajectory. Random anchor placement yields the lowest accuracy among the compared schemes, underperforming both fixed-position placements. The fixed anchor placement at 0.2/0.5/0.8 improves accuracy by a large margin over the random baseline, from about 36.6% to 44.7%. Shifting the anchors later (0.3/0.6/0.9) further boosts accuracy to 45.6%, the best among all placement variants.
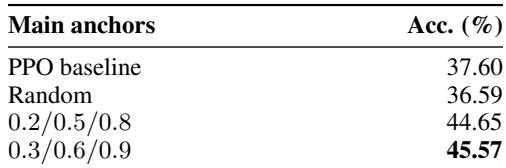
The proposed method consistently outperforms PPO and GRPO on both in-domain and out-of-distribution mathematical reasoning tasks across 4B and 8B models, with the largest gains over PPO, and it also yields more stable training dynamics as indicated by smaller actor updates and higher validation accuracy. Sparse supervision with a small number of well-placed anchors is more effective than dense supervision, and adding a final tail anchor substantially improves accuracy while reducing generation repetition. An ablation on anchor placement confirms that fixed-position schemes outperform random placement, with later anchors providing the best results.