Command Palette
Search for a command to run...
RayOrch: 파운데이션 모델 데이터 준비를 위한 계보 제어형 다중 입도 데이터플로우 프로그래밍 및 실행
RayOrch: 파운데이션 모델 데이터 준비를 위한 계보 제어형 다중 입도 데이터플로우 프로그래밍 및 실행
초록
파운데이션 모델을 위한 고품질 훈련 데이터를 준비하려면, 이질적인 문서나 비디오의 대규모 컬렉션을 구조화된 훈련 레코드로 변환하는 확장 가능한 파이프라인이 필요하다. 이러한 파이프라인은 처리 단위를 반복적으로 변경할 수 있다. 각 확장 단계에서 하나의 입력 항목(즉, 이 그래프의 부모 노드)은 순서가 있고 입력에 의존하는 출력 항목 시퀀스(데이터 계보 그래프에서는 그 자식으로 간주됨)를 생성하며, 부모들 간 자식 수의 분포는 롱테일(long-tail) 양상을 보인다. 반면, 특정 데이터 파이프라인 단계를 실행하는 GPU는 활용도를 극대화하기 위해 서로 다른 부모에서 나온 자식들을 배치로 묶어야 하며, 시스템은 각 결과를 해당 직계 부모에게 반환하고, 자식 순서를 보존하고, 필요한 모든 자식 결과가 종료 상태가 된 시점을 판정해야 한다. 기존 데이터 파이프라인 시스템은 대개 두 가지 불완전한 선택지 사이에서 선택한다. 거친 입도(coarse-grained) 함수는 각 문서나 비디오를 하나의 불투명한 작업으로 유지하여 병렬로 실행될 수 있는 페이지, 클립 또는 프레임을 감춘다. 평면 레코드(flat-record) 함수는 이러한 항목을 개별적으로 노출하지만, 응용 프로그램이 각 항목의 부모와 위치를 기억하고, 모든 항목이 완료된 시점을 추적하고, 원래 결과를 재구성하기 위해 레코드를 전역적으로 재그룹화하도록 강제한다. 이러한 문제를 해결하기 위해, 우리는 실행 전반에 걸쳐 이러한 부모-자식 관계를 유지하는 프로그래밍 모델이자 분산 실행 엔진인 RayOrch를 제안한다. 프로그램은 순서가 있는 가변 카디널리티의 부모-자식 확장과 각 부모 결과를 재구성하는 짝을 이루는 자식-부모 수집(gather)을 선언한다. 컴파일러는 각 확장-수집 쌍을 검증한다. 런타임에 RayOrch는 모든 확장의 구조적 계보를 기록한다: 구체적인 자식 집합, 각 자식의 직계 부모와 불변 서수(ordinal), 그리고 각 결과의 종료 상태이다. 호출별 FIFO 준비 큐(Per-Call FIFO Ready Queue)는 여러 부모에 걸쳐 준비된 자식들을 배치로 묶으며, 수집은 배치 경계나 완료 순서가 아니라 선언된 소속 관계와 서수를 사용한다. 따라서 부모는 필요한 모든 자식 결과가 종료 상태가 되는 즉시 자신의 결과를 확정하고 다음 단계로 진행할 수 있다. 어떤 호출(Call)이 타입화된 부모 범위(parent-scoped) 실패를 보고하면, RayOrch는 해당 호출에 대해 그 부모의 아직 디스패치되지 않은 형제 작업들을 억제하면서 관련 없는 부모들은 계속 진행하도록 허용한다. RayOrch의 설계를 검증하기 위해, 우리는 종합적인 평가를 수행한다. NVIDIA H20 GPU에서 RayOrch는 MinerU를 GPU 4개에서 64개로 확장할 때 처리 시간 기준 15.14배의 속도 향상을 달성하고, 비디오 파이프라인을 GPU 8개에서 64개로 확장할 때 7.82배의 속도 향상을 달성한다. MinerU에서 Ray Data 대비 종단 간 시간을 13.1%, Daft 대비 29.0% 단축하고, Docling에서 Ray Data 대비 16.0% 단축한다. FIFO 디스패치는 ablation 실험의 벽시계 시간을 634.1초에서 579.3초로 8.6% 단축한다. 제어된 장애 주입 실험에서 RayOrch는 23,514개의 비트리거(nontrigger) 형제 계산 중 6,241개가 UDF에 진입하는 것을 방지하고, 장애가 없는 대응 실행과 비교해 평균 벽시계 시간을 14.93% 단축하면서, 영향을 받지 않은 부모들에 대한 모든 기대 출력을 보존한다. 코드는 https://github.com/OpenDCAI/RayOrch 에서 이용할 수 있다.
One-sentence Summary
Researchers at Peking University and collaborating institutions propose RayOrch, a programming model and distributed execution engine for foundation-model data preparation that preserves parent-child lineage through ordered variable-cardinality expansions and matching gathers, supports per-call FIFO ready queues, declared membership and ordinals, and parent-scoped failure suppression, and achieves on NVIDIA H20 GPUs a 15.14× MinerU scaling speedup while outperforming Ray Data and Daft.
Key Contributions
- RayOrch introduces a programming model and Ray-based execution engine for finite, acyclic multi-grain dataflows, with compiler-validated ordered variable-cardinality parent-to-child expansions, matching parent-scoped gathers, and runtime-owned structural lineage tracking.
- Per-Call FIFO ready queues batch ready children across parents, while declared membership and ordinals resolve ordered gathers so a parent can finalize once all required child results are terminal. Typed parent-scoped failure containment suppresses undispatched siblings of a failed parent while unrelated parents continue.
- On NVIDIA H20 GPUs, RayOrch achieves a 15.14× processing-time speedup when scaling MinerU from 4 to 64 GPUs and a 7.82× speedup when scaling the video pipeline from 8 to 64 GPUs. It reduces end-to-end time by 13.1% versus Ray Data and 29.0% versus Daft on MinerU, by 16.0% versus Ray Data on Docling, and by 8.6% via FIFO dispatch; in failure injection it prevents 6,241 of 23,514 nontrigger sibling computations from entering the UDF, reduces wall time by 14.93%, and preserves all expected outputs for unaffected parents.
Introduction
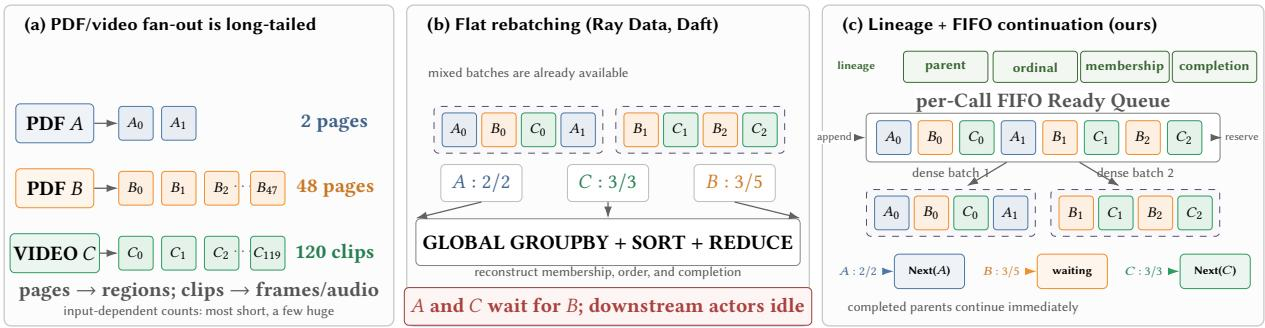
Foundation-model data preparation pipelines for layout-rich documents and long videos repeatedly change their unit of processing, such as documents producing pages, regions, and tables or videos producing clips, frames, and audio segments, so execution engines must expose fine-grained parallelism while preserving per-parent ordering and completion. Prior systems such as Spark, Dask, Ray Data, and Daft either keep parent-child structure implicit in coarse functions, hiding child-level parallelism and cross-parent batching, or flatten children into collections where parent keys and ordinals are only application fields, leaving completion and failure semantics to the application and often adding shuffle or regrouping barriers. The authors propose RayOrch, a programming model and Ray-based engine that declares ordered variable-cardinality expansions and parent-scoped gathers, maintains runtime structural lineage while physical batches remain transient, and uses immutable ordinals, generation-fenced commits, and typed parent-scoped failure containment to batch across parents without losing per-parent reconstruction or isolation.
Method
RayOrch exposes each pipeline through two complementary views: a logical view describing data units and structural transformations, and an execution view scheduling computations on available workers. The logical structure remains stable even as batching, retries, and worker placement change.
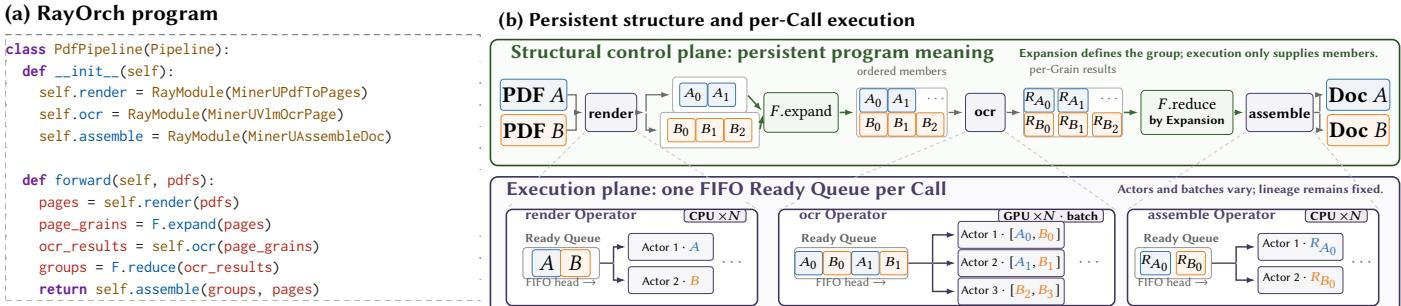
As shown in the figure above, panel (a) presents a concise, Torch-like user interface where a pipeline is defined as a Python class. For example, a PDF pipeline might declare rendering, OCR, and assembly stages. Panel (b) illustrates how this structure is executed. The upper plane shows the structural control plane, where operations like F.expand change the unit of computation (e.g., from PDF to Pages) and F.reduce reconstructs the document-level item. The lower plane shows the execution plane, where each configured Call becomes an Operator with a per-Call FIFO Ready Queue and a pool of workers. Ready Grains may be packed into transient physical batches, including batches that mix parents, which is an execution choice rather than a logical grouping.
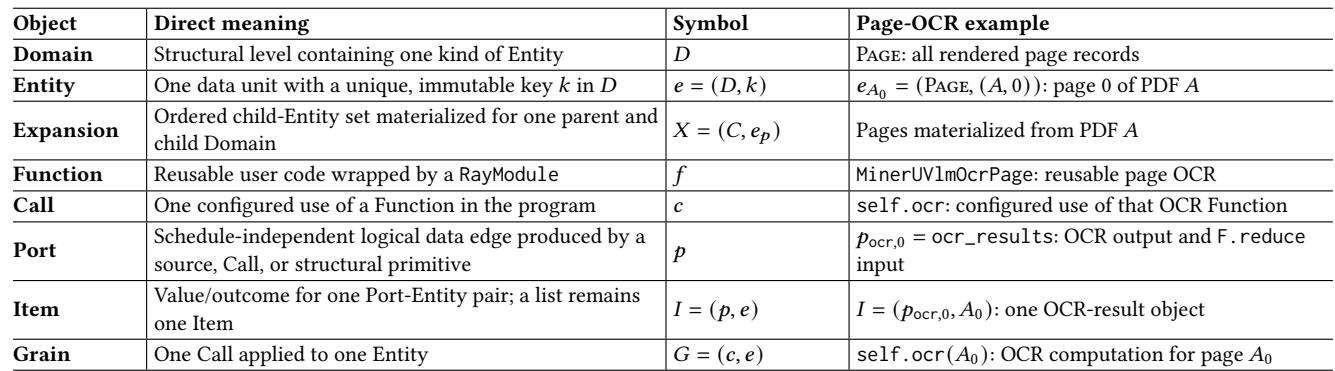
The authors represent the logical dataflow over hierarchical data units. A Domain names one level of the hierarchy, such as PDFs or Pages, and an Entity is one unit at that level. A Function is reusable user code, while a Call is one configured use of that function. Applying a Call to one Entity forms a Grain, the unit of computation. A declared Port carries logical values; the value for one Port and one Entity is an Item. The expansion relation is declared by the program, determining which child Entities belong to a parent and how they are reconstructed. This programming model is called a multi-grain dataflow, allowing users to express page-level or frame-level parallelism without manually maintaining child counts or grouping state.
The runtime compiles the symbolic DSL into an immutable graph after checking acyclicity and Domain compatibility. The graph contains Calls, Ports, Domains, consumers, and pre-indexed structural effects. For each child Domain and parent Entity ep, the runtime creates one Expansion X=(C,ep) containing the ordered child Entities materialized for that parent. Each logical object publishes exactly one terminal fact:
Entity: Published(e,ep), Item: Present(v)∣Dropped∣Failed∣Suppressed, Expansion: Succeeded(⟨e0,…,em−1⟩)∣Dropped∣Failed.Input propagation follows a fixed precedence: failed or suppressed input suppresses outputs; unresolved input waits; a dropped required input drops the output; otherwise the Grain becomes ready. The Reduce operation emits one parent Item only after its Expansion, every child-membership outcome, and every surviving value resolve.
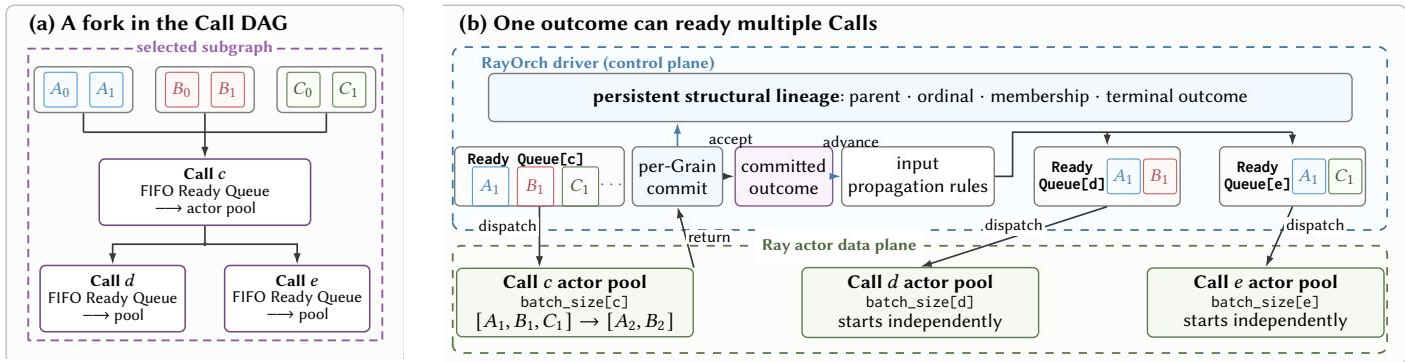
Refer to the framework diagram above for the scheduling mechanism. For each input microbatch, each Call owns one per-Call FIFO Ready Queue for READY Grains. It is an admission queue, not a grouping operation. As shown in panel (b), one committed outcome can activate multiple downstream Calls, whose Ready Queues dispatch independently rather than waiting for a stage-wide regrouping barrier. Resources, replicas, and batching scope are configured per Call. Elastic reservation removes at most k entries from the Ready Queue in O(k) and may mix parents. Parent-bound reservation takes up to k siblings of the first ready parent while preserving the relative order of all remaining queue entries. Both policies alter only the physical batch; Grain identity, membership, and reconstruction order remain unchanged. The physical Grain lifecycle follows:
WAITINGreadyREADYreserveIN-FLIGHTcommitSEALED, IN-FLIGHTretryREADY,WAITINGterminalSEALED.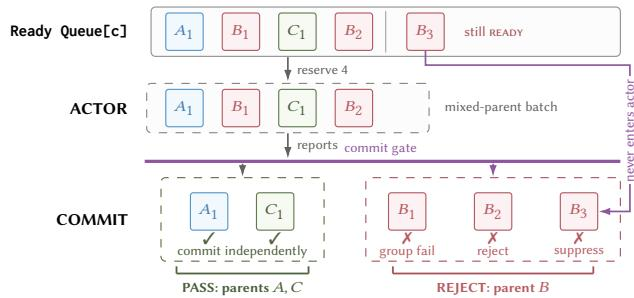
As illustrated in the figure above, the system separates logical commit from physical attempts. A typed RecordFailure is terminal for one Grain. A typed GroupFailure installs a local suppression barrier for one (Call, parent): queued siblings are suppressed before dispatch, in-flight siblings may finish but cannot commit, and already committed siblings remain untouched. Unrelated parents and queues remain live. An untyped UDF exception or infrastructure failure is instead a physical attempt failure. The runtime may retry the Grain or replace its actor and replay the Grain at a higher generation; these actions preserve Grain identity and change only the physical attempt. A report r commits only if its Grain is still in flight and its generation (the attempt number) is current:
Accept(r,G)⟺phase(G)=IN-FLIGHT∧r.grain=G∧r.generation=generation(G).An accepted report seals the Grain and publishes terminal facts atomically; the generation test rejects stale or duplicate reports.
RayOrch is implemented as a Python layer on Ray. Each configured Call is backed by a persistent Ray actor pool, while the driver retains the compiled plan, lineage metadata, and pending ObjectRefs. Payloads remain in Ray's object store; actor handles and references are physical execution state and never enter a Grain's logical identity. Each model stage is a Python class wrapped by RayModule and implements a batch UDF of the form List[Object] → List[Object]. The stage lifecycle follows the Torch module pattern: __init__ loads models and other heavyweight resources, whereas run performs the batch computation. Persistent actor instances amortize initialization across batches.
Experiment
The evaluation benchmarks RayOrch against Ray Data, Daft, native MinerU, and Docling Serve on document and video workloads using NVIDIA H20 GPUs, addressing end-to-end performance, scalability, scheduling, and failure containment. RayOrch achieves near-linear scaling and faster end-to-end performance by overlapping OCR with assembly and upload, avoiding the baselines' post-OCR regrouping tail. An ablation shows FIFO scheduling provides additional wall-time reduction beyond rebatching. A failure injection study confirms runtime-owned lineage suppresses doomed sibling work before UDF execution while preserving all expected healthy outputs.
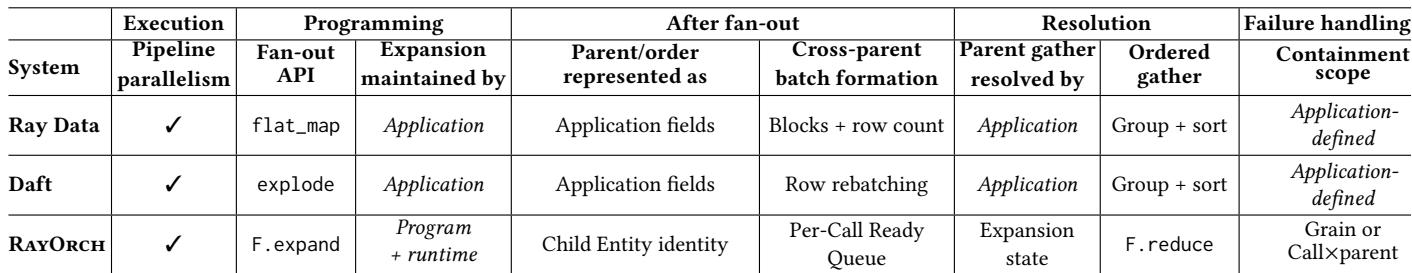
Ray Data and Daft rely on application-maintained expansion fields and group-and-sort operations to resolve ordered variable-cardinality fan-out, while RayOrch uses program-declared, runtime-maintained child identity and a per-call ready queue to preserve parent order. This runtime ownership lets RayOrch handle cross-parent batches through ready grains and scope containment to a grain or call-by-parent level, whereas the other systems use application-defined fields and containment. Reported experiments align with this contrast: RayOrch avoids the baselines' post-OCR regrouping tail, reduces wall time with FIFO scheduling, and suppresses doomed sibling work before execution. Ray Data and Daft maintain expansion and parent/order as application fields and resolve ordered gather with group-and-sort, while RayOrch uses child entity identity and a per-call ready queue. RayOrch is the only compared system with program-declared, compiler-validated, runtime-maintained expansion and containment scoped to grain or call-by-parent rather than application-defined scope. RayOrch completes parents locally and overlaps assembly and upload with OCR, avoiding the post-OCR regrouping tail seen in Ray Data and Daft. FIFO scheduling provides an additional wall-time reduction beyond rebatching, and lineage-scoped containment prevents doomed siblings from entering the UDF while preserving healthy outputs.
RayOrch represents pipelines as a logical dataflow over hierarchical data units. A Domain defines a structural level, an Entity is one keyed unit, and applying a Call to an Entity forms a Grain; Ports carry logical values and Items are values for one Port-Entity pair. In the PDF-to-page OCR example, expanding a PDF exposes ordered page entities, page-level OCR calls produce items, and reduction reconstructs document-level items in declared order. Domains, Entities, Functions, Calls, Ports, and Items form a schedule-independent logical model for hierarchical data processing. Expansion materializes ordered child entities for a parent, and reduction reconstructs parent-level items in the declared order rather than rediscovering groups from record fields.
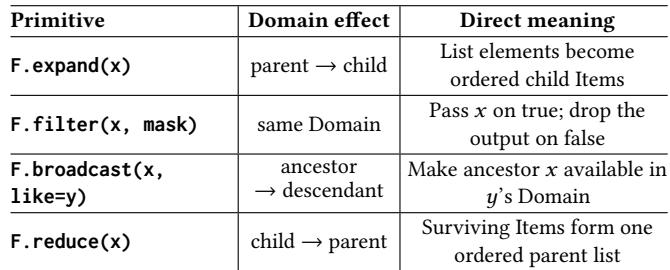
RayOrch's declarative structural DSL defines four primitives that move or filter data across Domains: expand, filter, broadcast, and reduce. Aligned variants preserve member alignment, and optional inputs affect propagation without adding a structural node. The compiler checks acyclicity and Domain compatibility before lowering the plan into an immutable graph, so the runtime consumes declared relations rather than inferring lineage. F.expand materializes an ordered child set, while F.reduce gathers surviving child items into one ordered parent list. F.filter changes membership within a Domain by passing items on true and dropping them on false. F.broadcast makes an ancestor item available in a descendant Domain. Together the primitives express hierarchical fan-out without arbitrary joins or regrouping, and invalid cross-Domain uses fail before execution.
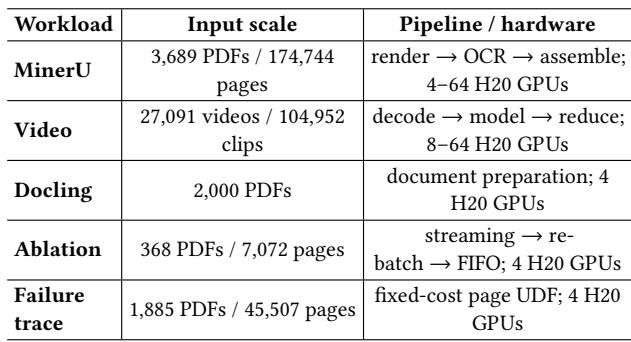
The evaluation spans five workload types: large-scale PDF processing, video processing, document preparation, scheduling ablation, and failure tracing. PDF and video workloads run on NVIDIA H20 GPU clusters scaling up to 64 GPUs, while ablation and failure studies use smaller inputs on four GPUs. The configurations use fixed software versions and shared baseline systems such as Ray Data and Daft. MinerU runs a render-OCR-assemble pipeline across thousands of PDFs and pages on 4 to 64 H20 GPUs. Video processing uses a decode-model-reduce pipeline over tens of thousands of videos and clips on 8 to 64 H20 GPUs. Docling, ablation, and failure trace experiments use smaller workloads and four H20 GPUs to isolate document preparation, scheduling, and failure containment behavior. Ray Data and Daft serve as common baselines, with native MinerU and Docling Serve used where applicable.
On a 64 NVIDIA H20 GPU MinerU workload, RayOrch records the lowest end-to-end time and highest throughput among the compared systems. It reduces wall time by roughly 13%, 29%, and 52% relative to Ray Data, Daft, and native MinerU, with corresponding throughput gains of about 15%, 41%, and 107%. These gains are attributed to overlapping OCR, assembly, and upload stages and avoiding a post-OCR regrouping tail. RayOrch achieves the best 64-GPU MinerU result, finishing faster than Ray Data, Daft, and native MinerU while processing the highest number of pages per second. Relative to the baselines, RayOrch lowers end-to-end time by approximately 13%, 29%, and 52%, and raises throughput by about 15%, 41%, and 107%. RayOrch overlaps OCR, assembly, and upload work, and parent-local commits help avoid the global regrouping tail seen in Ray Data and Daft.
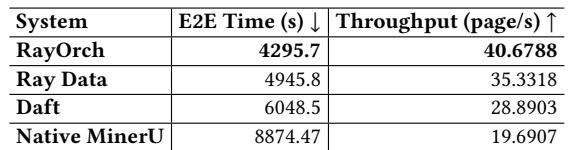
The experiments evaluate RayOrch against Ray Data, Daft, and native MinerU across large-scale PDF and video pipelines, document preparation, scheduling ablations, and failure tracing on NVIDIA H20 clusters. RayOrch relies on declared hierarchical primitives and runtime-maintained child identity with a per-call ready queue, while the baselines manage ordered fan-out through application-defined fields and group-and-sort operations. On the 64-GPU MinerU workload, RayOrch achieves the lowest end-to-end time and highest throughput, reducing wall time by roughly 13%, 29%, and 52% relative to Ray Data, Daft, and native MinerU, with throughput gains of about 15%, 41%, and 107%. The reported gains come from overlapping OCR, assembly, and upload work, avoiding a post-OCR regrouping tail, using FIFO scheduling, and applying lineage-scoped containment to prevent doomed sibling work before execution.