Command Palette
Search for a command to run...
MiniMax-H3는 물리 세계를 추론할 수 있는가? 옴니모달 생성 모델 평가
MiniMax-H3는 물리 세계를 추론할 수 있는가? 옴니모달 생성 모델 평가
초록
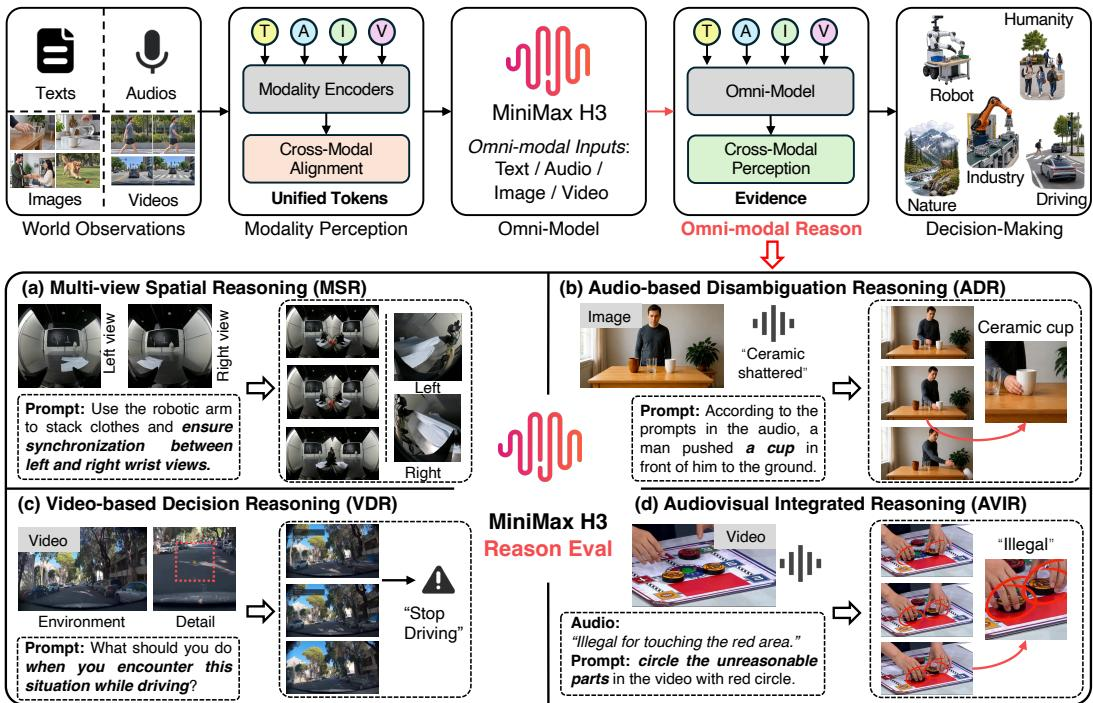
최근 옴니모달 생성 모델(Omni-Models)은 텍스트, 이미지, 비디오, 오디오의 통합 모델링으로 콘텐츠 생성을 발전시켜 왔다. MiniMax-H3는 공유 잠재 프레임워크에서 다중모달 맥락 이해와 오디오-비주얼 동시 생성을 결합함으로써 이러한 전환을 잘 보여준다. 이러한 통합 아키텍처는 근본적인 질문을 제기한다. 다중모달 정렬이 모델의 세계 추론 능력을 향상시킬 수 있는가? 그리고 옴니모달 입력은 어떤 새로운 평가 패러다임을 가능하게 하는가? 이 질문을 탐구하기 위해, 본 연구는 물리 세계 추론의 상호 보완적인 네 가지 차원으로 구성된 종합 평가 프레임워크를 제안한다. 기존 비디오 생성 및 세계 모델 평가 프레임워크는 입력 모달리티가 제한적이고 프롬프트가 대상 비디오 내용과 밀접하게 일치하는 평가 설정에 제약되는 경우가 많다. 반면, 본 평가는 Omni-Model의 다중모달 입력을 활용하도록 특별히 설계되었다. 우리는 모델이 여러 모달리티에 걸쳐 상호 보완적인 정보를 통합하도록 요구하는 다양하고 새로운 과제들을 구성한다. 구체적으로, 여러 프레임과 짝지어진 암시적 프롬프트, 오디오-이미지, 프리픽스 비디오(prefix-videos), 오디오-비디오 입력을 포함한 네 가지 시나리오를 고려한다. 각 단일 모달리티는 기저 사건에 대한 부분적 증거만을 제공하므로, 모델은 잠재 사건 상태와 미래 동역학을 추론하기 위해 상호 보완적인 의미 단서들을 함께 추론해야 한다. 517개의 평가 인스턴스에서 MiniMax-H3는 전체 성공률 41.97%를 달성했다. 비디오 기반 의사결정 추론(Video-based Decision Reasoning)이 56.00%로 가장 높은 성공률을 보인 반면, 오디오 기반 모호성 해소 추론(Audio-based Disambiguation Reasoning)은 27.40%에 그쳐 가장 낮았다. 이러한 결과는 다양한 입력 모달리티의 이점을 온전히 활용하려면 효과적인 다중모달 통합이 여전히 핵심임을 시사한다. 프로젝트는 https://github.com/gulucaptain/MiniMax-H3-Reason 에서 이용할 수 있다.
One-sentence Summary
Researchers from the National University of Singapore, Fudan University, and Tencent introduce a four-dimensional physical-world reasoning evaluation for the omni-modal generative model MiniMax-H3 that exploits multimodal inputs including implicit prompts paired with multiple frames, audio-image inputs, prefix-videos, and audio-video inputs; across 517 evaluation instances, MiniMax-H3 attains an overall success rate of 41.97%, with video-based decision reasoning achieving 56.00% and audio-based disambiguation reasoning achieving only 27.40%, indicating that effective multimodal integration remains key to fully exploiting diverse input modalities.
Key Contributions
- The paper introduces a comprehensive evaluation framework for physical-world reasoning in omni-modal generative models, covering four complementary input settings: implicit prompts with multiple frames, audio-image pairs, prefix videos, and audio-video inputs.
- It contributes a benchmark of 517 evaluation instances where each modality provides only partial evidence, requiring the model to jointly reason over complementary semantic cues to infer latent event states and future dynamics.
- Experiments with MiniMax-H3 report an overall success rate of 41.97%, with video-based decision reasoning at 56.00% and audio-based disambiguation reasoning at 27.40%, indicating that effective multimodal integration remains a key limitation.
Introduction
Omni-modal generative models such as MiniMax-H3 can condition generation on text, images, audio, and video at once, making it possible to study whether models can infer physical events from complementary but incomplete evidence. Existing video and world-model benchmarks usually describe the target event explicitly in the prompt, so additional modalities are often redundant and the evaluation mostly measures instruction-following rather than cross-modal reasoning. The authors introduce an implicit generation evaluation framework in which critical event semantics are omitted from the text and distributed across multiple input modalities, forcing the model to align partial observations and recover the intended event before generating a video. They build an expert-verified set of 517 instances across four reasoning scenarios: multi-view spatial reasoning, audio-based disambiguation, video-based decision reasoning, and audiovisual integrated reasoning. Evaluating MiniMax-H3 on this benchmark yields an overall success rate of 41.97%, exposing a notable gap between supporting omni-modal inputs and reliably using them for physical-world reasoning.
Dataset
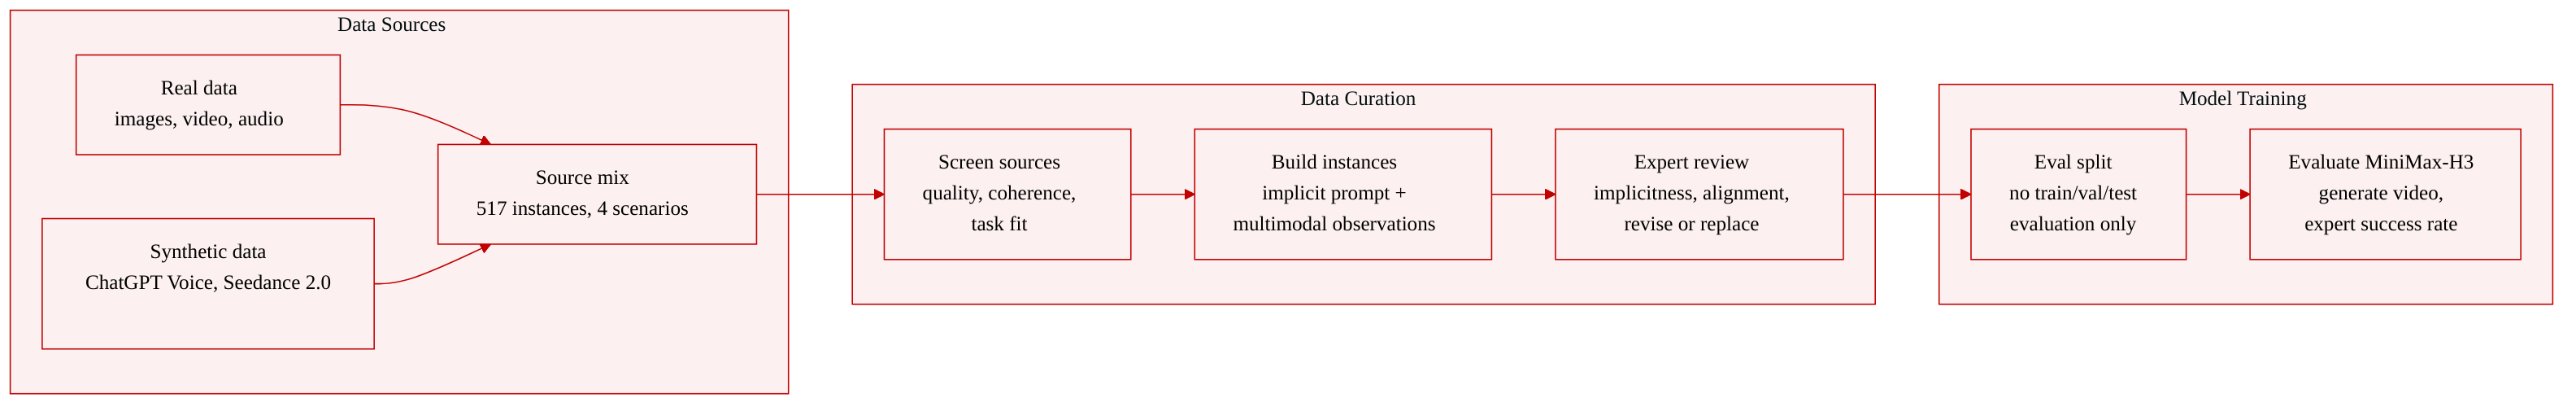
The authors construct an evaluation dataset, not a training corpus, for multimodal physical-world reasoning.
Key composition
- 517 instances across 4 scenarios and 29 subcategories.
- Scenario counts: MSR 200 instances/10 subcategories, ADR 146/6, VDR 100/8, AVIR 71/5.
- Each instance is stored as (qi,xi,τi): implicit prompt qi, multimodal observations xi, and scenario label τi.
Sources
- Real and synthetic visual and acoustic data, including images, videos, audio recordings, and generative clips.
- Synthetic sources include ChatGPT Voice for audio and Seedance 2.0 for video.
- Real/source datasets include HiFi-UMI-2K, VISTA-UMI 5K, HuMI-Unsheathe, Hy-Embodied-0.5-VLA-Data, and 10Kh-RealOmin-OpenData for multi-view visuals; LLaVA Video-178K for video; and FSD50K and ESC-50 for audio.
- Sources are screened for perceptual quality, semantic coherence, and task suitability. Sources with visual artifacts or unclear event structure are excluded.
Subset profiles
- MSR: household manipulation with multi-view observations, large viewpoint changes, and partial occlusions.
- ADR: static image plus audio, where audio helps identify which event occurs among multiple plausible object-sound interpretations.
- VDR: video-prefix continuation over human activities, animal motion, physical interactions, scene changes, and object dynamics.
- AVIR: video with environmental audio or spoken instructions for audio-guided continuation and visual inconsistency detection.
Processing and metadata
- Observations vary by scenario: multiple images, image paired with audio, video prefix, or video prefix/complete video plus audio.
- Prompts are designed to be implicit: text alone should not reveal the target, while observations provide sufficient evidence.
- ChatGPT and Qwen3 generate candidate prompt formulations, which experts then edit and verify.
- Each condition-prompt pair goes through iterative expert review for scene complexity, inferential richness, condition alignment, and prompt implicitness. Failed pairs are revised by prompt adjustment or input replacement.
- The provided text does not describe a cropping strategy, training split, or training mixture ratios.
Use in model evaluation
- The dataset is used for evaluating MiniMax-H3 rather than for training.
- Accepted condition-prompt pairs are verified through video generation for MiniMax-H3.
- Three independent experts evaluate each generated video and cross-check judgments. Success is based on whether the output satisfies the task requirement, not on matching a single reference video.
- The main metric is success rate (SR), computed as the percentage of samples judged successful per category and overall.
Method
The authors present a systematic evaluation pipeline for Omni-Modes, focusing on assessing the physical-world understanding and reasoning capabilities of MiniMax-H3. Unlike earlier generative models that primarily condition on images and text, MiniMax-H3 supports compositional inputs across multiple modalities. To evaluate this capability, the authors construct a comprehensive dataset through a multi-stage process involving multimodal source collection, task-specific instance construction, and iterative human review.
As shown in the figure below:
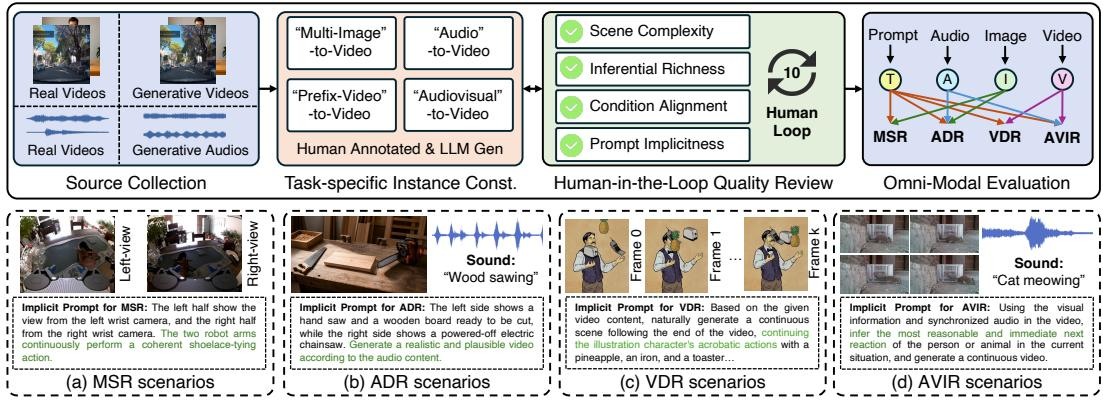
The data construction pipeline begins with source collection, where the authors gather real and synthetic visual and acoustic data. This includes images, videos, audio recordings, and clips produced by generative models. These sources are screened for perceptual quality, semantic coherence, and suitability for the intended task. Sources with visual artifacts or unclear event structures are excluded to ensure the evidence required for evaluation remains intact.
Following source collection, the authors construct task-specific instances. Each instance pairs multimodal observations with an implicit task prompt and an annotated semantic target. The inputs are organized into four reasoning scenarios: Multi-View Spatial Reasoning (MSR), Audio-Disambiguated Reasoning (ADR), Video-Continuation Reasoning (VDR), and Audiovisual-Inference Reasoning (AVIR). For example, in MSR, multiple views of a scene provide complementary evidence for a spatial relation. In ADR, an audio clip helps distinguish among plausible interpretations of a static image.
To ensure the model must rely on multimodal inference rather than textual cues, the authors employ large language models to generate implicit prompts. These prompts specify the requested generation operation but withhold the task-relevant information, which must be inferred from the observations. The prompt construction adheres to two criteria: the text alone should not disclose the target interpretation, and the multimodal inputs must provide sufficient evidence to infer the generative results.
The constructed condition-prompt pairs then undergo a rigorous 10-loop expert review process. Reviewers evaluate each pair across four dimensions: scene complexity, inferential richness, condition alignment, and prompt implicitness. Pairs that fail the review are revised by adjusting the prompt or replacing the input conditions and then reassessed.
After data collection, filtering, and human verification, each accepted instance is represented as Ei=(qi,xi,τi), where qi denotes the implicit task prompt, xi contains the input observations, and τi∈{MSR, ADR, VDR, AVIR} identifies the reasoning scenario.
As shown in the figure below:
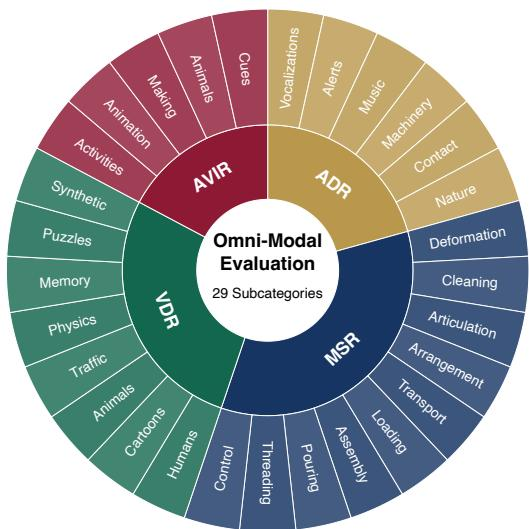
The final evaluation set encompasses 4 domains and 29 subdomains, totaling 517 paired conditions. This structured dataset ensures that the evaluation effectively measures the model's ability to integrate complementary cross-modal evidence for reliable physical-world reasoning.
Experiment
This work evaluates MiniMax-H3 as a representative omni-modal generative model on 517 expert-reviewed instances spanning four physical-world reasoning tasks: multi-view spatial reasoning, audio-based disambiguation, video-based decision, and audiovisual integrated reasoning. The setup tests whether text, image, video, and audio inputs can be combined so the model infers unspoken constraints and expresses them through video generation, continuation, or editing, with human raters judging task satisfaction rather than reference similarity. Qualitatively, the model often produces visually plausible outputs and follows dominant input cues, but its reliability remains limited, performing best on video continuation and worst on audio-grounded disambiguation. Recurring failures include incorrect evidence grounding, incomplete event realization, physical or configurational violations, and temporal inconsistency.
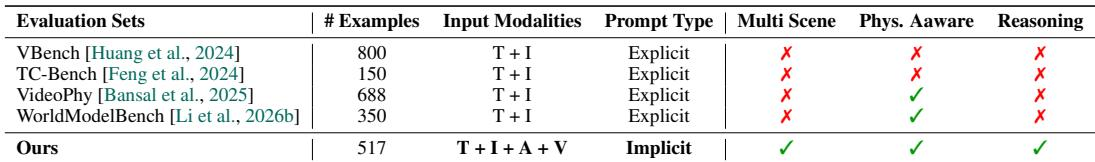
Existing evaluation benchmarks primarily rely on explicit text and image conditioning, and none combine multi-scene understanding, physical awareness, and multimodal reasoning. The proposed evaluation instead uses text, image, audio, and video inputs with implicit prompts, requiring models to infer missing event semantics from distributed multimodal evidence. This enables assessment of multi-scene understanding, physical awareness, and reasoning through generated video. Most prior benchmarks use only text and image inputs with explicit prompts and do not test multi-scene understanding or multimodal reasoning. Some prior benchmarks include physical awareness, but they still rely on explicit text-image conditioning and do not require reasoning across audio and video evidence. The proposed benchmark accepts text, image, audio, and video inputs with implicit prompts and is the only listed benchmark that covers multi-scene understanding, physical awareness, and reasoning together. Because prompts are implicit, generated video serves as a behavioral readout of whether the model recovered the missing event semantics rather than followed an explicit instruction.
Across 517 samples, MiniMax-H3 reaches an overall success rate of 41.97%. Video-based continuation is the most reliable scenario and audio-dependent reasoning the least reliable, with a large gap between them. Subcategory results are uneven, with strong traffic dynamics but much weaker outcomes on cartoons, puzzles, machinery, and contact sounds. Video-based continuation leads all four scenarios, while audio-dependent reasoning ranks lowest. Within video-based continuation, traffic dynamics are handled consistently well, but cartoons and puzzles show much lower success rates. Manipulation tasks vary considerably, with threading and pouring more reliable than cleaning, articulation, and transport.
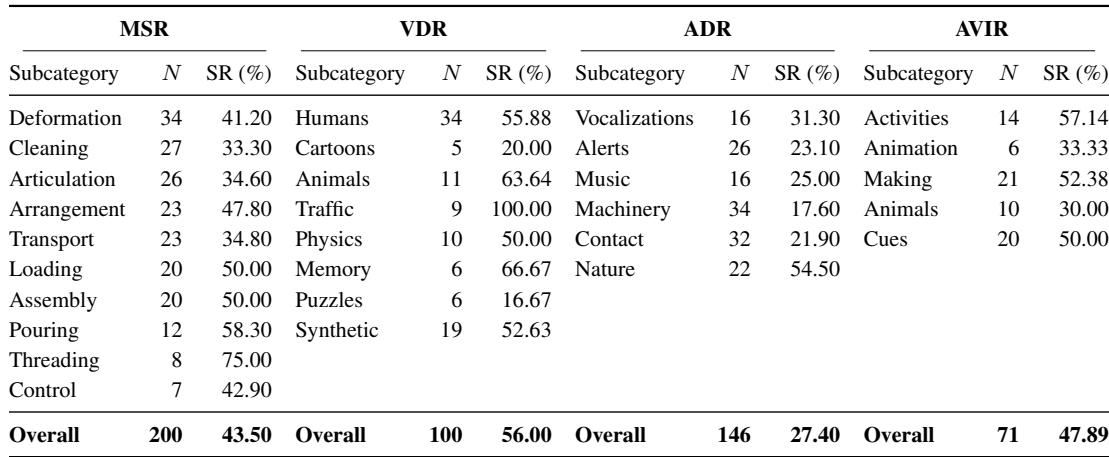
The proposed benchmark evaluates multimodal generation using text, image, audio, and video with implicit prompts, requiring models to infer missing event semantics and demonstrate multi-scene understanding, physical awareness, and reasoning through generated video. This differs from prior benchmarks that rely mainly on explicit text-image conditioning. In experiments, MiniMax-H3 is most reliable on video-based continuation and least reliable on audio-dependent reasoning, with uneven performance across subcategories such as stronger traffic dynamics but weaker cartoons, puzzles, machinery, and contact sounds. Overall, the results show that implicit multimodal reasoning remains challenging, particularly when it depends on audio evidence.