Command Palette
Search for a command to run...
자신감은 경험에서 나온다: 추론에서 에이전트까지의 경험적 자신감 추정
자신감은 경험에서 나온다: 추론에서 에이전트까지의 경험적 자신감 추정
Caiqi Zhang Xiaochen Zhu Chengzu Li Yulong Chen Dharshan Kumaran Nigel Collier
초록
신뢰할 수 있는 자신감 추정은 언어 모델의 신뢰할 수 있는 배포에 점점 더 중심이 되고 있다: 출력이 정확할 확률에 대한 보정된 추정치는 무엇을 출시하고, 무엇을 에스컬레이션하며, 무엇을 재시도할지를 결정한다. 그러나 기존의 자신감 추정기들은 공통된 설계 전제를 공유한다: 그들은 현재의 추론 과정만을 읽으며, 이를 내성적으로 검토하거나, 토큰 확률을 점수화하거나, 재표본화한다. 우리는 현재의 추론만으로는 자신감의 충분한 근거가 될 수 없다고 주장한다. 우리는 XConf(eXperiential Confidence)를 제안한다: 모델의 축적된 경험과 함께 자신감을 추정하는 방법이다. 경험은 모델 자신의 등급이 매겨진 과거 에피소드들의 기록으로 저장되며, 각 에피소드는 과제, 모델의 반성, 표명된 자신감, 결과, 그리고 등급이 도착한 후 작성된 교훈을 포함한다. 새로운 과제가 주어지면, XConf의 회상 단계는 유사한 과제에서 유사한 표명된 자신감과 마주친 과거 에피소드를 검색하고, 그들의 역사적 성공률을 읽는다; 반성 단계는 모델에게 이 기록을 보여주고, 반복되는 실패 모드를 명명하게 하며, 자신의 이력에 의해 정보를 얻은 자신감을 다시 진술하게 한다. 우리의 추정기는 형식에 구애받지 않으며, 로짓 접근이나 가중치 업데이트가 필요 없고, 단 한 번의 답변 생성만을 요구한다. 추론, 코딩, 멀티모달 QA, 그리고 대화형 에이전트를 포괄하는 9개의 벤치마크와 3개 패밀리의 4개 모델에 걸쳐, XConf는 24개의 비교 중 23개에서 판별력(AUROC)에 있어 10회 표본 자기 일관성을 능가하거나 일치하며, 훨씬 낮은 보정 오차(ECE)를 달성하고, 생성 비용은 10분의 1에 불과하다. 선택적 예측에 사용될 때, 가장 자신 없는 10%의 에피소드를 기권하면 에이전트 과제에서 전달 성공률이 최대 8.7포인트 향상된다. 따라서 우리는 경험적 자신감 추정을 미래의 범용 자신감 추정을 위한 새로운 패러다임으로 본다.
One-sentence Summary
Researchers at University of Cambridge and Google DeepMind propose XConf, an experiential confidence estimator that augments the current inference with graded past episodes via Recall and Reflect stages, matching 10-sample self-consistency in AUROC on 23/24 benchmark comparisons at a tenth of the generation cost and improving delivered success rates by up to 8.7 points in agent tasks.
Key Contributions
- Introduces XConf (eXperiential Confidence), a training-free confidence estimator that grounds uncertainty in a stored experience bank of graded past episodes, using a Recall stage to retrieve similar episodes and a Reflect stage to reread historical success rates and named failure modes before restating confidence.
- Requires no logit access or weight updates, costs only one answer generation, and remains format-general; across nine benchmarks (reasoning, coding, multimodal QA, interactive agents) and four models, XConf matches or beats ten-sample self-consistency in AUROC on 23 of 24 comparisons, with lower ECE and at one-tenth the generation cost.
- Demonstrates the confidence signal derives from stored experience, as permuting stored outcomes destroys the estimate, removing the record eliminates the gain, and enlarging the record improves calibration; abstaining on the 10% least-confident episodes raises delivered success rate by up to 8.7 points on agent tasks.
Introduction
Large language models are increasingly deployed in high-stakes settings such as code generation, browser automation, and agentic decision making, where incorrect outputs can have severe consequences. This makes reliable confidence estimation critical: it determines when to ship, escalate to a human, or retry. Existing confidence estimators all rely solely on the current inference process, whether through verbalized introspection, token likelihood scoring, or consistency across resampled outputs. None of these methods consult the model's past experience, despite decades of human metacognition research showing that people calibrate judgments partly by recalling how similar tasks turned out before. A student trusts a determinant solution without rechecking because similar problems have always worked, and braces for failure on a combinatorial proof because such proofs often collapsed previously; neither judgment comes from re-inspecting the derivation itself.
The authors propose XConf, a black-box, training-free, and format-general confidence estimator that leverages the model's accumulated experience rather than the current inference alone. XConf maintains a record of graded past episodes, each storing the task, the model's reflection, its stated confidence, and the outcome. For a new task, Recall retrieves similar episodes and computes the observed frequency of success given similar confidence levels, correcting habitual miscalibration mechanically. Reflect then shows the model its own track record, asks it to identify recurring failure modes, and has it restate confidence accordingly. Evaluated on nine benchmarks covering reasoning, coding, multimodal QA, and interactive agents, XConf matches or beats ten-sample self-consistency in discrimination while achieving much lower calibration error, with the largest gains on coding and agentic tasks. The approach also shows that experience transfers across datasets and models, improves as the record grows, and yields selective prediction gains of up to 8.7 points when abstaining on the least confident episodes, highlighting a shift from reading current inference to learning from accumulated experience.
Method
The authors introduce XConf, a confidence estimator that lets a model consult its own graded past before committing to a confidence. The central idea is that each piece of experience is read twice: a statistical read and a verbal read. The Recall stage treats the past as data, computing a confidence-conditioned hit rate over similar episodes, while the Reflect stage presents those episodes back to the model as text, so that the stated confidence is informed by the model's own track record rather than produced in isolation.
Problem formulation. The estimator operates on episodes collected during normal operation. Each episode is defined as
e=(x,ρ,a,r,v,y),where x is the task, ρ is the reasoning trace or rollout, a is the output, r is a short self-reflection written before grading, v∈ is the confidence stated at the end of the episode, and y∈{0,1} is the graded outcome. The experience bank B={e1,…,en} stores past episodes, with only those graded before the current one visible at test time. A confidence estimator is a map
c^=f(x,ρ,a,r,v;B),and the target is the calibrated probability P(y=1∣x,a). The key distinction is the dependence on B: existing estimators are trace-intrinsic, of the form c^=g(x,ρ,a), whereas XConf consults the bank through retrieval.
The experience bank. Each stored episode has five fields: the task, the model's reflection on its own solution (written before the outcome is known), the stated confidence, the graded outcome, and a one-time lesson written by the model itself once the grade arrives. The lesson is quarantined to the bank and is never shown to the model while it reflects on an ungraded solution, since outcome knowledge biases self-judgment in ways that instructions alone do not remove. The bank is a by-product of running the system rather than a separate data collection effort: these episodes were going to be graded anyway, during development, evaluation, or deployment with delayed feedback, and embedding them is offline and amortized. The same five fields describe a multiple-choice answer, a program, or a thirty-step rollout alike.
Recall: a confidence-conditioned hit rate. The Recall stage answers a single question: among past episodes similar to this one, on which the model stated a similar confidence, how often was it actually right? Each episode is keyed by two fields,
F(e)=[taskembeddingϕ(x);statedconfidencev],where ϕ is a frozen off-the-shelf embedder. To ensure that "similar" means fails for the same reasons rather than shares a topic, similarity is measured in a correctness-supervised rescaling of this space, fit on the bank's own graded episodes. Recall retrieves the k bank episodes nearest in this space, Nk(e), and reads off their outcome hit rate,
RECALL(e)=k1j∈Nk(e)∑yj,k=50,which is the model's historical accuracy on similar tasks met with a similar feeling. When the bank is sparse around the current task, the estimate degrades gracefully rather than failing: the k retrieved episodes are then only weakly similar, and the hit rate relaxes toward the model's base success rate at that stated confidence, a coarse but honest prior.
Reflect: reading one's own track record. The Reflect stage lets the model read its own past, lessons included. The episodes Recall retrieved are rendered as short in-context cards, one per episode: a task summary, the stated confidence at the time, the outcome, and the lesson. Shown the current task, its own reflection, and these cards, the model is asked first to name any recurring failure mode the record reveals, and only then to restate a calibrated confidence. Reflect is a short prompt that does not re-solve the task.
Final estimate. The final confidence averages the two readings of the same record, one statistical and one verbal:
Confidence(e)=21(RECALL(e)+REFLECT(e)).The equal weighting follows the long-standing finding that an equal-weight blend of two imperfectly correlated judges is hard to beat.
Experiment
The evaluation spans four models across nine benchmarks covering reasoning, multimodal QA, code, and interactive agent tasks, using a frozen embedder as a model-agnostic retrieval key. The proposed method, XConf, outperforms or matches ten-sample self-consistency on nearly all comparisons at a tenth of the generation cost, with consistently lower calibration error, and transfers effectively across task families without modification. Gains are largest where introspective signals fail, such as agent rollouts with silent failures, where XConf beats even a trained verifier without any training. The method scales with experience, improves selective prediction by allowing reliable abstention on low-confidence episodes, and remains robust across model sizes and bank transfers, though it degrades when outcome labels are self-generated rather than externally graded.
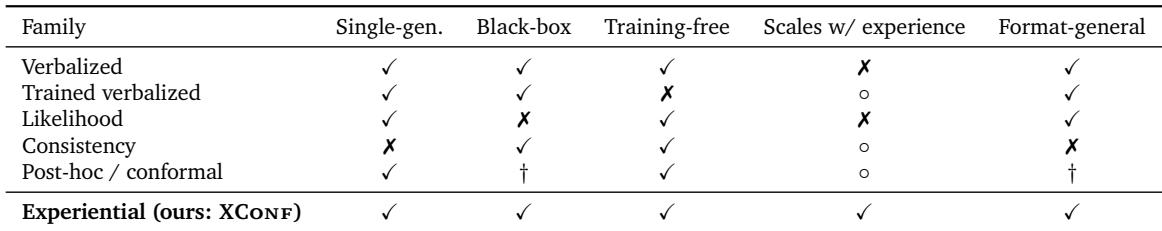
The table compares estimator families by their operational properties, showing that the proposed experiential estimator uniquely combines single-generation, black-box, training-free, and experience-scaling capabilities while remaining format-general. Experiment excerpts validate this design, demonstrating that experience-based estimates remain effective beyond difficulty controls, are robust to model size reductions, and require only independent outcome labels rather than model self-judgments. The experiential estimator is the only family that is single-generation, black-box, training-free, scales with experience, and works across formats. With question difficulty held constant, the experience-based estimate still separates correct from incorrect attempts at 0.79 AUROC, above chance in 35 of 36 cells. The estimate remains stable across model sizes, while only the self-reflective verbal reading degrades on smaller models. Using an independent judge's labels preserves most of the method's value, but using the model's own self-generated labels fails entirely. Stated confidence and reflective state are the most important elements for retrieval, with semantic retrieval greatly outperforming random neighbors.
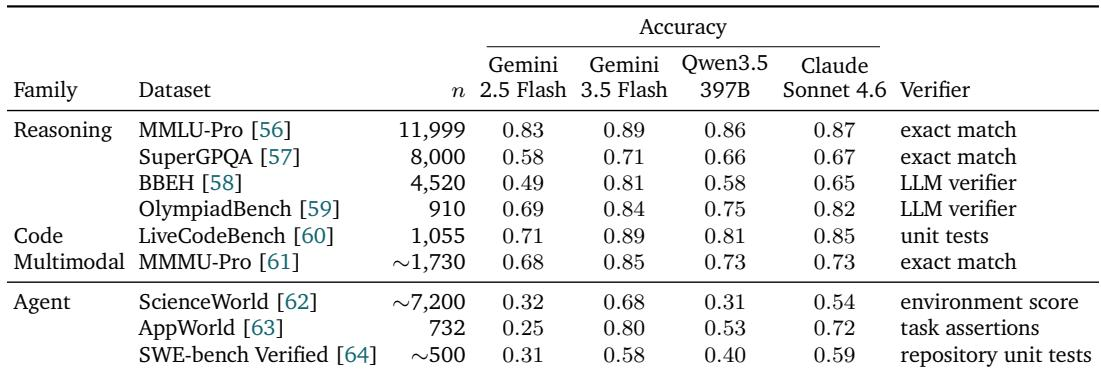
The table evaluates four models across nine benchmarks in reasoning, code, and multimodal tasks, with accuracy varying notably between Gemini generations and across model families. Grading relies on task-specific verifiers, ranging from exact match to unit tests, while the cited text highlights the importance of objective external grading for confidence estimation. Gemini 3.5 Flash substantially outperforms Gemini 2.5 Flash on all benchmarks, showing a clear capability gap. Claude Sonnet 4.6 and Qwen3.5-397B generally fall between the two Gemini models, with Claude often closer to the stronger Gemini. Reasoning benchmarks show the widest accuracy spread across models, while code and multimodal tasks also display consistent ordering. The verifier choice is task-specific: exact match for multiple-choice, LLM verifiers for free-form reasoning, and unit tests for code.
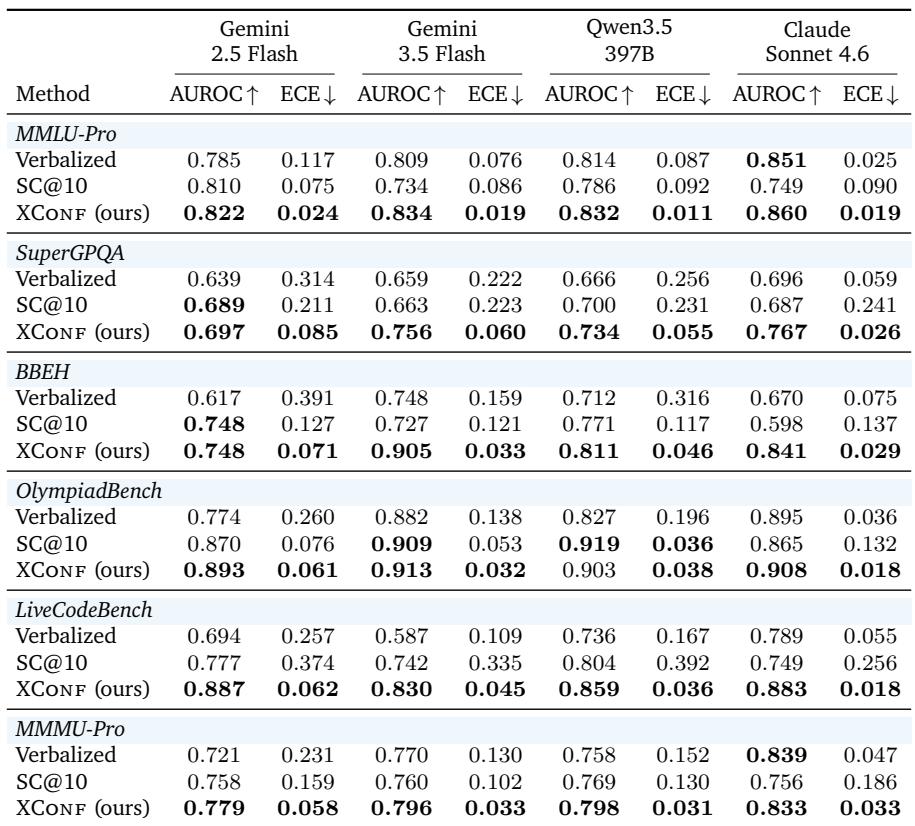
The proposed confidence estimation method consistently matches or outperforms existing approaches across reasoning, code, and multimodal tasks while operating at a fraction of the cost. Its gains are robust to difficulty confounds, model size reductions, and imperfect external grading labels, though it degrades when labels come from the model itself. The method beats or matches self-consistency on almost all evaluated combinations, with lower calibration error. Confidence estimates remain discriminative even when question difficulty is held constant, outperforming verbalized confidence. The approach is nearly unaffected by shrinking model size, except for the reflective component which degrades in smaller models. Replacing ground-truth labels with an independent weak grader preserves most of the benefit, while self-generated labels cause performance to drop below unlabeled baselines.
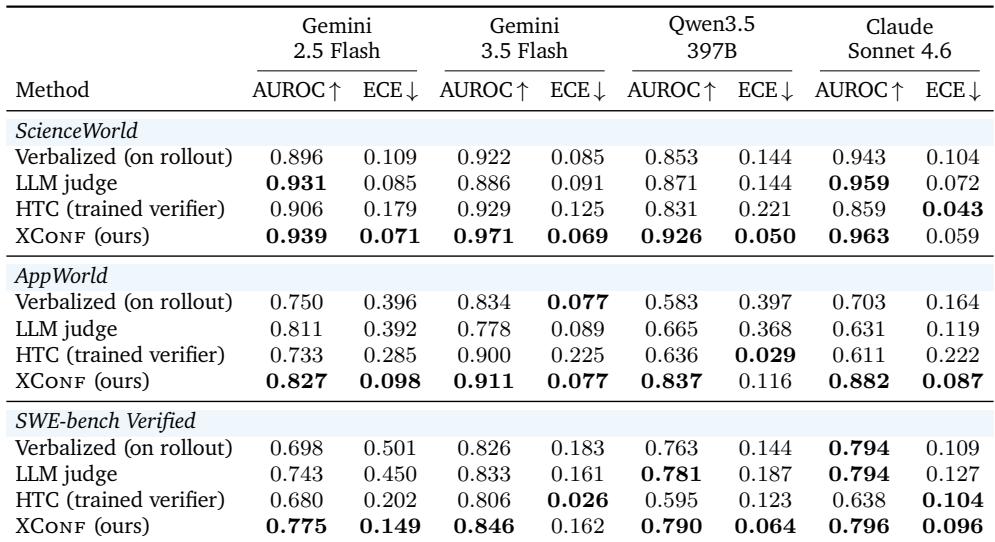
The proposed method consistently achieves the best or on-par AUROC and ECE across all tested agentic benchmarks and model backbones, outperforming both verbalized confidence and trained verifier baselines. The method's advantage persists even when controlling for question difficulty, and its performance is robust to the underlying model's size, although it relies on an independent outcome signal rather than the model's own self-judgment. The method achieves top AUROC and lowest or tied ECE in all twelve model-benchmark cells. It outperforms verbalized confidence and the HTC trained verifier on nearly every model. Even with question difficulty held constant, it separates correct from incorrect attempts at 0.79 AUROC, above chance in 35 of 36 cells. The estimate is nearly invariant to model size, except the verbal reflective component degrades below 27B parameters. Performance relies on an independent grading signal: replacing ground truth with an LLM judge preserves most value, while self-generated labels degrade performance below having no labels.
The proposed confidence estimation method consistently matches or outperforms baselines across reasoning, code, multimodal, and agentic benchmarks at lower cost, remaining discriminative when question difficulty is controlled and robust to model size reductions. Its effectiveness depends on independent outcome labels, as using an independent judge preserves most of the benefit while self-generated labels degrade performance below unlabeled baselines. The method also relies on semantic retrieval of reflective states, which are key for separating correct from incorrect attempts.